


Gemini Robotics ER 2 は、オブジェクトを指し示し、動画で追跡し、境界ボックスで検出し、移動軌跡を生成できます。このページの例では、すべて generate_content を使用した自然言語プロンプトを使用しています。
実行可能な完全なコードについては、ロボティクス クックブックをご覧ください。
オブジェクトを指す
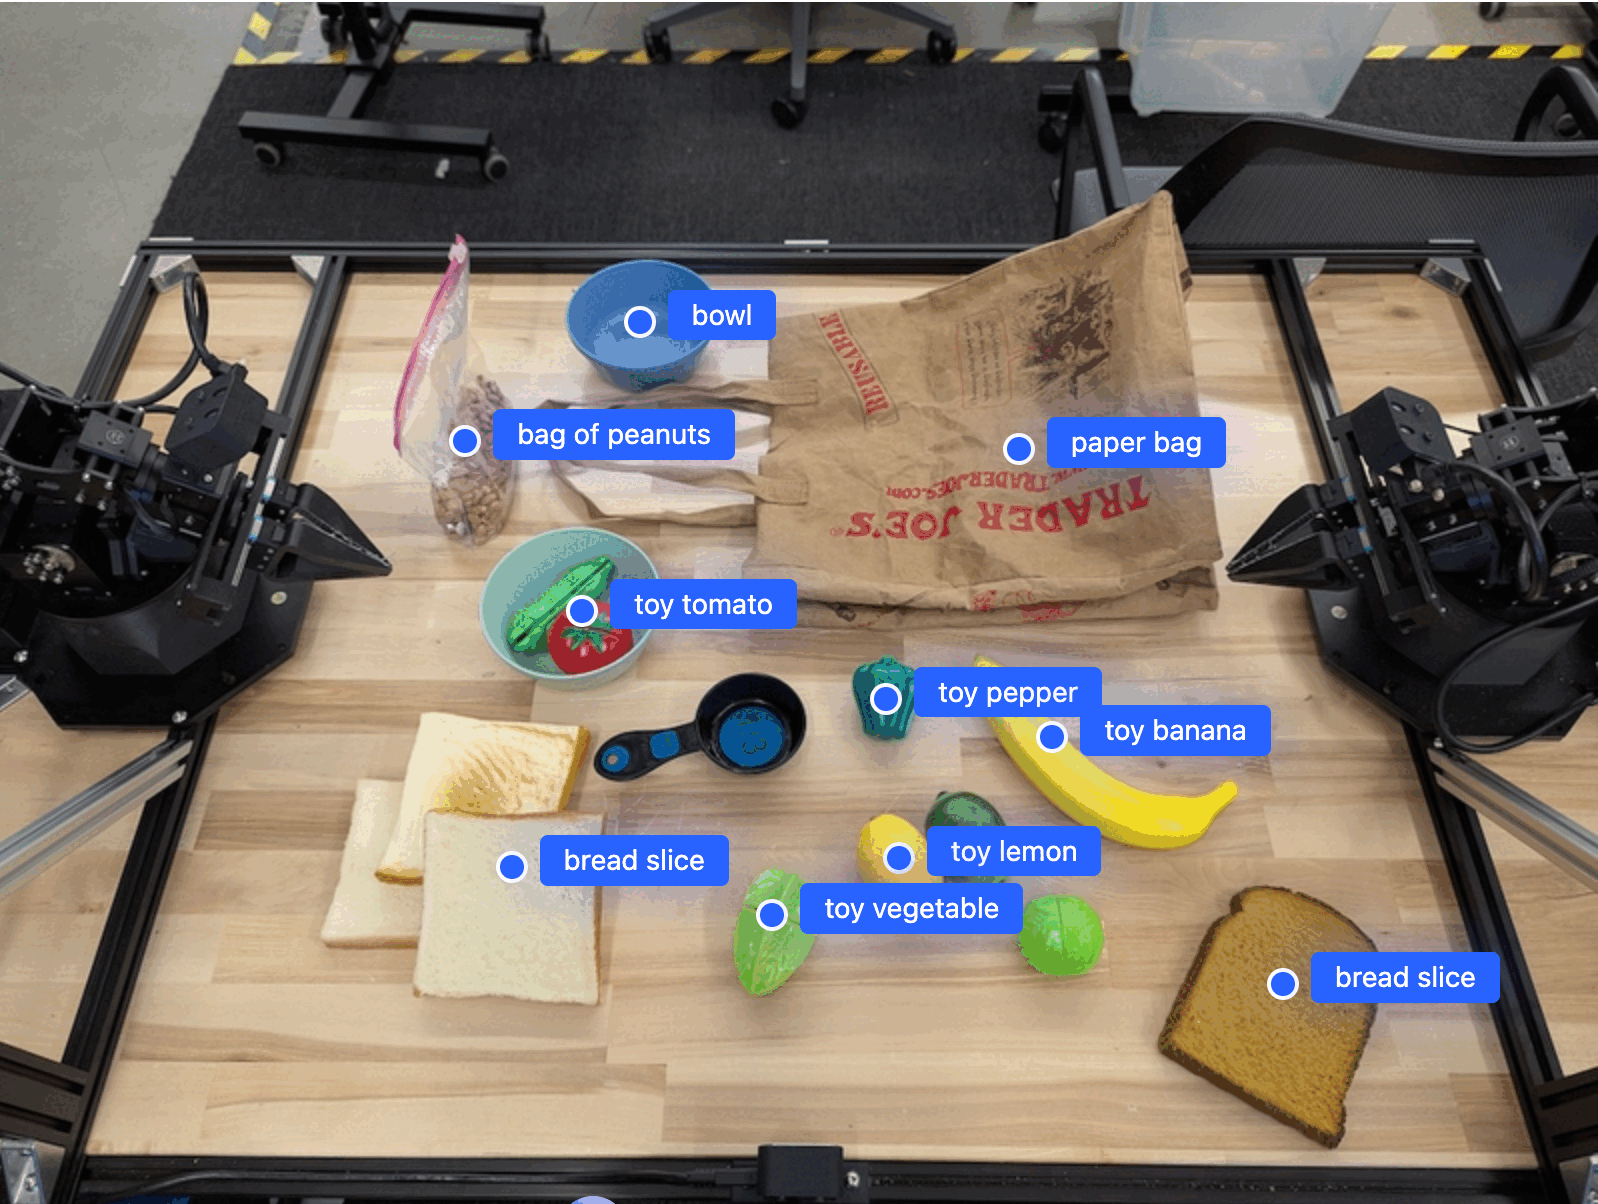
次の例では、画像内の特定のオブジェクトを検出し、正規化された [y, x] 座標を返します。
Python
from google import genai
from google.genai import types

PROMPT = """
          Point to no more than 10 items in the image. The label returned
          should be an identifying name for the object detected.
          The answer should follow the json format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format
          normalized to 0-1000.
        """
client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open("my-image.png", 'rb') as f:
    image_bytes = f.read()

image_response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/png',
        ),
        PROMPT
    ],
    config = types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(
            thinking_level=types.ThinkingLevel.HIGH
        )
    )
)

print(image_response.text)
REST
# First, ensure you have the image file locally.
# Encode the image to base64
IMAGE_BASE64=$(base64 -w 0 my-image.png)

# Set your Google Cloud project and location.
export PROJECT_ID="your-project-id"
export LOCATION="global"
export MODEL="gemini-robotics-er-2-preview"

curl -X POST \
  "https://aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL}:generateContent" \
  -H "Authorization: Bearer $(gcloud auth application-default print-access-token)" \
  -H "Content-Type: application/json" \
  -d '{
    "contents": [
      {
        "parts": [
          {
            "inlineData": {
              "mimeType": "image/png",
              "data": "'"${IMAGE_BASE64}"'"
            }
          },
          {
            "text": "Point to no more than 10 items in the image. The label returned should be an identifying name for the object detected. The answer should follow the json format: [{\"point\": [y, x], \"label\": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000."
          }
        ]
      }
    ],
    "generationConfig": {
      "thinkingConfig": {
        "thinkingLevel": "HIGH"
      }
    }
  }'
出力は、オブジェクトを含む JSON 配列になります。各オブジェクトには、point(正規化された [y, x] 座標)と、オブジェクトを識別する label が含まれます。
JSON
[
  {"point": [376, 508], "label": "small banana"},
  {"point": [287, 609], "label": "larger banana"},
  {"point": [223, 303], "label": "pink starfruit"},
  {"point": [435, 172], "label": "paper bag"},
  {"point": [270, 786], "label": "green plastic bowl"},
  {"point": [488, 775], "label": "metal measuring cup"},
  {"point": [673, 580], "label": "dark blue bowl"},
  {"point": [471, 353], "label": "light blue bowl"},
  {"point": [492, 497], "label": "bread"},
  {"point": [525, 429], "label": "lime"}
]
次の画像は、これらのポイントの表示例です。
動画内のオブジェクトを追跡する
Gemini Robotics ER 2 は、動画フレームを分析してオブジェクトを時系列で追跡することもできます。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your video
with open("my-video.mp4", 'rb') as f:
    video_bytes = f.read()

prompt = """
          Point to the red ball in every frame where it appears.
          The answer should follow the json format: [{"point": [y, x],
          "label": <label>}, ...]. The points are in [y, x] format
          normalized to 0-1000. Return one entry per frame that contains
          the object.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=video_bytes,
      mime_type='video/mp4',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
オブジェクト検出と境界ボックス
ポイントに加えて、モデルに 2D 境界ボックスを返すように指示することもできます。これにより、検出されたオブジェクトの空間的な詳細が提供されます。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

with open("my-image.png", 'rb') as f:
    image_bytes = f.read()

prompt = """
          Detect all objects in this image and return bounding boxes.
          The answer should follow the JSON format:
          [{"label": <label>, "y": <y_min>, "x": <x_min>,
            "y2": <y_max>, "x2": <x_max>}, ...]
          where coordinates are normalized to 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/png',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.LOW
      )
  )
)

print(image_response.text)
軌跡
Gemini Robotics ER 2 は、軌道を定義する一連のポイントを生成できます。これは、ロボットの動きをガイドするのに役立ちます。
この例では、赤いペンをオーガナイザーに移動する軌道をリクエストしています。これには、中間ウェイポイントの推定も含まれます。コードは、プロンプトのみを表示するように縮小されています。
Python
prompt = """
          Generate a trajectory for the robotic arm to pick up the red pen
          and place it in the organizer. Return a list of waypoints as JSON:
          [{"step": <int>, "point": [y, x], "action": <description>}, ...]
          where coordinates are normalized to 0-1000.
        """
ノートパソコンを置くスペースを確保する
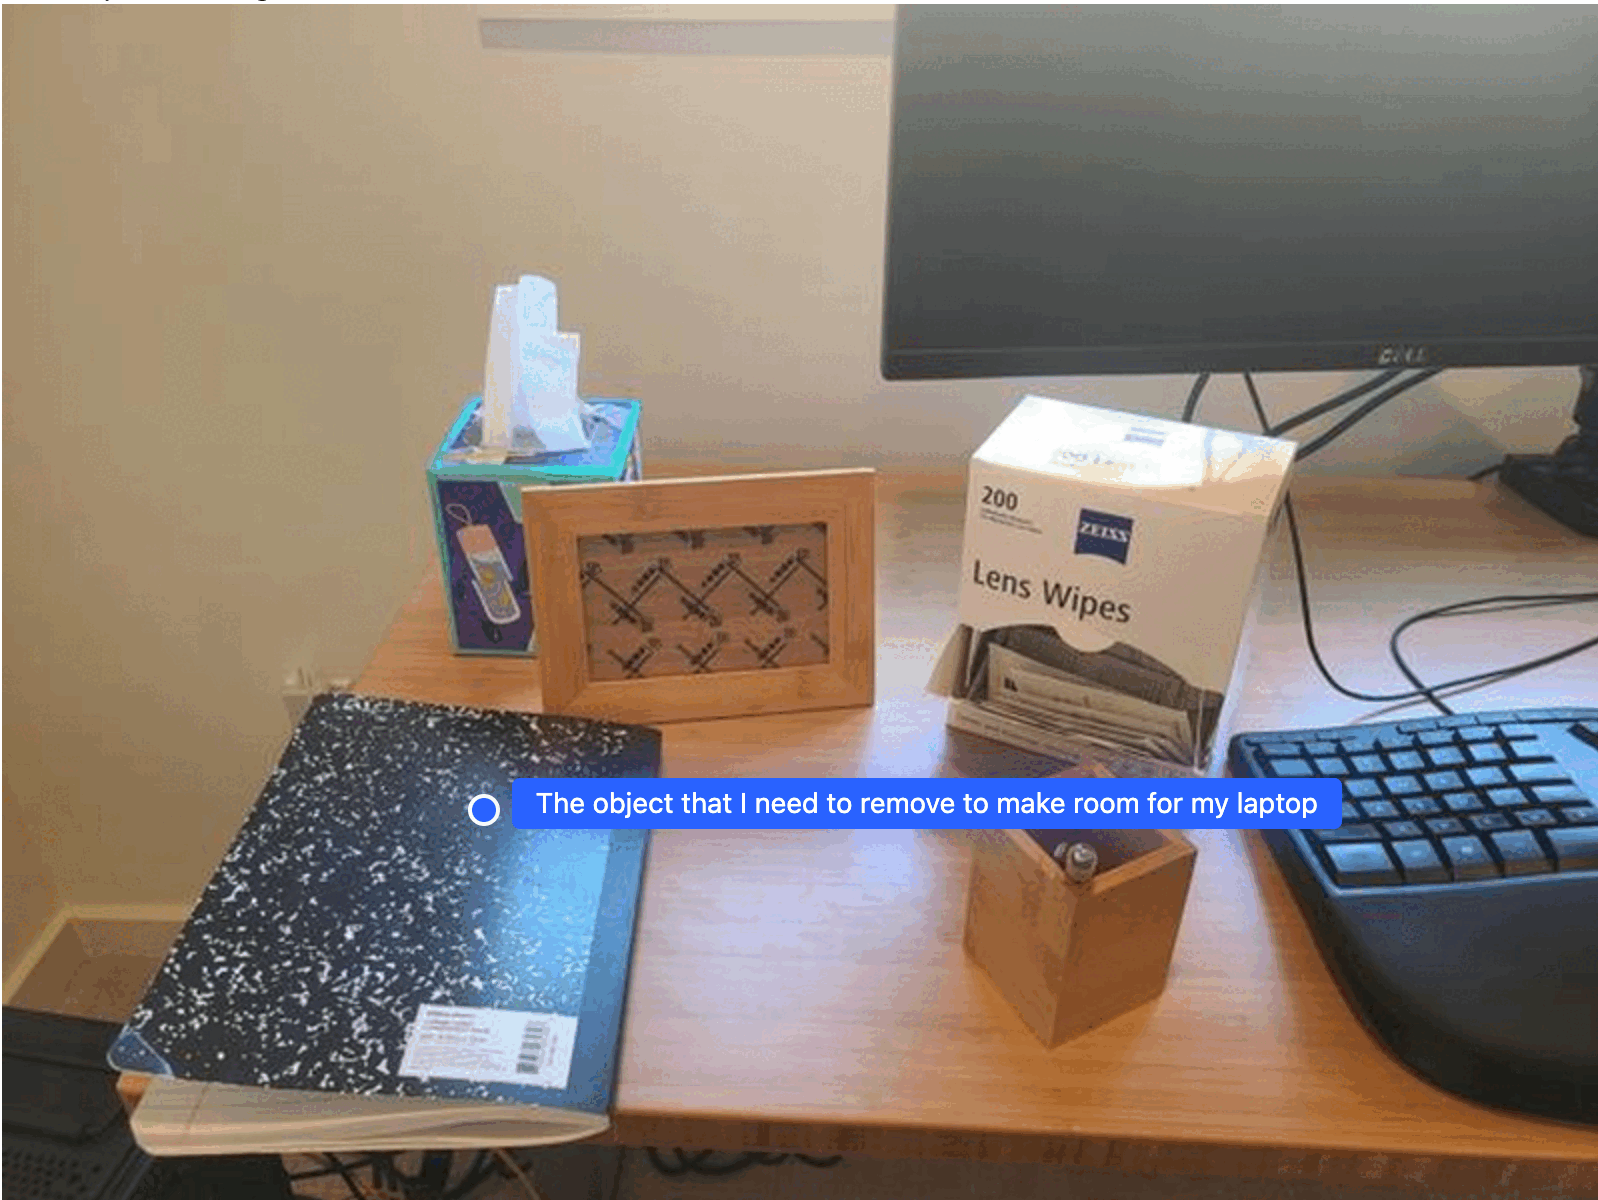
この例は、Gemini Robotics ER 2 が空間について推論する方法を示しています。このプロンプトは、別のアイテムのスペースを確保するために移動する必要があるオブジェクトを特定するようにモデルに指示します。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open('path/to/image-with-objects.jpg', 'rb') as f:
    image_bytes = f.read()

prompt = """
          Point to the object that I need to remove to make room for my laptop
          The answer should follow the JSON format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/jpeg',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
レスポンスには、ユーザーの質問に回答するオブジェクトの 2D 座標が含まれます。この場合、ノートパソコンを置くスペースを確保するために移動する必要があるオブジェクトです。
[
  {"point": [672, 301], "label": "The object that I need to remove to make room for my laptop"}
]
お弁当を作る
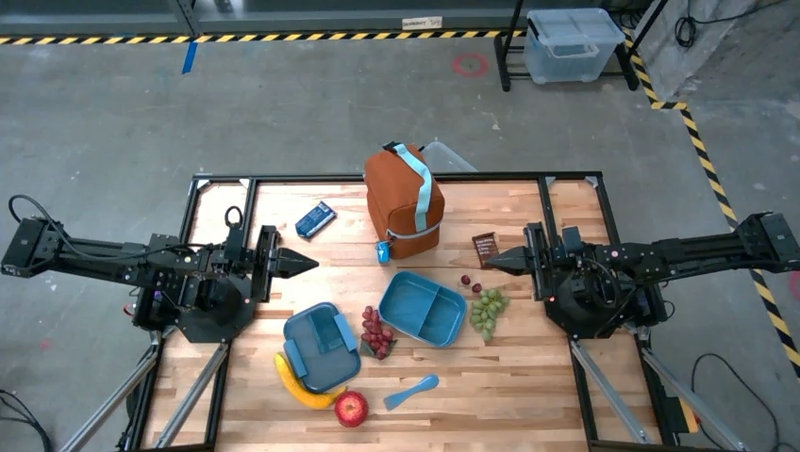
このモデルは、マルチステップ タスクの手順を提供し、各ステップに関連するオブジェクトを指し示すこともできます。この例は、モデルがランチバッグを詰める一連の手順を計画する方法を示しています。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image and set up your prompt
with open('path/to/image-of-lunch.jpg', 'rb') as f:
    image_bytes = f.read()

prompt = """
          Explain how to pack the lunch box and lunch bag. Point to each
          object that you refer to. Each point should be in the format:
          [{"point": [y, x], "label": }], where the coordinates are
          normalized between 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/jpeg',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
このプロンプトのレスポンスは、画像入力からランチバッグを詰める方法に関する一連の手順です。
入力画像
モデル出力
Based on the image, here is a plan to pack the lunch box and lunch bag:

1.  **Pack the fruit into the lunch box.** Place the apple, banana, red grapes, and green grapes into the blue lunch box.
2.  **Add the spoon to the lunch box.** Put the blue spoon inside the lunch box as well.
3.  **Close the lunch box.** Secure the lid on the blue lunch box.
4.  **Place the lunch box inside the lunch bag.** Put the closed blue lunch box into the brown lunch bag.
5.  **Pack the remaining items into the lunch bag.** Place the blue snack bar and the brown snack bar into the brown lunch bag.

Here is the list of objects and their locations:
*   [{"point": [899, 440], "label": "apple"}]
*   [{"point": [814, 363], "label": "banana"}]
*   [{"point": [727, 470], "label": "red grapes"}]
*   [{"point": [675, 608], "label": "green grapes"}]
*   [{"point": [706, 529], "label": "blue lunch box"}]
*   [{"point": [864, 517], "label": "blue spoon"}]
*   [{"point": [499, 401], "label": "blue snack bar"}]
*   [{"point": [614, 705], "label": "brown snack bar"}]
*   [{"point": [448, 501], "label": "brown lunch bag"}]
次のステップ
Gemini Robotics ER 2 の詳細については、次のリソースをご覧ください。
- エージェント機能: コード実行、計器の読み取り、画像アノテーション。
- タスク オーケストレーション: カスタム ロボット API を使用した長期的なタスク。
- 動画の理解: モーメントの検出と進行状況の分類。
- Gemini Robotics ER 2 の概要: 機能とクイックスタート。
- Gemini Robotics ER 2 モデル情報: 技術仕様、トークン制限、サポートされている機能。