


Gemini Robotics ER 2 は、Python コードを記述して実行し、画像を操作してロジックを適用してから回答できます。このページでは、ズームと切り抜きによるオブジェクト検出、計器の読み取り、流体測定、回路基板の読み取り、画像アノテーションなど、コード実行の例について説明します。
実行可能な完全なコードについては、ロボティクス クックブックをご覧ください。
思考レベル
思考レベルを制御して、レイテンシと精度のトレードオフを調整できます。オブジェクト検出などの空間タスクは、思考レベルが低くても良好なパフォーマンスを発揮します。カウントや重量推定などの複雑なタスクでは、高い値が有効です。
次の例では、複雑なカウントタスクに対して思考レベルを「高」に設定しています。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open('scene.jpeg', 'rb') as f:
    image_bytes = f.read()

response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/jpeg',
        ),
        "Identify and count all objects on the table."
    ],
    config = types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(
            # Use MINIMAL or LOW for faster spatial tasks.
            thinking_level=types.ThinkingLevel.HIGH
        ),
    )
)

print(response.text)
詳しくは、思考をご覧ください。
オブジェクト検出(ズームと切り抜き)
次の例は、コード実行を使用して画像をズームして切り抜き、オブジェクトを検出して境界ボックスを返すときに、より鮮明なビューを表示する方法を示しています。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open('sorting.jpeg', 'rb') as f:
    image_bytes = f.read()

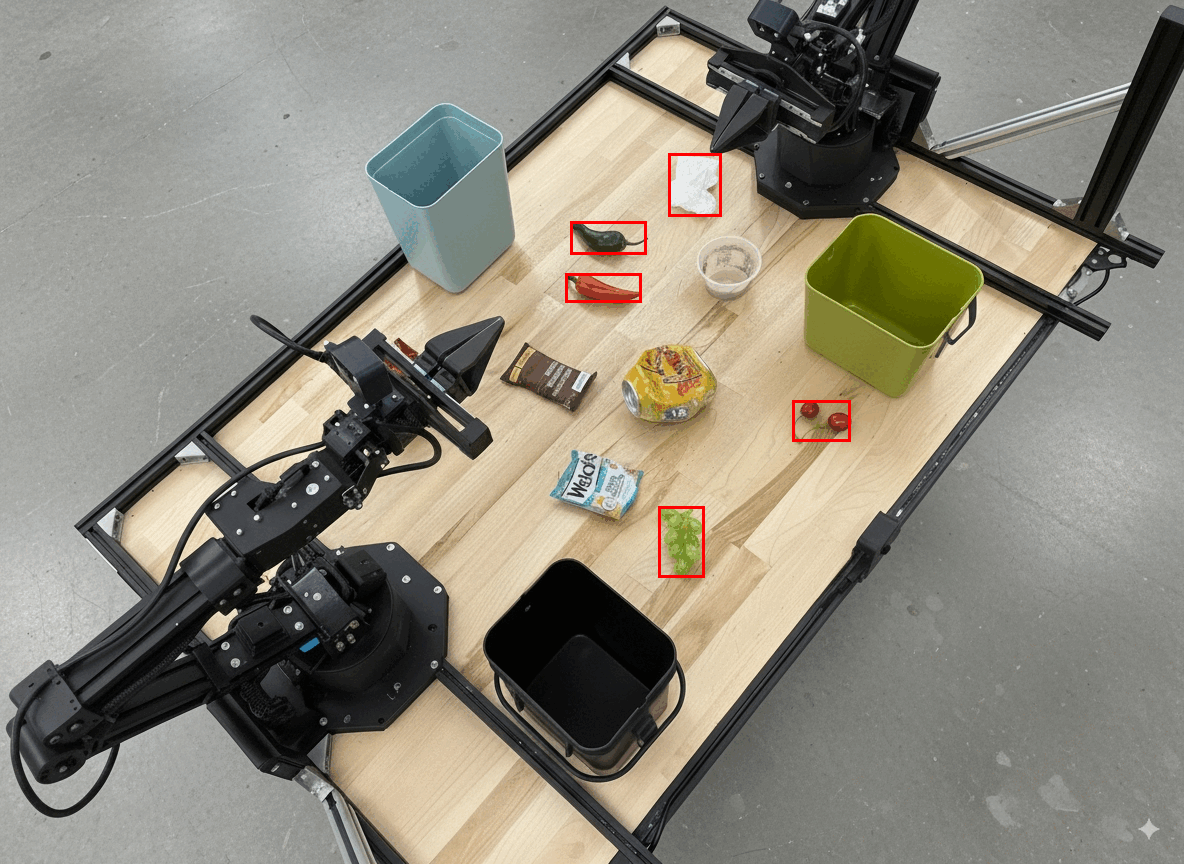
prompt = """
Return JSON in the format {label: val, y: val, x: val, y2: val, x2: val} for
the compostable objects in this scene. Please Zoom and crop the image for a
clearer view. Return an annotated image of the final result with the bounding
boxes drawn on it to the API caller as a part of your process.
"""

response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/jpeg',
        ),
        prompt
    ],
    config = types.GenerateContentConfig(
        tools=[types.Tool(code_execution=types.ToolCodeExecution)],
    )
)

print(response.text)
モデルの出力は次のようになります。
[
  {"label": "compostable", "y": 256, "x": 482, "y2": 295, "x2": 546},
  {"label": "compostable", "y": 317, "x": 478, "y2": 350, "x2": 542},
  {"label": "compostable", "y": 586, "x": 556, "y2": 668, "x2": 595},
  {"label": "compostable", "y": 463, "x": 669, "y2": 511, "x2": 718},
  {"label": "compostable", "y": 178, "x": 565, "y2": 250, "x2": 609}
]
以下に、モデルから返されたボックスを示します。
アナログ ゲージを読み取り、ロジックを適用する
次の例は、モデルを使用してアナログ ゲージを読み取り、時間計算を行う方法を示しています。システム指示を使用して JSON 出力を適用します。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

with open('gauge.jpeg', 'rb') as f:
    image_bytes = f.read()

system_instruction = "Be precise. When JSON is requested, reply with ONLY that JSON (no preface, no code block)."

response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/jpeg',
        ),
        """Read the current value from this gauge. Then, calculate how long
        it will take at the current rate for the value to reach maximum.
        Reply in JSON: {"current_value": val, "max_value": val,
        "time_to_max_minutes": val}"""
    ],
    config = types.GenerateContentConfig(
        system_instruction=system_instruction,
        tools=[types.Tool(code_execution=types.ToolCodeExecution)],
    )
)

print(response.text)
容器内の液体を測定する
次の例は、コード実行を使用して容器内の液体の量を測定する方法を示しています。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

with open('fluid.jpeg', 'rb') as f:
    image_bytes = f.read()

system_instruction = "Be precise. When JSON is requested, reply with ONLY that JSON (no preface, no code block)."

response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/jpeg',
        ),
        """Measure the amount of fluid in the container. Reply in JSON:
        {"fluid_level_ml": val, "container_capacity_ml": val,
        "percentage_full": val}"""
    ],
    config = types.GenerateContentConfig(
        system_instruction=system_instruction,
        tools=[types.Tool(code_execution=types.ToolCodeExecution)],
    )
)

print(response.text)
回路基板のマークを読み取る
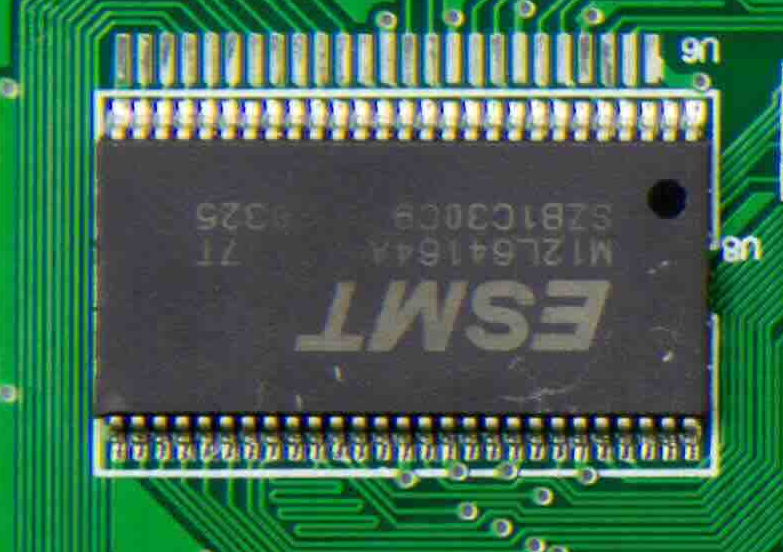
次の例は、コード実行を使用して回路基板のマークを読み取る方法を示しています。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

with open('circuit_board.jpeg', 'rb') as f:
    image_bytes = f.read()

system_instruction = "Be precise. When JSON is requested, reply with ONLY that JSON (no preface, no code block)."

response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/jpeg',
        ),
        """Read all visible component labels and markings on this circuit
        board. Reply in JSON: {"components": [{"label": val,
        "location": [y, x]}]}"""
    ],
    config = types.GenerateContentConfig(
        system_instruction=system_instruction,
        tools=[types.Tool(code_execution=types.ToolCodeExecution)],
    )
)

print(response.text)
画像アノテーション
次の例は、コード実行を使用して画像にアノテーションを付け(廃棄手順の矢印を描画するなど)、変更された画像を返す方法を示しています。
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open('sorting.jpeg', 'rb') as f:
    image_bytes = f.read()

prompt = """
Look at this image and return it as an annotated version using arrows of
different colors to represent which items should go in which bins for
disposal. You must return the final image to the API caller.
"""

response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/jpeg',
        ),
        prompt
    ],
    config = types.GenerateContentConfig(
        tools=[types.Tool(code_execution=types.ToolCodeExecution)],
    )
)

print(response.text)
以下は、画像入力の例です。
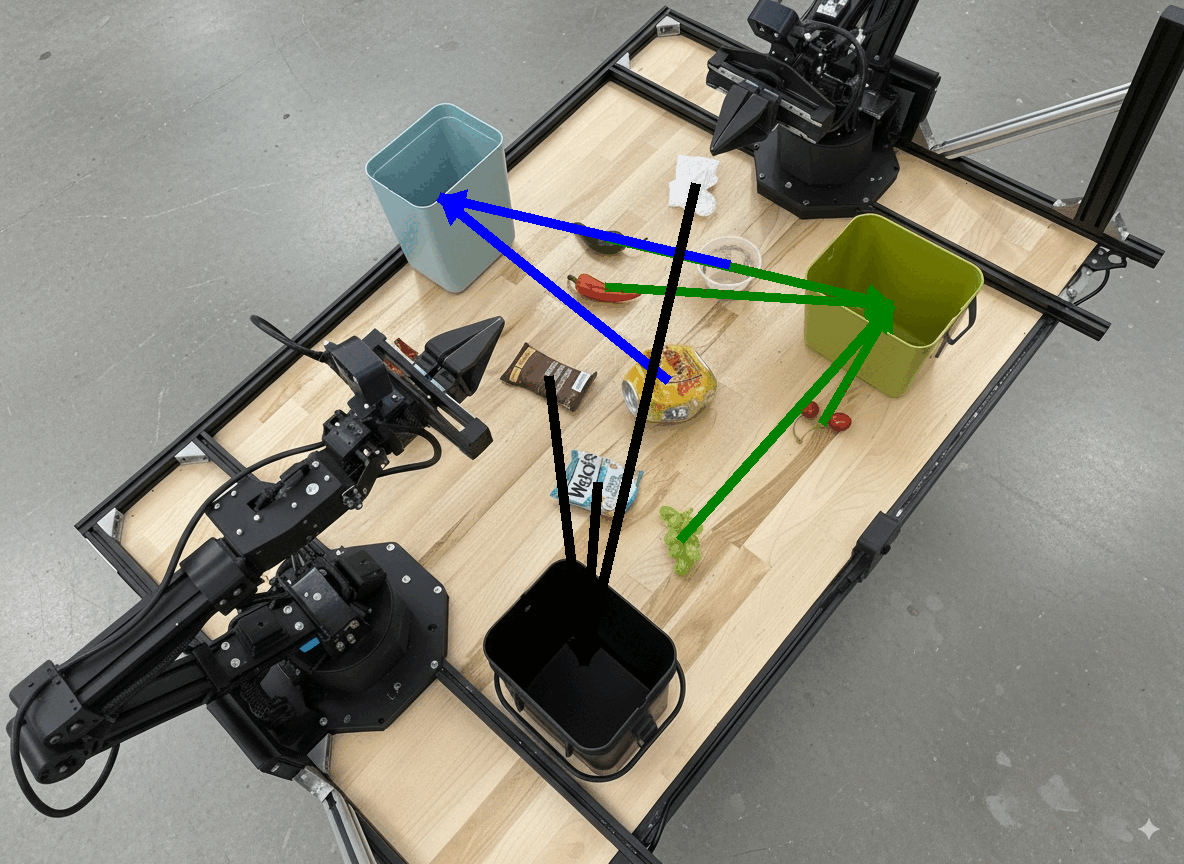
モデルの出力は次のようになります。
  The annotated image shows the suggested disposal locations for the items on the table:
  - **Green bin (Compost/Organic)**: Green chili, red chili, grapes, and cherries.
  - **Blue bin (Recycling)**: Yellow crushed can and plastic container.
  - **Black bin (Trash)**: Chocolate bar wrapper, Welch's packet, and white tissue.
次のステップ
Gemini Robotics ER 2 の詳細については、次のリソースをご覧ください。
- タスク オーケストレーション: カスタム ロボット API を使用した長期的なタスク。
- 空間推論: ポインティング、トラッキング、境界ボックス、軌跡。
- 動画の理解: モーメントの検出と進行状況の分類。
- Gemini Robotics ER 2 の概要: 機能とクイックスタート。
- Gemini Robotics ER 2 モデル情報: 技術仕様、トークン制限、サポートされている機能。