


Gemini Robotics ER 2 peut pointer vers des objets, les suivre dans une vidéo, les détecter à l'aide de cadres de délimitation et générer des trajectoires de mouvement. Tous les exemples de cette page utilisent des requêtes en langage naturel avec generate_content.
Pour obtenir un code exécutable complet, consultez le guide de robotique.
Pointer vers des objets
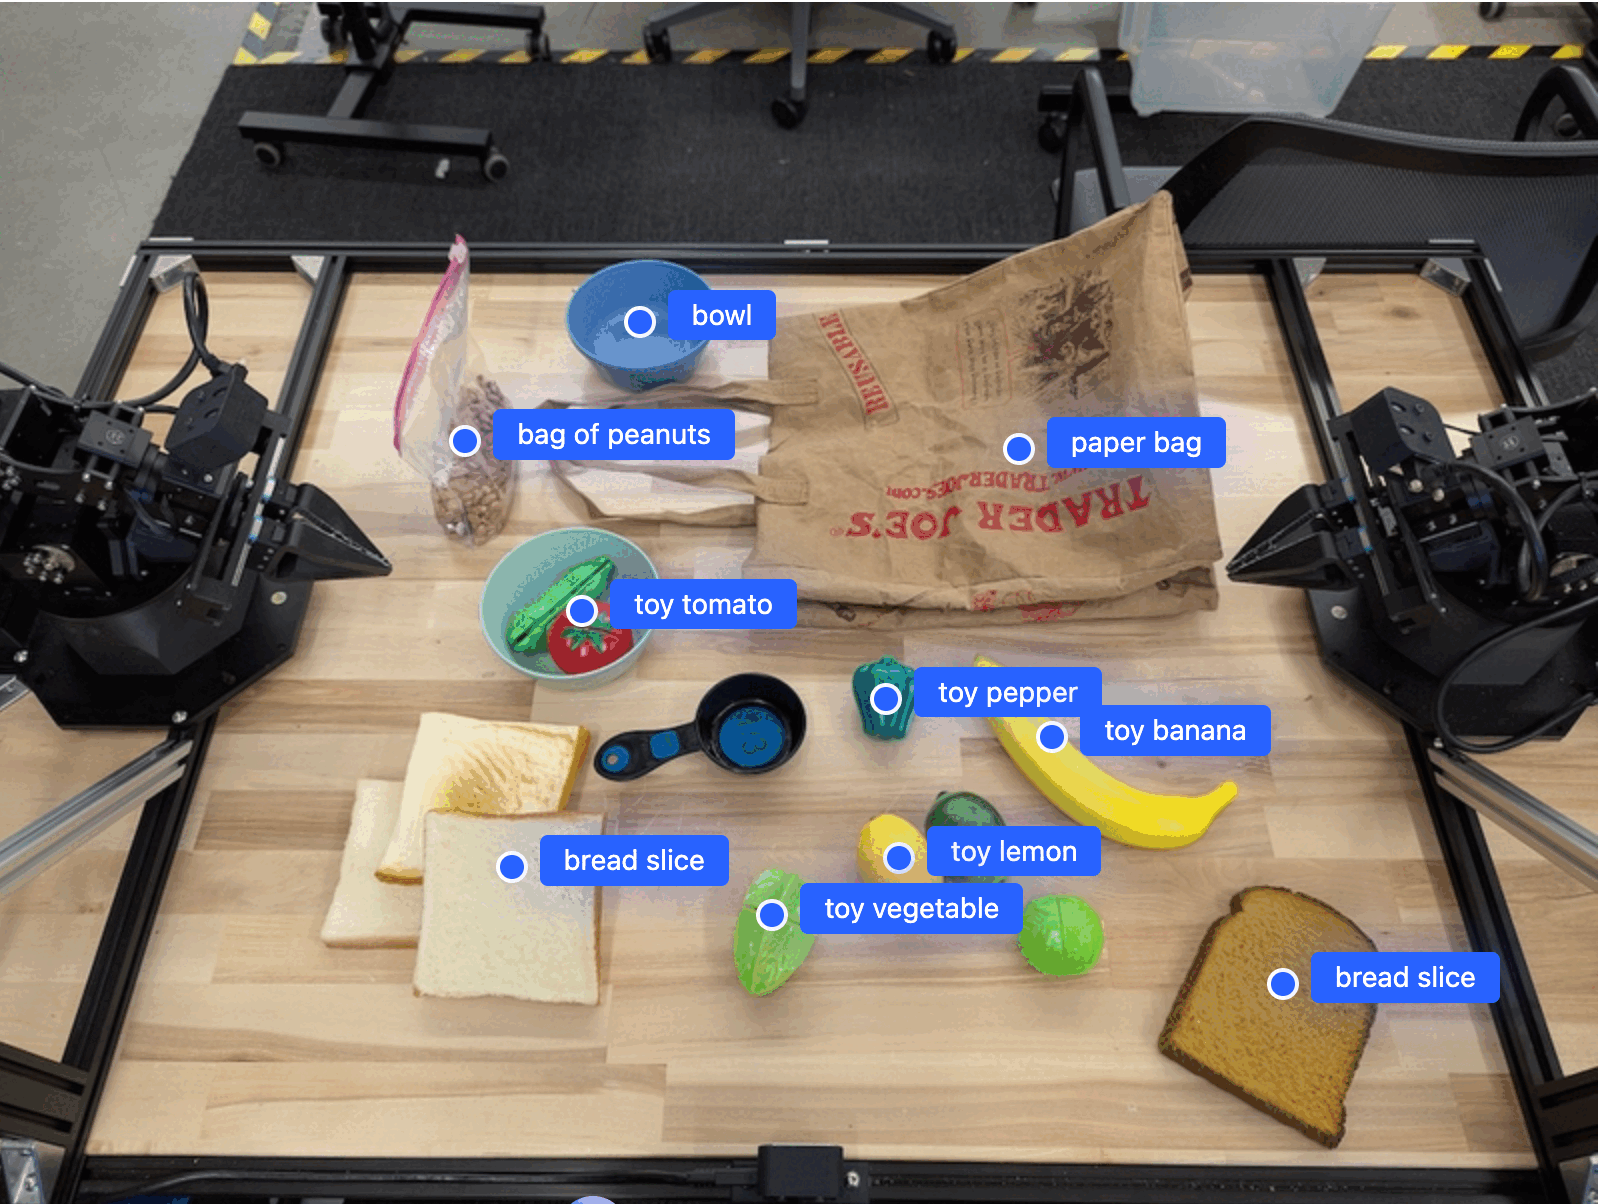
L'exemple suivant recherche des objets spécifiques dans une image et renvoie leurs coordonnées [y, x] normalisées :
Python
from google import genai
from google.genai import types

PROMPT = """
          Point to no more than 10 items in the image. The label returned
          should be an identifying name for the object detected.
          The answer should follow the json format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format
          normalized to 0-1000.
        """
client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open("my-image.png", 'rb') as f:
    image_bytes = f.read()

image_response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/png',
        ),
        PROMPT
    ],
    config = types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(
            thinking_level=types.ThinkingLevel.HIGH
        )
    )
)

print(image_response.text)
REST
# First, ensure you have the image file locally.
# Encode the image to base64
IMAGE_BASE64=$(base64 -w 0 my-image.png)

# Set your Google Cloud project and location.
export PROJECT_ID="your-project-id"
export LOCATION="global"
export MODEL="gemini-robotics-er-2-preview"

curl -X POST \
  "https://aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL}:generateContent" \
  -H "Authorization: Bearer $(gcloud auth application-default print-access-token)" \
  -H "Content-Type: application/json" \
  -d '{
    "contents": [
      {
        "parts": [
          {
            "inlineData": {
              "mimeType": "image/png",
              "data": "'"${IMAGE_BASE64}"'"
            }
          },
          {
            "text": "Point to no more than 10 items in the image. The label returned should be an identifying name for the object detected. The answer should follow the json format: [{\"point\": [y, x], \"label\": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000."
          }
        ]
      }
    ],
    "generationConfig": {
      "thinkingConfig": {
        "thinkingLevel": "HIGH"
      }
    }
  }'
Le résultat sera un tableau JSON contenant des objets, chacun avec un point (coordonnées [y, x] normalisées) et un label identifiant l'objet.
JSON
[
  {"point": [376, 508], "label": "small banana"},
  {"point": [287, 609], "label": "larger banana"},
  {"point": [223, 303], "label": "pink starfruit"},
  {"point": [435, 172], "label": "paper bag"},
  {"point": [270, 786], "label": "green plastic bowl"},
  {"point": [488, 775], "label": "metal measuring cup"},
  {"point": [673, 580], "label": "dark blue bowl"},
  {"point": [471, 353], "label": "light blue bowl"},
  {"point": [492, 497], "label": "bread"},
  {"point": [525, 429], "label": "lime"}
]
L'image suivante montre un exemple d'affichage de ces points :
Suivre des objets dans une vidéo
Gemini Robotics ER 2 peut également analyser des images vidéo pour suivre des objets au fil du temps.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your video
with open("my-video.mp4", 'rb') as f:
    video_bytes = f.read()

prompt = """
          Point to the red ball in every frame where it appears.
          The answer should follow the json format: [{"point": [y, x],
          "label": <label>}, ...]. The points are in [y, x] format
          normalized to 0-1000. Return one entry per frame that contains
          the object.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=video_bytes,
      mime_type='video/mp4',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
Détection d'objets et cadres de délimitation
En plus des points, vous pouvez demander au modèle de renvoyer des cadres de délimitation 2D, qui fournissent plus de détails spatiaux sur les objets détectés.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

with open("my-image.png", 'rb') as f:
    image_bytes = f.read()

prompt = """
          Detect all objects in this image and return bounding boxes.
          The answer should follow the JSON format:
          [{"label": <label>, "y": <y_min>, "x": <x_min>,
            "y2": <y_max>, "x2": <x_max>}, ...]
          where coordinates are normalized to 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/png',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.LOW
      )
  )
)

print(image_response.text)
Trajectoires
Gemini Robotics ER 2 peut générer des séquences de points qui définissent une trajectoire, ce qui est utile pour guider les mouvements d'un robot.
Cet exemple demande une trajectoire pour déplacer un stylo rouge vers un organisateur, y compris une estimation des points de cheminement intermédiaires. Le code a été réduit pour n'afficher que le prompt.
Python
prompt = """
          Generate a trajectory for the robotic arm to pick up the red pen
          and place it in the organizer. Return a list of waypoints as JSON:
          [{"step": <int>, "point": [y, x], "action": <description>}, ...]
          where coordinates are normalized to 0-1000.
        """
Faites de la place pour un ordinateur portable
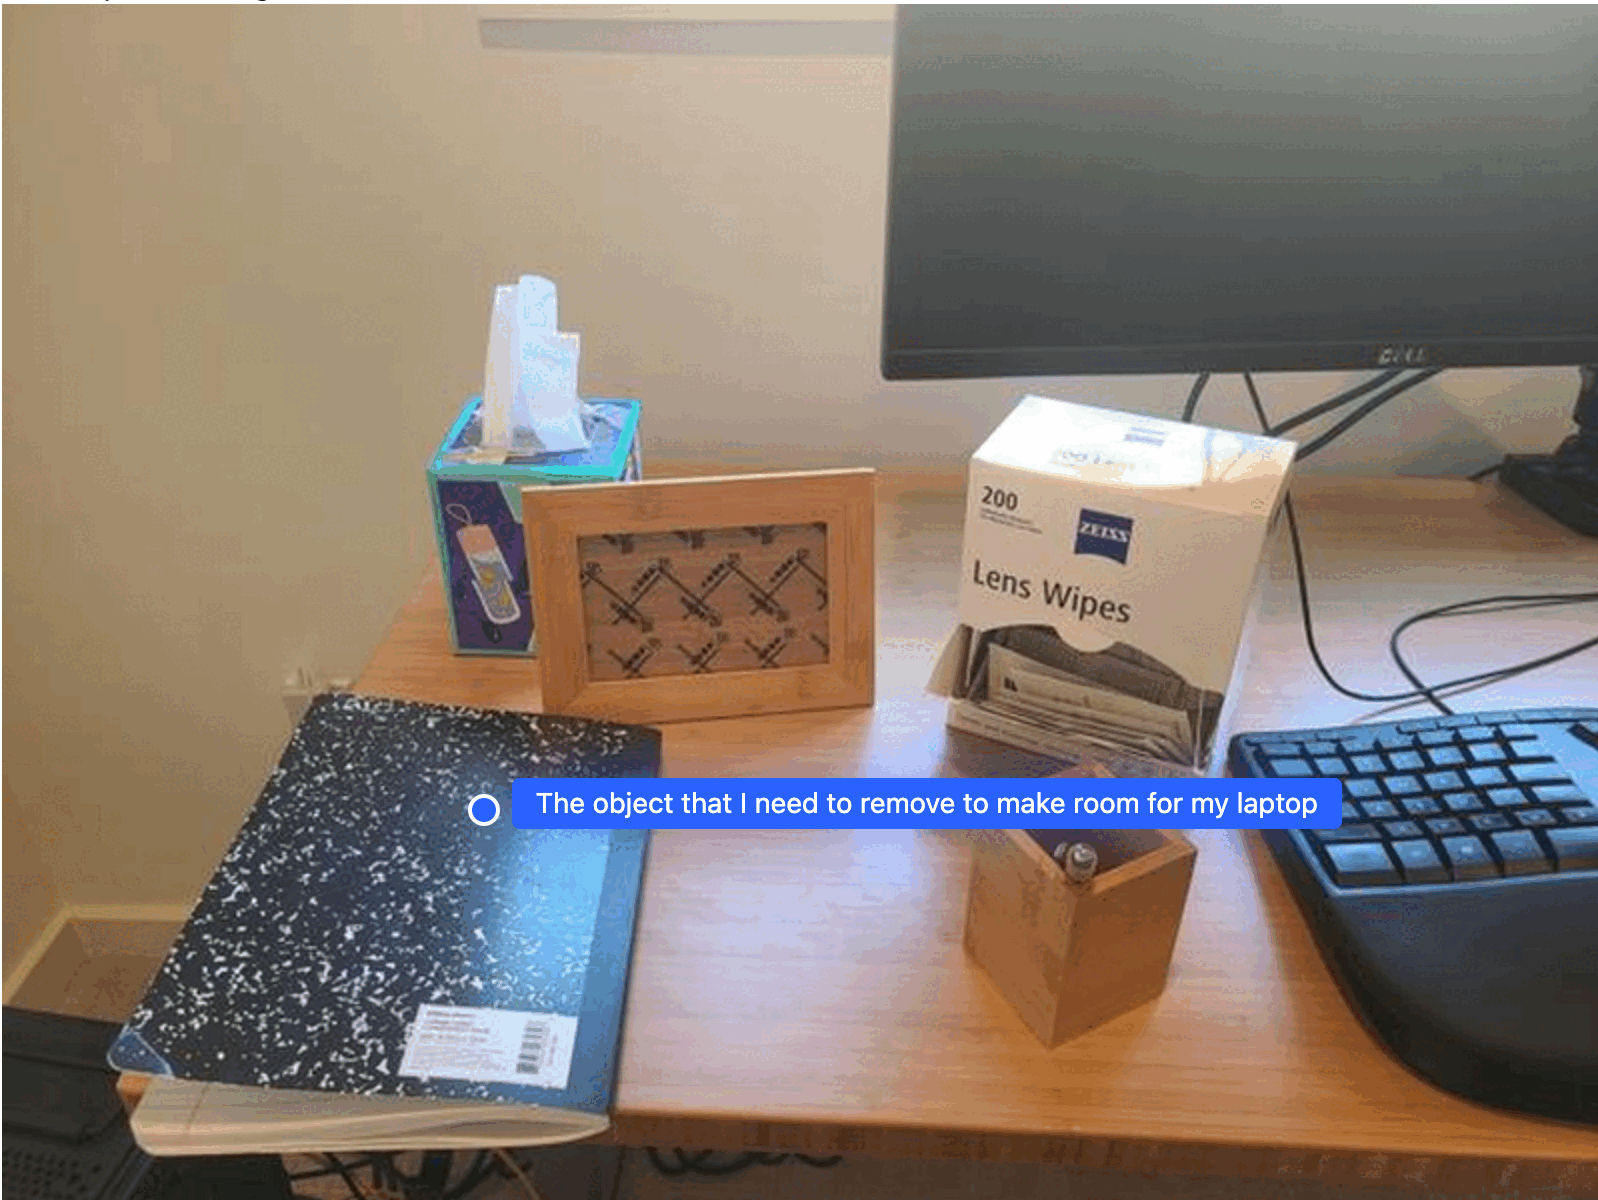
Cet exemple montre comment Gemini Robotics ER 2 peut raisonner sur un espace. La requête demande au modèle d'identifier l'objet à déplacer pour faire de la place à un autre élément.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open('path/to/image-with-objects.jpg', 'rb') as f:
    image_bytes = f.read()

prompt = """
          Point to the object that I need to remove to make room for my laptop
          The answer should follow the JSON format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/jpeg',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
La réponse contient les coordonnées 2D de l'objet qui répond à la question de l'utilisateur, en l'occurrence l'objet qui doit être déplacé pour faire de la place à un ordinateur portable.
[
  {"point": [672, 301], "label": "The object that I need to remove to make room for my laptop"}
]
Préparer un panier-repas
Le modèle peut également fournir des instructions pour les tâches en plusieurs étapes et pointer vers les objets pertinents pour chaque étape. Cet exemple montre comment le modèle planifie une série d'étapes pour préparer un panier-repas.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image and set up your prompt
with open('path/to/image-of-lunch.jpg', 'rb') as f:
    image_bytes = f.read()

prompt = """
          Explain how to pack the lunch box and lunch bag. Point to each
          object that you refer to. Each point should be in the format:
          [{"point": [y, x], "label": }], where the coordinates are
          normalized between 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/jpeg',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
La réponse à ce prompt est un ensemble d'instructions détaillées sur la façon de préparer un sac-repas à partir de l'image d'entrée.
Image d'entrée
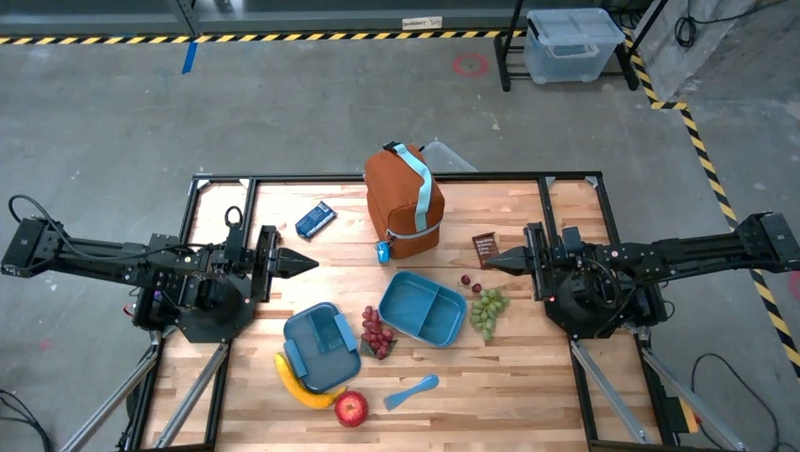
Sortie du modèle
Based on the image, here is a plan to pack the lunch box and lunch bag:

1.  **Pack the fruit into the lunch box.** Place the apple, banana, red grapes, and green grapes into the blue lunch box.
2.  **Add the spoon to the lunch box.** Put the blue spoon inside the lunch box as well.
3.  **Close the lunch box.** Secure the lid on the blue lunch box.
4.  **Place the lunch box inside the lunch bag.** Put the closed blue lunch box into the brown lunch bag.
5.  **Pack the remaining items into the lunch bag.** Place the blue snack bar and the brown snack bar into the brown lunch bag.

Here is the list of objects and their locations:
*   [{"point": [899, 440], "label": "apple"}]
*   [{"point": [814, 363], "label": "banana"}]
*   [{"point": [727, 470], "label": "red grapes"}]
*   [{"point": [675, 608], "label": "green grapes"}]
*   [{"point": [706, 529], "label": "blue lunch box"}]
*   [{"point": [864, 517], "label": "blue spoon"}]
*   [{"point": [499, 401], "label": "blue snack bar"}]
*   [{"point": [614, 705], "label": "brown snack bar"}]
*   [{"point": [448, 501], "label": "brown lunch bag"}]
Étapes suivantes
Pour en savoir plus sur Gemini Robotics ER 2, consultez les ressources suivantes :
- Capacités agentiques : exécution de code, lecture d'instruments et annotation d'images.
- Orchestration des tâches : tâches à long horizon avec des API de robot personnalisées.
- Compréhension des vidéos : recherche de moments et classification de la progression.
- Présentation de Gemini Robotics ER 2 : fonctionnalités et démarrage rapide.
- Informations sur le modèle Gemini Robotics ER 2 : caractéristiques techniques, limites de jetons et fonctionnalités compatibles.