


O Gemini Robotics ER 2 pode apontar para objetos, rastreá-los em vídeos, detectá-los com
caixas delimitadoras e gerar trajetórias de movimento. Todos os exemplos nesta página usam
comandos de linguagem natural com generate_content.
Para ver o código executável completo, consulte o guia de robótica.
Apontar para objetos
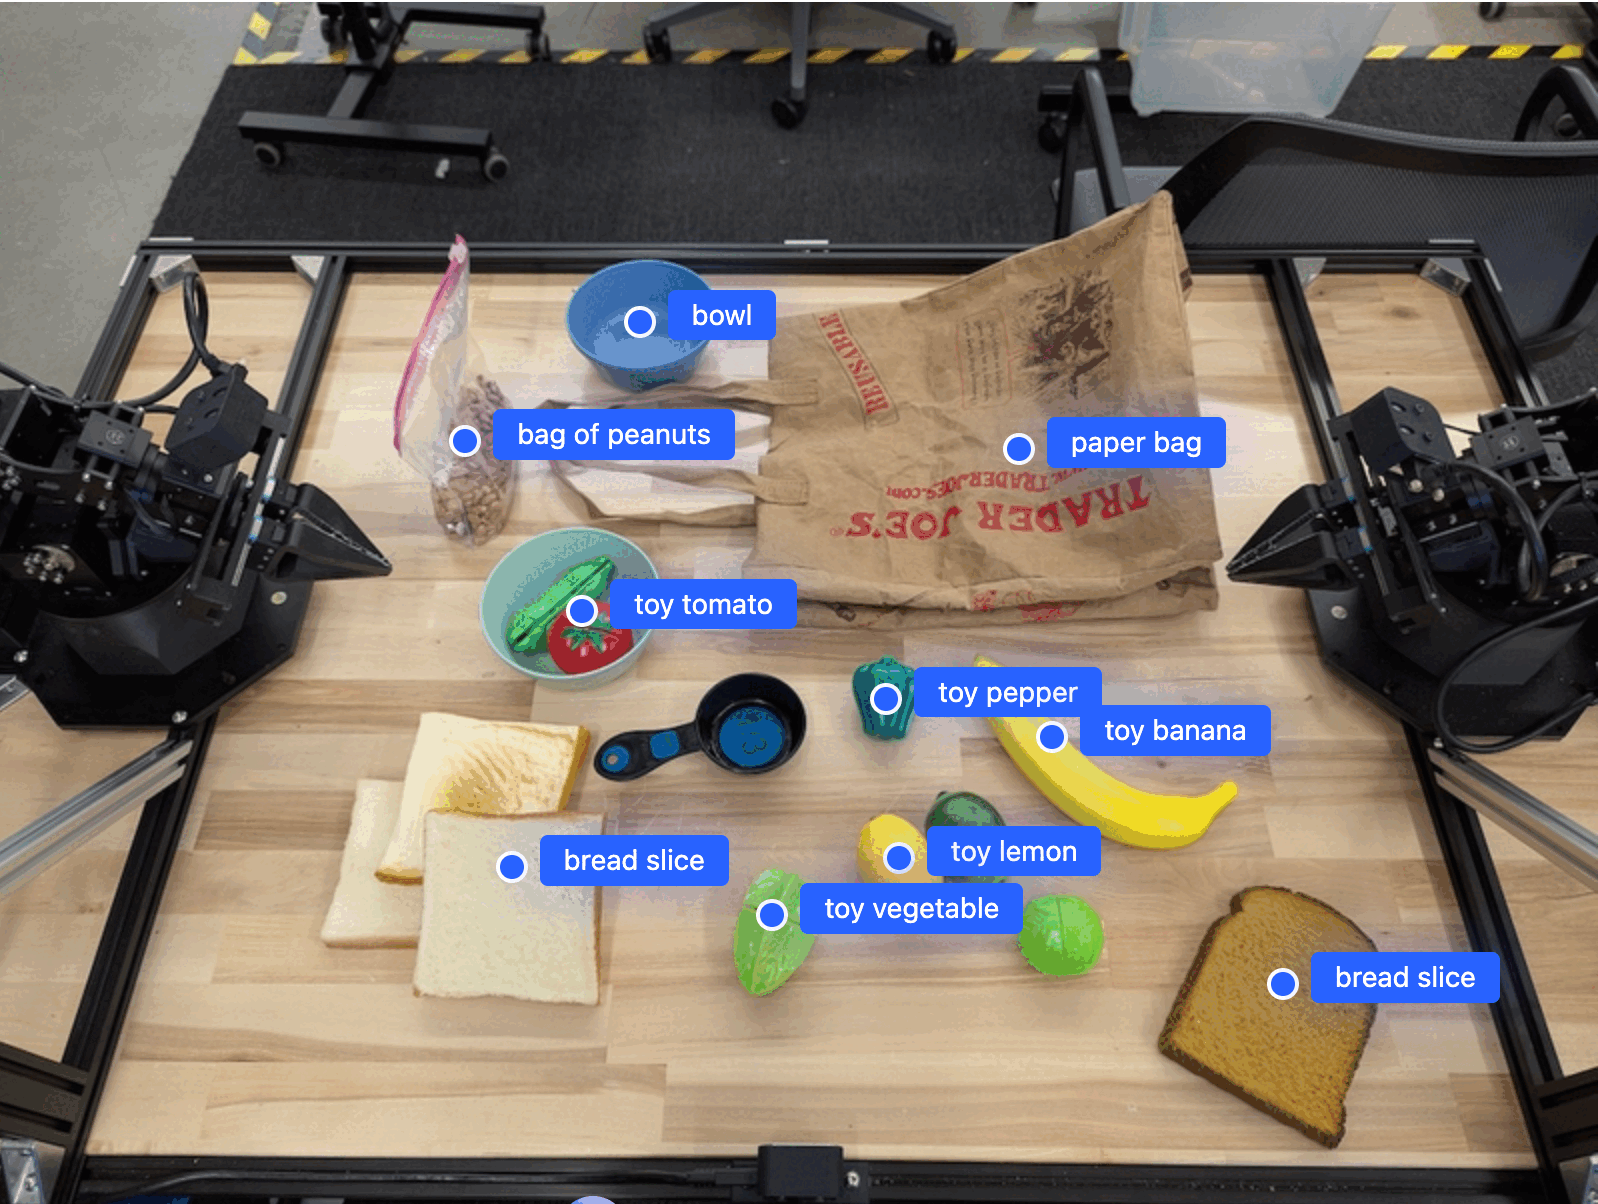
O exemplo a seguir encontra objetos específicos em uma imagem e retorna as coordenadas [y, x] normalizadas:
Python
from google import genai
from google.genai import types

PROMPT = """
          Point to no more than 10 items in the image. The label returned
          should be an identifying name for the object detected.
          The answer should follow the json format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format
          normalized to 0-1000.
        """
client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open("my-image.png", 'rb') as f:
    image_bytes = f.read()

image_response = client.models.generate_content(
    model="gemini-robotics-er-2-preview",
    contents=[
        types.Part.from_bytes(
            data=image_bytes,
            mime_type='image/png',
        ),
        PROMPT
    ],
    config = types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(
            thinking_level=types.ThinkingLevel.HIGH
        )
    )
)

print(image_response.text)
REST
# First, ensure you have the image file locally.
# Encode the image to base64
IMAGE_BASE64=$(base64 -w 0 my-image.png)

# Set your Google Cloud project and location.
export PROJECT_ID="your-project-id"
export LOCATION="global"
export MODEL="gemini-robotics-er-2-preview"

curl -X POST \
  "https://aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL}:generateContent" \
  -H "Authorization: Bearer $(gcloud auth application-default print-access-token)" \
  -H "Content-Type: application/json" \
  -d '{
    "contents": [
      {
        "parts": [
          {
            "inlineData": {
              "mimeType": "image/png",
              "data": "'"${IMAGE_BASE64}"'"
            }
          },
          {
            "text": "Point to no more than 10 items in the image. The label returned should be an identifying name for the object detected. The answer should follow the json format: [{\"point\": [y, x], \"label\": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000."
          }
        ]
      }
    ],
    "generationConfig": {
      "thinkingConfig": {
        "thinkingLevel": "HIGH"
      }
    }
  }'
A saída será uma matriz JSON com objetos, cada um com um point
(coordenadas [y, x] normalizadas) e um label que identifica o objeto.
JSON
[
  {"point": [376, 508], "label": "small banana"},
  {"point": [287, 609], "label": "larger banana"},
  {"point": [223, 303], "label": "pink starfruit"},
  {"point": [435, 172], "label": "paper bag"},
  {"point": [270, 786], "label": "green plastic bowl"},
  {"point": [488, 775], "label": "metal measuring cup"},
  {"point": [673, 580], "label": "dark blue bowl"},
  {"point": [471, 353], "label": "light blue bowl"},
  {"point": [492, 497], "label": "bread"},
  {"point": [525, 429], "label": "lime"}
]
A imagem a seguir é um exemplo de como esses pontos podem ser exibidos:
Rastrear objetos em um vídeo
O Gemini Robotics ER 2 também pode analisar frames de vídeo para rastrear objetos ao longo do tempo.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your video
with open("my-video.mp4", 'rb') as f:
    video_bytes = f.read()

prompt = """
          Point to the red ball in every frame where it appears.
          The answer should follow the json format: [{"point": [y, x],
          "label": <label>}, ...]. The points are in [y, x] format
          normalized to 0-1000. Return one entry per frame that contains
          the object.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=video_bytes,
      mime_type='video/mp4',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
Detecção de objetos e caixas delimitadoras
Além de pontos, você pode pedir ao modelo para retornar caixas delimitadoras 2D, que fornecem mais detalhes espaciais para os objetos detectados.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

with open("my-image.png", 'rb') as f:
    image_bytes = f.read()

prompt = """
          Detect all objects in this image and return bounding boxes.
          The answer should follow the JSON format:
          [{"label": <label>, "y": <y_min>, "x": <x_min>,
            "y2": <y_max>, "x2": <x_max>}, ...]
          where coordinates are normalized to 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/png',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.LOW
      )
  )
)

print(image_response.text)
Trajetórias
O Gemini Robotics ER 2 pode gerar sequências de pontos que definem uma trajetória, útil para guiar o movimento do robô.
Este exemplo solicita uma trajetória para mover uma caneta vermelha para um organizador, incluindo uma estimativa dos pontos de passagem intermediários. O código foi reduzido para mostrar apenas o comando.
Python
prompt = """
          Generate a trajectory for the robotic arm to pick up the red pen
          and place it in the organizer. Return a list of waypoints as JSON:
          [{"step": <int>, "point": [y, x], "action": <description>}, ...]
          where coordinates are normalized to 0-1000.
        """
Abra espaço para um notebook
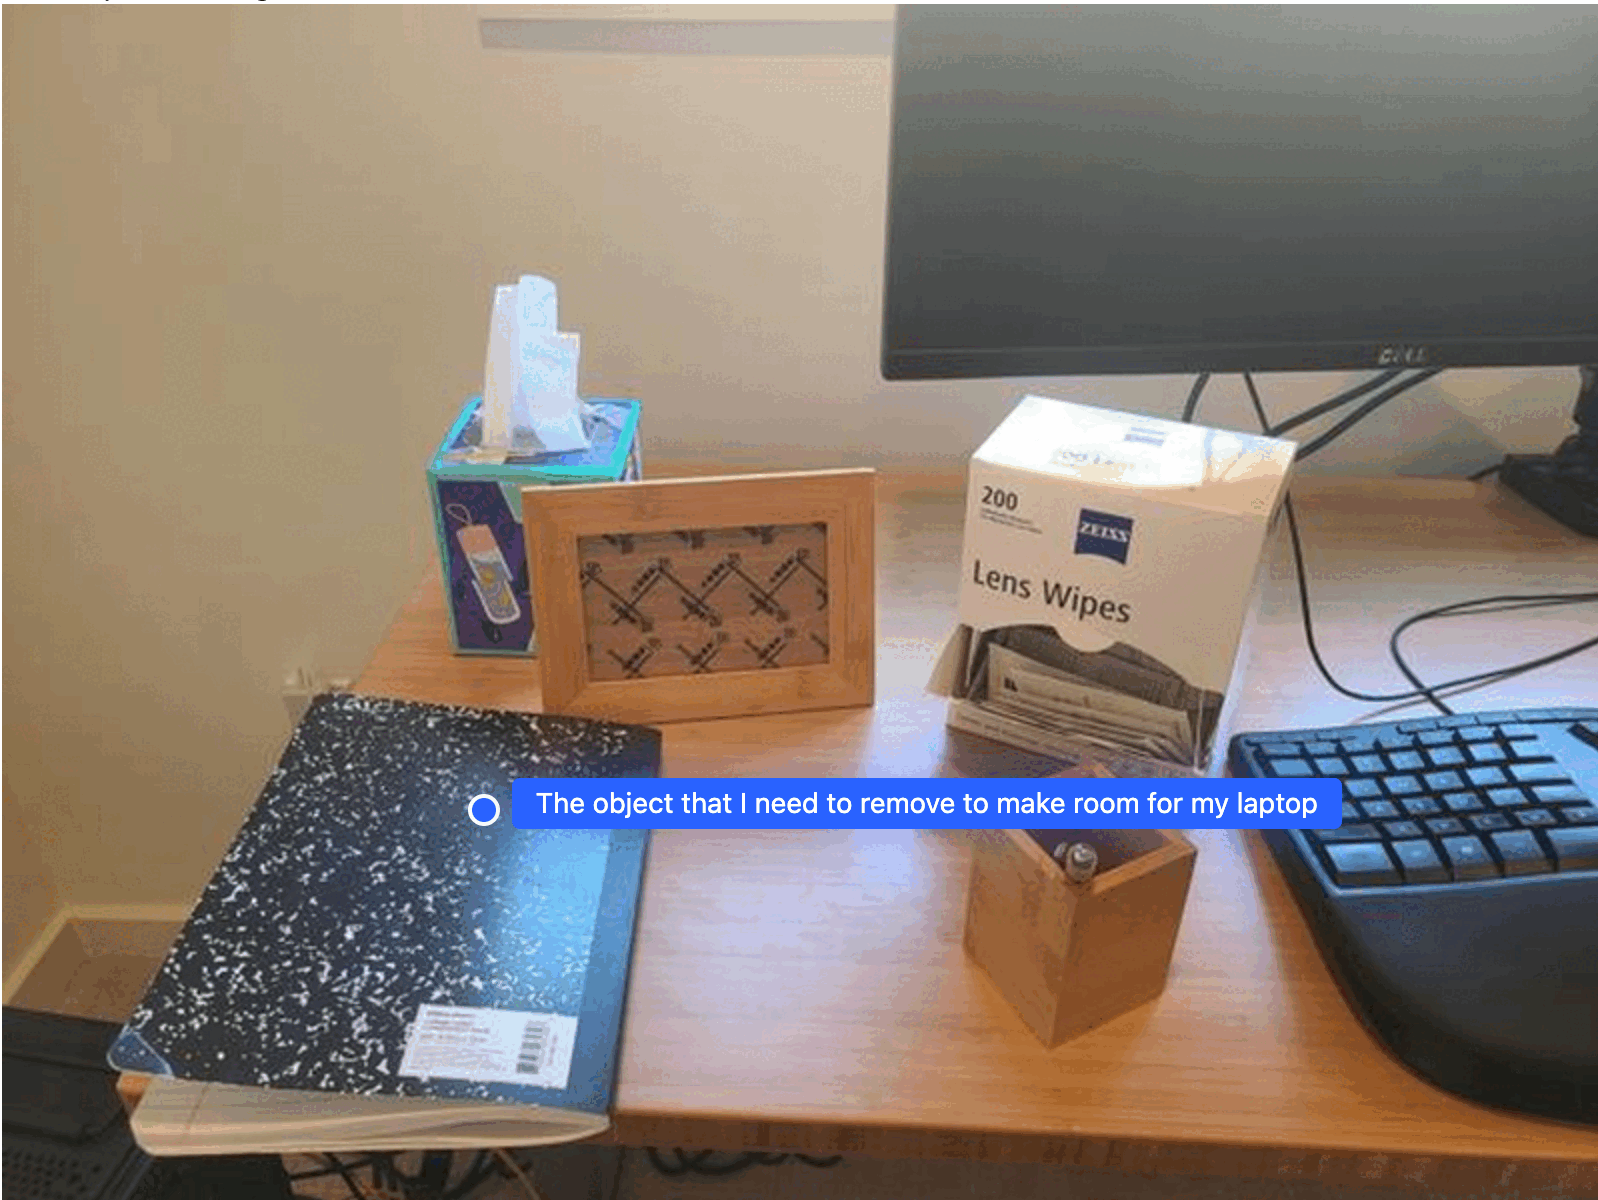
Este exemplo mostra como o Gemini Robotics ER 2 pode raciocinar sobre um espaço. O comando pede que o modelo identifique qual objeto precisa ser movido para criar espaço para outro item.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image
with open('path/to/image-with-objects.jpg', 'rb') as f:
    image_bytes = f.read()

prompt = """
          Point to the object that I need to remove to make room for my laptop
          The answer should follow the JSON format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/jpeg',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
A resposta contém uma coordenada 2D do objeto que responde à pergunta do usuário, neste caso, o objeto que deve ser movido para abrir espaço para um laptop.
[
  {"point": [672, 301], "label": "The object that I need to remove to make room for my laptop"}
]
Leve seu almoço
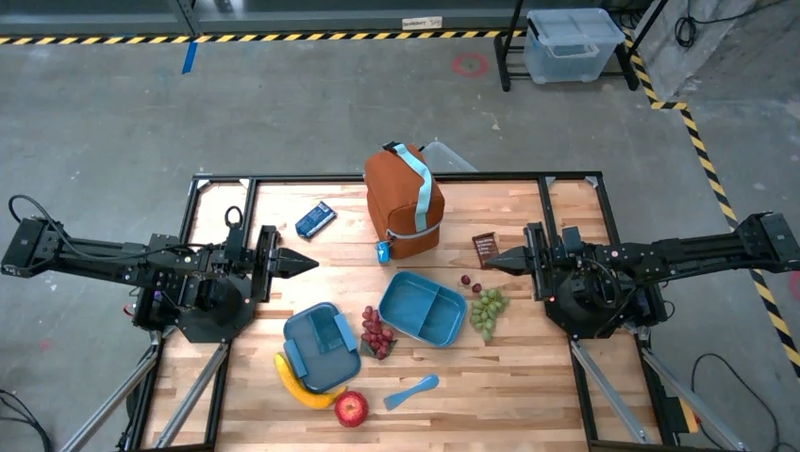
O modelo também pode fornecer instruções para tarefas de várias etapas e apontar para objetos relevantes para cada etapa. Este exemplo mostra como o modelo planeja uma série de etapas para preparar uma lancheira.
Python
from google import genai
from google.genai import types

client = genai.Client(
    enterprise=True,
    project="your-project-id",
    location="global",
)

# Load your image and set up your prompt
with open('path/to/image-of-lunch.jpg', 'rb') as f:
    image_bytes = f.read()

prompt = """
          Explain how to pack the lunch box and lunch bag. Point to each
          object that you refer to. Each point should be in the format:
          [{"point": [y, x], "label": }], where the coordinates are
          normalized between 0-1000.
        """

image_response = client.models.generate_content(
  model="gemini-robotics-er-2-preview",
  contents=[
    types.Part.from_bytes(
      data=image_bytes,
      mime_type='image/jpeg',
    ),
    prompt
  ],
  config = types.GenerateContentConfig(
      thinking_config=types.ThinkingConfig(
          thinking_level=types.ThinkingLevel.HIGH
      )
  )
)

print(image_response.text)
A resposta desse comando é um conjunto de instruções detalhadas sobre como preparar uma lancheira com base na imagem de entrada.
Imagem de entrada
Saída do modelo
Based on the image, here is a plan to pack the lunch box and lunch bag:

1.  **Pack the fruit into the lunch box.** Place the apple, banana, red grapes, and green grapes into the blue lunch box.
2.  **Add the spoon to the lunch box.** Put the blue spoon inside the lunch box as well.
3.  **Close the lunch box.** Secure the lid on the blue lunch box.
4.  **Place the lunch box inside the lunch bag.** Put the closed blue lunch box into the brown lunch bag.
5.  **Pack the remaining items into the lunch bag.** Place the blue snack bar and the brown snack bar into the brown lunch bag.

Here is the list of objects and their locations:
*   [{"point": [899, 440], "label": "apple"}]
*   [{"point": [814, 363], "label": "banana"}]
*   [{"point": [727, 470], "label": "red grapes"}]
*   [{"point": [675, 608], "label": "green grapes"}]
*   [{"point": [706, 529], "label": "blue lunch box"}]
*   [{"point": [864, 517], "label": "blue spoon"}]
*   [{"point": [499, 401], "label": "blue snack bar"}]
*   [{"point": [614, 705], "label": "brown snack bar"}]
*   [{"point": [448, 501], "label": "brown lunch bag"}]
A seguir
Para saber mais sobre o Gemini Robotics ER 2, consulte os seguintes recursos:
- Recursos agênticos: execução de código, leitura de instrumentos e anotação de imagens.
- Orquestração de tarefas: tarefas de longo alcance com APIs de robô personalizadas.
- Compreensão de vídeo: localização de momentos e classificação de progresso.
- Visão geral do Gemini Robotics ER 2: recursos e guia de início rápido.
- Informações sobre o modelo Gemini Robotics ER 2: especificações técnicas, limites de tokens e recursos compatíveis.