


멀티모달 임베딩 모델은 제공된 입력에 따라 다차원 벡터를 생성하며, 여기에는 이미지, 텍스트, 동영상 데이터의 조합이 포함될 수 있습니다. 그런 다음 임베딩 벡터를 이미지 분류 또는 동영상 콘텐츠 검토와 같은 후속 태스크에 사용할 수 있습니다.
이미지 및 텍스트 임베딩 벡터는 동일한 차원을 사용하는 동일한 시맨틱 공간에 위치합니다. 따라서 텍스트로 이미지를 검색하거나 이미지로 동영상을 검색하는 등의 사용 사례에 맞게 이러한 벡터를 서로 교환해서 사용할 수 있습니다.
텍스트 전용 임베딩 사용 사례의 경우 Gemini Enterprise Agent Platform 텍스트 임베딩 API를 대신 사용하는 것이 좋습니다. 예를 들어 텍스트 기반 시맨틱 검색, 클러스터링, 긴 형식 문서 분석, 기타 텍스트 검색 또는 질의 응답 사용 사례에 텍스트 임베딩 API가 더 적합할 수 있습니다. 자세한 내용은 텍스트 임베딩 가져오기를 참조하세요.
지원되는 모델
다음 모델을 사용하여 멀티모달 임베딩을 가져올 수 있습니다.
gemini-embedding-2multimodalembedding@001
권장사항
멀티모달 임베딩 모델을 사용할 때 다음 입력 측면을 고려하세요.
- 이미지의 텍스트 - 모델은 광학 문자 인식(OCR)과 유사하게 이미지의 텍스트를 구분할 수 있습니다. 이미지 콘텐츠 설명과 이미지 내 텍스트를 구분해야 하는 경우 프롬프트 엔지니어링을 사용하여 대상 콘텐츠를 지정하는 것이 좋습니다.
예를 들어 사용 사례에 따라 단순히 '고양이' 대신 '고양이 사진' 또는 '고양이' 텍스트'를 지정합니다.
'고양이' 텍스트
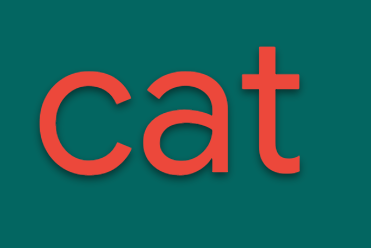
'고양이'라는 단어가 크고 굵은 글꼴로 렌더링됩니다.
고양이 사진
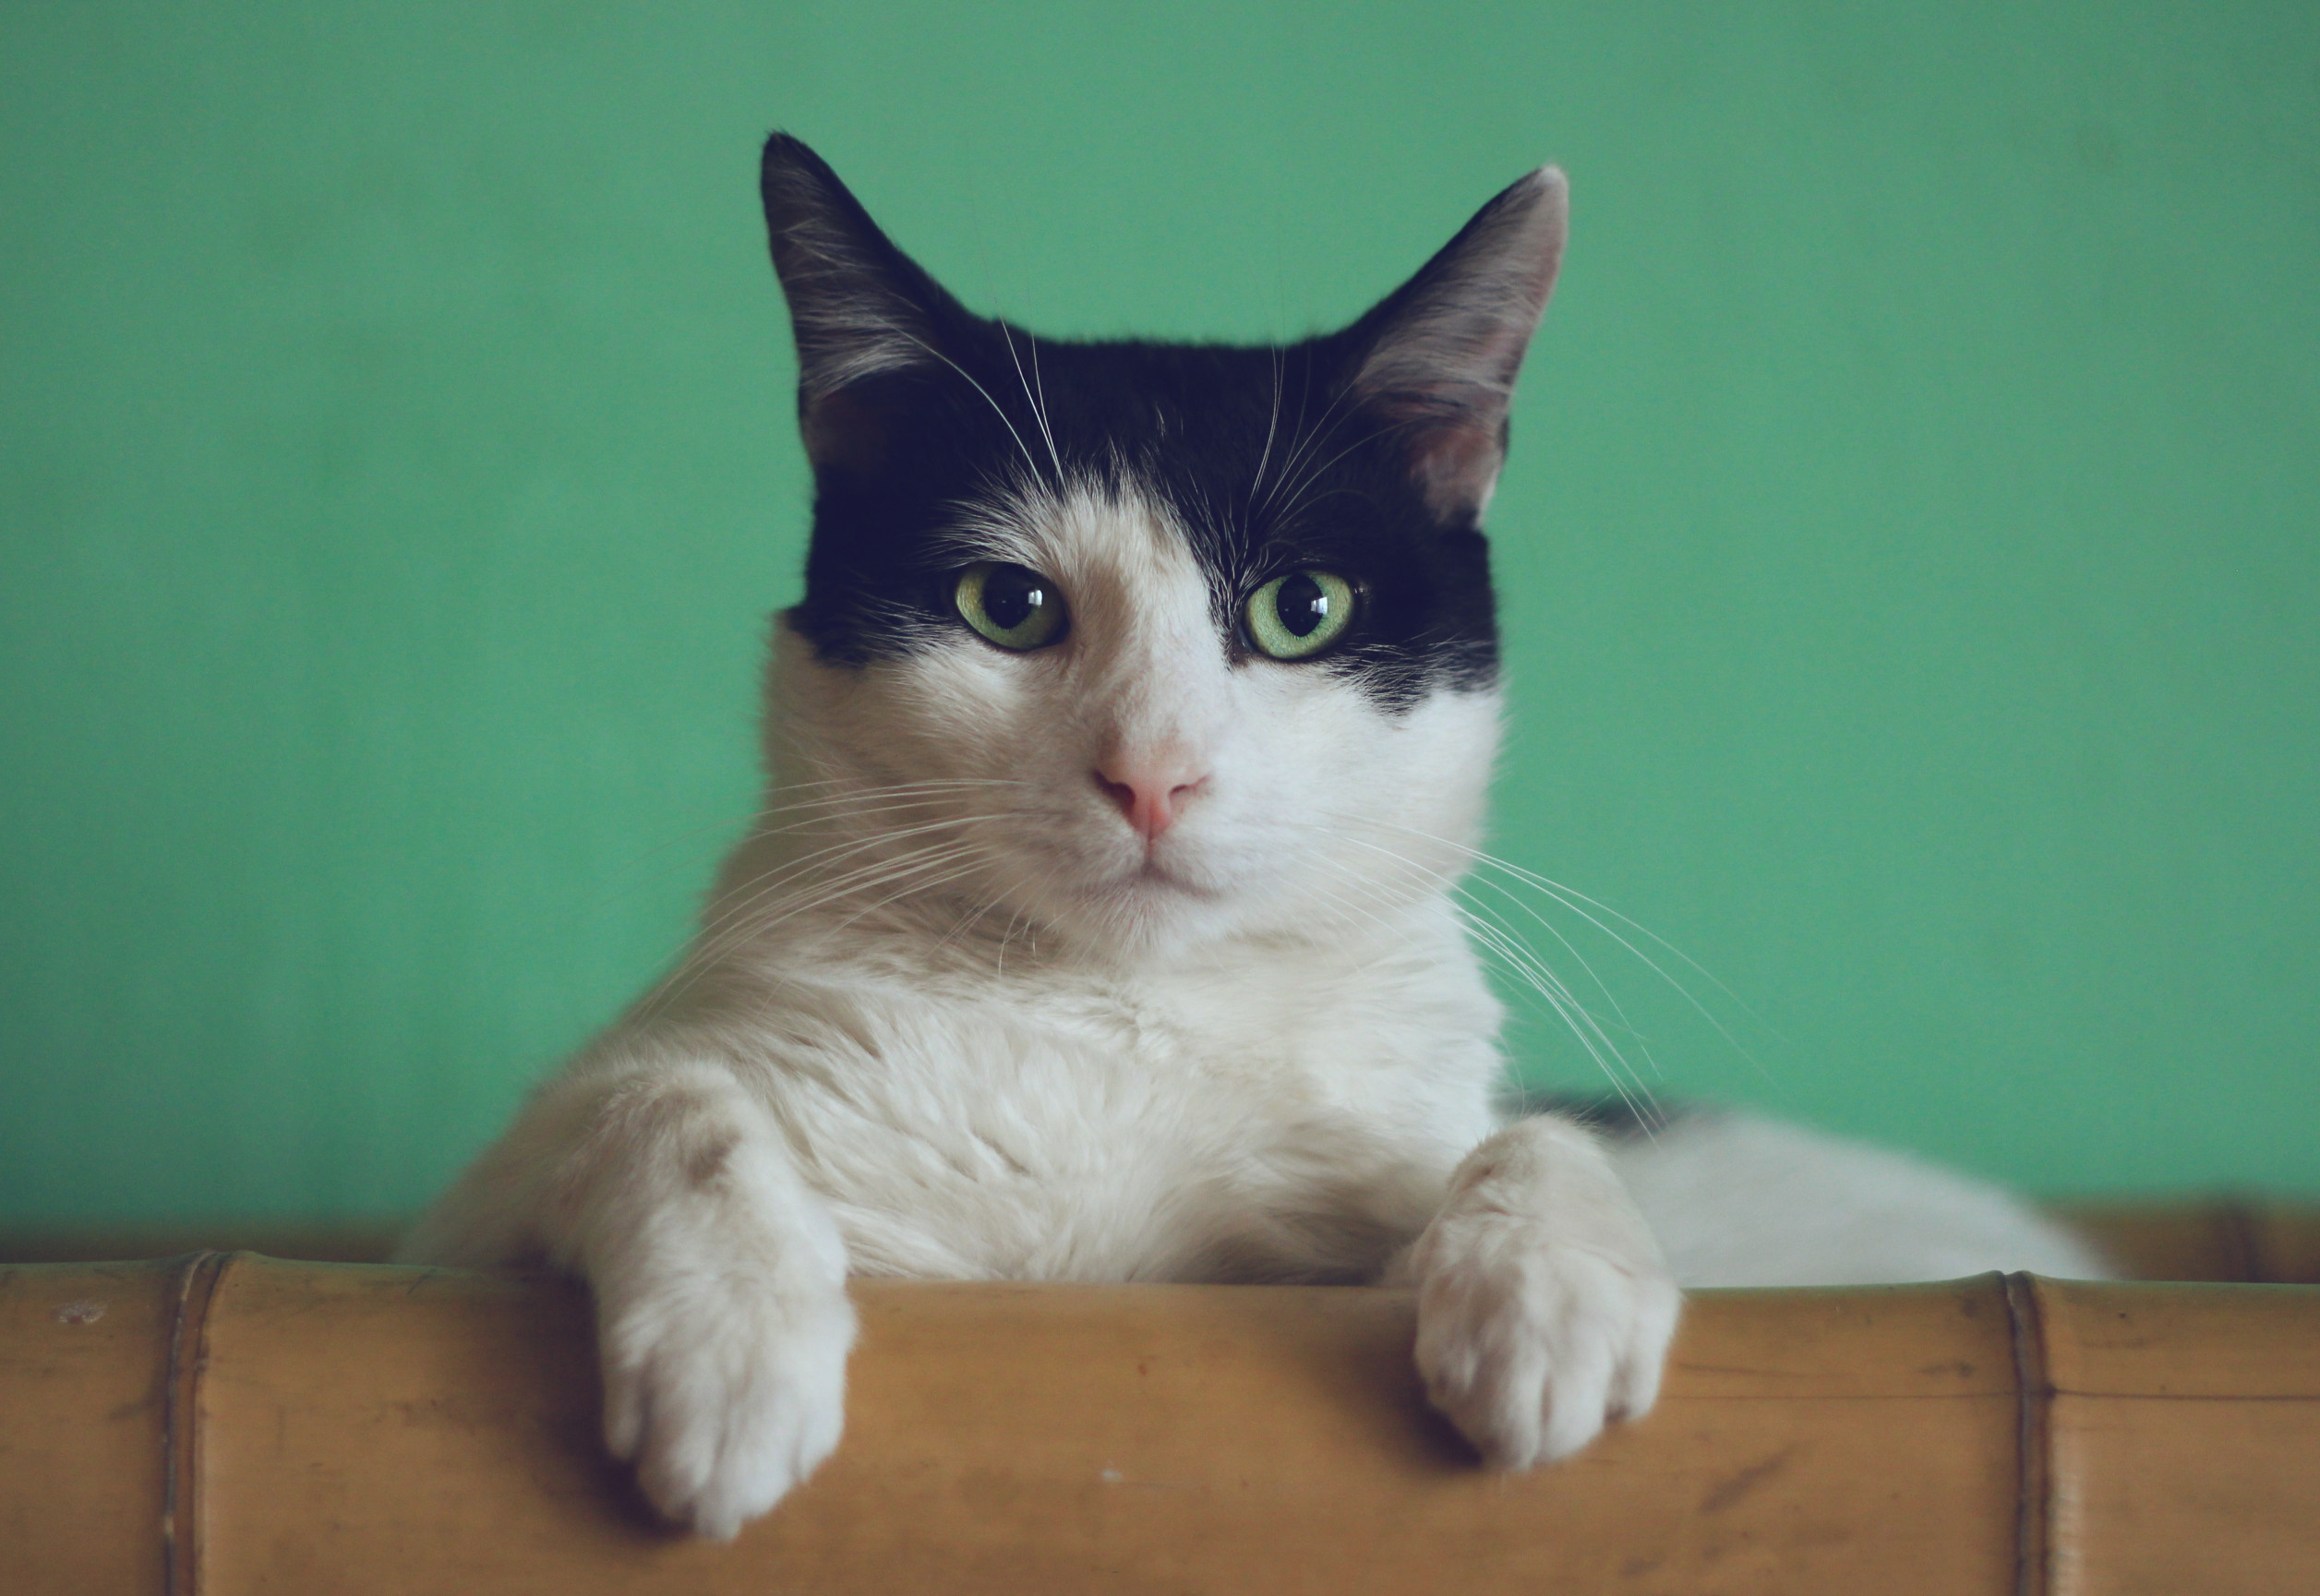
이미지 출처: Unsplash의 Manja Vitolic - 임베딩 유사성 - 임베딩의 내적은 보정된 확률이 아닙니다. 내적은 유사성 측정항목이며 사용 사례에 따라 점수 분포가 다를 수 있습니다. 따라서 품질을 측정할 때 고정 값 기준점을 사용하지 마세요. 그 대신 검색에 순위 접근 방식을 사용하거나 분류에 시그모이드를 사용합니다.
gemini-embedding-2 사용
gemini-embedding-2 모델은 이미지, 텍스트, 문서, 오디오, 동영상 모달에서 인터리브된 입력을 허용합니다.
성능 향상을 위한 작업 지침 지정
분류부터 문서 검색까지 다양한 작업에 임베딩을 사용할 수 있습니다. 올바른 작업 안내를 지정하면 의도한 관계에 맞게 삽입을 최적화하여 정확성과 효율성을 극대화할 수 있습니다.
다음 표에서는 gemini-embedding-2 모델을 사용하여 대칭 및 비대칭 사용 사례에 맞게 쿼리와 문서를 포맷하는 방법을 보여줍니다.
검색 사용 사례 (비대칭 형식)
| 사용 사례 | 쿼리 구조 | 문서 구조 |
|---|---|---|
| 검색어 | task: search result | query: {content} |
title: {title} | text: {content}제목이 없으면 title: none을 사용합니다. |
| 질의 응답 | task: question answering | query: {content} |
title: {title} | text: {content} |
| 사실확인 | task: fact checking | query: {content} |
title: {title} | text: {content} |
| 코드 검색 | task: code retrieval | query: {content} |
title: {title} | text: {content} |
단일 입력 사용 사례 (대칭 형식)
| 사용 사례 | 입력 구조 |
|---|---|
| 분류 | task: classification | query: {content} |
| 클러스터링 | task: clustering | query: {content} |
| 의미론적 유사도 | task: sentence similarity | query: {content}검색 또는 검색에는 사용하지 마세요. 시맨틱 텍스트 유사성을 위한 것입니다. |
Python의 사용 예
Python
# Generate embedding for a search query
def prepare_query(query):
    return f"task: search result | query: {query}"

# Generate embedding for a search document
def prepare_document(content, title=None):
    if title is None:
        title = "none"
    return f"title: {title} | text: {content}"

# Generate embedding for classification
def prepare_classification_input(content):
    return f"task: classification | query: {content}"
API 사용량
API 한도
gemini-embedding-2 모델을 사용할 때 다음 한도가 적용됩니다.
| 한도 | 값 및 설명 |
|---|---|
| 텍스트, 이미지, 문서, 동영상, 오디오 데이터 | |
| 입력 토큰 한도 | 8,192개 토큰 8,192개 토큰보다 긴 입력은 자동으로 잘립니다. 모든 모달리티는 총 8,192개의 토큰 컨텍스트 윈도우를 공유합니다. 토큰은 모달리티별로 다음과 같이 계산됩니다.
|
| 출력 차원 | 3072 (기본값, output_dimensionality 매개변수를 사용하여 구성 가능) |
| 이미지 제한 | 요청당 6개 이미지 |
| 이미지 형식 | JPEG, PNG, WebP, BMP, HEIC, HEIF, AVIF |
| 이미지 크기 | 이미지당 최대 16384x16384픽셀 |
| 문서 한도 | 요청당 파일 1개, 최대 6페이지 최상의 품질을 위해 PDF당 1페이지를 사용하는 것이 좋습니다. |
| 문서 형식 | |
| 동영상 및 오디오 데이터 | |
| 동영상 한도 | 요청당 동영상 1개, 최대 120프레임 120초 제한은 기본 1FPS 설정을 기준으로 합니다. FPS를 다르게 설정하면 지속 시간이 달라집니다.지속 시간 = 120 / FPS 기본적으로 동영상에 대한 오디오 추출은 사용 중지되어 있습니다. 오디오 트랙 추출 옵션을 사용 설정하면 길이는 최대 오디오 길이인 180초로 제한되며, 총 동영상 길이는 오디오 제한과 토큰 컨텍스트 윈도우 (8, 192개 토큰)에 의해 제한됩니다. |
| 동영상 형식 | 컨테이너: MOV, MP4 코덱: AV1, H264, H265, VP9 |
| 오디오 제한 | 요청당 180초 오디오 지원은 음성에 최적화되어 있습니다. 주변 소리와 음악이 최고 품질로 재생되지 않을 수 있습니다. |
| 오디오 형식 | MP3, WAV |
오디오 추출이 포함된 동영상 길이
모든 모달리티가 총 8, 192개의 토큰 컨텍스트 윈도우를 공유하므로 audio_track_extraction를 사용 설정하면 최대 동영상 길이가 달라집니다.
| 형식 | 토큰 수 |
|---|---|
| 오디오 | 초당 25개 토큰 |
| 동영상 프레임 | 프레임당 66개 토큰 |
| 타임스탬프 | 초당 10개 토큰 (초당 두 개의 타임스탬프가 'mm:ss' 형식으로 지정됨) |
| FPS | FPS 설정에 따라 결정됩니다 (기본값은 1). |
총 동영상 길이는 최대 180초 오디오 지원과 8,192 토큰 컨텍스트 윈도우에 의해 제한됩니다.
계산 예:
기본 샘플링 레이트가 1FPS인 동영상을 처리하고 오디오 추출을 사용 설정하면 다음이 적용됩니다.
- 소비율: 동영상 1초당 토큰 66개 (프레임 1개) + 토큰 25개 (오디오 1초) + 토큰 10개 (타임스탬프) = 토큰 101개가 소비됩니다.
- 최대 길이: 토큰 한도가 8,192인 경우 최대 길이는 약 8,192 / 101 ≈ 81초입니다.
입력이 컨텍스트 윈도우를 초과하면 초과된 부분이 자동으로 잘립니다.
멀티모달 임베딩 가져오기
REST
PROJECT_ID="YOUR_PROJECT_ID"
LOCATION="us"

curl -X POST \
  -H "Authorization: Bearer $(gcloud auth print-access-token)" \
  -H "Content-Type: application/json" \
  "https://aiplatform.${LOCATION}.rep.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/gemini-embedding-2:embedContent" \
  -d '{
  "content": {
    "parts": [
      {
        "text": "Whats this"
      },
      {
        "file_data": {
          "mime_type": "video/mp4",
          "file_uri": "gs://cloud-samples-data/generative-ai/video/pixel8.mp4"
        }
      }
    ]
  }
}'
Python
from google import genai
from google.genai import types

# Initialize the client.
client = genai.Client(vertexai=True, project="YOUR_PROJECT_ID", location="us")

content = types.Content(
    parts=[
        types.Part.from_text(text="Audio AI"),
        types.Part.from_uri(
            file_uri="gs://cloud-samples-data/generative-ai/audio/Chirp-3-Docs-Dive.mp3",
            mime_type="audio/mpeg",
        ),
    ],
)

response = client.models.embed_content(
    model="gemini-embedding-2",
    contents=[content]
)

print(response.embeddings[0].values)
위치
위치는 데이터가 영구 저장되는 위치를 제어하기 위해 요청에서 지정할 수 있는 리전입니다. 사용 가능한 리전 목록은 Agent Platform 위치를 참고하세요.
할당량
gemini-embedding-2의 할당량 한도를 확인하려면 에이전트 플랫폼 할당량 및 시스템 한도를 참고하세요.
측정기준
gemini-embedding-2 모델을 사용하는 경우 EmbedContentConfig에서 output_dimensionality 매개변수를 사용하여 더 낮은 차원을 지정할 수 있습니다.
다음 예시에서는 128 차원 벡터를 반환합니다. gemini-embedding-2의 경우 출력 임베딩이 기본이 아닌 차원에 대해 이미 L2 정규화되어 있습니다 (gemini-embedding-001와는 다름).
Python
import numpy as np
from google import genai
from google.genai import types

# Initialize the client.
client = genai.Client(vertexai=True, project="YOUR_PROJECT_ID", location="us")

content = types.Content(
    parts=[
        types.Part.from_uri(
            file_uri="gs://cloud-samples-data/generative-ai/audio/Chirp-3-Docs-Dive.mp3",
            mime_type="audio/mpeg",
        ),
    ],
)

response = client.models.embed_content(
    model="gemini-embedding-2",
    contents=[content],
    config=types.EmbedContentConfig(output_dimensionality=128),
)

embedding_values_np = np.array(response.embeddings[0].values)

print(f"Embedding length: {len(embedding_values_np)}")
print(f"Norm of embedding: {np.linalg.norm(embedding_values_np):.6f}") # Should be very close to 1
매개변수
기본 동영상 샘플링 속도는 초당 1프레임 (FPS)입니다. video_metadata를 사용하여 추가 매개변수를 추가할 수 있습니다.
Python
from google import genai
from google.genai import types

# Initialize the client.
client = genai.Client(vertexai=True, project="YOUR_PROJECT_ID", location="us")

content = types.Content(
    parts=[
        types.Part(
            file_data=types.FileData(
                file_uri="gs://cloud-samples-data/generative-ai/video/pixel8.mp4",
                mime_type="video/mp4",
            ),
            video_metadata=types.VideoMetadata(
                fps=0.5,
                start_offset="10s",
                end_offset="20s",
            ),
        ),
    ]
)

response = client.models.embed_content(
    model="gemini-embedding-2",
    contents=[content]
)

print(response.embeddings[0].values)
EmbedContentConfig에 추가 옵션이 있습니다.
| 옵션 | 유형 | 설명 |
|---|---|---|
output_dimensionality |
int |
출력 임베딩의 차원을 줄입니다. |
document_ocr |
bool |
문서 입력에 OCR을 사용 설정합니다. |
audio_track_extraction |
bool |
동영상 입력에서 오디오를 추출합니다. |
multimodalembedding@001 사용
텍스트 및 이미지 임베딩에 multimodalembedding@001 모델을 사용하는 경우 다음 한도가 적용됩니다.
| 한도 | 값 및 설명 |
|---|---|
| 텍스트 및 이미지 데이터 | |
| 프로젝트별 분당 최대 API 요청 수 | 리전에 따라 120~600 |
| 최대 텍스트 길이 | 토큰 32개(최대 32단어) 최대 텍스트 길이는 토큰 32개(약 32단어)입니다. 입력이 토큰 32개를 초과하면 모델은 내부적으로 입력을 이 길이로 줄입니다. |
| 언어 | 영어 |
| 이미지 형식 | BMP, GIF, JPG, PNG |
| 이미지 크기 | Base64로 인코딩된 이미지: 20MB(PNG로 트랜스코딩된 경우) Cloud Storage 이미지: 20MB(원본 파일 형식) 허용되는 최대 이미지 크기는 20MB입니다. 네트워크 지연 시간 증가를 방지하려면 작은 이미지를 사용합니다. 또한 모델은 이미지 크기를 512x512픽셀 해상도로 조정합니다. 따라서 더 높은 해상도의 이미지를 제공할 필요가 없습니다. |
| 동영상 데이터 | |
| 오디오 지원 | 해당 없음 - 이 모델에서는 동영상 임베딩을 생성할 때 오디오 콘텐츠를 고려하지 않습니다. |
| 동영상 형식 | AVI, FLV, MKV, MOV, MP4, MPEG, MPG, WEBM, WMV |
| 최대 동영상 길이(Cloud Storage) | 한도 없음. 하지만 한 번에 2분 분량의 콘텐츠만 분석할 수 있습니다. |
시작하기 전에
- Google Cloud 계정에 로그인합니다. Google Cloud를 처음 사용하는 경우 계정을 만들고 Google 제품의 실제 성능을 평가해 보세요. 신규 고객에게는 워크로드를 실행, 테스트, 배포하는 데 사용할 수 있는 $300의 무료 크레딧이 제공됩니다.
-
In the Google Cloud console, on the project selector page, select or create a Google Cloud project.
Roles required to select or create a project
- Select a project: Selecting a project doesn't require a specific IAM role—you can select any project that you've been granted a role on.
-
Create a project: To create a project, you need the Project Creator role
(
roles/resourcemanager.projectCreator), which contains theresourcemanager.projects.createpermission. Learn how to grant roles.
-
Verify that billing is enabled for your Google Cloud project.
Enable the Gemini Enterprise Agent Platform API, if it is not already enabled.
Roles required to enable APIs
To enable APIs, you need the
serviceusage.services.enablepermission. If you created the project, then you likely already have this permission through the Owner role (roles/owner). Otherwise, you can get this permission through the Service Usage Admin role (roles/serviceusage.serviceUsageAdmin). Learn how to grant roles.-
환경에 대한 인증을 설정하세요.
이 페이지의 샘플 사용 방법에 대한 탭을 선택하세요.
자바
로컬 개발 환경에서 이 페이지의 Java 샘플을 사용하려면 gcloud CLI를 설치 및 초기화한 다음 사용자 인증 정보로 애플리케이션 기본 사용자 인증 정보를 설정하세요.
-
Google Cloud CLI를 설치합니다.
-
외부 ID 공급업체 (IdP)를 사용하는 경우 먼저 제휴 ID로 gcloud CLI에 로그인해야 합니다.
-
gcloud CLI를 초기화한 후 업데이트하고 필요한 구성요소를 설치합니다.
gcloud components update
gcloud components install beta
-
로컬 셸을 사용하는 경우 사용자 계정에 대한 로컬 인증 사용자 인증 정보를 만듭니다.
gcloud auth application-default login
Cloud Shell을 사용하는 경우 이 작업을 수행할 필요는 없습니다.
인증 오류가 반환되고 외부 ID 공급업체(IdP)를 사용하는 경우 제휴 ID로 gcloud CLI에 로그인했는지 확인합니다.
자세한 내용은 Google Cloud 인증 문서의 로컬 개발 환경의 ADC 설정을 참고하세요.
Node.js
로컬 개발 환경에서 이 페이지의 Node.js 샘플을 사용하려면 gcloud CLI를 설치 및 초기화한 다음 사용자 인증 정보로 애플리케이션 기본 사용자 인증 정보를 설정하세요.
-
Google Cloud CLI를 설치합니다.
-
외부 ID 공급업체 (IdP)를 사용하는 경우 먼저 제휴 ID로 gcloud CLI에 로그인해야 합니다.
-
gcloud CLI를 초기화한 후 업데이트하고 필요한 구성요소를 설치합니다.
gcloud components update
gcloud components install beta
-
로컬 셸을 사용하는 경우 사용자 계정에 대한 로컬 인증 사용자 인증 정보를 만듭니다.
gcloud auth application-default login
Cloud Shell을 사용하는 경우 이 작업을 수행할 필요는 없습니다.
인증 오류가 반환되고 외부 ID 공급업체(IdP)를 사용하는 경우 제휴 ID로 gcloud CLI에 로그인했는지 확인합니다.
자세한 내용은 Google Cloud 인증 문서의 로컬 개발 환경의 ADC 설정을 참고하세요.
Python
로컬 개발 환경에서 이 페이지의 Python 샘플을 사용하려면 gcloud CLI를 설치하고 초기화한 후 사용자 인증 정보로 애플리케이션 기본 사용자 인증 정보를 설정합니다.
-
Google Cloud CLI를 설치합니다.
-
외부 ID 공급업체 (IdP)를 사용하는 경우 먼저 제휴 ID로 gcloud CLI에 로그인해야 합니다.
-
gcloud CLI를 초기화한 후 업데이트하고 필요한 구성요소를 설치합니다.
gcloud components update
gcloud components install beta
-
로컬 셸을 사용하는 경우 사용자 계정에 대한 로컬 인증 사용자 인증 정보를 만듭니다.
gcloud auth application-default login
Cloud Shell을 사용하는 경우 이 작업을 수행할 필요는 없습니다.
인증 오류가 반환되고 외부 ID 공급업체(IdP)를 사용하는 경우 제휴 ID로 gcloud CLI에 로그인했는지 확인합니다.
자세한 내용은 Google Cloud 인증 문서의 로컬 개발 환경의 ADC 설정을 참고하세요.
REST
로컬 개발 환경에서 이 페이지의 REST API 샘플을 사용하려면 gcloud CLI에 제공한 사용자 인증 정보를 사용합니다.
-
Google Cloud CLI를 설치합니다.
-
외부 ID 공급업체 (IdP)를 사용하는 경우 먼저 제휴 ID로 gcloud CLI에 로그인해야 합니다.
-
gcloud CLI를 초기화한 후 업데이트하고 필요한 구성요소를 설치합니다.
gcloud components update
gcloud components install beta
자세한 내용은 Google Cloud 인증 문서의 REST 사용을 위한 인증을 참조하세요.
-
- Python SDK를 사용하려면 Agent Platform SDK for Python 설치의 안내를 따르세요. 자세한 내용은 Agent Platform SDK for Python API 참고 문서를 확인하세요.
- (선택사항) 이 기능의 가격 책정을 검토합니다. 임베딩 가격 책정은 전송하는 데이터 유형(예: 이미지 또는 텍스트)과 특정 데이터 유형에 사용하는 모드(예: Video Plus, Video Standard, Video Essential)에 따라 달라집니다.
위치
위치는 데이터가 영구 저장되는 위치를 제어하기 위해 요청에서 지정할 수 있는 리전입니다. 사용 가능한 리전 목록은 Agent Platform 위치를 참고하세요.
오류 메시지
이 섹션에서는 발생할 수 있는 일반적인 오류 메시지를 설명합니다.
할당량 초과 오류
google.api_core.exceptions.ResourceExhausted: 429 Quota exceeded for
aiplatform.googleapis.com/online_prediction_requests_per_base_model with base
model: multimodalembedding. Please submit a quota increase request.
이 오류가 처음 발생하는 경우 Google Cloud 콘솔을 사용하여 프로젝트의 할당량 조정을 요청합니다. 조정을 요청하기 전에 다음 필터를 사용합니다.
Service ID: aiplatform.googleapis.commetric: aiplatform.googleapis.com/online_prediction_requests_per_base_modelbase_model:multimodalembedding
이미 할당량 조정 요청을 보낸 경우 다시 요청을 보내기 전에 기다립니다. 할당량을 더 늘려야 하는 경우 지속적인 할당량 조정에 대한 근거를 포함하여 할당량 조정 요청을 반복합니다.
저차원 임베딩 지정
사용되는 모델에 따라 임베딩 요청은 1408 부동 소수점 벡터 또는 3072 부동 소수점 벡터를 반환합니다. 텍스트 및 이미지 데이터에 더 낮은 차원 임베딩을 지정하여 지연 시간과 스토리지 또는 품질을 최적화할 수 있습니다. 저차원 임베딩은 스토리지 요구사항을 줄이고 후속 임베딩 작업 (예: 검색 또는 추천)의 지연 시간을 단축합니다. 고차원 임베딩은 이러한 작업에 대해 더 높은 정확성을 제공하지만 스토리지 요구 사항과 지연 시간이 더 높습니다.
다음 표에는 각 모델에 사용할 수 있는 기본 및 사용 가능한 하위 차원이 나와 있습니다.
| 모델 | 기본 측정기준 (가장 높음) | 지원되는 측정기준 (범위) | 권장 하위 측정기준 |
|---|---|---|---|
gemini-embedding-2 |
3072 | 128~3072 | 128, 768 또는 1536 |
multimodalembedding@001 |
1408 | 128~1408 | 128, 256, 512 |
다음 샘플을 사용하여 차원이 낮은 임베딩을 생성합니다.
REST
parameters.dimension 필드를 추가하면 더 낮은 차원에 액세스할 수 있습니다.
이 매개변수는 모델에 사용할 수 있는 측정기준 값을 허용합니다.
예를 들어 multimodalembedding@001 모델을 사용할 때 128, 256, 512 또는 1408를 지정할 수 있습니다. 응답에는 지정된 차원의 임베딩이 포함됩니다.
요청 데이터를 사용하기 전에 다음을 바꿉니다.
- PROJECT_ID: Google Cloud 프로젝트 ID
-
IMAGE_URI: 임베딩을 가져올 대상 이미지의 Cloud Storage URI입니다. 예를 들면
gs://my-bucket/embeddings/supermarket-img.png입니다.이미지를 base64 인코딩 바이트 문자열로 제공할 수도 있습니다.
[...] "image": { "bytesBase64Encoded": "B64_ENCODED_IMAGE" } [...] -
TEXT: 임베딩을 가져올 대상 텍스트. 예를 들면
a
      cat
입니다. -
EMBEDDING_DIMENSION: 임베딩 차원 수입니다. 값이 작을수록 이후 태스크에 이러한 임베딩을 사용할 때 지연 시간이 줄어들고 값이 높을수록 정확성이 높아집니다. 사용 가능한 값:
128,256,512,1408(기본값)
HTTP 메서드 및 URL:
POST https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict
JSON 요청 본문:
{
  "instances": [
    {
      "image": {
        "gcsUri": "IMAGE_URI"
      },
      "text": "TEXT"
    }
  ],
  "parameters": {
    "dimension": EMBEDDING_DIMENSION
  }
}
요청을 보내려면 다음 옵션 중 하나를 선택합니다.
curl
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
curl -X POST \
     -H "Authorization: Bearer $(gcloud auth print-access-token)" \
     -H "Content-Type: application/json; charset=utf-8" \
     -d @request.json \
     "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict"
PowerShell
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
$cred = gcloud auth print-access-token
$headers = @{ "Authorization" = "Bearer $cred" }

Invoke-WebRequest `
    -Method POST `
    -Headers $headers `
    -ContentType: "application/json; charset=utf-8" `
    -InFile request.json `
    -Uri "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict" | Select-Object -Expand Content
128차원:
{
  "predictions": [
    {
      "imageEmbedding": [
        0.0279239565,
        [...128 dimension vector...]
        0.00403284049
      ],
      "textEmbedding": [
        0.202921599,
        [...128 dimension vector...]
        -0.0365431122
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
256차원:
{
  "predictions": [
    {
      "imageEmbedding": [
        0.248620048,
        [...256 dimension vector...]
        -0.0646447465
      ],
      "textEmbedding": [
        0.0757875815,
        [...256 dimension vector...]
        -0.02749932
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
512차원:
{
  "predictions": [
    {
      "imageEmbedding": [
        -0.0523675755,
        [...512 dimension vector...]
        -0.0444030389
      ],
      "textEmbedding": [
        -0.0592851527,
        [...512 dimension vector...]
        0.0350437127
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
Python
Go
이미지 및 텍스트 임베딩 가져오기 (multimodalembedding@001)
다음 코드 샘플을 사용하여 이미지 및 텍스트 데이터가 포함된 임베딩 요청을 보냅니다. 이 샘플은 두 데이터 유형이 모두 포함된 요청을 보내는 방법을 보여 주지만 개별 데이터 유형에서 서비스를 사용할 수도 있습니다.
텍스트 및 이미지 임베딩 가져오기
REST
요청 데이터를 사용하기 전에 다음을 바꿉니다.
- PROJECT_ID: Google Cloud 프로젝트 ID
-
TEXT: 임베딩을 가져올 대상 텍스트. 예를 들면
a
      cat
입니다. - B64_ENCODED_IMG: 임베딩을 가져올 대상 이미지. 이미지는 base64 인코딩 바이트 문자열로 지정되어야 합니다.
HTTP 메서드 및 URL:
POST https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict
JSON 요청 본문:
{
  "instances": [
    {
      "text": "TEXT",
      "image": {
        "bytesBase64Encoded": "B64_ENCODED_IMG"
      }
    }
  ]
}
요청을 보내려면 다음 옵션 중 하나를 선택합니다.
curl
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
curl -X POST \
     -H "Authorization: Bearer $(gcloud auth print-access-token)" \
     -H "Content-Type: application/json; charset=utf-8" \
     -d @request.json \
     "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict"
PowerShell
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
$cred = gcloud auth print-access-token
$headers = @{ "Authorization" = "Bearer $cred" }

Invoke-WebRequest `
    -Method POST `
    -Headers $headers `
    -ContentType: "application/json; charset=utf-8" `
    -InFile request.json `
    -Uri "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict" | Select-Object -Expand Content
{
  "predictions": [
    {
      "textEmbedding": [
        0.010477379,
        -0.00399621,
        0.00576670747,
        [...]
        -0.00823613815,
        -0.0169572588,
        -0.00472954148
      ],
      "imageEmbedding": [
        0.00262696808,
        -0.00198890246,
        0.0152047109,
        -0.0103145819,
        [...]
        0.0324628279,
        0.0284924973,
        0.011650892,
        -0.00452344026
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
Python
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Python 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
Node.js
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Node.js 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
Java
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Java 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
Go
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Go 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
동영상, 이미지 또는 텍스트 임베딩 가져오기 (multimodalembedding@001)
임베딩 요청을 보낼 때 입력 동영상만 지정하거나 동영상, 이미지, 텍스트 데이터의 조합을 지정할 수 있습니다.
동영상 임베딩 모드
동영상 임베딩에는 Essential, Standard 또는 Plus와 같은 3가지 모드를 사용할 수 있습니다. 이 모드는 생성된 임베딩의 밀도에 해당하며 요청의 interval_sec 구성으로 지정될 수 있습니다. interval_sec 길이의 동영상 간격마다 임베딩이 생성됩니다. 최소 동영상 간격 길이는 4초입니다. 간격 길이가 120초를 초과하면 생성된 임베딩의 품질이 부정적인 영향을 받을 수 있습니다.
동영상 임베딩에 대한 가격 책정은 사용하는 모드에 따라 다릅니다. 자세한 내용은 가격 책정을 참조하세요.
다음 표에는 동영상 임베딩에 사용할 수 있는 세 가지 모드가 요약되어 있습니다.
| 모드 | 분당 최대 임베딩 수 | 동영상 임베딩 간격(최솟값) |
|---|---|---|
| Essential | 4 | 15 다음에 해당합니다. intervalSec >= 15 |
| Standard | 8 | 8 다음에 해당합니다. 8 <= intervalSec < 15 |
| Plus | 15 | 4 다음에 해당합니다. 4 <= intervalSec < 8 |
동영상 임베딩 권장사항
동영상 임베딩 요청을 보낼 때 다음 사항을 고려하세요.
길이가 다른 입력 동영상의 처음 2분에 대한 단일 임베딩을 생성하려면 다음
videoSegmentConfig설정을 사용합니다.request.json:// other request body content "videoSegmentConfig": { "intervalSec": 120 } // other request body content길이가 2분을 초과하는 동영상의 임베딩을 생성하려면
videoSegmentConfig에서 시작 시간과 종료 시간을 지정하는 요청 여러 개를 전송하면 됩니다.request1.json:// other request body content "videoSegmentConfig": { "startOffsetSec": 0, "endOffsetSec": 120 } // other request body contentrequest2.json:// other request body content "videoSegmentConfig": { "startOffsetSec": 120, "endOffsetSec": 240 } // other request body content동영상 임베딩 가져오기
다음 샘플을 사용하여 동영상 콘텐츠만의 임베딩을 가져옵니다.
REST
다음 예시에서는 Cloud Storage에 있는 동영상을 사용합니다. video.bytesBase64Encoded 필드를 사용하여 동영상의 base64 인코딩 문자열 표현을 제공할 수도 있습니다.
요청 데이터를 사용하기 전에 다음을 바꿉니다.
- PROJECT_ID: Google Cloud 프로젝트 ID
-
VIDEO_URI: 임베딩을 가져올 대상 동영상의 Cloud Storage URI입니다. 예를 들면
gs://my-bucket/embeddings/supermarket-video.mp4입니다.동영상을 base64 인코딩 바이트 문자열로 제공할 수도 있습니다.
[...] "video": { "bytesBase64Encoded": "B64_ENCODED_VIDEO" } [...] -
videoSegmentConfig(START_SECOND, END_SECOND, INTERVAL_SECONDS). 선택사항입니다. 임베딩이 생성될 특정 동영상 세그먼트 (초)입니다.예를 들면 다음과 같습니다.
[...]
"videoSegmentConfig": {
  "startOffsetSec": 10,
  "endOffsetSec": 60,
  "intervalSec": 10
}
[...]
이 구성을 사용하면 10초에서 60초 사이의 동영상 데이터가 지정되고 다음 10초 비디오 간격([10, 20), [20, 30), [30, 40), [40, 50), [50, 60))에 대한 임베딩이 생성됩니다. 이 동영상 간격(
"intervalSec": 10)은 Standard 동영상 임베딩 모드에 속하며 Standard 모드 가격 책정 요금이 부과됩니다.videoSegmentConfig를 생략하면 서비스에서 기본값"videoSegmentConfig": { "startOffsetSec": 0, "endOffsetSec": 120, "intervalSec": 16 }을 사용합니다. 이 동영상 간격("intervalSec": 16)은 Essential 동영상 임베딩 모드에 속하며 사용자에게 Essential 모드 가격 책정 요금이 부과됩니다.
HTTP 메서드 및 URL:
POST https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict
JSON 요청 본문:
{
  "instances": [
    {
      "video": {
        "gcsUri": "VIDEO_URI",
        "videoSegmentConfig": {
          "startOffsetSec": START_SECOND,
          "endOffsetSec": END_SECOND,
          "intervalSec": INTERVAL_SECONDS
        }
      }
    }
  ]
}
요청을 보내려면 다음 옵션 중 하나를 선택합니다.
curl
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
curl -X POST \
     -H "Authorization: Bearer $(gcloud auth print-access-token)" \
     -H "Content-Type: application/json; charset=utf-8" \
     -d @request.json \
     "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict"
PowerShell
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
$cred = gcloud auth print-access-token
$headers = @{ "Authorization" = "Bearer $cred" }

Invoke-WebRequest `
    -Method POST `
    -Headers $headers `
    -ContentType: "application/json; charset=utf-8" `
    -InFile request.json `
    -Uri "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict" | Select-Object -Expand Content
응답(7초 동영상, 지정된 videoSegmentConfig 없음):
{
  "predictions": [
    {
      "videoEmbeddings": [
        {
          "endOffsetSec": 7,
          "embedding": [
            -0.0045467657,
            0.0258095954,
            0.0146885719,
            0.00945400633,
            [...]
            -0.0023291884,
            -0.00493789,
            0.00975185353,
            0.0168156829
          ],
          "startOffsetSec": 0
        }
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
응답(59초 동영상, "videoSegmentConfig": { "startOffsetSec": 0, "endOffsetSec": 60, "intervalSec": 10 } 동영상 세그먼트 구성 포함):
{
  "predictions": [
    {
      "videoEmbeddings": [
        {
          "endOffsetSec": 10,
          "startOffsetSec": 0,
          "embedding": [
            -0.00683252793,
            0.0390476175,
            [...]
            0.00657121744,
            0.013023301
          ]
        },
        {
          "startOffsetSec": 10,
          "endOffsetSec": 20,
          "embedding": [
            -0.0104404651,
            0.0357737206,
            [...]
            0.00509833824,
            0.0131902946
          ]
        },
        {
          "startOffsetSec": 20,
          "embedding": [
            -0.0113538112,
            0.0305239167,
            [...]
            -0.00195809244,
            0.00941874553
          ],
          "endOffsetSec": 30
        },
        {
          "embedding": [
            -0.00299320649,
            0.0322436653,
            [...]
            -0.00993082579,
            0.00968887936
          ],
          "startOffsetSec": 30,
          "endOffsetSec": 40
        },
        {
          "endOffsetSec": 50,
          "startOffsetSec": 40,
          "embedding": [
            -0.00591270532,
            0.0368893594,
            [...]
            -0.00219071587,
            0.0042470959
          ]
        },
        {
          "embedding": [
            -0.00458270218,
            0.0368121453,
            [...]
            -0.00317760976,
            0.00595594104
          ],
          "endOffsetSec": 59,
          "startOffsetSec": 50
        }
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
Python
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Python 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
Go
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Go 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
이미지, 텍스트, 동영상 임베딩 가져오기
다음 샘플을 사용하여 동영상, 텍스트, 이미지 콘텐츠의 임베딩을 가져옵니다.
REST
다음 예시에서는 이미지, 텍스트, 동영상 데이터를 사용합니다. 요청 본문에서 이러한 데이터 유형의 조합을 사용할 수 있습니다.
또한 이 샘플에서는 Cloud Storage에 있는 동영상을 사용합니다. video.bytesBase64Encoded 필드를 사용하여 동영상의 base64 인코딩 문자열 표현을 제공할 수도 있습니다.
요청 데이터를 사용하기 전에 다음을 바꿉니다.
- PROJECT_ID: Google Cloud 프로젝트 ID
-
TEXT: 임베딩을 가져올 대상 텍스트. 예를 들면
a
      cat
입니다. -
IMAGE_URI: 임베딩을 가져올 대상 이미지의 Cloud Storage URI입니다. 예를 들면
gs://my-bucket/embeddings/supermarket-img.png입니다.이미지를 base64 인코딩 바이트 문자열로 제공할 수도 있습니다.
[...] "image": { "bytesBase64Encoded": "B64_ENCODED_IMAGE" } [...] -
VIDEO_URI: 임베딩을 가져올 대상 동영상의 Cloud Storage URI입니다. 예를 들면
gs://my-bucket/embeddings/supermarket-video.mp4입니다.동영상을 base64 인코딩 바이트 문자열로 제공할 수도 있습니다.
[...] "video": { "bytesBase64Encoded": "B64_ENCODED_VIDEO" } [...] -
videoSegmentConfig(START_SECOND, END_SECOND, INTERVAL_SECONDS). 선택사항입니다. 임베딩이 생성될 특정 동영상 세그먼트 (초)입니다.예를 들면 다음과 같습니다.
[...]
  "videoSegmentConfig": {
    "startOffsetSec": 10,
    "endOffsetSec": 60,
    "intervalSec": 10
  }
  [...]
이 구성을 사용하면 10초에서 60초 사이의 동영상 데이터가 지정되고 다음 10초 비디오 간격([10, 20), [20, 30), [30, 40), [40, 50), [50, 60))에 대한 임베딩이 생성됩니다. 이 동영상 간격(
"intervalSec": 10)은 Standard 동영상 임베딩 모드에 속하며 사용자에게 Standard 모드 가격 책정 요금이 부과됩니다.videoSegmentConfig를 생략하면 서비스에서 기본값"videoSegmentConfig": { "startOffsetSec": 0, "endOffsetSec": 120, "intervalSec": 16 }을 사용합니다. 이 동영상 간격("intervalSec": 16)은 Essential 동영상 임베딩 모드에 속하며 사용자에게 Essential 모드 가격 책정 요금이 부과됩니다.
HTTP 메서드 및 URL:
POST https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict
JSON 요청 본문:
{
  "instances": [
    {
      "text": "TEXT",
      "image": {
        "gcsUri": "IMAGE_URI"
      },
      "video": {
        "gcsUri": "VIDEO_URI",
        "videoSegmentConfig": {
          "startOffsetSec": START_SECOND,
          "endOffsetSec": END_SECOND,
          "intervalSec": INTERVAL_SECONDS
        }
      }
    }
  ]
}
요청을 보내려면 다음 옵션 중 하나를 선택합니다.
curl
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
curl -X POST \
     -H "Authorization: Bearer $(gcloud auth print-access-token)" \
     -H "Content-Type: application/json; charset=utf-8" \
     -d @request.json \
     "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict"
PowerShell
요청 본문을 request.json 파일에 저장하고 다음 명령어를 실행합니다.
$cred = gcloud auth print-access-token
$headers = @{ "Authorization" = "Bearer $cred" }

Invoke-WebRequest `
    -Method POST `
    -Headers $headers `
    -ContentType: "application/json; charset=utf-8" `
    -InFile request.json `
    -Uri "https://LOCATION-aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/LOCATION/publishers/google/models/multimodalembedding@001:predict" | Select-Object -Expand Content
{
  "predictions": [
    {
      "textEmbedding": [
        0.0105433334,
        -0.00302835181,
        0.00656806398,
        0.00603460241,
        [...]
        0.00445805816,
        0.0139605571,
        -0.00170318608,
        -0.00490092579
      ],
      "videoEmbeddings": [
        {
          "startOffsetSec": 0,
          "endOffsetSec": 7,
          "embedding": [
            -0.00673126569,
            0.0248149596,
            0.0128901172,
            0.0107588246,
            [...]
            -0.00180952181,
            -0.0054573305,
            0.0117037306,
            0.0169312079
          ]
        }
      ],
      "imageEmbedding": [
        -0.00728622358,
        0.031021487,
        -0.00206603738,
        0.0273937676,
        [...]
        -0.00204976718,
        0.00321615417,
        0.0121978866,
        0.0193375275
      ]
    }
  ],
  "deployedModelId": "DEPLOYED_MODEL_ID"
}
Python
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Python 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
Go
이 샘플을 사용해 보기 전에 Agent Platform 빠른 시작: 클라이언트 라이브러리 사용의 Go 설정 안내를 따르세요.
Agent Platform에 인증하려면 애플리케이션 기본 사용자 인증 정보를 설정합니다. 자세한 내용은 로컬 개발 환경의 인증 설정을 참조하세요.
다음 단계
- '멀티모달 검색이란? '비전을 사용한 LLM' 비즈니스 변경' 블로그 읽어보기
- 텍스트 전용 사용 사례(텍스트 기반 시맨틱 검색, 클러스터링, 긴 형식 문서 분석, 기타 텍스트 검색 또는 질문 답변 사용 사례)에 대한 자세한 내용은 텍스트 임베딩 가져오기 읽어보기
- Model Garden의 미리 학습된 모델 살펴보기
- 책임감 있는 AI 권장사항 및 Gemini Enterprise Agent Platform의 안전 필터 알아보기