

Use the Data Engineering Agent to build and modify data pipelines
The Data Engineering Agent in BigQuery and Dataform lets you build, modify, and manage data pipelines to load and process data in BigQuery. You can use natural language prompts to generate data pipelines from various data sources or adapt existing data pipelines to suit your data engineering needs.
The agent generates and organizes data pipeline code directly within Dataform repositories and operates in the Dataform workspace, so Dataform pipelines are automatically available to the agent. You can also interact with the agent using the Data Engineering Agent API, which uses the A2A protocol. For examples of prompts that you can use, see Sample prompts.
The Data Engineering Agent is powered by Gemini for Google Cloud and supports BigQuery AI and ML functions for building batch AI enrichment, semantic search, and machine learning pipelines in Dataform. For more information, see BigQuery AI and ML support.
Limitations
The Data Engineering Agent has the following limitations:
- The Data Engineering Agent doesn't support natural-language commands for the
following file types:
- Notebooks
- Data preparation
- The Data Engineering Agent cannot execute pipelines. You must review and run or schedule pipelines.
- The Data Engineering Agent cannot search any web links or URLs provided through instructions or direct prompts.
- When importing files in an
agent instruction file,
the
@import syntax supports only paths that begin with./,/, or a letter. - The data preview feature is supported only for
tables, declarations, or queries with the
hasOutputflag set totrue. - The Data Engineering Agent is subject to the general limitations of AI technology.
- When creating pipelines over Apache Iceberg external tables managed by the Lakehouse runtime catalog (formerly BigLake metastore), all Lakehouse runtime catalog limitations apply. Most notably, the agent cannot generate write mutations (such as
INSERT,UPDATE,DELETE, orMERGE) or DDL statements (such asCREATE TABLEorDROP TABLE) on Iceberg tables. For more information, see Apache Iceberg REST catalog endpoint concepts.
Before you begin
Before you use the Data Engineering Agent, perform the steps in this section.
Enable Gemini in BigQuery
Make sure that Gemini in BigQuery is enabled for your Google Cloud project. For more information, see Set up Gemini in BigQuery.
Enable the required APIs
console
Enable the following APIs in the Google Cloud console for the Google Cloud project you use with the Conversational Analytics API, if they aren't already enabled.
Enable the Gemini Data Analytics API
gcloud
To enable the Gemini Data Analytics API, the Gemini for Google Cloud
API, and the BigQuery API, if they aren't already enabled, use the
Google Cloud CLI and run the following
gcloud services enable commands:
gcloud services enable geminidataanalytics.googleapis.com --project=PROJECT_ID
gcloud services enable cloudaicompanion.googleapis.com --project=PROJECT_ID
gcloud services enable bigquery.googleapis.com --project=PROJECT_ID
Replace PROJECT_ID with your Google Cloud project ID.
Required roles
To get the permission that you need to use the Data Engineering Agent, ask your administrator to grant you the following IAM roles on the project:
- Dataform Code Editor (
roles/dataform.codeEditor) - BigQuery Job User (
roles/bigquery.jobUser) - Gemini Data Analytics Stateless Chat User (
roles/geminidataanalytics.dataAgentStatelessUser)
For more information about granting roles, see Manage access to projects, folders, and organizations.
This predefined role contains the
geminidataanalytics.locations.useDataEngineeringAgent
permission,
which is required to
use the Data Engineering Agent.
You might also be able to get this permission with custom roles or other predefined roles.
For details on the required roles to query Apache Iceberg tables, see Required roles for Lakehouse Apache Iceberg support.
Knowledge Catalog integration prerequisites
To get the permission that
you need to integrate the Data Engineering Agent with Knowledge Catalog,
ask your administrator to grant you the
Dataplex Catalog Editor (roles/dataplex.catalogEditor) IAM role on the project.
For more information about granting roles, see Manage access to projects, folders, and organizations.
This predefined role contains the
geminidataanalytics.locations.useDataEngineeringAgent
permission,
which is required to
integrate the Data Engineering Agent with Knowledge Catalog.
You might also be able to get this permission with custom roles or other predefined roles.
If you use a custom service account to run pipelines, you must grant the
Dataplex Catalog Editor
(roles/dataplex.catalogEditor) role on the project or @bigquery entry group.
Additionally, you must enable the
Dataplex API.
Encrypt data with Cloud Key Management Service keys
You can encrypt data at the dataset or project level with the default customer-managed Cloud Key Management Service keys in BigQuery. For more information, see Set a dataset default key and Set a project default key.
You can encrypt pipeline code at the project level by setting a default Dataform Cloud Key Management Service key.
Configure VPC Service Controls perimeters
If you use VPC Service Controls, you must configure the perimeter to protect Dataform, BigQuery, and Conversational Analytics API. For more information, see Dataform, BigQuery, and Conversational Analytics API.
Generate a data pipeline with the Data Engineering Agent
To use the Data Engineering Agent in BigQuery, select one of the following options:
BigQuery pipelines
You can use the Data Engineering Agent in the BigQuery pipelines interface by doing the following:
Go to the BigQuery page.
In the query editor, click arrow_drop_down Create new > Pipeline.
In the pipeline interface, click Ask agent.
In the Ask agent field, enter a natural language prompt to generate a data pipeline—for example:
  Create dimension tables for a taxi trips star schema from
  new_york_taxi_trips.tlc_green_trips_2022. Generate surrogate keys and all
  the descriptive attributes.
After you enter a prompt, click Send.
The Data Engineering Agent generates a data pipeline based on your prompt.
The Data Engineering Agent generates a proposed draft of a data pipeline. You can click a pipeline node to review the generated SQLX query. To apply the agent-suggested data pipeline, click Apply.
Dataform
You can use the Data Engineering Agent in Dataform by doing the following:
Go to Dataform.
Select a repository.
Select or create a development workspace.
In the workspace, click Ask Agent.
In the Ask agent prompt that appears, enter a natural language prompt to generate a data pipeline—for example:
  Create dimension tables for a taxi trips star schema from
  new_york_taxi_trips.tlc_green_trips_2022. Generate surrogate keys and all
  the descriptive attributes.
After you enter a prompt, click Send.
After your prompt is sent, the Data Engineering Agent generates a data pipeline and modifies Dataform SQLX files based on your prompt. The agent applies these changes directly to your workspace files.
Edit a data pipeline
To edit your data pipeline, click Ask agent, and then enter a prompt that suggests a change to the data pipeline.

Review the changes proposed by the Data Engineering Agent, and then click Apply to apply the changes.
You can also edit a SQLX query manually by selecting a pipeline node and then clicking Open.
Review a data pipeline
You can click a pipeline node in a data pipeline generated by the Data Engineering Agent to review it.
- The Configuration tab shows the generated SQLX query associated with the node.
- The Data preview tab shows the input and output table of the file. You can preview your data transformation through this node by clicking Run task to run the task with or without dependencies.
Troubleshoot data pipeline errors
If you encounter any errors when you generate the data pipeline, complete all prerequisites to run the Data Engineering Agent.
Errors in your pipeline appear as failed execution runs in the Executions tab. To use the Data Engineering Agent to run a root cause analysis and get troubleshooting recommendations, do the following:
In the Executions tab, click the status of a failed execution run, and then click Investigate.
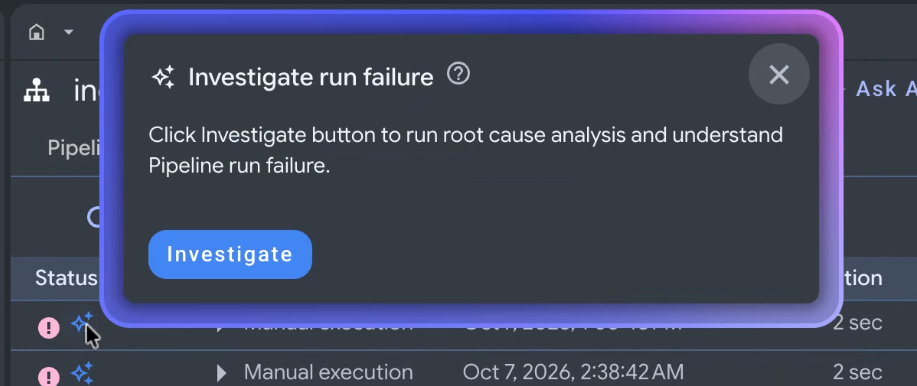
The Ask agent panel opens with a request that prompts the agent to perform a root cause analysis for the failed run.
Review the troubleshooting report from the agent.
The troubleshooting report includes more information about the errors in the pipeline generation process. You can prompt the agent to fix these pipeline errors based on the report.
Create agent instructions
Agent instructions are natural-language instructions for the Data Engineering Agent that let you store persistent instructions so the agent follows a set of custom, predefined rules. Use agent instructions if you want the agent's results to be consistent across your organization—for example, with naming conventions or to enforce a style guide.
You can create a GEMINI.MD context
file
as an agent instruction file for the Data Engineering Agent. You can create agent
instruction files to use in your local workspace, or you can use the same
instruction files across multiple data pipelines with an external repository.
To create agent instructions, do the following:
- Under Ask agent, click Pipeline instructions.
- In the Instructions for pipeline pane, click Create instructions file.
In the
GEMINI.MDfile that appears, enter your instructions in natural language.The following example shows an agent instruction file with several rules:
  1. All event-specific tables MUST be prefixed with `cs_event_`.
  2. The primary key for any player activity table is a composite key of `player_id` and `event_timestamp_micros`.
  3. Filter out any player actions where `mana_spent` is greater than `max_mana_pool`. This is considered a data anomaly.
Click Save.
For information on how best to structure your agent instruction files, see Best practices with agent instruction files.
Load agent instructions from an external repository
To reuse a set of agent instructions across multiple data pipelines, link an external repository:
- Under Ask agent, click Pipeline instructions.
- Under External repository, select Use instructions from external repository.
- In the fields provided, specify a repository that contains agent instructions you want to use with your data pipeline.
- Click Save.
BigQuery AI and ML support
The Data Engineering Agent supports many BigQuery AI,
ML, and object functions and statements in the generated Dataform SQLX pipelines and in the agent instruction
files (GEMINI.MD) that you create, including the
following:
AI.FORECASTAI.DETECT_ANOMALIESAI.CAUSAL_EFFECTAI.EVALUATEAI.KEY_DRIVERSAI.GENERATEAI.GENERATE_TABLEAI.GENERATE_EMBEDDINGAI.IFAI.SCOREAI.CLASSIFYAI.SEARCHAI.SIMILARITYAI.AGGCREATE MODEL(includingLOGISTIC_REG,KMEANS,CONTRIBUTION_ANALYSIS, remote models (REMOTE WITH CONNECTION), and theTRANSFORMclause)CREATE TABLEwith autonomous embedding generation (AI.EMBED)ML.PREDICTML.EVALUATEML.CORRELATIONML.DETECT_CHANGE_POINTSML.GET_INSIGHTSML.SEASONALITYML.TRENDML.VALIDATE_DATA_DRIFTVECTOR_SEARCHOBJ.GET_ACCESS_URL
To execute Dataform pipelines that contain generative AI
functions or remote models, the service account or user running the pipeline
must have the required permissions to run generative AI
queries. When the Data Engineering
Agent generates DDL statements such as CREATE MODEL or CREATE TABLE with
autonomous embedding generation, it configures them as Dataform
operations actions (type: "operations") with hasOutput: true so that
downstream pipeline nodes can reference them using ${ref("RESOURCE_NAME")}.
The agent only uses the AI.SEARCH function on tables that have autonomous
embedding generation enabled.
When working with ObjectRef functions, the user must also have delegated
access to the underlying Cloud Storage bucket. For more information, see
Delegated access.
For more information about AI and ML functions in BigQuery, see Introduction to AI in BigQuery.
Use cases
To activate supported AI and ML functions in your data pipelines, use them in the following ways:
Prompt the Data Engineering Agent to build or modify a pipeline—for example, if you are a data engineer building a scheduled ELT pipeline that enriches raw text, extracts structured fields from unstructured documents, or scores new records—the agent generates the appropriate Dataform SQLX files and dependency graph.
Define persistent pipeline rules in an agent instruction file (
GEMINI.MD)—for example, to standardize model endpoints, connection IDs, or default anomaly thresholds across your organization's pipelines.
The following table shows examples of prompts that activate the use of AI or ML functions for batch data pipelining:
| Use case | Sample usage | Public dataset |
|---|---|---|
Batch text summarization (AI.GENERATE) |
"Create a staging table from bigquery-public-data.bbc_news.fulltext for 'sports' articles and add a column that summarizes the body column in 1-2 sentences." |
bigquery-public-data.bbc_news.fulltext |
Structured schema extraction (AI.GENERATE_TABLE) |
"Build a pipeline table that extracts a structured schema (company_name STRING, key_topic STRING, is_earnings_related BOOL) from the body column of business articles in bigquery-public-data.bbc_news.fulltext." |
bigquery-public-data.bbc_news.fulltext |
Multimodal object enrichment (OBJ.GET_ACCESS_URL) |
"Create an external object table over our Cloud Storage product images bucket and build a downstream table that generates an image_description and entities array for each image using OBJ.GET_ACCESS_URL." |
Cloud Storage object table (for example, gs://cloud-samples-data/bigquery/tutorials/cymbal-pets/images/*.png) |
Semantic data filtering (AI.IF) |
"Create a cleaned table of tech articles from bigquery-public-data.bbc_news.fulltext, filtering to keep only rows that discuss breakthroughs in artificial intelligence." |
bigquery-public-data.bbc_news.fulltext |
Batch sentiment scoring (AI.SCORE) |
"Create an enriched table from bigquery-public-data.bbc_news.fulltext for the entertainment category with a numeric sentiment_score column rating the degree of positive sentiment." |
bigquery-public-data.bbc_news.fulltext |
Automated taxonomy classification (AI.CLASSIFY) |
"Using the film reviews in bigquery-public-data.imdb.reviews, automatically categorize each review into our editorial taxonomy tiers for Narrative Archetype (e.g., 'Character Study', 'Action Spectacle', 'Psychological Thriller') and Viewing Mood (e.g., 'Dark & Gritty', 'Uplifting', 'Suspenseful'). Write the results along with movie metadata into a curated table." |
bigquery-public-data.imdb.reviews |
Grouped semantic rollup (AI.AGG) |
"For each film in bigquery-public-data.imdb.reviews, aggregate all audience feedback across hundreds of reviews into a consolidated executive summary highlighting the consensus critical reception, top praise, and recurring viewer complaints. Group the results by movie_id and title alongside metrics like total review counts and average rating to produce a unified movie-level intelligence table for studio executives and marketing teams." |
bigquery-public-data.imdb.reviews |
Batch embedding generation (AI.GENERATE_EMBEDDING) |
"Create a pipeline node that generates vector embeddings for the review column in bigquery-public-data.imdb.reviews and materializes them into a feature table." |
bigquery-public-data.imdb.reviews |
Autonomous embeddings and semantic search (AI.EMBED, AI.SEARCH) |
"Create a table of movie reviews with autonomous embedding generation enabled on the review column, and create a downstream reporting table that finds the top 10 reviews matching 'tension-building psychological thriller'." | bigquery-public-data.imdb.reviews |
Scheduled demand forecasting (AI.FORECAST) |
"Create a daily reporting table that forecasts the number of bikeshare trips per day for the next 30 days from bigquery-public-data.san_francisco_bikeshare.bikeshare_trips." |
bigquery-public-data.san_francisco_bikeshare.bikeshare_trips |
Pipeline anomaly detection (AI.DETECT_ANOMALIES) |
"Build a monitoring table that detects daily trip volume anomalies in 2018 using 2017 as the historical baseline from bigquery-public-data.san_francisco_bikeshare.bikeshare_trips." |
bigquery-public-data.san_francisco_bikeshare.bikeshare_trips |
Automated key driver reporting (AI.KEY_DRIVERS) |
"Create a reporting table that identifies the key drivers for changes in trip volume between 2017 and 2018 using bigquery-public-data.austin_bikeshare.bikeshare_trips." |
bigquery-public-data.austin_bikeshare.bikeshare_trips |
Change point detection (ML.DETECT_CHANGE_POINTS) |
"Create a table that detects structural change points in daily trip volume from bigquery-public-data.san_francisco_bikeshare.bikeshare_trips." |
bigquery-public-data.san_francisco_bikeshare.bikeshare_trips |
Model training with preprocessing, evaluation & batch scoring (CREATE MODEL, TRANSFORM, ML.EVALUATE, ML.PREDICT) |
"Create a Dataform pipeline on bigquery-public-data.ml_datasets.census_adult_income that trains a logistic regression model with a TRANSFORM clause to predict income_bracket, evaluates the model in an evaluation table, and outputs batch predictions to a scoring table." |
bigquery-public-data.ml_datasets.census_adult_income |
Customer segmentation (CREATE MODEL with KMEANS) |
"Create a pipeline that trains a K-means clustering model on penguin physical measurements from bigquery-public-data.ml_datasets.penguins and assigns cluster IDs to a segmented output table." |
bigquery-public-data.ml_datasets.penguins |
Automated data drift validation (ML.VALIDATE_DATA_DRIFT) |
"Add a monitoring table to the pipeline that validates feature drift between our 2017 baseline trips table and 2018 serving trips table from bigquery-public-data.san_francisco_bikeshare.bikeshare_trips." |
bigquery-public-data.san_francisco_bikeshare.bikeshare_trips |
Sample prompts
The following sections provide sample prompts you can use with the Data Engineering Agent to develop your data pipeline.
Aggregate existing data into a new table
With this prompt, the Data Engineering Agent uses the schema and samples to infer data grouping by key. The agent typically sets up a new table configuration with table and column descriptions.
  Create a daily sales report from the
  bigquery-public-data.thelook_ecommerce.order_items table into a
  reporting.daily_sales_aggregation table.
Create a new derived column and add data quality checks to the new table
This prompt shows how to add a table and a column, and specify quality checks to the table at the same time:
  Create a new table named staging.products from
  bigquery-public-data.thelook_ecommerce.products and add a calculated column
  named gross_profit, which is the retail_price minus the cost.


  Also, add the following assertions: ID must not be null and must be unique.
  The retail_price must be greater than or equal to the cost. The department
  column can only contain 'Men' or 'Women'.
Create UDFs as part of the model definition
The Data Engineering Agent can also set up the DDL to create user-defined functions (UDFs). While the agent won't actually create the UDF, you can create the UDF by running the data pipeline. These UDFs can be used in model definitions in your data pipeline.
  Create a user-defined function (UDF) named get_age_group that takes an integer
  age as input and returns a string representing the age group ('Gen Z',
  'Millennial', 'Gen X', 'Baby Boomer').


  Use this UDF on the age column from the
  bigquery-public-data.thelook_ecommerce.users table to create a new view called
  reporting.user_age_demographics that includes user_id, age, and the calculated
  age_group.
Enrich unstructured data and run batch ML predictions in a pipeline
This prompt shows how to combine behavioral feature engineering, BigQuery ML classification modeling, and generative AI personalization across chained Dataform pipeline nodes:
  Create a multi-step Dataform pipeline using
  bigquery-public-data.thelook_ecommerce.users and bigquery-public-data.thelook_ecommerce.orders:

  1. Create a staging table on a sample of customers to engineer retention
     features (tenure, lifetime spend, recency) and label churn based on
     inactivity over the past 90 days.
  2. Train a BigQuery ML logistic regression model on those behavioral features
     to predict churn risk.
  3. Create a final table that scores customer churn probabilities and drafts
     personalized, 3-sentence win-back emails with purchase-tailored discounts
     for the 20 customers at highest risk of churning.
Best practices
To improve results when working with the Data Engineering Agent and Dataform, we recommend that you do the following:
Use agent instructions for common requests. If you commonly apply certain techniques, or if you frequently make the same corrections to the agent, use agent instructions as a centralized location to store common instructions and requests.
Utilize agent plans. Agent plans can be helpful to break down complex pipeline tasks. Agent plans can also show you agent assumptions and intentions, so we recommend reviewing those plans to make sure the agent is provided the correct context.
After reviewing a plan, you can edit the plan by prompting the Data Engineering Agent with feedback and changes. For example:
In the plan, ensure that all of the intermediate tables are views.
In some cases, it can be helpful to ask the agent to generate a plan that doesn't need your explicit approval. The act of making the agent plan forces the Data Engineering Agent to break down its actions, which often leads to better outcomes. You can force the agent to generate a plan and execute it automatically. For example:
Create a plan for a pipeline that finds the
top N pick up and drop off locations in NYC. You have my explicit pre-approval
to go ahead and execute this plan.
Write clearly. State your request clearly and avoid being vague. Where possible, provide source and destination data sources when prompting, as shown in the following example:
  Extract data from the sales.customers table in the us_west_1 region, and load
  it into the reporting.dim_customers table in BigQuery. Match the schema of the
  destination table.
Provide direct and scoped requests. Ask one question at a time, and keep prompts concise. For prompts with more than one question, itemize each distinct part of the question to improve clarity, as shown in the following example:
  1. Create a new table named staging.events_cleaned. Use raw.events as the
     source. This new table should filter out any records where the user_agent
     matches the pattern '%bot%'. All original columns should be included.

  2. Next, create a table named analytics.user_sessions. Use
     staging.events_cleaned as the source. This table should calculate the
     duration for each session by grouping by session_id and finding the
     difference between the MAX(event_timestamp) and MIN(event_timestamp).
Provide explicit instructions and emphasize key terms. You can add emphasis to key terms or concepts in your prompts and label certain requirements as important, as shown in the following example:
  When creating the staging.customers table, it is *VERY IMPORTANT* that you
  transform the email column from the source table bronze.raw_customers.
  Coalesce any NULL values in the email column to an empty string ''.
Specify the order of operations. For ordered tasks, structure your prompt in lists, where listed items are divided into small, focused steps, as shown in the following example:
  Create a pipeline with the following steps:
  1. Extract data from the ecomm.orders table.
  2. Join the extracted data with the marts.customers table on customer_id.
  3. Load the final result into the reporting.customer_orders table.
Refine and iterate. Keep trying different phrases and approaches to see what yields the best results. If the agent generates invalid SQL or other mistakes, guide the agent with examples or public documentation.
  The previous query was incorrect because it removed the timestamp. Please
  correct the SQL. Use the TIMESTAMP_TRUNC function to truncate the
  event_timestamp to the nearest hour, instead of casting it as a DATE. For
  example: TIMESTAMP_TRUNC(event_timestamp, HOUR).