


從 Cloud Storage 載入 Parquet 資料
BigQuery 可讓您將 Cloud Storage 中的 Parquet 資料載入新的資料表或分區,或附加至現有資料表或分區,或覆寫現有資料表或分區。Parquet 是開放原始碼的欄式資料格式,廣泛用於 Apache Hadoop 生態系統,BigQuery 會在載入期間將其轉換為 Capacitor 欄式儲存格式。如要瞭解如何從本機檔案載入 Parquet 資料,請參閱「從本機檔案載入資料」。
限制
從 Cloud Storage bucket 將資料載入 BigQuery 時,須遵守下列限制:
- BigQuery 不保證外部資料來源的資料一致性。如果基礎資料在查詢執行期間遭到變更,可能會導致非預期的行為。
BigQuery 不支援 Cloud Storage 物件版本管理。如果您在 Cloud Storage URI 中加入世代編號,載入工作就會失敗。
如果要載入的檔案有不同的結構定義,就無法在 Cloud Storage URI 中使用萬用字元。只要資料欄位置不同,就視為不同的結構定義。
輸入檔案規定
將 Parquet 檔案載入 BigQuery 時,為避免發生 resourcesExceeded 錯誤,請遵循下列規範:
- 資料列大小不得超過 50 MB。
- 如果輸入資料超過 100 欄,建議將頁面大小縮減至小於預設頁面大小 (1 * 1024 * 1024 位元組)。如果使用大幅壓縮,這項功能就特別實用。
- 為達到最佳效能,資料列群組大小應至少為 16 MiB。資料列群組越小,I/O 就會增加,載入和查詢速度也會變慢。
事前準備
授予 Identity and Access Management (IAM) 角色,讓使用者具備必要權限,可執行本文件中的各項工作,並建立資料集來儲存資料。
所需權限
如要將資料載入 BigQuery,您必須具備 IAM 權限,才能執行載入工作,並將資料載入 BigQuery 資料表和分區。如果您是從 Cloud Storage 載入資料,也需要 IAM 權限,才能存取含有資料的 bucket。
將資料載入 BigQuery 的權限
如要將資料載入新的 BigQuery 資料表或分區,或附加或覆寫現有資料表或分區,您必須具備下列 IAM 權限:
bigquery.tables.createbigquery.tables.updateDatabigquery.tables.updatebigquery.jobs.create
下列各項預先定義的 IAM 角色,都包含將資料載入 BigQuery 資料表或分區所需的權限:
roles/bigquery.dataEditorroles/bigquery.dataOwnerroles/bigquery.admin(包含bigquery.jobs.create權限)bigquery.user(包含bigquery.jobs.create權限)bigquery.jobUser(包含bigquery.jobs.create權限)
此外,如果您具備 bigquery.datasets.create 權限,則可在建立的資料集中,使用載入工作建立及更新資料表。
如要進一步瞭解 BigQuery 的 IAM 角色和權限,請參閱「預先定義的角色和權限」。
從 Cloud Storage 載入資料的權限
如要取得從 Cloud Storage bucket 載入資料所需的權限,請要求管理員授予您 bucket 的儲存空間管理員 (roles/storage.admin) IAM 角色。如要進一步瞭解如何授予角色,請參閱「管理專案、資料夾和組織的存取權」。
這個預先定義的角色具備從 Cloud Storage bucket 載入資料所需的權限。如要查看確切的必要權限,請展開「Required permissions」(必要權限) 部分:
所需權限
您必須具備下列權限,才能從 Cloud Storage bucket 載入資料:
-
storage.buckets.get -
storage.objects.get -
storage.objects.list (required if you are using a URI wildcard)
建立資料集
建立 BigQuery 資料集來儲存資料。
Parquet 結構定義
將 Parquet 檔案載入 BigQuery 時,系統會從自述式來源資料自動擷取資料表結構定義。從來源資料擷取結構定義時,BigQuery 會按照字母順序使用最後一個檔案。
舉例來說,Cloud Storage 中有下列 Parquet 檔案:
gs://mybucket/00/
  a.parquet
  z.parquet
gs://mybucket/01/
  b.parquet
在 bq 指令列工具中執行這項指令,會載入所有檔案 (以逗號分隔的清單),並從 mybucket/01/b.parquet 衍生結構定義:
bq load \
--source_format=PARQUET \
dataset.table \
"gs://mybucket/00/*.parquet","gs://mybucket/01/*.parquet"
載入具有不同結構定義的多個 Parquet 檔案時,不同結構定義中指定的相同資料欄必須在各個結構定義中採用相同的模式。
BigQuery 偵測到結構定義時,會將部分 Parquet 資料類型轉換為 BigQuery 資料類型,使其與 GoogleSQL 語法相容。詳情請參閱 Parquet 轉換。
如要提供資料表結構定義來建立外部資料表,請將 BigQuery API 中的referenceFileSchemaUri 屬性或 bq 指令列工具中的 --reference_file_schema_uri 參數設為參考檔案的網址。例如 --reference_file_schema_uri="gs://mybucket/schema.parquet"。
Parquet 壓縮
BigQuery 支援下列 Parquet 檔案內容壓縮轉碼器:
GZipLZO_1CLZO_1XLZ4_RAWSnappyZSTD
將 Parquet 資料載入至新的資料表
您可以使用下列任一方式,將 Parquet 資料載入新資料表:
- Google Cloud 控制台
- bq 指令列工具的
bq load指令 jobs.insertAPI 方法和設定load工作- 用戶端程式庫
如要將 Parquet 資料從 Cloud Storage 載入新的 BigQuery 資料表,請執行下列操作:
控制台
前往 Google Cloud 控制台的「BigQuery」頁面。
- 點選左側窗格中的 「Explorer」。
- 在「Explorer」窗格中展開專案,點選「資料集」,然後選取資料集。
- 在「資料集資訊」部分,點選 「建立資料表」。
- 在「建立資料表」窗格中,指定下列詳細資料:
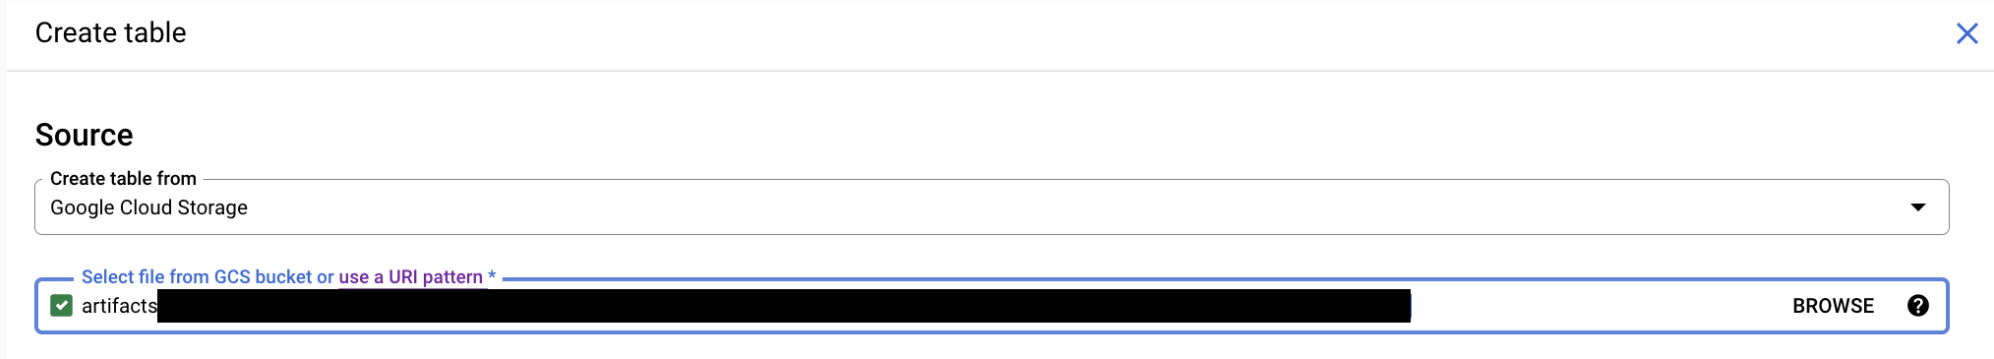
- 在「Source」(來源) 部分,從「Create table from」(建立資料表來源) 清單中選取「Google Cloud Storage」。接著,按照下列步驟操作:
- 從 Cloud Storage bucket 選取檔案,或輸入 Cloud Storage URI。您無法在 Google Cloud 控制台中加入多個 URI,但可以使用萬用字元。Cloud Storage bucket 必須與資料集位於相同位置,且該資料集包含您要建立、附加或覆寫的資料表。
- 在「File format」(檔案格式) 部分,選取「Parquet」。
- 從 Cloud Storage bucket 選取檔案,或輸入 Cloud Storage URI。您無法在 Google Cloud 控制台中加入多個 URI,但可以使用萬用字元。Cloud Storage bucket 必須與資料集位於相同位置,且該資料集包含您要建立、附加或覆寫的資料表。
- 在「Destination」(目的地) 部分,指定下列詳細資料:
- 在「Dataset」(資料集) 部分,選取要在其中建立資料表的資料集。
- 在「Table」(資料表) 欄位中,輸入要建立的資料表名稱。
- 確認「資料表類型」欄位設為「原生資料表」。
- 在「Schema」(結構定義) 區段中,無需採取任何行動。Parquet 檔案中的結構定義為自述式。
- 選用:指定分區和叢集設定。詳情請參閱「建立分區資料表」和「建立及使用分群資料表」。
- 按一下「進階選項」,然後執行下列操作:
- 讓「Write preference」(寫入偏好設定) 的 [Write if empty] (空白時寫入) 選項維持在已選取狀態。這個選項會建立新資料表,並將資料載入其中。
- 如要忽略資料列中未出現在資料表結構定義的值,請選取「Unknown values」(不明的值)。
- 在「Encryption」(加密) 部分,按一下「Customer-managed key」(客戶自行管理的金鑰),即可使用 Cloud Key Management Service 金鑰。如果保留 Google-managed key 設定,BigQuery 會加密靜態資料。
- 點選「建立資料表」。
SQL
使用 LOAD DATA DDL 陳述式。以下範例會將 Parquet 檔案載入新資料表 mytable:
前往 Google Cloud 控制台的「BigQuery」頁面。
在查詢編輯器中輸入下列陳述式:
LOAD DATA OVERWRITE mydataset.mytable
FROM FILES (
  format = 'PARQUET',
  uris = ['gs://bucket/path/file.parquet']);
按一下「 執行」。
如要進一步瞭解如何執行查詢,請參閱「執行互動式查詢」。
bq
請使用 bq load 指令,然後使用 --source_format 旗標指定 PARQUET,並加入 Cloud Storage URI。您可以加入單一 URI、以逗號分隔的 URI 清單,或包含萬用字元的 URI。
(選用) 提供 --location 旗標,並將值設為您的位置。
其他選用標記包括:
--time_partitioning_type:啟用資料表的時間分區功能,並設定分區類型。可能的值為HOUR、DAY、MONTH和YEAR。建立依DATE、DATETIME或TIMESTAMP資料欄分區的資料表時,可以選擇是否使用這個旗標。時間分區的預設分區類型為DAY。您無法變更現有資料表的分區規格。--time_partitioning_expiration:這是一個整數,用來指定系統應在何時刪除時間分區 (以秒為單位)。到期時間的計算方式為分區的世界標準時間日期加上整數值。--time_partitioning_field:用於建立分區資料表的DATE或TIMESTAMP欄。如果啟用時間分區,但未提供這個值,系統會建立擷取時間分區資料表。--require_partition_filter:這個選項啟用後,系統會要求使用者加入WHERE子句,以指定要查詢的分區。規定必須使用分區篩選器,可降低費用及提高成效。 詳情請參閱「在查詢中要求分區篩選器」。--clustering_fields:以半形逗號分隔的清單,最多列出四個用於建立分群資料表的資料欄名稱。--destination_kms_key:用於加密資料表資料的 Cloud KMS 金鑰。--column_name_character_map:定義資料欄名稱字元的範圍和處理方式,並可選擇啟用彈性資料欄名稱。詳情請參閱load_option_list。如要進一步瞭解支援和不支援的字元,請參閱「彈性資料欄名稱」。如要進一步瞭解分區資料表,請參閱:
如要進一步瞭解分群資料表,請參閱:
如要進一步瞭解資料表加密作業,請參閱下列說明文章:
如要將 Parquet 資料載入 BigQuery,請輸入下列指令:
bq --location=LOCATION load \
--source_format=FORMAT \
DATASET.TABLE \
PATH_TO_SOURCE
更改下列內容:
LOCATION:您的位置。--location是選用旗標。舉例來說,如果您在東京地區使用 BigQuery,就可以將旗標的值設為asia-northeast1。您可以使用 .bigqueryrc 檔案,設定該位置的預設值。FORMAT:PARQUET.DATASET:現有資料集。TABLE:要載入資料的資料表名稱。PATH_TO_SOURCE:完整 Cloud Storage URI,或以半形逗號分隔的 URI 清單。您也可以使用萬用字元。
範例:
下列指令會將資料從 gs://mybucket/mydata.parquet 載入到 mydataset 中名為 mytable 的資料表。
    bq load \
    --source_format=PARQUET \
    mydataset.mytable \
    gs://mybucket/mydata.parquet
下列指令會將 gs://mybucket/mydata.parquet 中的資料,載入 mydataset 中名為 mytable 的新擷取時間分區資料表。
    bq load \
    --source_format=PARQUET \
    --time_partitioning_type=DAY \
    mydataset.mytable \
    gs://mybucket/mydata.parquet
下列指令會將資料從 gs://mybucket/mydata.parquet 載入到 mydataset 中名為 mytable 的分區資料表。資料表會依 mytimestamp 資料欄進行分區。
    bq load \
    --source_format=PARQUET \
    --time_partitioning_field mytimestamp \
    mydataset.mytable \
    gs://mybucket/mydata.parquet
下列指令會將 gs://mybucket/ 中多個檔案的資料載入到 mydataset 中名為 mytable 的資料表。指令中的 Cloud Storage URI 使用萬用字元。
    bq load \
    --source_format=PARQUET \
    mydataset.mytable \
    gs://mybucket/mydata*.parquet
下列指令會將 gs://mybucket/ 中多個檔案的資料載入到 mydataset 中名為 mytable 的資料表。指令包含以逗號分隔且帶有萬用字元的 Cloud Storage URI 清單。
    bq load \
    --source_format=PARQUET \
    mydataset.mytable \
    "gs://mybucket/00/*.parquet","gs://mybucket/01/*.parquet"
API
建立指向 Cloud Storage 中來源資料的
load工作。source URIs屬性必須完整,格式為gs://BUCKET/OBJECT。每個 URI 都可以包含一個「*」萬用字元。將
sourceFormat屬性設為PARQUET,以指定 Parquet 資料格式。如要檢查工作狀態,請呼叫
jobs.get(JOB_ID*),並將 JOB_ID 替換為初始要求傳回的工作 ID。- 如果是
status.state = DONE,代表工作已順利完成。 - 如果出現
status.errorResult屬性,表示要求失敗,且該物件會包含說明錯誤原因的資訊。如果要求執行失敗,系統就不會建立任何資料表,也不會載入任何資料。 - 如果沒有
status.errorResult,代表工作已順利完成,但可能發生一些非嚴重錯誤,例如匯入幾列資料時發生問題。非嚴重錯誤會列在傳回的工作物件status.errors屬性中。
- 如果是
API 附註:
載入工作具有原子性和一致性:如果載入工作失敗,則所有資料都無法使用;如果載入工作成功,則所有資料都可使用。
最佳做法是產生專屬 ID,並在呼叫
jobs.insert建立載入工作時,將該 ID 做為jobReference.jobId傳遞。這個方法較不受網路故障問題的影響,因為用戶端可使用已知的工作 ID 進行輪詢或重試。對指定的工作 ID 呼叫
jobs.insert是一種冪等作業。也就是說,您可以對同一個工作 ID 重試無數次,最多會有一個作業成功。
Go
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Go 設定操作說明進行操作。詳情請參閱 BigQuery Go API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
Java
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Java 設定操作說明進行操作。詳情請參閱 BigQuery Java API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
Node.js
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Node.js 設定操作說明進行操作。詳情請參閱 BigQuery Node.js API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
PHP
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 PHP 設定操作說明進行操作。詳情請參閱 BigQuery PHP API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
Python
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Python 設定操作說明進行操作。詳情請參閱 BigQuery Python API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
使用 Client.load_table_from_uri() 方法,從 Cloud Storage 啟動載入工作。如要使用 Parquet,請將 LoadJobConfig.source_format 屬性設為字串PARQUET,並將工作設定做為 job_config 引數傳遞至 load_table_from_uri() 方法。
使用 Parquet 資料附加到資料表或覆寫資料表
如要將其他資料載入資料表,您可以指定來源檔案或附加查詢結果。
在 Google Cloud 控制台中,使用「Write preference」(寫入偏好設定) 選項,指定從來源檔案或查詢結果載入資料時要採取的動作。
將額外資料載入資料表時,可以選擇下列選項:
| 主控台選項 | bq 工具旗標 | BigQuery API 屬性 | 說明 |
|---|---|---|---|
| 空白時寫入 | 不支援 | WRITE_EMPTY |
資料表空白時才會寫入資料。 |
| 附加到資料表 | --noreplace 或 --replace=false;如果未指定 --[no]replace,則預設動作為附加 |
WRITE_APPEND |
(預設) 將資料附加至資料表結尾。 |
| 覆寫資料表 | --replace或--replace=true |
WRITE_TRUNCATE |
在寫入新資料前,清除資料表中的所有現有資料。 這項操作也會刪除資料表結構定義、資料列層級安全性,並移除所有 Cloud KMS 金鑰。 |
如果您將資料載入現有資料表,該載入工作可附加資料,或覆寫資料表。
您可以使用下列任一方法附加或覆寫資料表:
- Google Cloud 控制台
- bq 指令列工具的
bq load指令 jobs.insertAPI 方法和設定load工作- 用戶端程式庫
如要使用 Parquet 資料對資料表進行附加或覆寫,請執行下列操作:
控制台
前往 Google Cloud 控制台的「BigQuery」頁面。
- 點選左側窗格中的 「Explorer」。
- 在「Explorer」窗格中展開專案,點選「資料集」,然後選取資料集。
- 在「資料集資訊」部分,點選 「建立資料表」。
- 在「建立資料表」窗格中,指定下列詳細資料:
- 在「Source」(來源) 部分,從「Create table from」(建立資料表來源) 清單中選取「Google Cloud Storage」。接著,按照下列步驟操作:
- 從 Cloud Storage bucket 選取檔案,或輸入 Cloud Storage URI。您無法在 Google Cloud 控制台中加入多個 URI,但可以使用萬用字元。Cloud Storage bucket 必須與資料集位於相同位置,且該資料集包含您要建立、附加或覆寫的資料表。
- 在「File format」(檔案格式) 中選取「Parquet」。
- 從 Cloud Storage bucket 選取檔案,或輸入 Cloud Storage URI。您無法在 Google Cloud 控制台中加入多個 URI,但可以使用萬用字元。Cloud Storage bucket 必須與資料集位於相同位置,且該資料集包含您要建立、附加或覆寫的資料表。
- 在「Destination」(目的地) 部分,指定下列詳細資料:
- 在「Dataset」(資料集) 部分,選取要在其中建立資料表的資料集。
- 在「Table」(資料表) 欄位中,輸入要建立的資料表名稱。
- 確認「資料表類型」欄位設為「原生資料表」。
- 在「Schema」(結構定義) 區段中,無需採取任何行動。結構定義在 Parquet 檔案中會自行描述。
- 選用:指定分區和叢集設定。詳情請參閱「建立分區資料表」和「建立及使用分群資料表」。您無法透過附加或覆寫資料表,將資料表轉換為分區或分群資料表。 Google Cloud 控制台不支援在載入工作中附加或覆寫分區或分群資料表。
- 按一下「進階選項」,然後執行下列操作:
- 在「Write preference」(寫入偏好設定) 部分,選擇「Append to table」(附加至資料表) 或「Overwrite table」(覆寫資料表)。
- 如要忽略資料列中未出現在資料表結構定義的值,請選取「Unknown values」(不明的值)。
- 在「Encryption」(加密) 部分,按一下「Customer-managed key」(客戶自行管理的金鑰),即可使用 Cloud Key Management Service 金鑰。如果保留 Google-managed key 設定,BigQuery 會加密靜態資料。
- 點選「建立資料表」。
SQL
使用 LOAD DATA DDL 陳述式。以下範例會將 Parquet 檔案附加至資料表 mytable:
前往 Google Cloud 控制台的「BigQuery」頁面。
在查詢編輯器中輸入下列陳述式:
LOAD DATA INTO mydataset.mytable
FROM FILES (
  format = 'PARQUET',
  uris = ['gs://bucket/path/file.parquet']);
按一下「 執行」。
如要進一步瞭解如何執行查詢,請參閱「執行互動式查詢」。
bq
如要覆寫資料表,請輸入 bq load 指令並加上 --replace 旗標。如要附加資料至資料表,使用 --noreplace 旗標。若未指定任何旗標,預設動作為附加資料。提供 --source_format 旗標,並將其設為 PARQUET。由於 Parquet 結構定義會自動從自我描述來源資料中擷取,因此您不需要提供結構定義定義。
(選用) 提供 --location 旗標,並將值設為您的位置。
其他選用標記包括:
--destination_kms_key:用於加密資料表資料的 Cloud KMS 金鑰。
bq --location=LOCATION load \
--[no]replace \
--source_format=FORMAT \
DATASET.TABLE \
PATH_TO_SOURCE
更改下列內容:
location:您的位置。--location是選用旗標。您可以使用 .bigqueryrc 檔案來設定位置的預設值。format:PARQUET.dataset:現有資料集。table:要載入資料的資料表名稱。path_to_source:完整 Cloud Storage URI,或以半形逗號分隔的 URI 清單。您也可以使用萬用字元。
範例:
下列指令會從 gs://mybucket/mydata.parquet 載入資料,並覆寫 mydataset 中名為 mytable 的資料表。
    bq load \
    --replace \
    --source_format=PARQUET \
    mydataset.mytable \
    gs://mybucket/mydata.parquet
下列指令會從 gs://mybucket/mydata.parquet 載入資料,並將資料附加至 mydataset 中名為 mytable 的資料表。
    bq load \
    --noreplace \
    --source_format=PARQUET \
    mydataset.mytable \
    gs://mybucket/mydata.parquet
如要瞭解如何使用 bq 指令列工具附加及覆寫分區資料表,請參閱「附加及覆寫分區資料表資料」。
API
建立指向 Cloud Storage 中來源資料的
load工作。source URIs屬性必須完整,格式為gs://BUCKET/OBJECT。您可以使用以逗號分隔清單的形式包含多個 URI。請注意,系統也支援使用萬用字元。藉由將
configuration.load.sourceFormat屬性設為PARQUET,以指定資料格式。藉由將
configuration.load.writeDisposition屬性設為WRITE_TRUNCATE或WRITE_APPEND,以指定寫入偏好設定。
Go
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Go 設定操作說明進行操作。詳情請參閱 BigQuery Go API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
Java
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Java 設定操作說明進行操作。詳情請參閱 BigQuery Java API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
Node.js
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Node.js 設定操作說明進行操作。詳情請參閱 BigQuery Node.js API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
PHP
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 PHP 設定操作說明進行操作。詳情請參閱 BigQuery PHP API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
Python
在試用這個範例之前,請先按照「使用用戶端程式庫的 BigQuery 快速入門導覽課程」中的 Python 設定操作說明進行操作。詳情請參閱 BigQuery Python API 參考文件。
如要向 BigQuery 進行驗證,請設定應用程式預設憑證。詳情請參閱「設定用戶端程式庫的驗證機制」。
如要將資料列附加至現有資料表,請將LoadJobConfig.write_disposition 屬性設為 WRITE_APPEND。
如要取代現有資料表中的資料列,請將 LoadJobConfig.write_disposition 屬性設為 WRITE_TRUNCATE。
載入 Hive 分區的 Parquet 資料
BigQuery 支援載入儲存在 Cloud Storage 的 Hive 分區 Parquet 資料,並將 Hive 分區資料欄填入目的地 BigQuery 代管資料表。詳情請參閱「載入外部分區資料」。
Parquet 轉換
本節說明 BigQuery 如何在載入 Parquet 資料時剖析各種資料類型。
部分 Parquet 資料類型 (例如 INT32、INT64、BYTE_ARRAY 和 FIXED_LEN_BYTE_ARRAY) 可轉換為多種 BigQuery 資料類型。為確保 BigQuery 正確轉換 Parquet 資料類型,請在 Parquet 檔案中指定適當的資料類型。
舉例來說,如要將 Parquet INT32 資料類型轉換為 BigQuery DATE 資料類型,請指定下列內容:
optional int32 date_col (DATE);
BigQuery 會將 Parquet 資料類型轉換為 BigQuery 資料類型,詳情請參閱下列各節。
類型轉換
| BigQuery 資料類型 | ||
|---|---|---|
BOOLEAN |
無 | BOOLEAN |
| INT32 | 無、INTEGER (UINT_8、UINT_16、UINT_32、INT_8、INT_16、INT_32) |
INT64 |
| INT32 | DECIMAL | NUMERIC、BIGNUMERIC 或 STRING |
INT32 |
DATE |
DATE |
INT32 |
TIME,precision=MILLIS
(TIME_MILLIS)
|
時間 |
INT64 |
無,INTEGER (UINT_64,INT_64)
|
INT64 |
| INT64 | DECIMAL | NUMERIC、BIGNUMERIC 或 STRING |
INT64 |
TIME,precision=MICROS
(TIME_MICROS)
|
時間 |
INT64 |
TIMESTAMP,precision=MILLIS
(TIMESTAMP_MILLIS)
|
TIMESTAMP |
INT64 |
TIMESTAMP,precision=MICROS
(TIMESTAMP_MICROS)
|
TIMESTAMP |
INT96 |
無 | TIMESTAMP |
FLOAT |
無 | FLOAT64 |
DOUBLE |
無 | FLOAT64 |
BYTE_ARRAY |
無 | BYTES |
BYTE_ARRAY |
STRING (UTF8) |
STRING |
| FIXED_LEN_BYTE_ARRAY | DECIMAL | NUMERIC、BIGNUMERIC 或 STRING |
FIXED_LEN_BYTE_ARRAY |
無 | BYTES |
巢狀群組會轉換為 STRUCT 類型。系統不支援其他 Parquet 類型與轉換類型的組合。
不帶正負號的邏輯類型
Parquet UINT_8、UINT_16、UINT_32 和 UINT_64 類型不帶正負號。載入 BigQuery 帶正負號的 INTEGER 資料欄時,BigQuery 會將這些類型的值視為不帶正負號。如果是 UINT_64,當無正負號的值超過 INTEGER 的最大值 9,223,372,036,854,775,807 時,系統會傳回錯誤。
Decimal 邏輯類型
Decimal 邏輯類型可轉換為 NUMERIC、BIGNUMERIC 或 STRING 類型。轉換後的類型取決於 decimal 邏輯類型的有效位數和小數位數參數,以及指定的小數目標類型。請按照下列方式指定十進位指定類型:
- 如要使用
jobs.insertAPI 執行載入工作,請使用JobConfigurationLoad.decimalTargetTypes欄位。 - 如要使用 bq 指令列工具中的
bq load指令執行載入工作,請使用--decimal_target_types旗標。 - 如要查詢具有外部來源的資料表,請使用
ExternalDataConfiguration.decimalTargetTypes欄位。 - 如果是使用 DDL 建立的永久外部資料表:請使用
decimal_target_types選項。
列舉邏輯類型
Enum 邏輯類型可轉換為 STRING 或 BYTES。指定轉換後的目標類型,如下所示:
- 如要使用
jobs.insertAPI 執行載入工作,請使用JobConfigurationLoad.parquetOptions欄位。 - 如要使用 bq 指令列工具中的
bq load指令執行載入工作,請使用--parquet_enum_as_string旗標。 - 如果是使用
bq mk建立的永久外部資料表:請使用--parquet_enum_as_string旗標。
清單邏輯類型
您可以為 Parquet LIST 邏輯類型啟用結構定義推論。BigQuery 會檢查 LIST 節點是否為標準形式,或符合回溯相容性規則所述的其中一種形式:
// standard form
<optional | required> group <name> (LIST) {
  repeated group list {
    <optional | required> <element-type> element;
  }
}
如果是,則轉換後結構定義中 LIST 節點的對應欄位,會視為節點具有下列結構定義:
repeated <element-type> <name>
「list」和「element」節點會省略。
- 如果是使用
jobs.insertAPI 的載入工作,請使用JobConfigurationLoad.parquetOptions欄位。 - 如要使用 bq 指令列工具中的
bq load指令執行載入工作,請使用--parquet_enable_list_inference旗標。 - 如果是使用
bq mk建立的永久外部資料表,請使用--parquet_enable_list_inference旗標。 - 如果是使用
CREATE EXTERNAL TABLE陳述式建立的永久外部資料表,請使用enable_list_inference選項。
地理空間資料
您可以載入 Parquet 檔案,其中包含 STRING 欄中的 WKT、十六進位編碼 WKB 或 GeoJSON,或 BYTE_ARRAY 欄中的 WKB,方法是指定 GEOGRAPHY 類型的 BigQuery 結構定義。詳情請參閱「載入地理空間資料」。
您也可以載入 GeoParquet 檔案。在這種情況下,GeoParquet 中繼資料描述的資料欄預設會解讀為 GEOGRAPHY 類型。您也可以提供明確的結構定義,將原始 WKB 資料載入 BYTES 資料欄。詳情請參閱「載入 GeoParquet 檔案」。
資料欄名稱轉換
資料欄名稱可以包含英文字母 (a-z、A-Z)、數字 (0-9) 或底線 (_),且開頭必須是英文字母或底線。如果使用彈性資料欄名稱,BigQuery 支援以數字開頭的資料欄名稱。如果資料欄名稱開頭為數字,請務必謹慎,因為搭配使用 BigQuery Storage Read API 或 BigQuery Storage Write API (gRPC) 時,需要特別處理彈性資料欄名稱。如要進一步瞭解彈性資料欄名稱支援,請參閱「彈性資料欄名稱」。
資料欄名稱長度上限為 300 個半形字元。資料欄名稱不得使用下列任何前置字元:
_TABLE__FILE__PARTITION_ROW_TIMESTAMP__ROOT___COLIDENTIFIER_CHANGE_SEQUENCE_NUMBER_CHANGE_TYPE_CHANGE_TIMESTAMP
資料欄名稱不得重複,即使大小寫不同也是如此。舉例來說,名為 Column1 的資料欄會視為與名為 column1 的資料欄相同。如要進一步瞭解資料欄命名規則,請參閱 GoogleSQL 參考資料中的「資料欄名稱」。
如果資料表名稱 (例如 test) 與其中一個資料欄名稱 (例如 test) 相同,SELECT 運算式會將 test 資料欄解讀為包含所有其他資料表資料欄的 STRUCT。如要避免這種衝突,請使用下列其中一種方法:
避免為資料表和資料欄使用相同名稱。
請勿使用
_field_做為資料欄名稱前置字串。系統保留的前置字串會在查詢期間自動重新命名。舉例來說,SELECT _field_ FROM project1.dataset.test查詢會傳回名為_field_1的資料欄。如要查詢這個名稱的資料欄,請使用別名控制輸出內容。為資料表指派其他別名。舉例來說,下列查詢會將資料表別名
t指派給資料表project1.dataset.test:SELECT test FROM project1.dataset.test AS t;參照資料欄時,請一併提供資料表名稱。例如:
SELECT test.test FROM project1.dataset.test;
彈性設定資料欄名稱
您可以更靈活地命名資料欄,包括使用更多非英文字元和其他符號。如果彈性資料欄名稱是加上引號的 ID,請務必使用倒引號 (`) 字元括住。
彈性資料欄名稱支援下列字元:
- 任何語言的任何字母,以 Unicode 規則運算式
\p{L}表示。 - 任何語言中的任何數字字元,以 Unicode 規則運算式
\p{N}表示。 - 任何連接器標點符號字元,包括底線,以 Unicode 規則運算式
\p{Pc}表示。 - Unicode 規則運算式
\p{Pd}表示的連字號或破折號。 - 任何用於搭配其他字元的標記,以 Unicode 規則運算式
\p{M}表示。例如重音符號、變音符號或外框。 - 下列特殊字元:
- 以 Unicode 規則運算式
\u0026表示的 & 符號 (&)。 - 百分比符號 (
%),以 Unicode 規則運算式\u0025表示。 - 等號 (
=),以 Unicode 規則運算式\u003D表示。 - 加號 (
+),以 Unicode 規則運算式\u002B表示。 - 冒號 (
:),以 Unicode 規則運算式\u003A表示。 - 縮寫符號 (
'),以 Unicode 規則運算式\u0027表示。 - 小於符號 (
<),以 Unicode 規則運算式\u003C表示。 - 大於符號 (
>),以 Unicode 規則運算式\u003E表示。 - 以 Unicode 規則運算式
\u0023表示的數字符號 (#)。 - 垂直線 (
|),以 Unicode 規則運算式\u007c表示。 - 空格字元。
- 以 Unicode 規則運算式
彈性資料欄名稱不支援下列特殊字元:
- 驚嘆號 (
!),以 Unicode 規則運算式\u0021表示。 - 引號 (
"),以 Unicode 規則運算式\u0022表示。 - 錢幣符號 (
$),以 Unicode 規則運算式\u0024表示。 - 左括號 (
(),以 Unicode 規則運算式\u0028表示。 - 右括號 (
)),以 Unicode 規則運算式\u0029表示。 - 星號 (
*),以 Unicode 規則運算式\u002A表示。 - 以 Unicode 規則運算式
\u002C表示的半形逗號 (,)。 - 句號 (
.),以 Unicode 規則運算式\u002E表示。使用資料欄名稱字元對應時,Parquet 檔案資料欄名稱中的句號不會替換為底線。詳情請參閱「彈性資料欄限制」。 - 斜線 (
/),以 Unicode 規則運算式\u002F表示。 - 分號 (
;),以 Unicode 規則運算式\u003B表示。 - 問號 (
?),以 Unicode 規則運算式\u003F表示。 - 以 Unicode 規則運算式
\u0040表示的小老鼠符號 (@)。 - 左方括號 (
[),以 Unicode 規則運算式\u005B表示。 - 反斜線 (
\),以 Unicode 規則運算式\u005C表示。 - 右方括號 (
]),以 Unicode 規則運算式\u005D表示。 - 揚抑符號 (
^),以 Unicode 規則運算式\u005E表示。 - 重音符號 (
`),以 Unicode 規則運算式\u0060表示。 - 左大括號 {
{),以 Unicode 規則運算式\u007B表示。 - 右大括號 (
}),以 Unicode 規則運算式\u007D表示。 - 波浪號 (
~),以 Unicode 規則運算式\u007E表示。
如需其他規範,請參閱「資料欄名稱」。
BigQuery Storage Read API 和 BigQuery Storage Write API (gRPC) 都支援擴充的資料欄字元。如要搭配 BigQuery Storage Read API 使用擴充的 Unicode 字元清單,您必須設定旗標。您可以使用 displayName 屬性擷取資料欄名稱。以下範例說明如何使用 Python 用戶端設定旗標:
from google.cloud.bigquery_storage import types
requested_session = types.ReadSession()

#set avro serialization options for flexible column.
options = types.AvroSerializationOptions()
options.enable_display_name_attribute = True
requested_session.read_options.avro_serialization_options = options
如要透過 BigQuery Storage Write API (gRPC) 使用擴充的 Unicode 字元清單,您必須提供含有 column_name 標記法的結構定義,除非您使用的是 JsonStreamWriter 寫入器物件。以下範例說明如何提供結構定義:
syntax = "proto2";
package mypackage;
// Source protos located in github.com/googleapis/googleapis
import "google/cloud/bigquery/storage/v1/annotations.proto";

message FlexibleSchema {
  optional string item_name_column = 1
  [(.google.cloud.bigquery.storage.v1.column_name) = "name-列"];
  optional string item_description_column = 2
  [(.google.cloud.bigquery.storage.v1.column_name) = "description-列"];
}
在這個範例中,item_name_column 和 item_description_column 是預留位置名稱,必須符合通訊協定緩衝區命名慣例。請注意,column_name 註解一律優先於預留位置名稱。
限制
- Iceberg 代管資料表、Iceberg 外部資料表,以及由 Lakehouse 執行階段目錄代管的 Apache Iceberg 資料表,預設支援彈性資料欄名稱。其他外部資料表 (例如 Parquet、ORC、Avro、CSV 或 Delta Lake) 則預設不啟用彈性資料欄名稱。如要申請專案層級啟用,請與 Cloud Customer Care 聯絡。
- 如果是 Delta Lake 資料表,您也必須在
id或name模式中啟用資料欄對應。
- 如果是 Delta Lake 資料表,您也必須在
- 將具有彈性資料欄名稱的外部資料表匯出為開放檔案格式 (例如使用
EXPORT DATA或擷取工作的 Parquet 或 Avro) 時,系統會將不支援的資料欄名稱對應至產生的內部雜湊名稱 (col_...),因為第三方格式不含 BigQuery 顯示名稱中繼資料。 舊版 SQL 不支援彈性資料欄名稱。您必須使用 GoogleSQL。
如果 Parquet 檔案的資料欄名稱含有半形句號 (.),則無法載入。
載入 BigQuery 時,Parquet 檔案的資料欄名稱不區分大小寫。如果名稱相同 (不區分大小寫),就會發生衝突。如要避免這種情況,請在其中一個重複的資料欄名稱後方加上底線,或是在載入前重新命名資料欄。
對 Parquet 檔案進行偵錯
如果載入工作因資料錯誤而失敗,您可以使用 PyArrow 驗證 Parquet 資料檔案是否損毀。如果 PyArrow 無法讀取檔案,BigQuery 載入工作可能會拒絕這些檔案。以下範例說明如何使用 PyArrow 讀取 Parquet 檔案的內容:
from pyarrow import parquet as pq

# Read the entire file
pq.read_table('your_sample_file.parquet')
# Read specific columns
pq.read_table('your_sample_file.parquet',columns=['some_column', 'another_column'])
# Read the metadata of specific columns
file_metadata=pq.read_metadata('your_sample_file.parquet')
for col in file_metadata.row_group(0).to_dict()['columns']:
    print col['column_path_in_schema']
    print col['num_values']
詳情請參閱 PyArrow 說明文件。