


本文說明如何在專案或叢集層級,為 Managed Service for Apache Spark 工作啟用資料歷程。
資料歷程是 Knowledge Catalog 的功能,可以追蹤資料在系統的移動情形,包括來源、傳遞目的地和採用的轉換作業。
除了 SparkR 和 Spark 串流工作外,所有 Managed Service for Apache Spark 工作都支援資料歷程,並支援 BigQuery、Cloud Storage 和 Lakehouse 執行階段目錄 Apache Iceberg REST 目錄資料表。Managed Service for Apache Spark 2.0.74+、2.1.22+、2.2.50+、2.3.1+ 和 3.0 映像檔版本皆包含這項功能。
在 Managed Service for Apache Spark 叢集啟用這項功能後,Managed Service for Apache Spark Spark 工作就會擷取資料歷程事件,並發布至 Knowledge Catalog Data Lineage API。Managed Service for Apache Spark 透過 OpenLineage 與 Data Lineage API 整合,並使用 OpenLineage Spark 外掛程式。
您可以透過 Knowledge Catalog,使用下列方式存取資料歷程資訊:
事前準備
在 Google Cloud 控制台的專案選取器頁面中,選取包含要追蹤歷程之 Managed Service for Apache Spark 叢集的專案。
啟用 Data Lineage API。
即將推出的 Spark 資料歷程異動:請參閱 Managed Service for Apache Spark 版本資訊,瞭解異動公告。啟用 Data Lineage API 後,Spark 資料歷程會自動提供給專案和叢集 (請參閱「控管服務的歷程擷取作業」),不需額外設定專案或叢集層級。
必要的角色
如果您使用預設 VM 服務帳戶建立 Managed Service for Apache Spark 叢集,該帳戶會具備 Dataproc Worker 角色。這個角色包含 datalineage.locations.processOpenLineageMessage 權限,OpenLineage Spark 外掛程式會使用這項權限擷取歷程事件,並發布至 Data Lineage API。您不需採取其他行動。
如果您建立的 Managed Service for Apache Spark 叢集使用自訂服務帳戶,該服務帳戶必須具備發布歷程事件的權限。為遵循最小權限原則,請授予用途所需的最低角色:
- Dataproc 工作站 (
roles/dataproc.worker):Managed Service for Apache Spark 資料層作業所需的標準角色。這個角色已包含datalineage.locations.processOpenLineageMessage權限,因此如果自訂服務帳戶已有這個角色,就不必另外授予資料歷程角色。 - 資料歷程事件產生者 (
roles/datalineage.producer):自訂服務帳戶發布歷程事件所需的最低獨立資料歷程角色。如果服務帳戶沒有 Dataproc 工作站角色,請授予這個角色。 - 資料歷程編輯者 (
roles/datalineage.editor):授予編輯和刪除歷程程序和事件的權限,以及發布這些項目的權限。這個角色提供的權限超出標準管道執行作業所需,只有在工作負載必須修改現有歷程中繼資料時,才需要這個角色。 - 資料歷程管理員 (
roles/datalineage.admin):授予資料歷程資源的完整管理權限。叢集服務帳戶不需要這個角色。
啟用 Spark 資料歷程
您可以在專案或叢集層級啟用 Spark 資料歷程。
在專案層級啟用 Spark 資料歷程
在專案層級啟用 Spark 資料歷程後,在專案中 Managed Service for Apache Spark 叢集上執行的後續 Spark 工作,都會啟用 Spark 資料歷程。
如要在專案層級啟用 Spark 資料歷程,請設定下列自訂專案中繼資料:
| 鍵 | 值 |
|---|---|
DATAPROC_LINEAGE_ENABLED |
true |
DATAPROC_CLUSTER_SCOPES |
https://www.googleapis.com/auth/cloud-platform只有 2.0 映像檔版本叢集需要設定這個 VM 存取權範圍。系統會自動在 2.1 以上版本的映像檔叢集上設定這項屬性。 |
如要在專案層級停用 Spark 資料歷程,請將 DATAPROC_LINEAGE_ENABLED 中繼資料設為 false。
在叢集層級啟用 Spark 資料歷程
如果在建立叢集時啟用 Spark 資料歷程,在 Managed Service for Apache Spark 叢集上執行的支援 Spark 工作,就會啟用 Spark 資料歷程。這項設定會覆寫專案層級的任何 Spark 資料歷程設定:如果專案層級停用 Spark 資料歷程,但叢集層級啟用,則叢集層級優先,在叢集上執行的支援 Spark 工作會啟用資料歷程。
如要在叢集上啟用 Spark 資料歷程,請建立 Managed Service for Apache Spark 叢集,並將 dataproc:dataproc.lineage.enabled 叢集屬性設為 true。
gcloud CLI 範例:
gcloud dataproc clusters create CLUSTER_NAME \
    --project PROJECT_ID \
    --region REGION \
    --properties 'dataproc:dataproc.lineage.enabled=true'
建立叢集時,您可以將 dataproc:dataproc.lineage.enabled 屬性設為 false,停用叢集上的 Spark 資料歷程。
停用叢集的資料歷程:如要建立停用歷程的叢集,請設定
dataproc:dataproc.lineage.enabled=false。叢集建立後,您無法停用叢集上的 Spark 資料歷程。如要停用現有叢集的 Spark 資料歷程,您可以重新建立叢集,並將dataproc:dataproc.lineage.enabled屬性設為false。設定 2.0 映像檔版本叢集的範圍:Spark 資料歷程需要 Managed Service for Apache Spark 叢集 VM 存取權
cloud-platform範圍。使用2.1以上映像檔版本建立的 Managed Service for Apache Spark 映像檔版本叢集,會啟用cloud-platform。如果您在建立叢集時指定 Managed Service for Apache Spark 映像檔版本2.0,請將範圍設為cloud-platform。
停用工作的 Spark 資料歷程
如果叢集已啟用 Spark 資料歷程,您可以在提交工作時傳遞 spark.extraListeners 屬性,並將值留空 (""),即可停用工作的 Spark 資料歷程。
gcloud dataproc jobs submit spark \
    --cluster=CLUSTER_NAME \
    --project PROJECT_ID \
    --region REGION \
    --class CLASS \
    --jars=gs://APPLICATION_BUCKET/spark-application.jar \
    --properties=spark.extraListeners=''
提交 Spark 工作
在啟用 Spark 資料歷程的 Managed Service for Apache Spark 叢集上提交支援的 Spark 工作時,Managed Service for Apache Spark 會擷取資料歷程資訊,並回報給 Data Lineage API。
gcloud dataproc jobs submit spark \
    --cluster=CLUSTER_NAME \
    --project PROJECT_ID \
    --region REGION \
    --class CLASS \
    --jars=gs://APPLICATION_BUCKET/spark-application.jar \
    --properties=spark.openlineage.namespace=CUSTOM_NAMESPACE,spark.openlineage.appName=CUSTOM_APPNAME
注意:
- 您可以選擇是否要新增
spark.openlineage.namespace和spark.openlineage.appName屬性,用於識別工作。如未新增這些屬性,Managed Service for Apache Spark 會使用下列預設值:spark.openlineage.namespace的預設值:PROJECT_IDspark.openlineage.appName的預設值:spark.app.name
在 Knowledge Catalog 中查看歷程
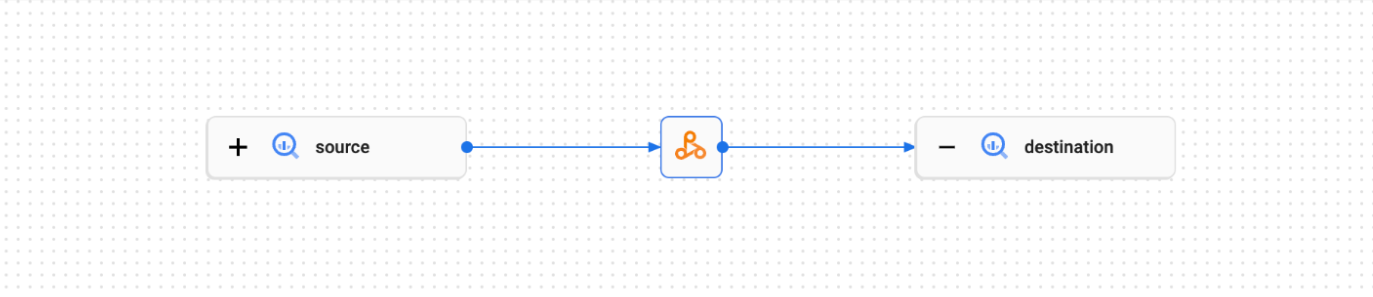
歷程圖會顯示專案資源與建立這些資源的程序之間的關係。您可以在 Google Cloud 控制台中查看資料歷程資訊,也可以從 Data Lineage API 擷取 JSON 格式的資料歷程資訊。
PySpark 程式碼範例:
下列 PySpark 工作會從公開 BigQuery 資料表讀取資料,然後將輸出內容寫入現有 BigQuery 資料集中的新資料表。並使用 Cloud Storage bucket 做為暫時儲存空間。
#!/usr/bin/env python

from pyspark.sql import SparkSession
import sys

spark = SparkSession \
  .builder \
  .appName('LINEAGE_BQ_TO_BQ') \
  .getOrCreate()

bucket = 'gs://BUCKET`
spark.conf.set('temporaryCloudStorageBucket', bucket)

source = 'bigquery-public-data:samples.shakespeare'
words = spark.read.format('bigquery') \
  .option('table', source) \
  .load()
words.createOrReplaceTempView('words')

word_count = spark.sql('SELECT word, SUM(word_count) AS word_count FROM words GROUP BY word')

destination_table = 'PROJECT_ID:DATASET.TABLE'
word_count.write.format('bigquery') \
  .option('table', destination_table) \
  .save()
請依指示取代下列項目:
BUCKET:現有 Cloud Storage bucket 的名稱
PROJECT_ID、DATASET 和 TABLE:專案 ID、現有 BigQuery 資料集的名稱,以及要在資料集中建立的新資料表名稱 (資料表不得存在)
您可以在 Knowledge Catalog UI 中查看歷程圖。
後續步驟
- 進一步瞭解資料歷程。