

This document describes how you can organize and prioritize your alerts by giving them user-defined labels. These labels are configured on alerting policies and are listed on alerting policies and alerts. Depending on your configuration, the labels are also listed on certain notifications.
About labels
Labels, which are key-value pairs, are used to attach information to a time-series, alerting policy, alert, or notification. For example, the labels on a time series might identify the specific virtual machine (VM) instance from which data was collected. Labels are either user-defined or predefined.
User-defined labels
User-defined labels contain information that you specify. These labels can have either static or dynamic values:
Static user-defined labels have values that can't be changed. You can create static user-defined labels when you configure an alerting policy by using the Google Cloud console or the Cloud Monitoring API. For more information, see the following documents:
Dynamic user-defined labels have values that can change based on values of the time-series data. You can create dynamic user-defined labels when you configure the condition of an alerting policy with PromQL. For an example, see Example: Add user-defined labels with dynamic values.
Label keys must start with a lowercase letter. Both label keys and label values can contain only lowercase letters, digits, underscores, and dashes.
Predefined labels
Predefined labels are included in resource descriptors; these labels must be populated when time-series data is written. These labels show information about the metric being collected or the resource against which the metric is written. For example, the labels on a time series might identify a virtual machine (VM), a zone, a Google Cloud project, and a device type. When Monitoring creates an alert based off that time series, the alert inherits those labels.
App Hub labels
App Hub attaches labels to log, metric, and trace data generated by an application and its services and workloads. These labels let the Google Cloud infrastructure create application, service, and workload dashboards that show metric and log data. For more information, see one of the following documents:
- Google Cloud console: Associate an alerting policy with an App Hub application.
- Cloud Monitoring API: Associate an alerting policy with an App Hub application.
How to view labels
You can view the labels of an alerting policy or an alert on the details page of an alert, the details page of an alerting policy, and in some notifications.
- Alerting policies: Static user-defined labels are listed in the User Labels section. Dynamic user-defined labels and predefined labels aren't visible.
- Alerts: Static user-defined labels are listed in the Policy Labels section, and dynamic user-defined labels are listed in the Metric Labels section. Predefined labels are listed in the Monitored Resource Labels and Metric Labels sections.
Notifications: Predefined labels and user-defined labels are listed in the following notification types:
- Google Chat
- PagerDuty
- Pub/Sub
- Webhook
Example: Add user-defined labels with dynamic values
You can use PromQL to configure a label so that its value
changes dynamically based on time-series data. For example, you want
your alerts to have a criticality label whose value changes
depending on the value of the monitored CPU utilization metric:
  label_replace(
    avg_over_time({"compute.googleapis.com/instance/cpu/utilization", monitored_resource="gce_instance"}[5m]) >= 0.9,
    "criticality", "CRITICAL", "", ""
  )
or ignoring (criticality)
  label_replace(
    avg_over_time({"compute.googleapis.com/instance/cpu/utilization", monitored_resource="gce_instance"}[5m]) >= 0.8,
    "criticality", "WARNING", "", ""
  )
or ignoring (criticality)
  label_replace(
    avg_over_time({"compute.googleapis.com/instance/cpu/utilization", monitored_resource="gce_instance"}[5m]) >= 0.7,
    "criticality", "INFO", "", ""
  )
or ignoring (criticality)
  label_replace(
    avg_over_time({"compute.googleapis.com/instance/cpu/utilization", monitored_resource="gce_instance"}[5m]),
    "criticality", "GOOD", "", ""
  )
The following figure illustrates how alerting policies that use PromQL queries process the time-series data they monitor:
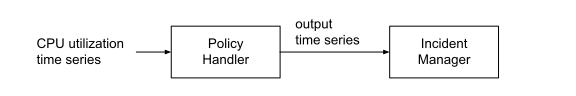
The policy handler processes the CPU utilization data and outputs a time series that indicates when the condition is met. In the previous example, the condition is met when the CPU utilization is at least 70%. For each input time series, the policy handler can generate one of four time series:
| Output time series name | Condition met | Description |
|---|---|---|
| "GOOD" | No | This time series has the same labels as the input time series. It doesn't have a severity label. |
| "CRITICAL" | Yes | The CPU utilization is at least 90%. The output time series has the same labels as the "GOOD" time series plus a severity label with the value of "CRITICAL". |
| "WARNING" | Yes | The CPU utilization is at least 80% but less than 90%. The output time series has the same labels as the "GOOD" time series plus a severity label with the value of "WARNING". |
| "INFO" | Yes | The CPU utilization is at least 70% but less than 80%. The output time series has the same labels as the "GOOD" time series plus a severity label with the value of "INFO". |
The time-series data generated by the policy handler is the input to the
alert manager, which determines when alerts are created and
closed. To determine when to close an alert, the alert manager
uses the values of the duration, evaluationMissingData,
and autoClose fields.
Best practices
To verify that at most one alert is open at a time when you create labels whose values are set dynamically, do the following:
In the
MetricThresholdobject, override the default values for the following fields:durationfield: Set to a non-zero value.evaluationMissingDatafield: Set so that alerts are closed when data stops arriving. When you use the Cloud Monitoring API, set this field toEVALUATION_MISSING_DATA_INACTIVE. When you use the Google Cloud console, set the field to "Missing data points treated as values that don't violate the policy condition".
In the
AlertStrategyobject, set theautoClosefield to its minimum value of 30 minutes. When you use the Cloud Monitoring API, set this field to30m.
For more information, see Partial metric data.
Alert flow
Suppose that the CPU utilization measurements are less than 70% when the alerting policy is created. The following sequence illustrates how alerts are opened and closed:
Because the CPU utilization measurements are less than 70%, the policy handler generates the "GOOD" time series and no alerts are opened.
Next, assume the CPU utilization rises to 93%. The policy handler stops generating the "GOOD" time-series data and starts generating data for the "CRITICAL" time series.
The alert manager sees a new "CRITICAL" time series that meets the condition, and then opens an alert. The notification includes the severity label with a value of
CRITICAL.Assume the CPU utilization falls to 75%. The policy handler stops generating the "CRITICAL" time series and starts generating the "INFO" time series.
The alert manager sees a new "INFO" time series that meets the condition, and then opens an alert. The notification includes the severity label with a value of
INFO.The alert manager sees that no data is arriving for the "CRITICAL" time series and that an alert is open for that time series. Because the policy is configured to close alerts when data stops arriving, the alert manager closes the alert associated with the "CRITICAL" time series. Therefore, only the alert whose severity label has a value of
INFOremains open.Finally, assume that the CPU utilization falls to 45%. This value is less than all thresholds, so the policy handler stops generating the "INFO" time series and starts generating the "GOOD" time series.
The alert manager sees that no data is arriving for the "INFO" time series and that an alert is open for that time series. Because the policy is using the recommended settings, the alert is closed.
If you don't use the recommended value for the evaluationMissingData field,
then when data stops arriving, open alerts aren't closed immediately.
The result is that you might see multiple open alerts for the same
input time series. For more information, see
Partial metric data.
What's next
- Create alerting policies by using the Monitoring API
- Create alerting policies by using PromQL
- Handling partial metric data