

To give your operational applications low-latency, transactional access to your analytical data, sync tables from BigQuery into your AlloyDB for PostgreSQL instance. Unlike a foreign data wrapper (FDW), which queries data in BigQuery, the sync feature copies the data into AlloyDB storage so that your queries read from local tables to improve performance.
AlloyDB provides the following ways to move BigQuery data into your instance:
One-time sync: creates a writable, independent copy of your BigQuery table.
Periodic sync or mirroring: creates a read-only local table that automatically refreshes on a schedule—for example, every 6 hours or daily.
Performance and operational considerations
When you use BigQuery sync tables, consider the following:
- Resource usage: data movement consumes CPU and memory. For very large tables, consider scheduling syncs during off-peak hours to avoid affecting your primary transactional workload.
- Data visibility: during a replace operation, the existing target table is dropped and recreated upfront. Queries during the import see an empty table initially, followed by newly imported data appearing incrementally as batch transactions commit.
Before you begin
- Set the
alloydb_sync.enabled=ondatabase flag on your AlloyDB instance. For more information, see Configure an instance's database flags. - Familiarize yourself with how the
bigquery_fdwhandles BigQuery data types and column mappings, because thealloydb_syncextension usesbigquery_fdwto connect to BigQuery. - Sign in to your Google Cloud account. If you're new to Google Cloud, create an account to evaluate how our products perform in real-world scenarios. New customers also get $300 in free credits to run, test, and deploy workloads.
-
In the Google Cloud console, on the project selector page, select or create a Google Cloud project.
Roles required to select or create a project
- Select a project: Selecting a project doesn't require a specific IAM role—you can select any project that you've been granted a role on.
-
Create a project: To create a project, you need the Project Creator role
(
roles/resourcemanager.projectCreator), which contains theresourcemanager.projects.createpermission. Learn how to grant roles.
-
Verify that billing is enabled for your Google Cloud project.
-
In the Google Cloud console, on the project selector page, select or create a Google Cloud project.
Roles required to select or create a project
- Select a project: Selecting a project doesn't require a specific IAM role—you can select any project that you've been granted a role on.
-
Create a project: To create a project, you need the Project Creator role
(
roles/resourcemanager.projectCreator), which contains theresourcemanager.projects.createpermission. Learn how to grant roles.
-
Verify that billing is enabled for your Google Cloud project.
-
Enable the Cloud APIs necessary to create and connect to AlloyDB.
-
To confirm the name of the project you are going to make changes to, in the Confirm project step, click Next.
-
In the Enable APIs step, click Enable to enable the following:
- AlloyDB API
- Compute Engine API
- Cloud Resource Manager API
- Service Networking API
- BigQuery Storage API
The Service Networking API is required if you plan to configure network connectivity to AlloyDB using a VPC network that resides in the same Google Cloud project as AlloyDB.
The Compute Engine API and Cloud Resource Manager API are required if you plan to configure network connectivity to AlloyDB using a VPC network that resides in a different Google Cloud project.
-
- Ensure you have an existing BigQuery table to sync data from. For more information, see Create and use BigQuery tables.
Required roles
To grant the BigQuery dataset access to the AlloyDB cluster service account, you need the following permissions:
- BigQuery Data Viewer
(
roles/bigquery.dataViewer) or any custom role with permissionsbigquery.tables.getandbigquery.tables.getData. When granted on a service account, this role provides permissions to read data and metadata from the table or view. - BigQuery Read Session User
(
roles/bigquery.readSessionUser) or any custom role with permissionsbigquery.readsessions.createandbigquery.readsessions.getData. Provides the ability to create and use read sessions. - BigQuery Job User
(
roles/bigquery.jobUser) or any custom role with permissionsbigquery.jobs.create. Provides the ability to create and run jobs, including query jobs. When you provide a separate runtime project, the job is run in that project instead of in the data project. This means that you must grant the Job User role on the runtime project.
Configure the extension
Before you sync tables from BigQuery, enable the required extension and configure the connection to BigQuery. If you use the Google Cloud console, AlloyDB performs these steps automatically.
Create the extension.
- Connect to the AlloyDB instance using the psql client by following the instructions in Connect a psql client to an instance.
Run the following command:
CREATE EXTENSION IF NOT EXISTS alloydb_sync;
To let AlloyDB authenticate with BigQuery, create the foreign server and user mapping:
CREATE EXTENSION IF NOT EXISTS bigquery_fdw; CREATE SERVER IF NOT EXISTS bigquery_server FOREIGN DATA WRAPPER bigquery_fdw OPTIONS (runtime_project 'RUNTIME_PROJECT_ID'); CREATE USER MAPPING IF NOT EXISTS FOR USER SERVER bigquery_server;Replace the following:
RUNTIME_PROJECT_ID: optional. The ID of the Google Cloud project that processes the query and accrues compute costs. If omitted, the queries are billed to the project that stores the data.USER: a database username or an IAM user that accesses the BigQuery table.
Sync a BigQuery table for one-time export
You can sync a BigQuery table for one-time export using the Google Cloud console or by using psql.
Use the Google Cloud console
To sync a BigQuery table to AlloyDB using the Google Cloud console, do the following:
Open the BigQuery page in the Google Cloud console.
In the left pane, click Explorer:
If you don't see the left pane, click Expand left pane to open the pane.
In the Explorer pane, expand your project, click Datasets, and then click your dataset.
Click Overview > Tables, and then select a table.
In the details pane, click More > Export or sync to AlloyDB.
Under Choose a project, select the project for your AlloyDB cluster. If you have the required permissions, you can select a project other than your current BigQuery project.
Under Choose a target cluster, select one of the following options:
Select Use an existing cluster to export the BigQuery table to an existing AlloyDB cluster. Then, do the following:
Select the primary AlloyDB cluster.
Select the destination AlloyDB database.
Select the schema for your destination AlloyDB table.
Specify a name for your destination AlloyDB table.
For Sync frequency, select Just once to create a copy of the BigQuery table.
Click Setup export.
When the sync setup is complete, you can use the provided SQL statements to track the import job and query the imported tables. Click Query to be directed to your imported table in AlloyDB studio.
Select Create a new cluster to export the BigQuery table to a new AlloyDB cluster. Then, do the following:
Click Setup export.
In the Redirect to AlloyDB dialog, select Redirect.
Select a cluster type, either Free trial cluster or Provisioned cluster.
Click Continue.
In Sync Configuration, select the default
postgresdestination AlloyDB database, the defaultpublicschema for your destination AlloyDB table, and specify a name for your destination AlloyDB table.For Sync frequency, select Just once to create a copy of the BigQuery table.
Click Continue.
Configure your cluster. For more information about each field, see Create a new cluster and primary instance.
Click Create cluster.
When the sync setup is complete, navigate to AlloyDB studio to query your imported tables.
Sync a BigQuery table one-time using psql
To create an editable copy of BigQuery data, use
psql to run the alloydb_sync.import_bq_table
function.
SELECT alloydb_sync.import_bq_table(
  'PROJECT_ID.DATASET_ID.TABLE_ID',
  'ALLOYDB_DESTINATION_TABLE_NAME',
  'ON_EXISTS',
  ARRAY['PRIMARY_KEY_COLUMN']
);
Replace the following:
PROJECT_ID: the ID of the project where the BigQuery dataset resides.DATASET_ID: the name of the BigQuery dataset for the table. For Iceberg tables with a 4-part name, this is theCatalog.Namespace.TABLE_ID: the name of the BigQuery table or view.ALLOYDB_DESTINATION_TABLE_NAME: the name of the local table in the AlloyDB database to create and import data into. You can include the schema name—for example,public.local_sales.ON_EXISTS: the strategy to use if the destination table already exists.PRIMARY_KEY_COLUMN: an optional list of column names to use as the primary key.
Example
The following example shows how to sync a table named transactions from a
BigQuery dataset into a new AlloyDB table named
public.local_sales:
SELECT alloydb_sync.import_bq_table(
    'my-gcp-project.sales_data.transactions',
    'public.local_sales',
    'replace'
);
on_exists parameter
The on_exists parameter determines how the function handles the sync if the
destination table already exists in AlloyDB:
error: the default option. Stops the sync if the destination table already exists.skip: skips the sync if the destination table already exists.replace: replaces the existing local table with fresh data from BigQuery.
Primary key support
If you provide the optional primary_key parameter as a text array,
AlloyDB creates the table with the specified columns as the
primary key.
SELECT alloydb_sync.import_bq_table(
    'my-gcp-project.sales_data.transactions',
    'public.local_sales',
    ARRAY['transaction_id']
);
Sync a BigQuery table for periodic export
You can sync a BigQuery table for periodic export using the Google Cloud console or by using psql.
Use the Google Cloud console
To sync a BigQuery table to AlloyDB using the Google Cloud console, do the following:
Open the BigQuery page in the Google Cloud console.
In the left pane, click Explorer:
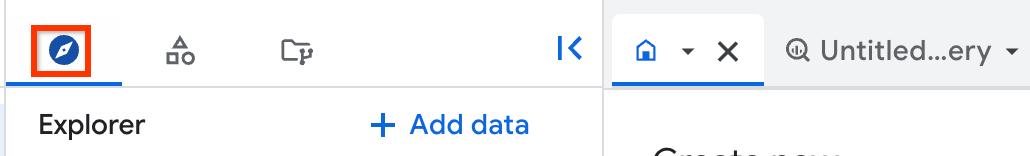
If you don't see the left pane, click Expand left pane to open the pane.
In the Explorer pane, expand your project, click Datasets, and then click your dataset.
Click Overview > Tables, and then select a table.
In the details pane, click More > Export or sync to AlloyDB.
Under Choose a project, select the project for your AlloyDB cluster. If you have the required permissions, you can select a project other than your current BigQuery project.
Under Choose a target cluster, select one of the following options:
Select Use an existing cluster to export the BigQuery table to an existing AlloyDB cluster. Then, do the following:
Select the primary AlloyDB cluster.
Select the destination AlloyDB database.
Select the schema for your destination AlloyDB table.
Specify a name for your destination AlloyDB table.
For Sync frequency, select a timeframe to create a periodic sync of the BigQuery table—for example, Every hour, Every six hours.
Click Setup export.
When the sync setup is complete, you can use the provided SQL statements to track the import job and query the imported table. Click Query to be directed to your imported table in AlloyDB studio.
Select Create a new cluster to export the BigQuery table to a new AlloyDB cluster. Then, do the following:
Click Setup export.
In the Redirect to AlloyDB dialog, select Redirect.
Select a cluster type, either Free trial cluster or Provisioned cluster.
Click Continue.
In Sync Configuration, select the default
postgresdestination AlloyDB database, the defaultpublicschema for your destination AlloyDB table, and specify a name for your destination AlloyDB table.For Sync frequency, select Just once to create a copy of the BigQuery table.
Click Continue.
Configure your cluster. For more information about each field, see Create a new cluster and primary instance.
Click Create cluster.
When the sync setup is complete, navigate to AlloyDB studio to query your imported tables.
Create a periodic sync
To maintain a read-only table that stays synced with BigQuery
data, use psql to run the alloydb_sync.create_bq_sync_table function.
SELECT alloydb_sync.create_bq_sync_table(
    'PROJECT_ID.DATASET_ID.TABLE_ID',
    'ALLOYDB_DESTINATION_TABLE_NAME',
    'REFRESH_INTERVAL',
    'ON_EXISTS',
    ARRAY['PRIMARY_KEY_COLUMN']
);
Replace the following:
PROJECT_ID.DATASET_ID.TABLE_ID: The fully qualified name of the BigQuery table or view, including the project ID, dataset ID, and table ID, separated by periods. For Iceberg tables with a 4-part name, theDATASET_IDis represented asCatalog.Namespace. For example,my-gcp-project.sales_data.transactions.ALLOYDB_DESTINATION_TABLE_NAME: the name of the local table in the AlloyDB database to create and sync data into.REFRESH_INTERVAL: the interval at which AlloyDB periodically refreshes data from BigQuery—for example,12 hours.ON_EXISTS: the strategy to use if the destination table already exists.PRIMARY_KEY_COLUMN: an optional list of column names to use as the primary key.
Example
The following example shows how to create a customer profile mirror that refreshes every 12 hours:
SELECT alloydb_sync.create_bq_sync_table(
    'my-gcp-project.crm_data.profiles',
    'public.customer_mirror',
    '12 hours',
    'replace'
);
Monitor and manage jobs
After you initiate a sync, you can monitor its progress and manage the jobs.
Check job status
Large syncs can take time. You can monitor progress, including records
processed and estimated completion time, by querying the job_status view:
SELECT
    import_id,
    status,
    records_processed,
    total_records,
    error_message
FROM alloydb_sync.job_status;
For example, to cancel the job, run the following command:
SELECT alloydb_sync.cancel_import_job('85bb5dfa-dfb9-4017-9153-738f55abe4b1');
Stop and delete a sync job
To stop mirroring a BigQuery table and delete the local table,
use the alloydb_sync.delete_bq_sync_table function:
SELECT alloydb_sync.delete_bq_sync_table('public.customer_mirror');
Data type mappings
When you sync or import data from BigQuery to
AlloyDB using the alloydb_sync extension,
AlloyDB maps BigQuery data types to
corresponding PostgreSQL data types in your target table.
Verify that your source BigQuery table columns use the supported data types listed in the following table:
| BigQuery table data types | PostgreSQL data types |
|---|---|
BOOLEAN |
BOOLEAN |
INTEGER (INT64) |
BIGINT |
FLOAT (FLOAT64) |
DOUBLE PRECISION |
STRING |
TEXT |
NUMERIC |
NUMERIC |
BIGNUMERIC |
NUMERIC |
DATE |
DATE |
TIMESTAMP |
TIMESTAMPTZ |
TIME |
TIME |
DATETIME |
TIMESTAMP |
JSON |
JSONB |
BYTES |
BYTEA |
Limitations
The following limitations apply when syncing tables from BigQuery:
- This feature is supported for PostgreSQL version 18 only.
- This feature requires the
alloydb_sync.enabled=ondatabase flag on the instance. - When you configure the
bigquery_fdwforeign server and user mapping in a database, you must name the foreign serverbigquery_server. - Complex BigQuery data types such as
ARRAY,STRUCT,VECTOR,GEOGRAPHY,RANGE, andINTERVALaren't supported for synchronization. Parameterized BigQuery data types such asSTRING(L),BYTES(L),NUMERIC(P, S), andBIGNUMERIC(P, S)map toTEXT. For more information, see the supported BigQuery data types and column mappings. - When you specify the
primary_keyparameter, the comma-separated list of primary key column names must not exceed 1,023 bytes. In addition, the JSON-serialized primary key column names and values for a row must not exceed 255 bytes. - For periodic sync tables created with the
alloydb_sync.create_bq_sync_tablefunction, therefresh_intervalparameter doesn't support months or years. Specify the interval as a whole number of days, hours less than 24, minutes less than 60, or seconds less than 60. Mixed-unit intervals, such as1 hour 30 minutesor90 minutes, are truncated to the whole number of the largest time unit, such as1 hour. Only the database user who initiated a sync job or created a periodic sync table can do the following:
- View the job in the
alloydb_sync.job_statusview - Cancel the job with the
alloydb_sync.cancel_import_jobfunction - Delete the sync table with the
alloydb_sync.delete_bq_sync_tablefunction
- View the job in the
Sync jobs commit data incrementally in batches rather than in a single transaction. During a
replaceoperation, the destination table is dropped and recreated before data loads, so concurrent queries see an empty or partially populated table until the job finishes. If an import job fails or is canceled before completion, partially imported rows and an internal foreign table definition remain in the database. To recover, rerun the import with theon_existsparameter set toreplace.If an interruption occurs during the initial background import for a newly registered periodic sync table, the table remains incomplete until its next scheduled refresh interval.
Standard
DROP DATABASEcommands fail while the background job tracker worker is connected to a database that has periodic sync tables or sync activity within the last 10 seconds.In databases that have no periodic sync tables configured using the
alloydb_sync.create_bq_sync_tablefunction, the background job tracker worker shuts down after 10 seconds of idle time. The worker allocates a new dynamic shared memory segment on the nextalloydb_sync.import_bq_tablefunction call or when thealloydb_syncextension is dropped and recreated. Running a large number of isolated one-time imports separated by idle periods without an active periodic sync table can exhaust shared memory slots, requiring an instance restart.
Best practices
Follow these best practices when configuring and managing table syncs from BigQuery:
- Run the
CREATE EXTENSION IF NOT EXISTS alloydb_sync CASCADE;statement in its own committed transaction before calling any sync functions. - Avoid modifying the source BigQuery table during an import. If the source table is updated concurrently, a sync job might import the updated data.
- Specify a consistent, schema-qualified destination table name, such as
public.my_table, when calling thealloydb_sync.import_bq_table,alloydb_sync.create_bq_sync_table, oralloydb_sync.delete_bq_sync_tablefunctions. Don't start multiple sync jobs for the same destination table at the same time. If you sync tables in multiple databases on the same cluster, use distinct schema or table names across databases. - When creating a periodic sync table with the
alloydb_sync.create_bq_sync_tablefunction, set theon_existsparameter toreplaceso that scheduled refreshes update the destination table. Specify therefresh_intervalparameter as a single whole unit of days, hours less than 24, minutes less than 60, or seconds less than 60. - When importing very large BigQuery tables, increase the value
of the
temp_file_limitdatabase flag, and optionally the value of thework_memflag, on your instance so that the import doesn't exceed the temporary file size limit. During an import, incoming rows are buffered in memory up to thework_memlimit and then staged in local PostgreSQL temporary files before batch commits complete. - Don't manually run the
DROP TABLEstatement on a replicated sync table or a table with an active import. To stop an in-progress import, first run thealloydb_sync.cancel_import_jobfunction as the database user who started the job. To remove a periodic sync table and its schedule, use thealloydb_sync.delete_bq_sync_tablefunction and pass the exact destination table name that you used when creating the sync table. - If a one-time import fails or is canceled before completion, rerun the
alloydb_sync.import_bq_tablefunction with theon_existsparameter set toreplace. If the initial background import for a newly registered periodic sync table is interrupted and you want to resolve it immediately instead of waiting for the next scheduled refresh, delete the sync table using thealloydb_sync.delete_bq_sync_tablefunction and recreate it. If background worker slots in
max_worker_processesare exhausted when a job starts, or if the database crashes while an import is queued or running, the job metadata might remain stuck in theQUEUEDorRUNNINGstate and block future imports to that table. To unblock the table, update the job status as the database user who started the job by running the following command:UPDATE alloydb_sync.import_job_status SET status = 'FAILED' WHERE status IN ('QUEUED', 'RUNNING');To drop a database that has periodic sync tables or recent sync activity, run
DROP DATABASE DATABASE_NAME WITH (FORCE), or first delete all sync tables and wait at least 10 seconds for the background tracker worker to exit. You can verify whether the worker is still connected to the database by querying thepg_stat_activityview:SELECT pid, datname, backend_type FROM pg_stat_activity WHERE datname = 'DATABASE_NAME' AND backend_type = 'job_tracker';Replace
DATABASE_NAMEwith the name of your database.
Pricing
When you sync data from BigQuery to AlloyDB, you are billed using BigQuery streaming reads (Storage Read API) pricing.
After the data is exported, you're charged for storing the data in AlloyDB. For more information, see AlloyDB for PostgreSQL pricing.
What's next
- Learn more about Export data to AlloyDB (reverse ETL).
- Learn more about querying BigQuery data in-place using FDW.