This document describes the tools and files you can use to monitor and troubleshoot Managed Service for Apache Spark
[batch workloads](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-batch.md.txt).
## Troubleshoot workloads from the Google Cloud console
When a batch job fails or has poor performance, a recommended first step is to open
its **Job details** (**Batch details** ) page by clicking the batch **Job ID** on the
**Serverless Spark** tab of the [**Jobs**](https://console.cloud.google.com/dataproc/jobs)
page in the Google Cloud console.
### Use the Summary tab: your troubleshooting Hub
The **Summary** tab, which is selected by default when the batch **Job details** page
opens, displays critical metrics and filtered logs to help you make a quick
initial assessment of batch health. After this initial assessment, you can perform
a deeper analysis using more specialized tools available from the batch **Job details** page,
such as the [Spark UI](https://docs.cloud.google.com/managed-spark/docs/guides/monitor-troubleshoot-batches.md.txt#spark_ui),
the [Logs Explorer](https://docs.cloud.google.com/logging/docs/view/logs-explorer-interface.md.txt), and
[Gemini Cloud Assist](https://docs.cloud.google.com/managed-spark/docs/guides/ai-investigations-with-gca.md.txt).
### Batch metric highlights
The **Summary** and **Monitoring** tabs on the batch **Job details** page include charts that display
important batch workload metric values. The metric charts populate after the
completes, and offer a visual indication of potential issues such as resource
contention, data skew, or memory pressure.
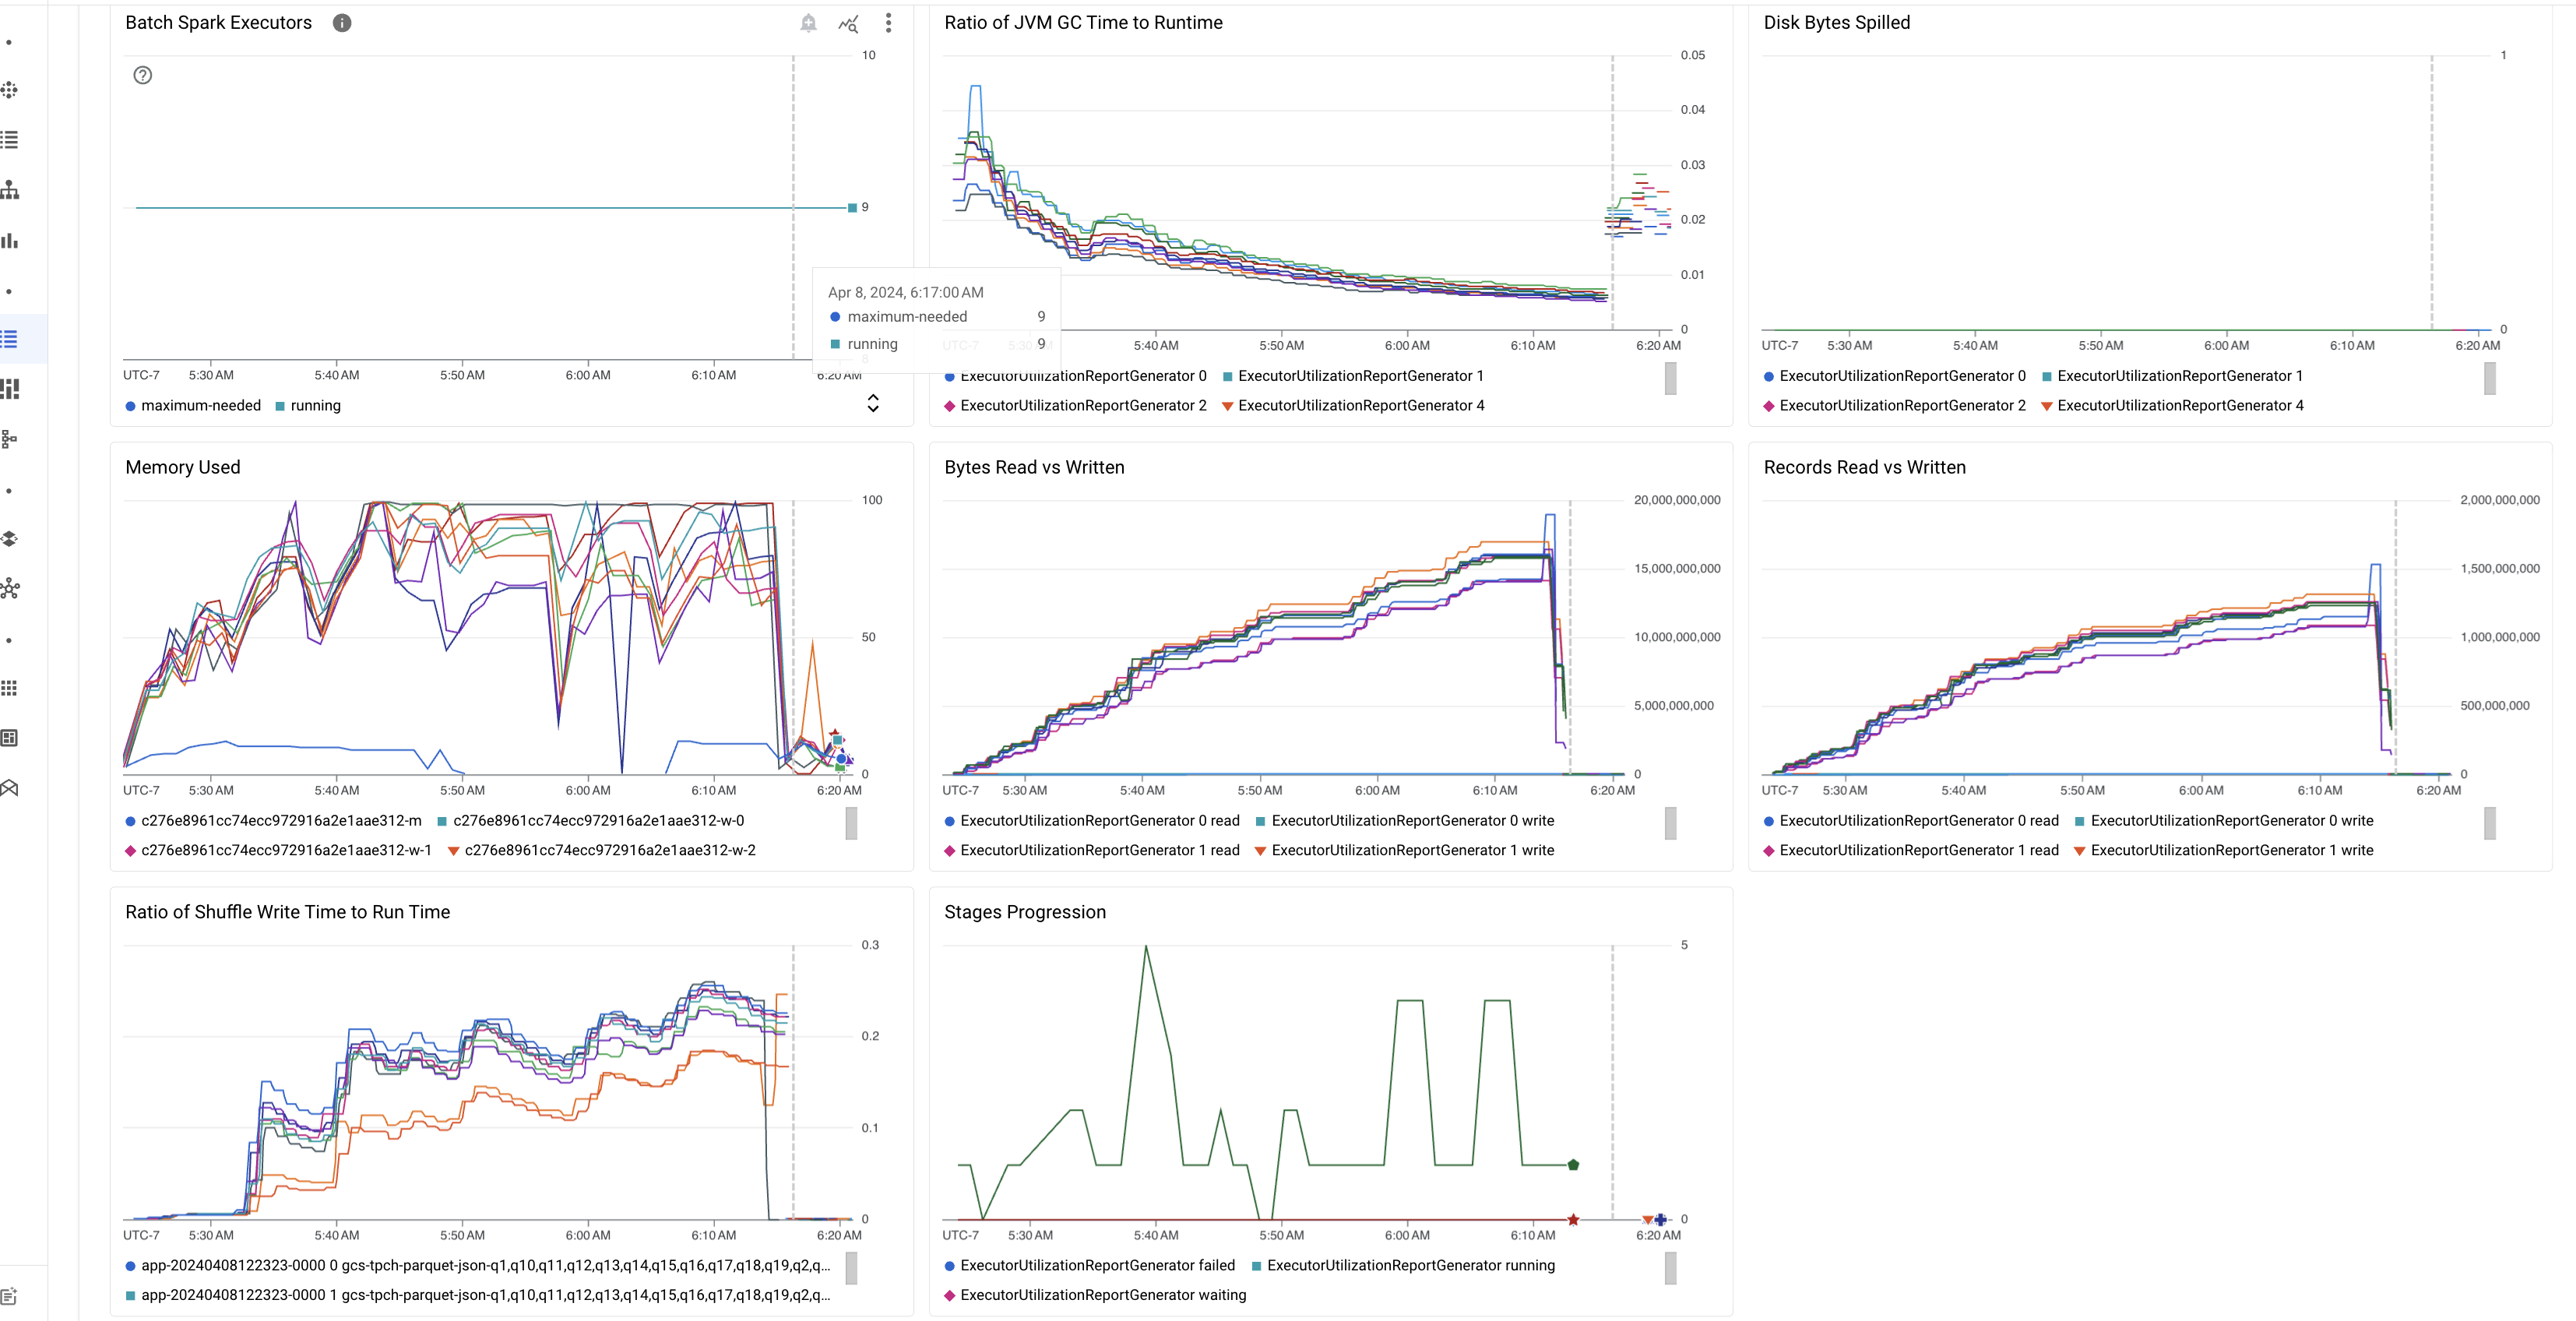
**Metrics table**
The following table lists the Spark workload metrics displayed on the
batch **Job details** page in the Google Cloud console, and describes how metric
values can provide insight into workload status and performance.
| Metric | What does it show? |
| Metrics at the Executor level ||
|---|---|
| Ratio of JVM GC Time to Runtime | This metric shows the ratio of JVM GC (garbage collection) time to runtime per executor. High ratios can indicate memory leaks within tasks running on particular executors or inefficient data structures, which can lead to high object churn. |
| Disk Bytes Spilled | This metric shows the total number of disk bytes spilled across different executors. If an executor shows high disk bytes spilled, this can indicate data skew. If the metric increases over time, this can indicate that there are stages with memory pressure or memory leaks. |
| Bytes Read and Written | This metric shows the bytes written versus bytes read per executor. Large discrepancies in bytes read or written can indicate scenarios where replicated joins lead to data amplification on specific executors. |
| Records Read and Written | This metric shows records read and written per executor. Large numbers record read with low numbers of records written can indicate a bottleneck in processing logic on specific executors, leading to records being read while waiting. Executors that consistently lag in reads and writes can indicate resource contention on those nodes or executor-specific code inefficiencies. |
| Ratio of Shuffle Write Time to Run Time | The metric shows the amount of time the executor spent in shuffle runtime as compared to overall runtime. If this value is high for some executors, it can indicate data skew or inefficient data serialization. You can identify stages with long shuffle write times in the Spark UI. Look for outlier tasks within those stages taking more than the average time to complete. Check whether the executors with high shuffle write times also show high disk I/O activity. More efficient serialization and additional partitioning steps might help. Very large record writes compared to record reads can indicate unintended data duplication due to inefficient joins or incorrect transformations. |
| Stages Progression | This metric shows the number of stages in failed, waiting, and running stages. A large number of failed or waiting stages can indicate data skew. Check for data partitions, and debug the reason for stage failure using the **Stages** tab in the Spark UI. |
| Batch Spark Executors | This metric shows the number of executors that might be required versus the number of executors running. A large difference between required and running executors can indicate autoscaling issues. |
| Memory Used | This metric shows the percentage of VM memory in use. If the master percentage is high, it can indicate that the driver is under memory pressure. For other VM nodes, a high percentage can indicate that the executors are running out of memory, which can lead to high disk spillage and a slower workload runtime. Use the Spark UI to analyze executors to check for high GC time and high task failures. Also debug Spark code for large dataset caching and unnecessary broadcast of variables. |
### Job logs
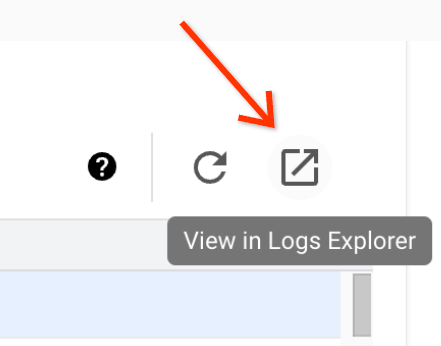
The batch **Job details** page includes a **Job logs** tab (and log highlights) that lists warnings and errors filtered from the job (batch workload) logs. This feature allows for quick identification of critical issues without needing to manually parse through extensive log files. You can select a log **Severity** (for example, `Error`) from the drop-down menu and add a text **Filter** to narrow down the results. To perform a more in-depth analysis, click the **View in Logs Explorer** icon
to open the selected batch logs in the [Logs Explorer](https://docs.cloud.google.com/logging/docs/view/logs-explorer-interface.md.txt).
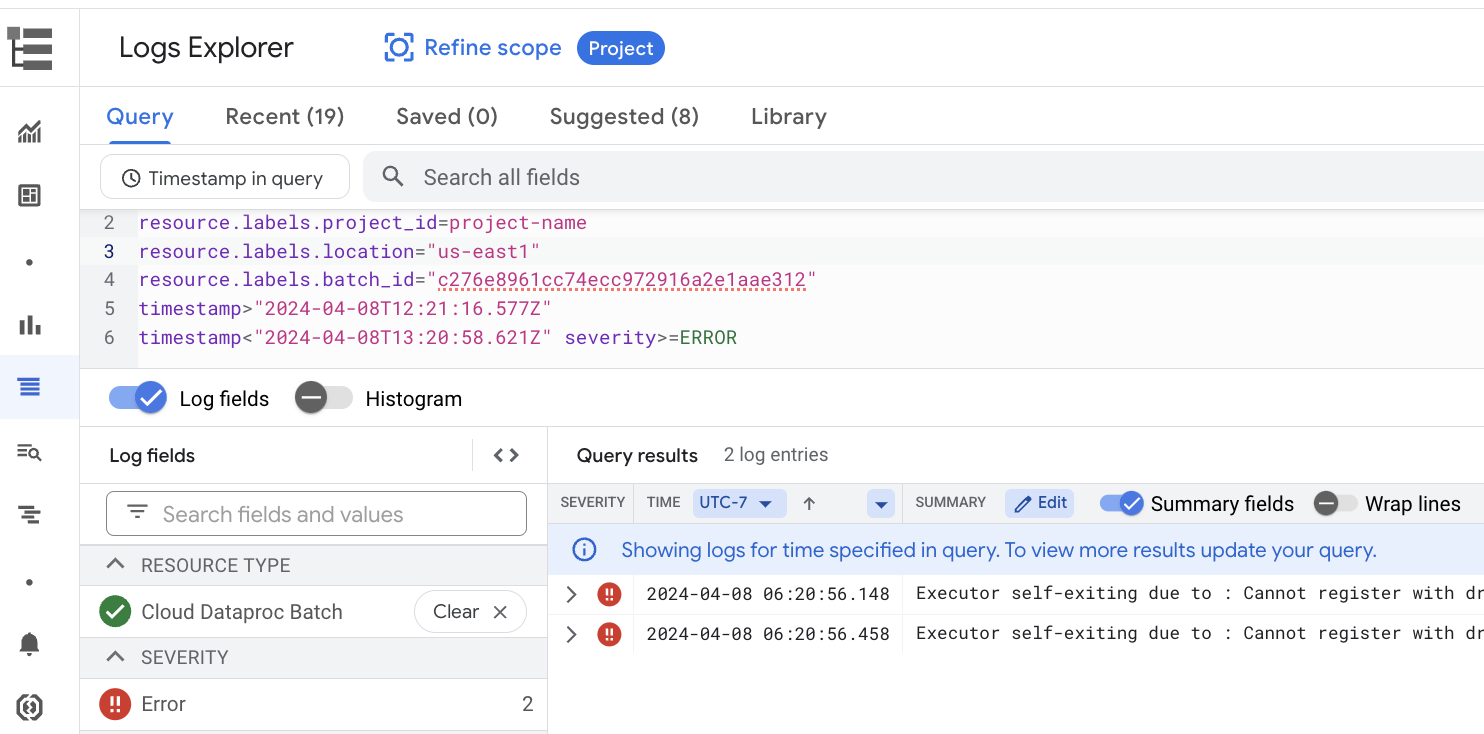
 View batch logs in Cloud Logging
Example: **Logs Explorer** opens after choosing `Errors` from the Severity
selector on the batch **Job details** page in the Google Cloud console.
## Spark UI
The Spark UI collects Apache Spark execution details from Managed Service for Apache Spark
batch workloads. There is no charge for the Spark UI feature, which is
enabled by default.
Data collected by the Spark UI feature is retained for 90 days. You can use this
web interface to monitor and debug Spark workloads without having to create a
[Persistent History Server](https://docs.cloud.google.com/managed-spark/docs/guides/monitor-troubleshoot-batches.md.txt#persistent_history_server).
> [!NOTE]
> **Note:** The Spark UI also collects and displays execution details from Managed Service for Apache Spark interactive sessions. See [Monitor and troubleshoot Managed Service for Apache Spark interactive sessions](https://docs.cloud.google.com/managed-spark/docs/guides/monitor-troubleshoot-sessions.md.txt) for more information.
### Required Identity and Access Management permissions and roles
The following permissions are required to use the Spark UI feature with batch
workloads.
- Data collection permission: `dataproc.batches.sparkApplicationWrite`. This
permission must be granted to the service account that runs batch workloads.
This permission is included in the
[`Managed Service for Apache Spark Worker`](https://docs.cloud.google.com/iam/docs/roles-permissions/dataproc.md.txt#dataproc.worker)
role, which is automatically granted to the Compute Engine default service account
that Managed Service for Apache Spark uses by default (see
[Managed Service for Apache Spark service account](https://docs.cloud.google.com/managed-spark/docs/concepts/service-account)).
However, if you specify a
[custom service account](https://docs.cloud.google.com/managed-spark/docs/concepts/service-account)
for your batch workload, you must add the `dataproc.batches.sparkApplicationWrite`
permission to that service account (typically, by granting the service account
the Managed Service for Apache Spark `Worker` role).
- Spark UI access permission: `dataproc.batches.sparkApplicationRead`. This
permission must be granted to a user to access the Spark UI in the
Google Cloud console. This permission is included in the
[`Dataproc Viewer`, `Dataproc Editor` and `Dataproc Administrator`](https://docs.cloud.google.com/managed-spark/docs/concepts/iam#roles)
roles. To open the Spark UI in the Google Cloud console, you must have one of
these roles or have a custom role that includes this permission.
### Open the Spark UI
The Spark UI page is available in the Google Cloud console batch workloads.
1. In the Google Cloud console, go to the Managed Service for Apache Spark
**Jobs** page.
[Go to Managed Service for Apache Spark Jobs](https://console.cloud.google.com/dataproc/jobs)
2. Select the **Serverless Spark** tab, and click a batch **Job ID** to open
its **Job details** page.
3. Click **View in Spark UI** (next to **Spark application ID** ) or **View Spark UI**.
The **View in Spark UI** link is disabled in the following cases:
- If a [required permission](https://docs.cloud.google.com/managed-spark/docs/guides/monitor-troubleshoot-batches.md.txt#required-iam-permissions-and-roles) isn't granted
- If the Spark UI isn't enabled on the batch **Job details** page
- If you set the `spark.dataproc.appContext.enabled` property to `false` when you [submit a batch workload](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-batch.md.txt#submit_a_spark_batch_workload)
## Managed Service for Apache Spark logs
Logging is enabled by default in Managed Service for Apache Spark, and workload logs persist after a
workload finishes. Managed Service for Apache Spark collects workload logs in [Cloud Logging](https://docs.cloud.google.com/logging/docs.md.txt).
You can access Managed Service for Apache Spark logs under the
`Cloud Dataproc Batch` resource in the Logs Explorer.
### Query Managed Service for Apache Spark logs
The Logs Explorer in the Google Cloud console provides
a [query pane](https://docs.cloud.google.com/logging/docs/view/building-queries.md.txt#building-queries)
to help you build a query to examine batch workload logs.
Here are steps you can follow to build a query to examine batch workload
logs:
1. [Go to Logs Explorer](https://console.cloud.google.com/logs/query)
2. Your current project is selected. You can click **Refine scope Project** to select a different project.
3. Define a batch logs query.
- Use [filter menus](https://docs.cloud.google.com/logging/docs/view/building-queries.md.txt#query-builder-menus)
to filter for a batch workload.
1. Under **All resources** , select the **Cloud Managed Service for Apache Spark Batch** resource.
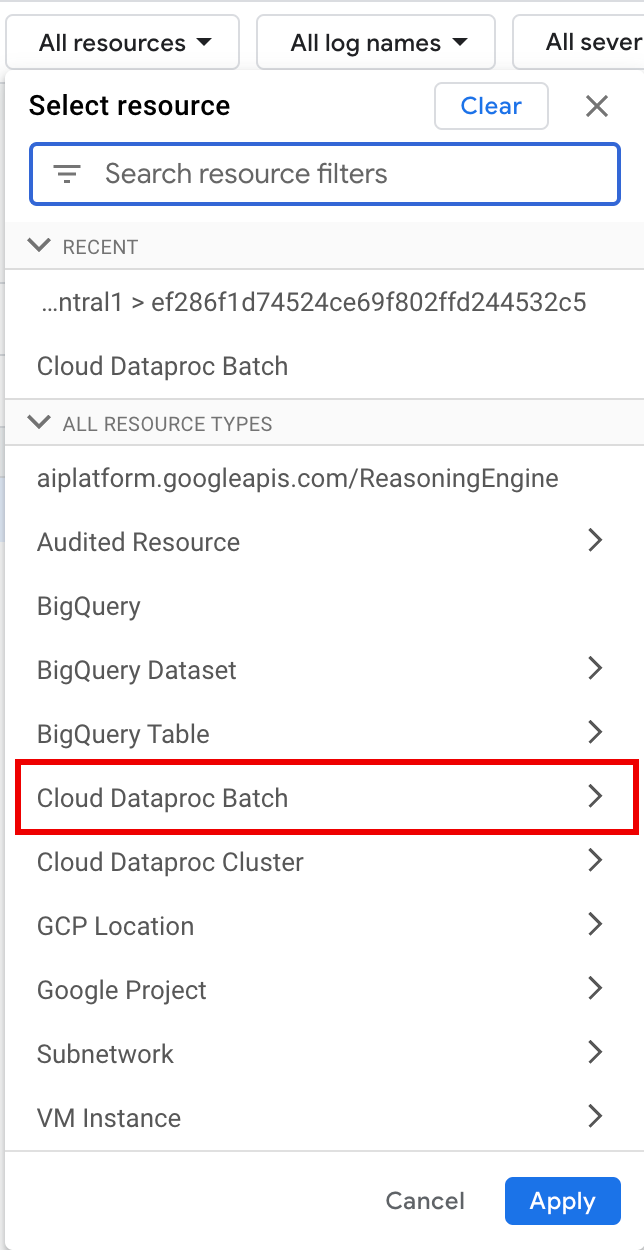
1. In the **Select resource** panel, select the batch **LOCATION** , then the
**BATCH ID** . These batch parameters are listed on the
**Serverless Spark** tab of the Managed Service for Apache Spark
[**Jobs**](https://console.cloud.google.com/dataproc/jobs)
page in the Google Cloud console.
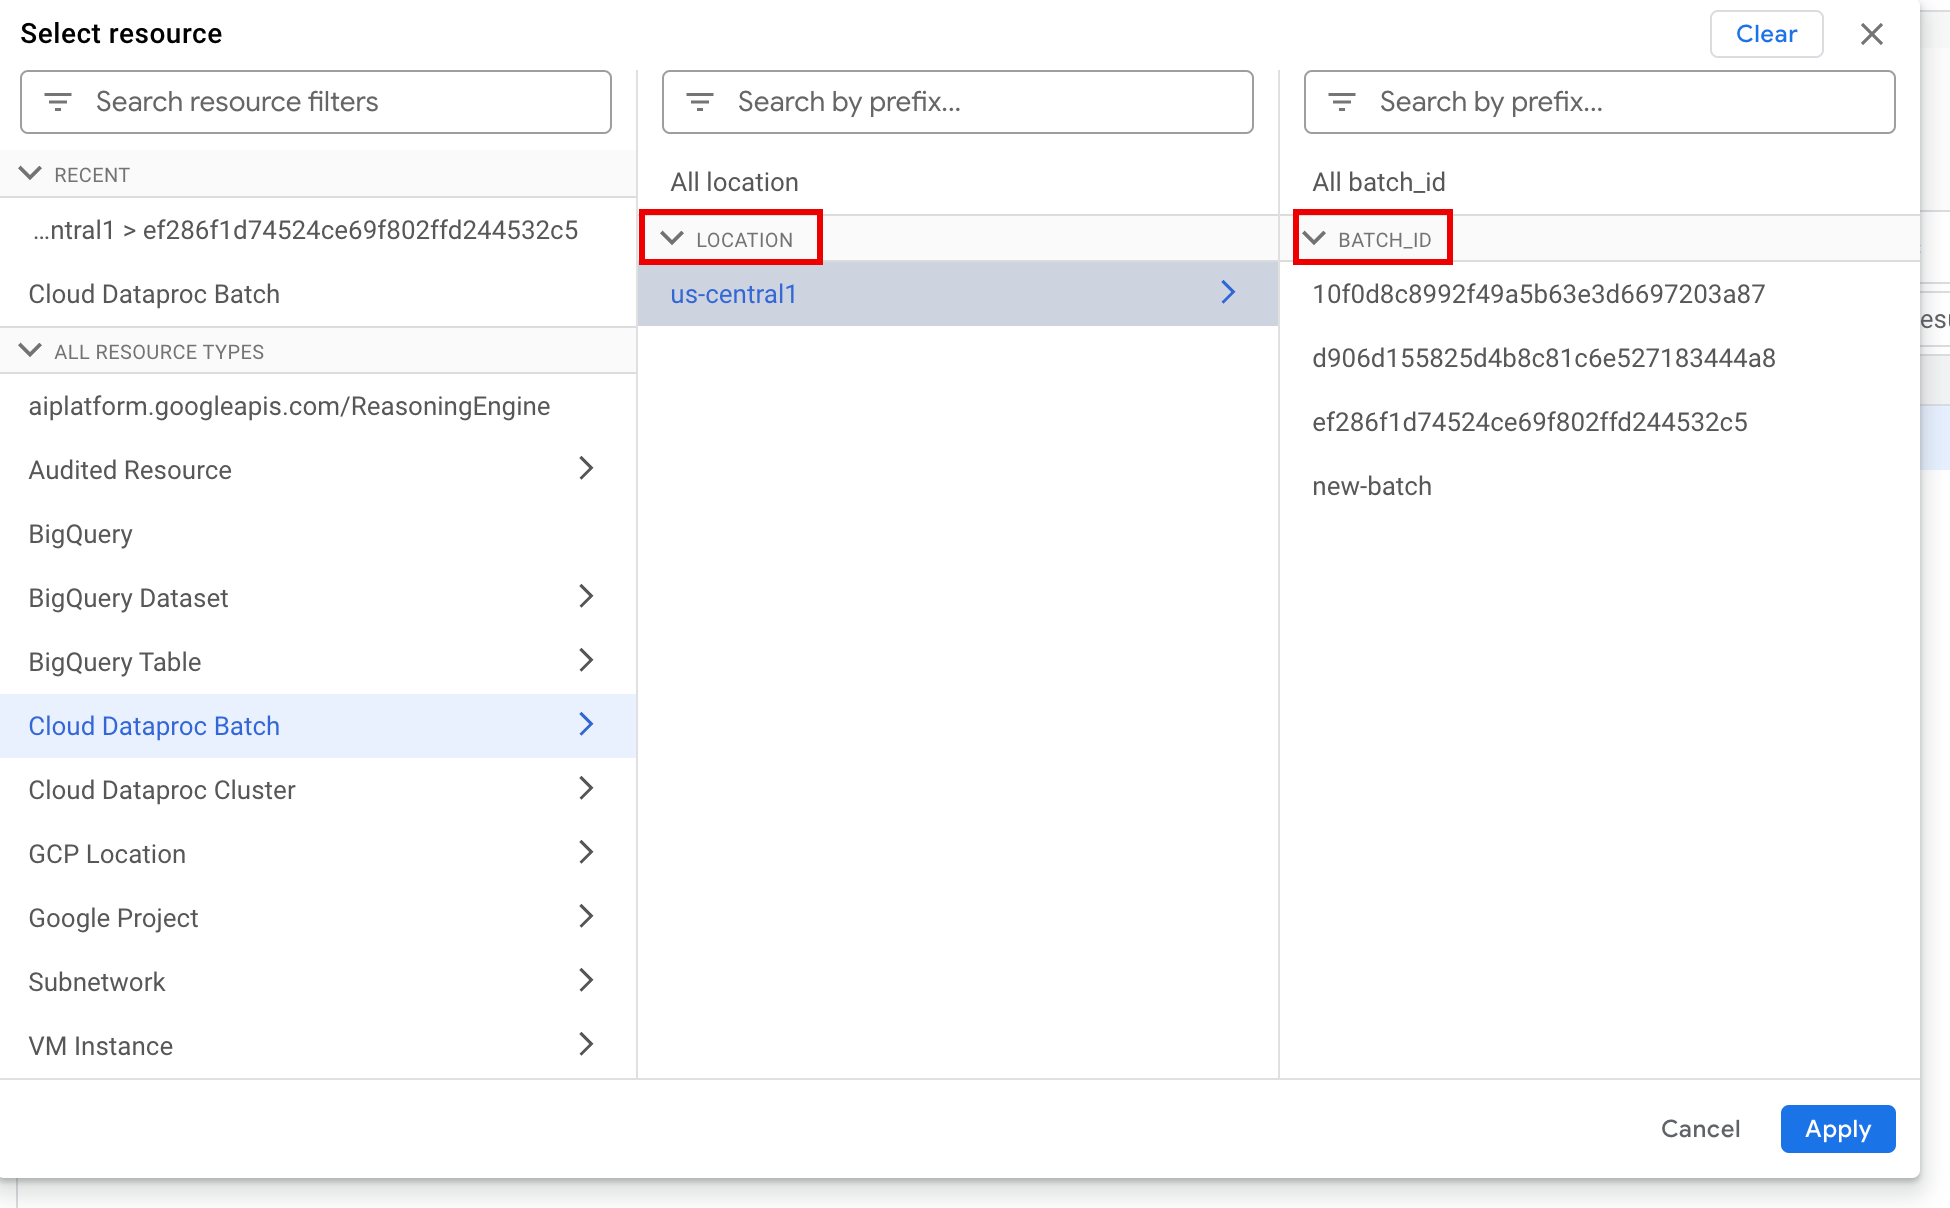
2. Click **Apply**.
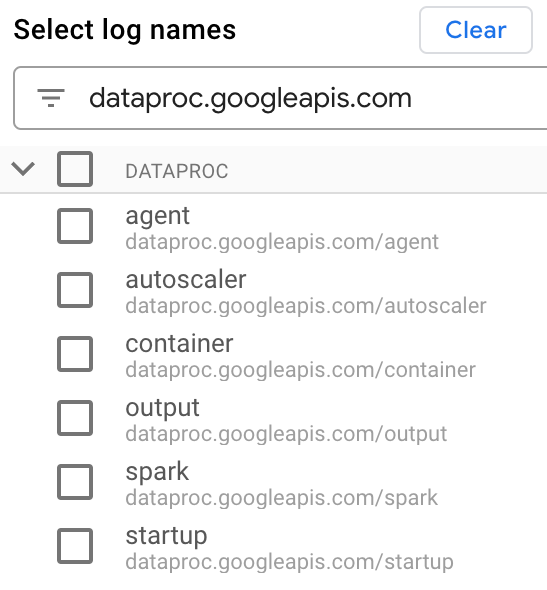
3. Under **Select log names** . enter `dataproc.googleapis.com`
in the **Search log names** box to limit the log types to query. Select
one or more of the listed log file names.
- Use the query editor to filter for VM-specific logs.
1. Specify the resource type and VM resource name as shown in the following example:
```
resource.type="cloud_dataproc_batch"
labels."dataproc.googleapis.com/resource_name"="VM_NAME_PREFIX-BATCH_UUID-VM_SUFFIX"
```
Notes:
- **VM_NAME_PREFIX:** Use `gdpic-rm` for batch workloads that run on Managed Service for Apache Spark `3.0` and later runtime versions; use `gdpic-srvls-batch` for batch workloads that run on earlier runtime versions.
- **BATCH_UUID:** The batch **Job UUID** is listed on the batch **Job details** (**Batch details** ) page in the Google Cloud console, which opens when you click the batch **Job ID** on the **Serverless Spark** tab of the **Jobs** page. 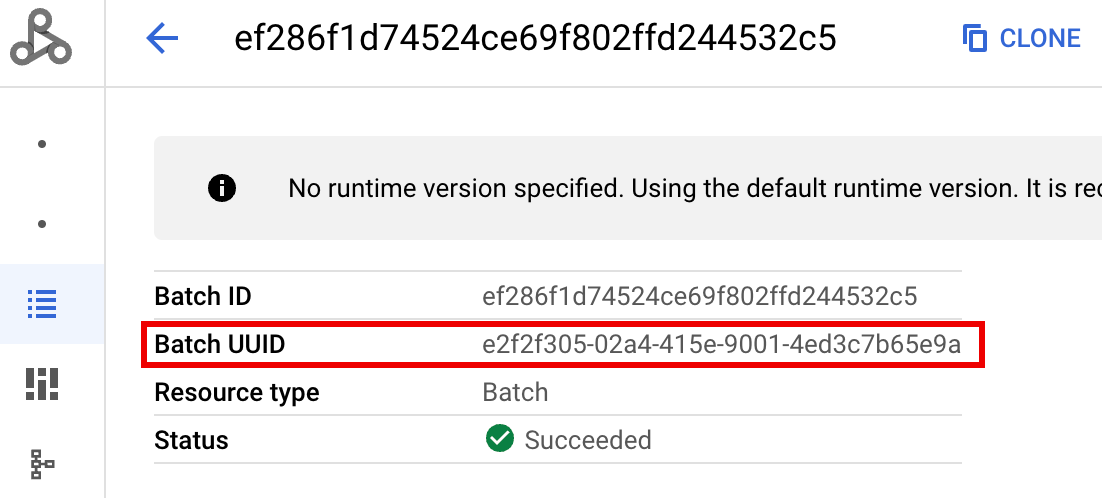
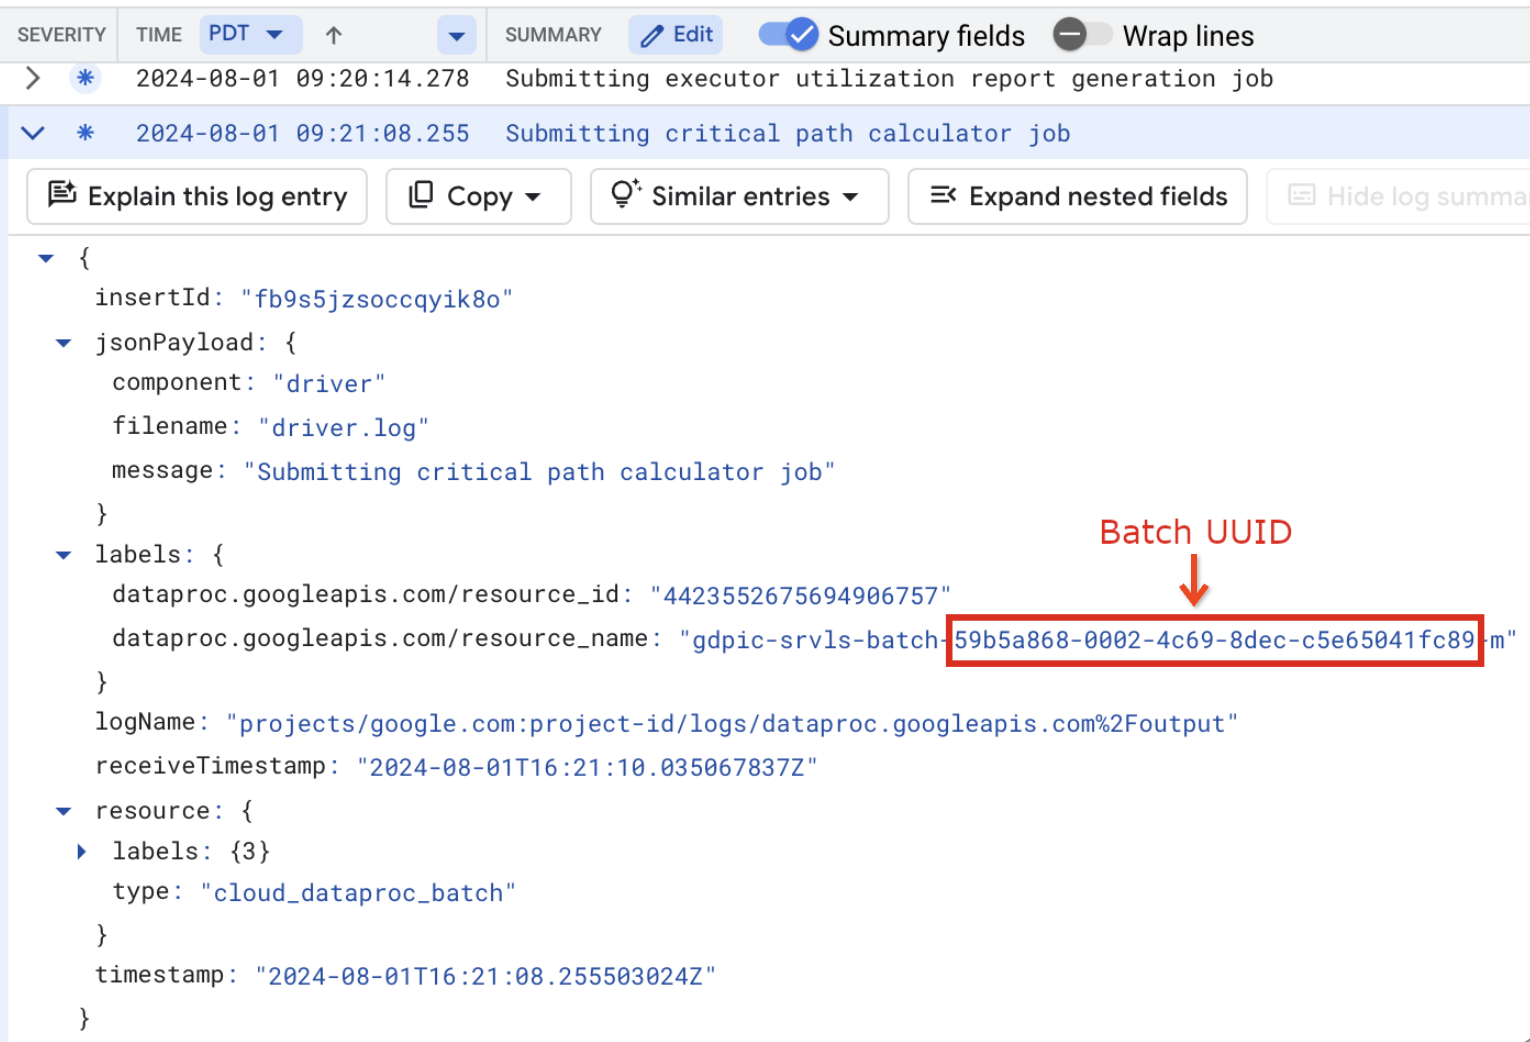
The batch logs also list the batch UUID in the VM resource name.
Here's an example from a batch driver.log:
4. Click **Run query**.
#### Managed Service for Apache Spark log types and sample queries
The following list describes different Managed Service for Apache Spark log types and
provides sample Logs Explorer queries for each log type.
1. `dataproc.googleapis.com/output`: This log file contains batch workload output.
Managed Service for Apache Spark streams batch output to the `output` namespace,
and sets the filename to `JOB_ID.driver.log`.
Sample Logs Explorer query for output logs:
```
resource.type="cloud_dataproc_batch"
resource.labels.location="REGION"
resource.labels.batch_id="BATCH_ID"
logName="projects/PROJECT_ID/logs/dataproc.googleapis.com%2Foutput"
```
2. `dataproc.googleapis.com/spark`: The `spark` namespace aggregates Spark
logs for daemons and executors running on Managed Service for Apache Spark
cluster master and worker VMs. Each log entry includes a
`master`, `worker` or `executor` component label to identify
the log source, as follows:
- `executor`: Logs from user-code executors. Typically, these are distributed logs.
- `master`: Logs from the Spark standalone resource manager master, which are similar to Managed Service for Apache Spark YARN `ResourceManager` logs.
- `worker`: Logs from the Spark standalone resource manager worker, which are similar to Managed Service for Apache Spark YARN `NodeManager` logs.
Sample Logs Explorer query for all logs in the `spark` namespace:
```
resource.type="cloud_dataproc_batch"
resource.labels.location="REGION"
resource.labels.batch_id="BATCH_ID"
logName="projects/PROJECT_ID/logs/dataproc.googleapis.com%2Fspark"
```
Sample Logs Explorer query for Spark standalone component logs in
the `spark` namespace:
```
resource.type="cloud_dataproc_batch"
resource.labels.location="REGION"
resource.labels.batch_id="BATCH_ID"
logName="projects/PROJECT_ID/logs/dataproc.googleapis.com%2Fspark"
jsonPayload.component="COMPONENT"
```
3. `dataproc.googleapis.com/startup`: The `startup` namespace includes the
batch (cluster) startup logs. Any initialization script logs are
included. Components are identified by label, for example:
```
startup-script[855]: ... activate-component-spark[3050]: ... enable spark-worker
```
Sample Logs Explorer query for logs startup logs on a specified VM:
```
resource.type="cloud_dataproc_batch"
resource.labels.location="REGION"
resource.labels.batch_id="BATCH_ID"
logName="projects/PROJECT_ID/logs/dataproc.googleapis.com%2Fstartup"
labels."dataproc.googleapis.com/resource_name"="VM_NAME_PREFIX-BATCH_UUID-VM_SUFFIX"
```
4. `dataproc.googleapis.com/agent`: The `agent` namespace aggregates
Managed Service for Apache Spark agent logs. Each log entry includes filename label
that identifies the log source.
Sample Logs Explorer query for agent logs generated by a specified worker VM:
```
resource.type="cloud_dataproc_batch"
resource.labels.location="REGION"
resource.labels.batch_id="BATCH_ID"
logName="projects/PROJECT_ID/logs/dataproc.googleapis.com%2Fagent"
labels."dataproc.googleapis.com/resource_name"="VM_NAME_PREFIX-BATCHUUID-wWORKER#"
```
5. `dataproc.googleapis.com/autoscaler`: The `autoscaler` namespace aggregates
Managed Service for Apache Spark autoscaler logs.
Sample Logs Explorer query for autoscaler logs generated by a specified worker VM:
```
resource.type="cloud_dataproc_batch"
resource.labels.location="REGION"
resource.labels.batch_id="BATCH_ID"
logName="projects/PROJECT_ID/logs/dataproc.googleapis.com%2Fautoscaler"
labels."dataproc.googleapis.com/resource_name"="VM_NAME_PREFIX-BATCHUUID-wWORKER#"
```
For more information,
see [Managed Service for Apache Spark logs](https://docs.cloud.google.com/managed-spark/docs/guides/logging.md.txt).
For information on Managed Service for Apache Spark audit logs, see
[Managed Service for Apache Spark audit logging](https://docs.cloud.google.com/managed-spark/docs/guides/audit-logging.md.txt).
## Workload metrics
Managed Service for Apache Spark provides batch and Spark metrics that you can view from the
[**Metrics Explorer**](https://docs.cloud.google.com/monitoring/charts/metrics-selector.md.txt) or the
batch **Job details** page in the Google Cloud console.
### Batch metrics
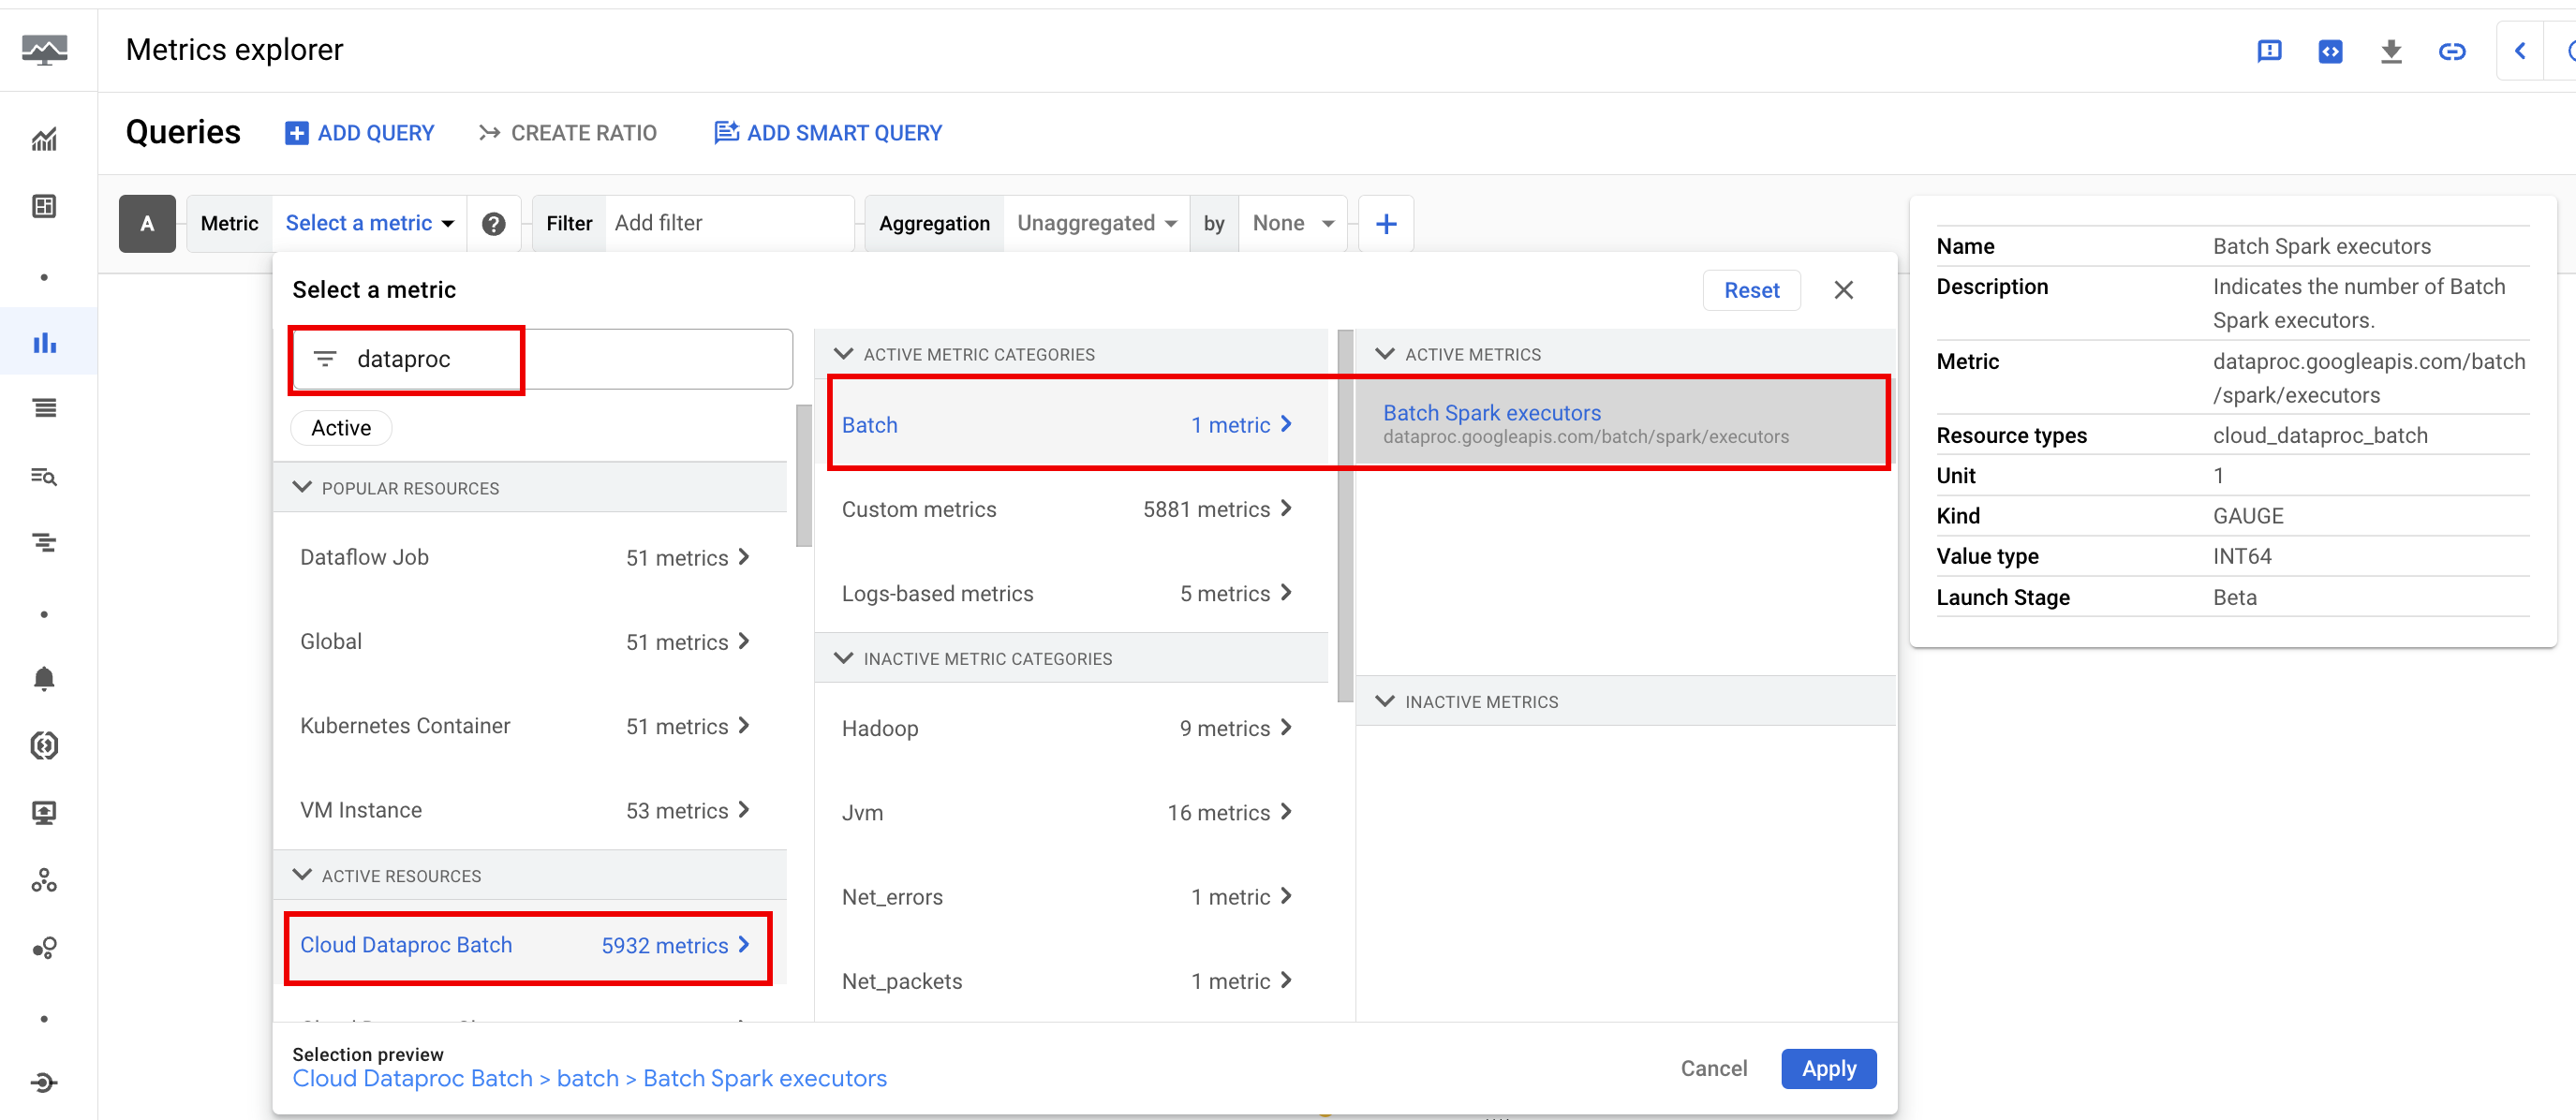
Managed Service for Apache Spark `batch` resource metrics provide insight into batch resources,
such as the number of batch executors. Batch metrics are prefixed with
`dataproc.googleapis.com/batch`.
### Spark metrics
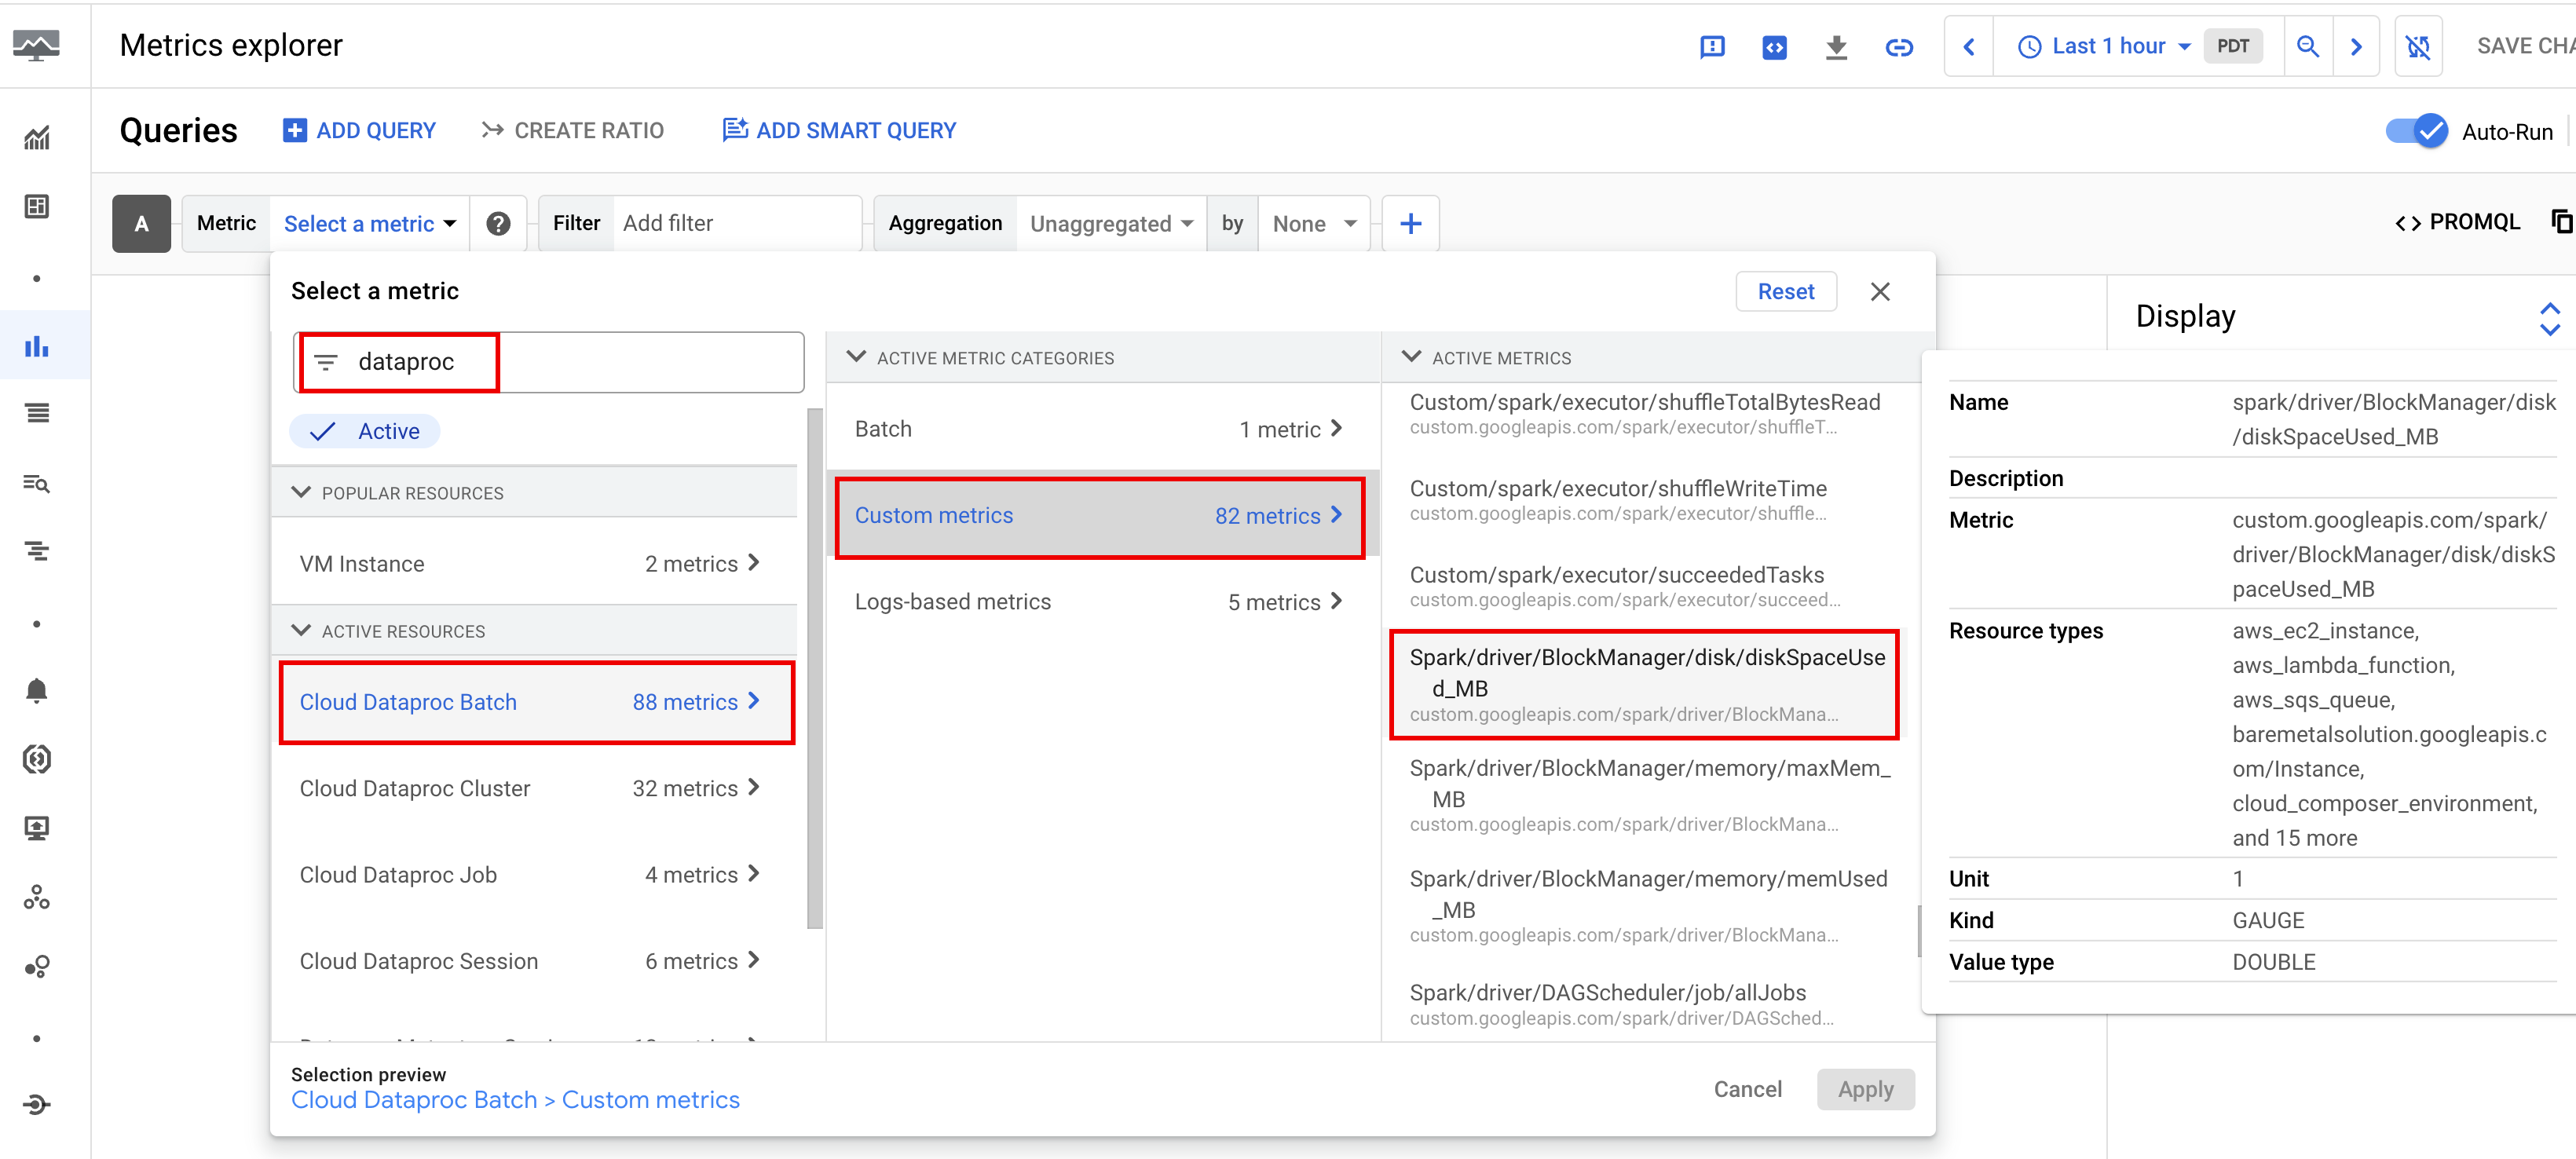
By default, Managed Service for Apache Spark enables the collection of
[available Spark metrics](https://docs.cloud.google.com/managed-spark/docs/concepts/metrics#available_spark_metrics),
unless you use
[Spark metrics collection properties](https://docs.cloud.google.com/managed-spark/docs/concepts/metrics#spark_metrics_collection_properties)
to disable or override the collection of one or more Spark metrics.
[Available Spark metrics](https://docs.cloud.google.com/managed-spark/docs/concepts/metrics#available_spark_metrics)
include Spark driver and executor metrics, and system metrics. Available Spark metrics are prefixed
with `custom.googleapis.com/`.
### Set up metric alerts
You can [create Managed Service for Apache Spark metric alerts](https://docs.cloud.google.com/managed-spark/docs/guides/alerts.md.txt)
to receive notice of workload issues.
### Create charts
You can create charts that visualize workload metrics by using the
[**Metrics Explorer**](https://docs.cloud.google.com/monitoring/charts/metrics-selector.md.txt) in the
Google Cloud console. For example, you can
create a chart to display `disk:bytes_used`, and then filter by `batch_id`.
## Cloud Monitoring
Monitoring uses workload metadata and metrics to provide insights
into the health and performance of Managed Service for Apache Spark workloads.
Workload metrics include Spark metrics, batch metrics, and operation metrics.
You can use [Cloud Monitoring](https://console.cloud.google.com/monitoring) in the Google Cloud console
to explore metrics, add charts, create dashboards, and create alerts.
### Create dashboards
You can create a dashboard to monitor workloads using metrics from multiple
projects and different Google Cloud products. For more information, see
[Create and manage custom dashboards](https://docs.cloud.google.com/monitoring/charts/dashboards.md.txt).
## Persistent History Server
Managed Service for Apache Spark creates the compute resources that are needed to run a workload,
runs the workload on those resources, and then deletes the resources when the workload finishes.
Workload metrics and events don't persist after a workload completes. However, you can use a
Persistent History Server (PHS) to retain workload application history (event
logs) in Cloud Storage.
To use a PHS with a batch workload, do the following:
1. [Create a Managed Service for Apache Spark Persistent History Server (PHS)](https://docs.cloud.google.com/managed-spark/docs/concepts/jobs/history-server.md.txt#create_a_phs_cluster).
> [!NOTE]
> **Note:** The [Spark UI](https://docs.cloud.google.com/managed-spark/docs/guides/monitor-troubleshoot-batches.md.txt#spark_ui) page in the Google Cloud console collects and displays Spark workload execution details that help you monitor and debug your workloads without requiring the creation of a PHS cluster.
2. Specify your PHS when you [submit a workload](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-batch.md.txt#submit_a_spark_batch_workload).
3. Use the [Component Gateway](https://docs.cloud.google.com/managed-spark/docs/concepts/jobs/history-server.md.txt#component_gateway_web_interfaces)
to connect to the PHS to view application details, scheduler stages, task level details, and
environment and executor information.
## Autotuning
- **Enable autotuning for Managed Service for Apache Spark:** You can enable Autotuning for Managed Service for Apache Spark when you submit each recurring Spark batch workload using the Google Cloud console, gcloud CLI, or the Managed Service for Apache Spark API.
### Console
Perform the following steps to enable autotuning on each recurring Spark batch workload:
1. In the Google Cloud console, go to the Managed Service for Apache Spark
**Jobs** page.
[Go to Managed Service for Apache Spark Jobs](https://console.cloud.google.com/dataproc/jobs)
2. To create a batch workload, click **Submit job** to open the **Submit a job**
page.
3. Under **Select compute type for job** , confirm that **Serverless Spark** is
selected.
4. In the **Serverless job details** section:
1. Specify a **Job ID** or accept the default ID.
2. Select a **Runtime profile** (or keep **Default service configuration** for your region), and then click **Configure** in the **Summary** card (or click **Create new profile** in the **Runtime profile** menu) to open the runtime profile configuration panel.
3. In the runtime profile configuration panel, expand **Additional
configuration** , and then click **Edit** next to **Other
customizations**.
4. In the **Other customizations** panel, under **Autotuning** , click the **Enable** toggle and fill in the **Cohort ID** , which identifies the batch as one of a series of recurring workloads. Gemini-assisted analysis is applied to the second and subsequent workloads that are submitted with this cohort ID. For example, specify `tpch-query1` as the cohort ID for a scheduled workload that runs a daily TPC-H query.
5. Click **Save** in the **Other customizations** panel, and then click **Use configuration** (or **Save new profile**) in the runtime profile configuration panel.
5. Fill in the **Files and artifacts** and **Job execution and properties**
sections on the **Submit a job** page as needed, and then click **Submit** .
For more information, see
[Submit a batch workload](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-batch.md.txt#dataproc_serverless_create_batch_workload-console).
### gcloud
Run the following gcloud CLI
[`gcloud dataproc batches submit`](https://docs.cloud.google.com/sdk/gcloud/reference/dataproc/batches/submit.md.txt)
command locally in a terminal window or in [Cloud Shell](https://console.cloud.google.com/?cloudshell=true)
to enable autotuning on each recurring Spark batch workload:
```bash
gcloud dataproc batches submit COMMAND \
--region=REGION \
--cohort=COHORT \
other arguments ...
```
Replace the following:
- COMMAND: the Spark workload type, such as `Spark`, `PySpark`, `Spark-Sql`, or `Spark-R`.
- REGION: the [region](https://docs.cloud.google.com/compute/docs/regions-zones.md.txt#available) where your workload will run.
- COHORT: the cohort name, which identifies the batch as one of a series of recurring workloads. Gemini-assisted analysis is applied to the second and subsequent workloads that are submitted with this cohort name. For example, specify `TPCH Query 1` as the cohort name for a scheduled workload that runs a daily TPC-H query.
### API
Include the `RuntimeConfig.cohort`
name in a [batches.create](https://docs.cloud.google.com/managed-spark/docs/reference/rest/v1/projects.locations.batches/create.md.txt)
request to enable autotuning on each recurring Spark
batch workload. Autotuning is applied to the second and subsequent workloads submitted with this cohort name. For example, specify `TPCH-Query1` as the cohort name for a scheduled workload that runs a daily TPC-H query.
Example:
```bash
...
runtimeConfig:
cohort: TPCH-Query1
...
```