This document describes how to install and use the JupyterLab
extension on a machine or self-managed VM that has access to Google services. It
also describes how to develop and deploy serverless Spark notebook code.
Install the extension within minutes to take advantage of the following features:
- Launch serverless Spark \& BigQuery notebooks to develop code quickly
- Browse and preview BigQuery datasets in JupyterLab
- Edit Cloud Storage files in JupyterLab
- Schedule a notebook on Composer
> [!NOTE]
> **Note:** The JupyterLab extension is pre-installed on Vertex AI Workbench instances. For more information, see [Create a Spark-enabled Vertex AI Workbench instance](https://docs.cloud.google.com/vertex-ai/docs/workbench/instances/create-dataproc-enabled).
**Use Google Cloud Data Agent Kit** : In addition to JupyterLab, you can also develop
and manage your Managed Service for Apache Spark workloads in VS Code using
[Data Agent Kit](https://docs.cloud.google.com/data-agent-kit/overview.md.txt).
Data Agent Kit lets you manage your entire data workload
lifecycle in your IDE or using a supported agentic CLI, including
[building data pipelines](https://docs.cloud.google.com/data-agent-kit/build-pipelines.md.txt).
## Before you begin
### Required roles
Certain IAM roles are required to
run the examples on this page. Depending on organization policies, these
roles may have already been granted. To check role grants, see
[Do you need to grant roles?](https://docs.cloud.google.com/managed-spark/docs/concepts/iam#do_you_need_to_grant_roles).
For more information about granting roles, see
[Manage access to projects, folders, and organizations](https://docs.cloud.google.com/iam/docs/granting-changing-revoking-access.md.txt).
#### User roles
To get the permissions that
you need to create a interactive notebook session,
ask your administrator to grant you the
following IAM roles:
- [Dataproc Editor](https://docs.cloud.google.com/iam/docs/roles-permissions/dataproc.md.txt#dataproc.editor) (`roles/dataproc.editor`) on the project
- [Service Account User](https://docs.cloud.google.com/iam/docs/roles-permissions/iam.md.txt#iam.serviceAccountUser) (`roles/iam.serviceAccountUser`) on the Compute Engine default service account
#### Service account role
To ensure that the Compute Engine default service account has the necessary
permissions to create an interactive session,
ask your administrator to grant the
[Dataproc Worker](https://docs.cloud.google.com/iam/docs/roles-permissions/dataproc.md.txt#dataproc.worker) (`roles/dataproc.worker`) IAM role to the Compute Engine default service account on the project.
**Important:** You must grant this role to the Compute Engine default service account, *not* to your user account. Failure to grant the role to the correct principal might result in permission errors.
## Install the JupyterLab extension
> [!NOTE]
> **Note:** The JupyterLab extension is provided without charge. However, you're charged for using Google Cloud services. You can use the [pricing calculator](https://cloud.google.com/products/calculator) to generate a cost estimate based on your projected usage of Google Cloud resources.
You can install and use the JupyterLab extension on a
machine or VM that has access to Google services, such as your local machine or
a [Compute Engine VM instance](https://docs.cloud.google.com/compute/docs/instances/create-start-instance.md.txt).
To install the extension, follow these steps:
1. Download and install Python version 3.11 or higher from
[`python.org/downloads`](https://www.python.org/downloads/).
- Verify the Python 3.11+ installation.
```
python3 --version
```
2. Virtualize the Python environment.
```
pip3 install pipenv
```
- Create a installation folder.
```
mkdir jupyter
```
- Change to the installation folder.
```
cd jupyter
```
- Create a virtual environment.
```
pipenv shell
```
3. Install JupyterLab in the virtual environment.
```
pipenv install jupyterlab
```
4. Install the JupyterLab extension.
```
pipenv install bigquery-jupyter-plugin
```
5. [Start JupyterLab](https://jupyterlab.readthedocs.io/en/stable/getting_started/starting.html).
```
jupyter lab
```
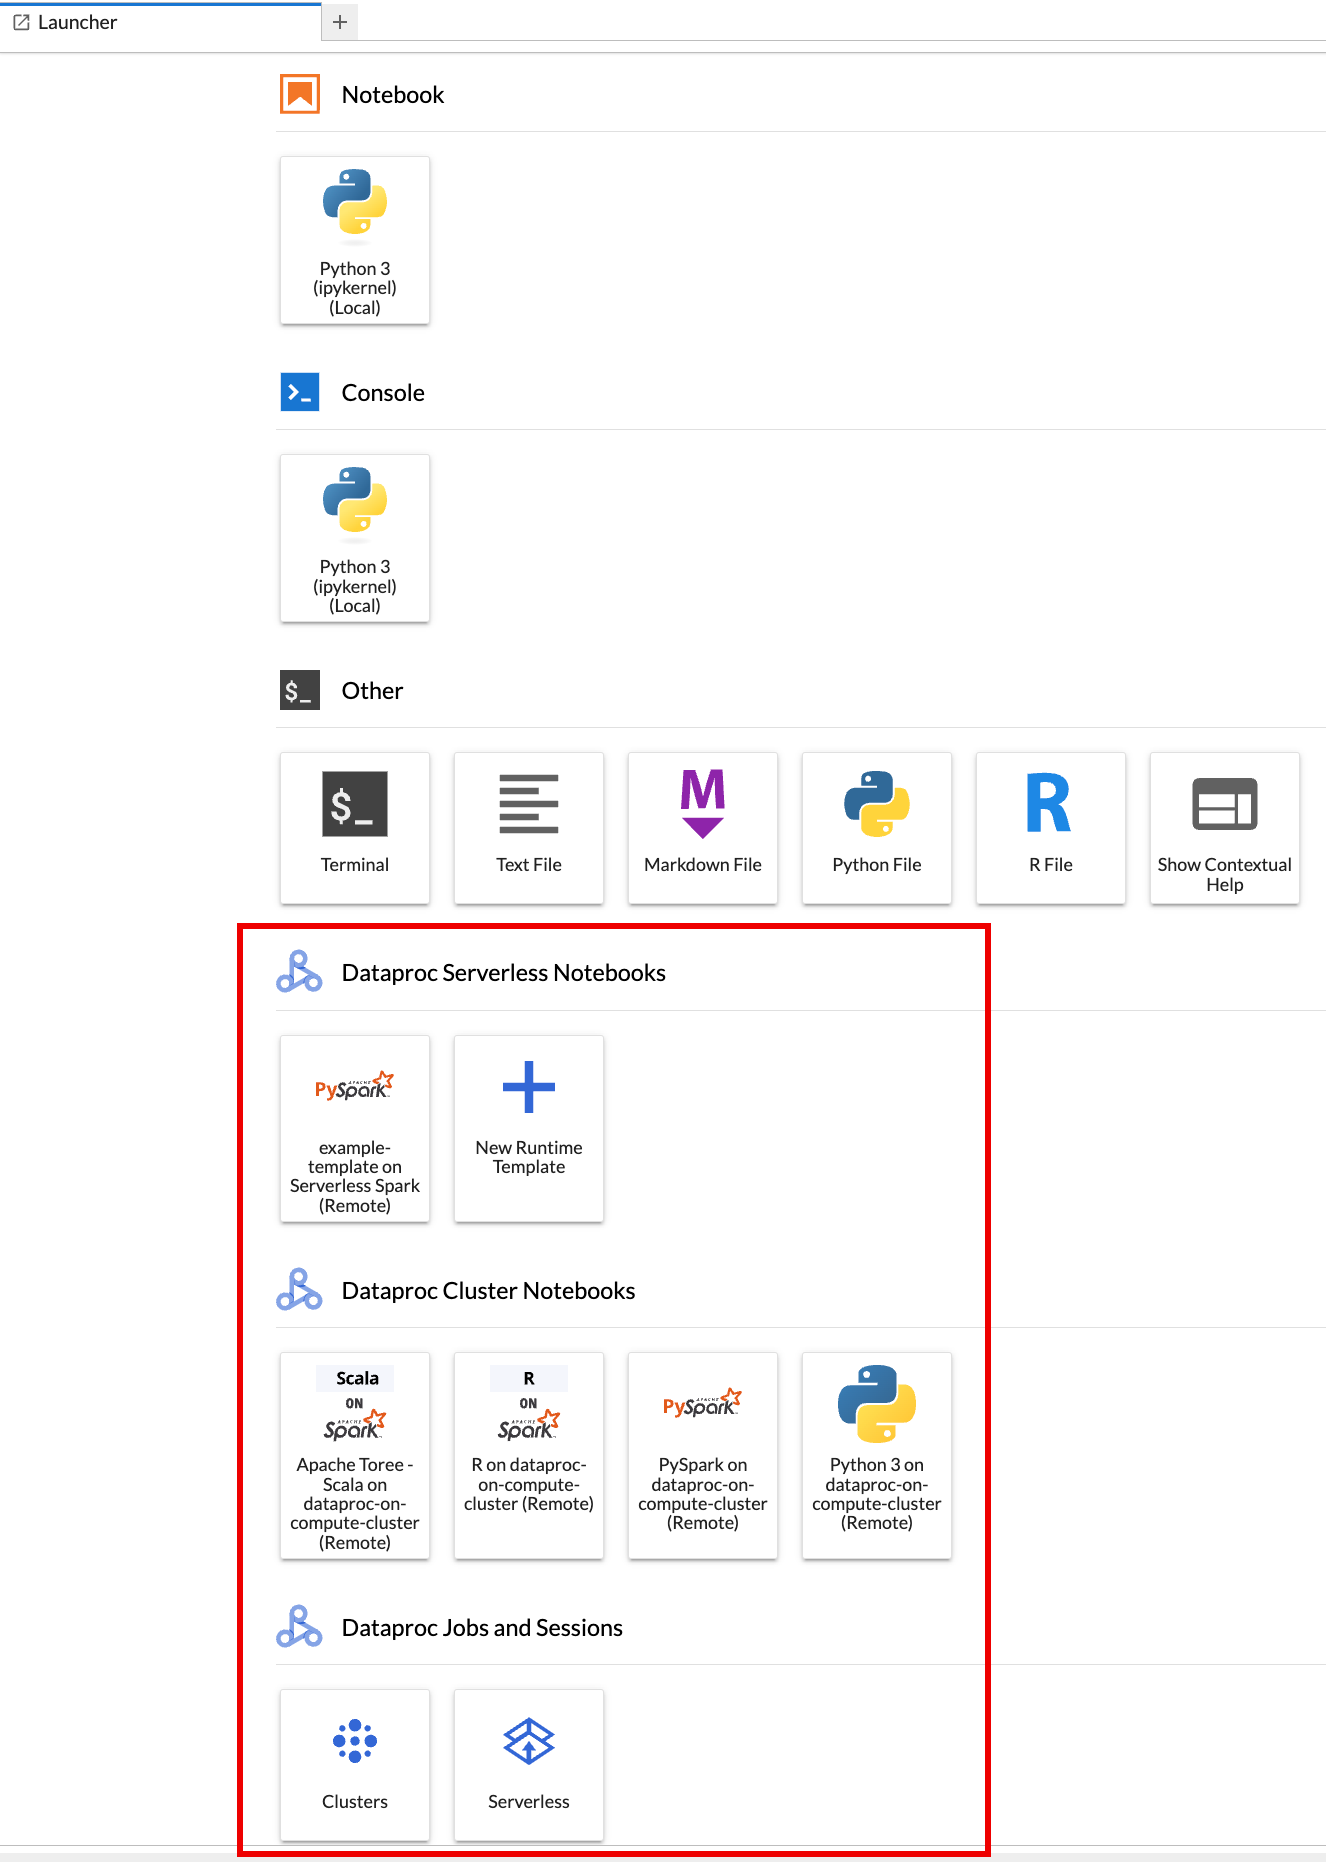
1. The JupyterLab **Launcher** page opens in your browser. It contains
a **Dataproc Jobs and Sessions** section. It can also contain
**Dataproc Serverless Notebooks** and **Dataproc Cluster Notebooks** sections
if you have access to Managed Service for Apache Spark notebooks or clusters
with the [Jupyter optional component](https://docs.cloud.google.com/managed-spark/docs/concepts/components/jupyter.md.txt)
running in your project.
 On macOS, if you receive a **SSL: CERTIFICATE_VERIFY_FAILED** error in your terminal when you launch Jupyterlab, update your Python SSL certificate by executing `Install Certificates.command` from the Python installation path. This file is located in the Python home directory.
2. By default, your interactive session runs
in the project and region you set when you ran `gcloud init` in
[Before you begin](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#before_you_begin). You can change the project and
region settings for your sessions from
JupyterLab **Settings \> Google Cloud Settings \> Google Cloud Project Settings**.
You must restart the extension for the changes to take effect.
## Create a Managed Service for Apache Spark runtime template
Managed Service for Apache Spark runtime templates (called *runtime profiles* on the
[Serverless Runtime Profiles](https://console.cloud.google.com/dataproc/runtimeProfiles) page in the
Google Cloud console and *session templates* in the Google Cloud CLI and
Dataproc API) contain configuration settings for executing Spark code in a
session. You can create and manage runtime templates using JupyterLab, the
[Google Cloud console](https://docs.cloud.google.com/managed-spark/docs/guides/create-serverless-sessions-templates.md.txt#dataproc_serverless_session_template_create-console),
or the Google Cloud CLI.
### JupyterLab
1. Click the `New runtime template` card in the **Dataproc Serverless Notebooks**
section on the JupyterLab **Launcher** page.
2. Fill in the **Runtime template** form.
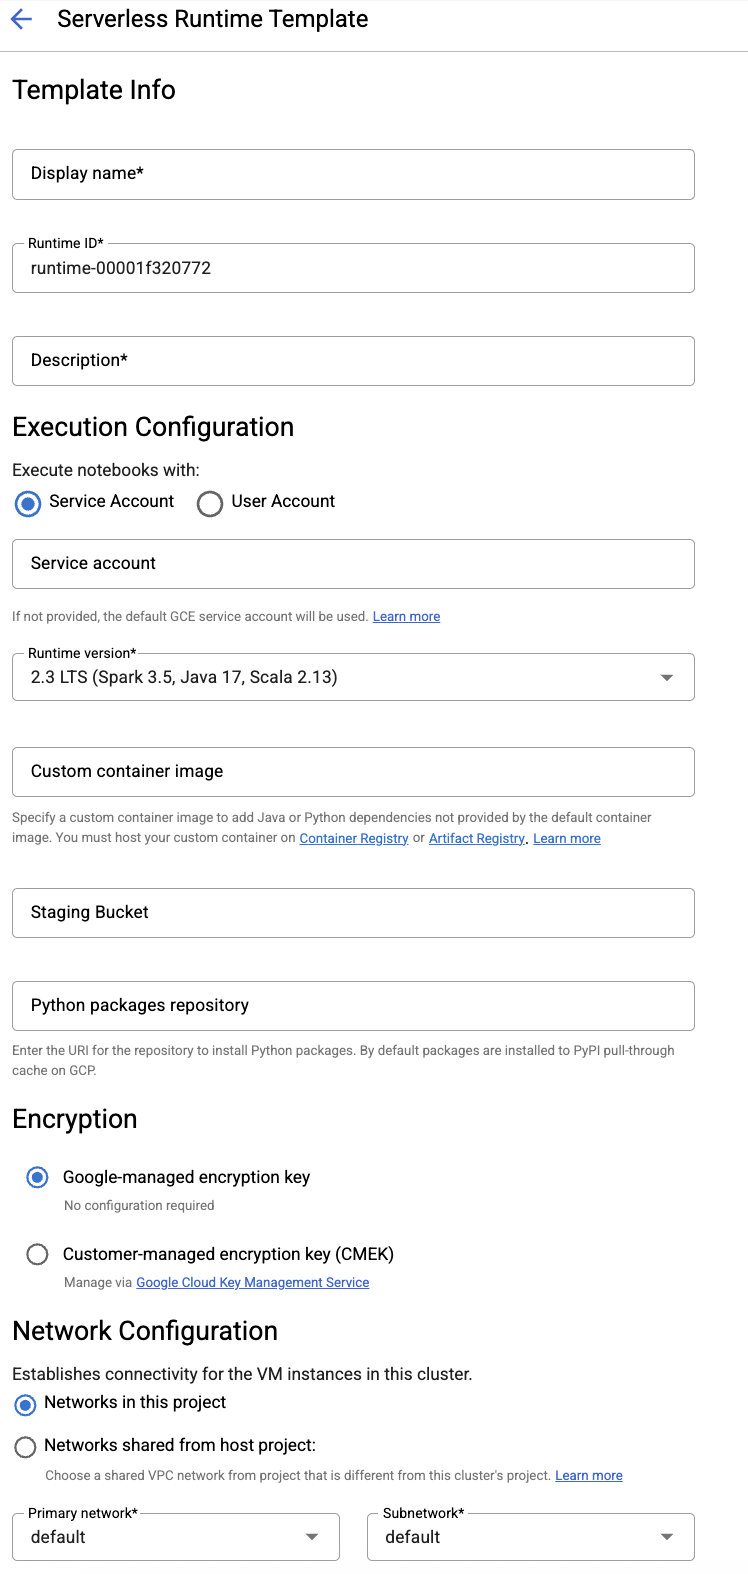
- **Template Info**:
- **Display name** , **Runtime ID** , and **Description**: Accept or fill a template display name, template runtime ID, and template description.
- **Execution Configuration** : Select **User Account** to execute notebooks
with the user identity instead of the Dataproc service account identity.
- **Service Account** : If you do not specify a service account, the [Compute Engine default service account is used](https://docs.cloud.google.com/managed-spark/docs/concepts/service-account).
- **Runtime version** : Confirm or select the `2.3` [runtime version](https://docs.cloud.google.com/managed-spark/docs/concepts/versions/serverless-versions.md.txt#supported-dataproc-serverless-for-spark-runtime-versions).
- **Custom container image** : Optionally specify the URI of a [custom container image](https://docs.cloud.google.com/managed-spark/docs/guides/custom-containers.md.txt).
- **Staging Bucket** : You can optionally specify the name of a Cloud Storage [staging bucket](https://docs.cloud.google.com/managed-spark/docs/concepts/buckets) for use by Managed Service for Apache Spark.
- **Python packages repository** : By default, Python packages are downloaded and installed from the PyPI pull-through cache when users execute `pip` install commands in their notebooks. You can specify your organization's private artifacts repository for Python packages to use as the default Python packages repository.
- **Encryption** : Accept the default **Google-owned and Google-managed encryption key** or select
[**Customer-managed encryption key** (CMEK)](https://docs.cloud.google.com/managed-spark/docs/guides/cmek-serverless.md.txt).
If CMEK, select or provide the key information.
- **Network Configuration** : Select a **subnetwork**
in the project or shared from a host project (you can change the project
from JupyterLab **Settings \> Google Cloud Settings \> Google Cloud Project Settings** .
You can specify [network tags](https://docs.cloud.google.com/vpc/docs/add-remove-network-tags.md.txt)
to apply to the specified network. Note that Managed Service for Apache Spark
enables [Private Google Access (PGA)](https://docs.cloud.google.com/vpc/docs/private-google-access.md.txt) on the
specified subnet. For network connectivity requirements, see
[Managed Service for Apache Spark network configuration](https://docs.cloud.google.com/managed-spark/docs/concepts/network#open_subnet_connectivity).
- **Session Configuration**: You can optionally fill in these fields to
limit the duration of sessions created with the template.
- **Max idle time:** The maximum idle time before the session is terminated. Allowable range: 10 minutes to 336 hours (14 days).
- **Max session time:** The maximum lifetime of a session before the session is terminated. Allowable range: 10 minutes to 336 hours (14 days).
- **Metastore** : To use a
[Dataproc Metastore service](https://docs.cloud.google.com/dataproc-metastore/docs/create-service-cluster.md.txt)
with your sessions, select the metastore project ID and service.
- **Persistent History Server** : You can select an available
[Persistent Spark History Server](https://docs.cloud.google.com/managed-spark/docs/concepts/jobs/history-server.md.txt)
to allow you to access session logs during and after sessions.
The PHS must be set up in location (region) where your sessions run. By default, Managed Service for Apache Spark sessions run in the project and region set with the [gcloud init](https://docs.cloud.google.com/sdk/gcloud/reference/init) command. You can change the project and region settings from JupyterLab **Settings \> Google Cloud Settings \> Google Cloud Project Settings**.
- **Spark properties:** You can select then add Spark **Resource Allocation** ,
**Autoscaling** , or **GPU** properties. Click **Add Property** to add
other Spark properties. For more information, see
[Spark properties](https://docs.cloud.google.com/managed-spark/docs/concepts/properties).
- **Labels:** Click **Add Label** for each
[label](https://docs.cloud.google.com/compute/docs/labeling-resources.md.txt) to set on sessions created with
the template.
3. Click **Save** to create the template.
4. To view or delete a runtime template.
1. Click **Settings \> Google Cloud Settings**.
2. The **Dataproc Settings \> Serverless Runtime Templates**
section displays the list of runtime templates.
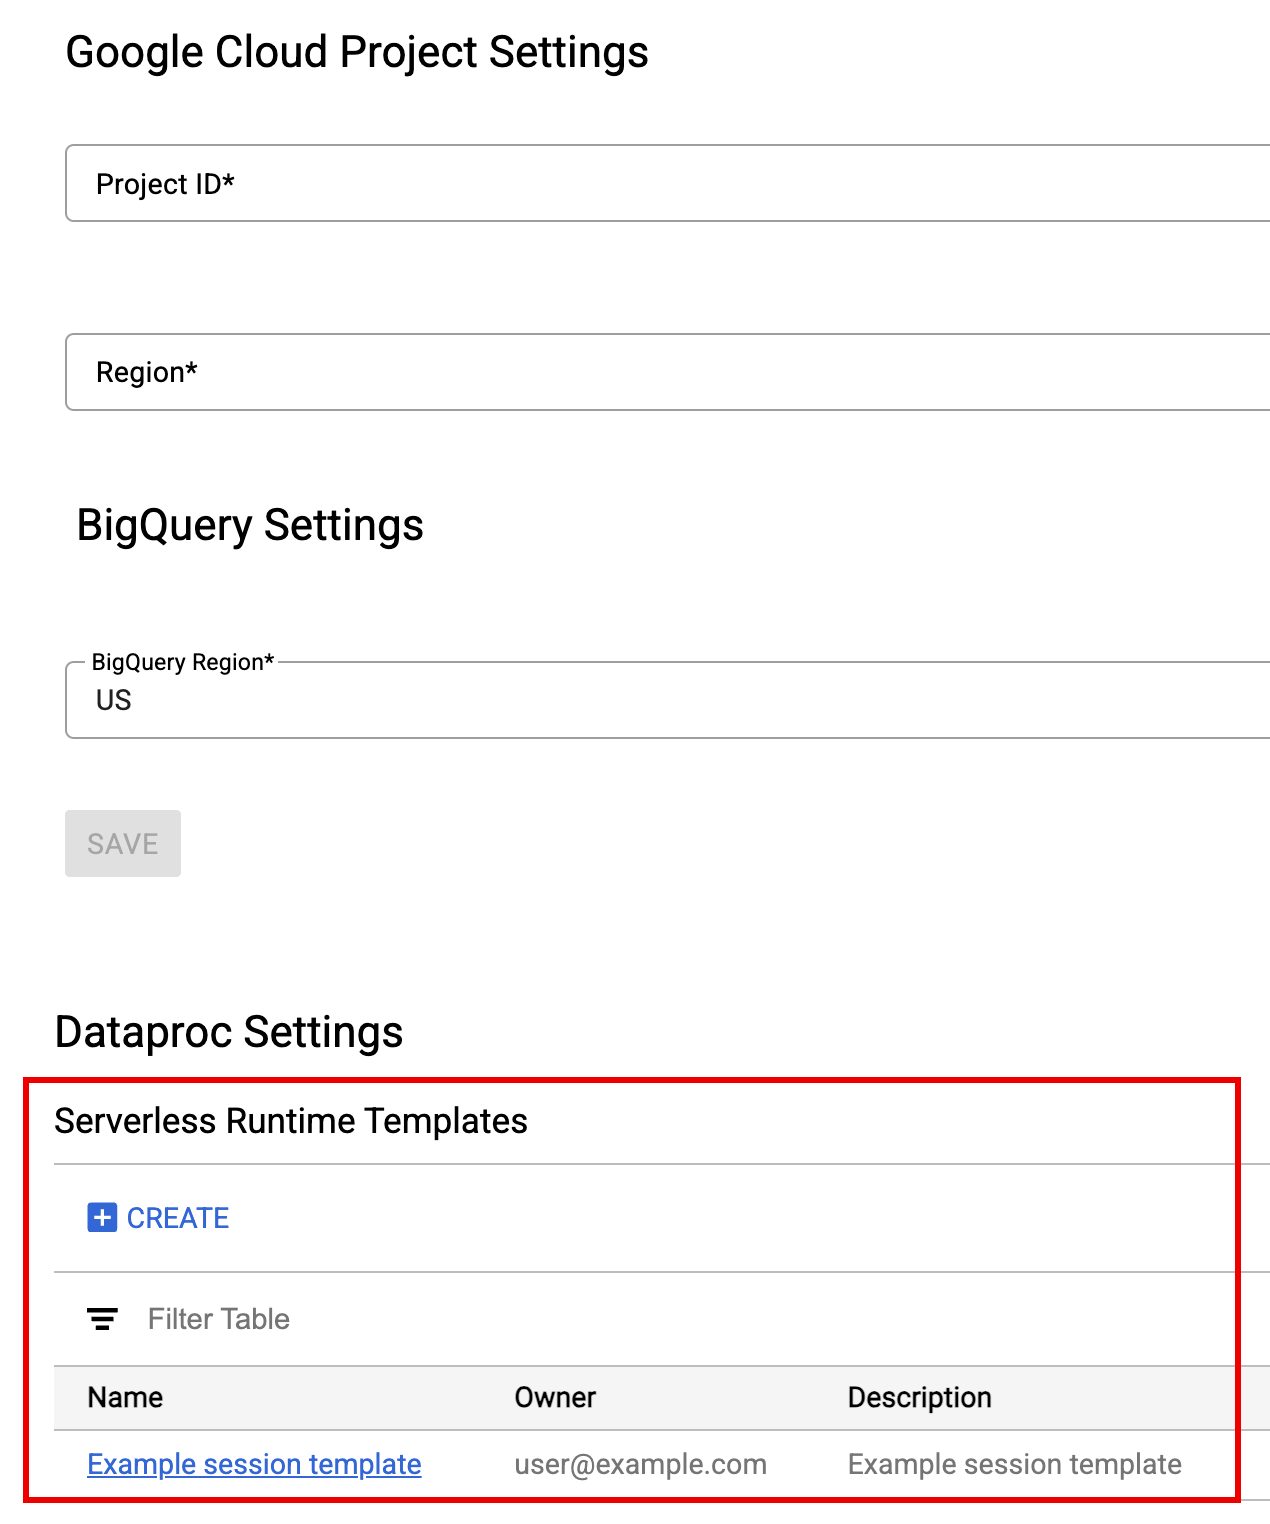
- Click a template name to view template details.
- You can delete a template from the **Action** menu for the template.
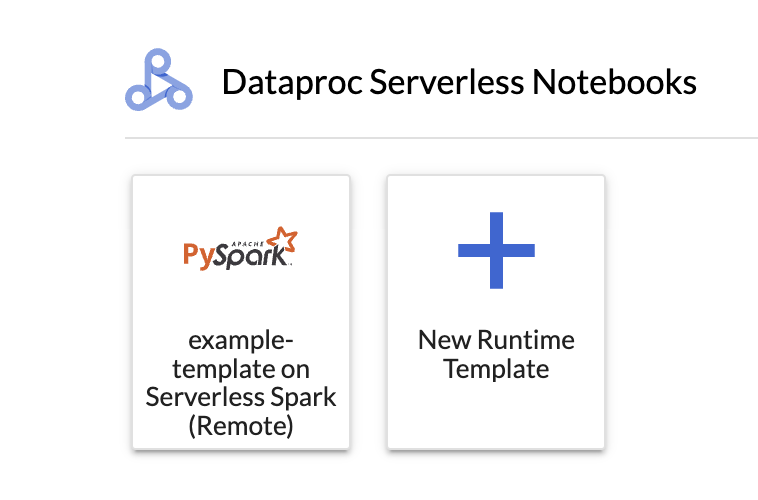
5. Open and reload the JupyterLab **Launcher** page to view the saved notebook template
card on the JupyterLab **Launcher** page.
### gcloud
1. Create a YAML file with your runtime template configuration.
### Simple YAML
```
environmentConfig:
executionConfig:
networkUri: default
jupyterSession:
kernel: PYTHON
displayName: Team A
labels:
purpose: testing
description: Team A Development Environment
```
### Complex YAML
```
description: Example session template
environmentConfig:
executionConfig:
serviceAccount: sa1
# Choose either networkUri or subnetworkUri
networkUri:
subnetworkUri: default
networkTags:
- tag1
kmsKey: key1
idleTtl: 3600s
ttl: 14400s
stagingBucket: staging-bucket
peripheralsConfig:
metastoreService: projects/my-project-id/locations/us-central1/services/my-metastore-id
sparkHistoryServerConfig:
dataprocCluster: projects/my-project-id/regions/us-central1/clusters/my-cluster-id
jupyterSession:
kernel: PYTHON
displayName: Team A
labels:
purpose: testing
runtimeConfig:
version: "2.3"
containerImage: gcr.io/my-project-id/my-image:1.0.1
properties:
"p1": "v1"
description: Team A Development Environment
```
2. Create a session template (runtime profile) from your YAML file by running the following
[gcloud beta dataproc session-templates import](https://docs.cloud.google.com/sdk/gcloud/reference/beta/dataproc/session-templates/import)
command locally or in [Cloud Shell](https://console.cloud.google.com/?cloudshell=true):
```
gcloud beta dataproc session-templates import TEMPLATE_ID \
--source=YAML_FILE \
--project=PROJECT_ID \
--location=REGION
```
- See [gcloud beta dataproc session-templates](https://docs.cloud.google.com/sdk/gcloud/reference/beta/dataproc/session-templates) for commands to describe, list, export, and delete session templates (runtime profiles).
## Launch and manage notebooks
After [installing the Managed Service for Apache Spark JupyterLab extension](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#install-jupyterlab-extension),
you can click template cards on the JupyterLab **Launcher** page to:
- [Launch a Jupyter notebook](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_jupyter_notebook_on_dataproc-serverless).
- [Launch a Jupyter notebook on a cluster](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_notebook_on_a_on_cluster).
### Launch a Jupyter notebook
The **Dataproc Serverless Notebooks** section
on the JupyterLab Launcher page displays notebook template
cards that map to Managed Service for Apache Spark runtime templates (see
[Create a Managed Service for Apache Spark runtime template](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#create-runtime-template)).
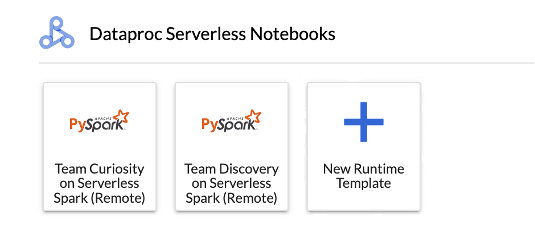
1. Click a card to create a Managed Service for Apache Spark session and
launch a notebook. When session creation is complete and the notebook
kernel is ready to use, the kernel status changes
from `Starting` to `Idle (Ready)`.
2. Write and test notebook code.
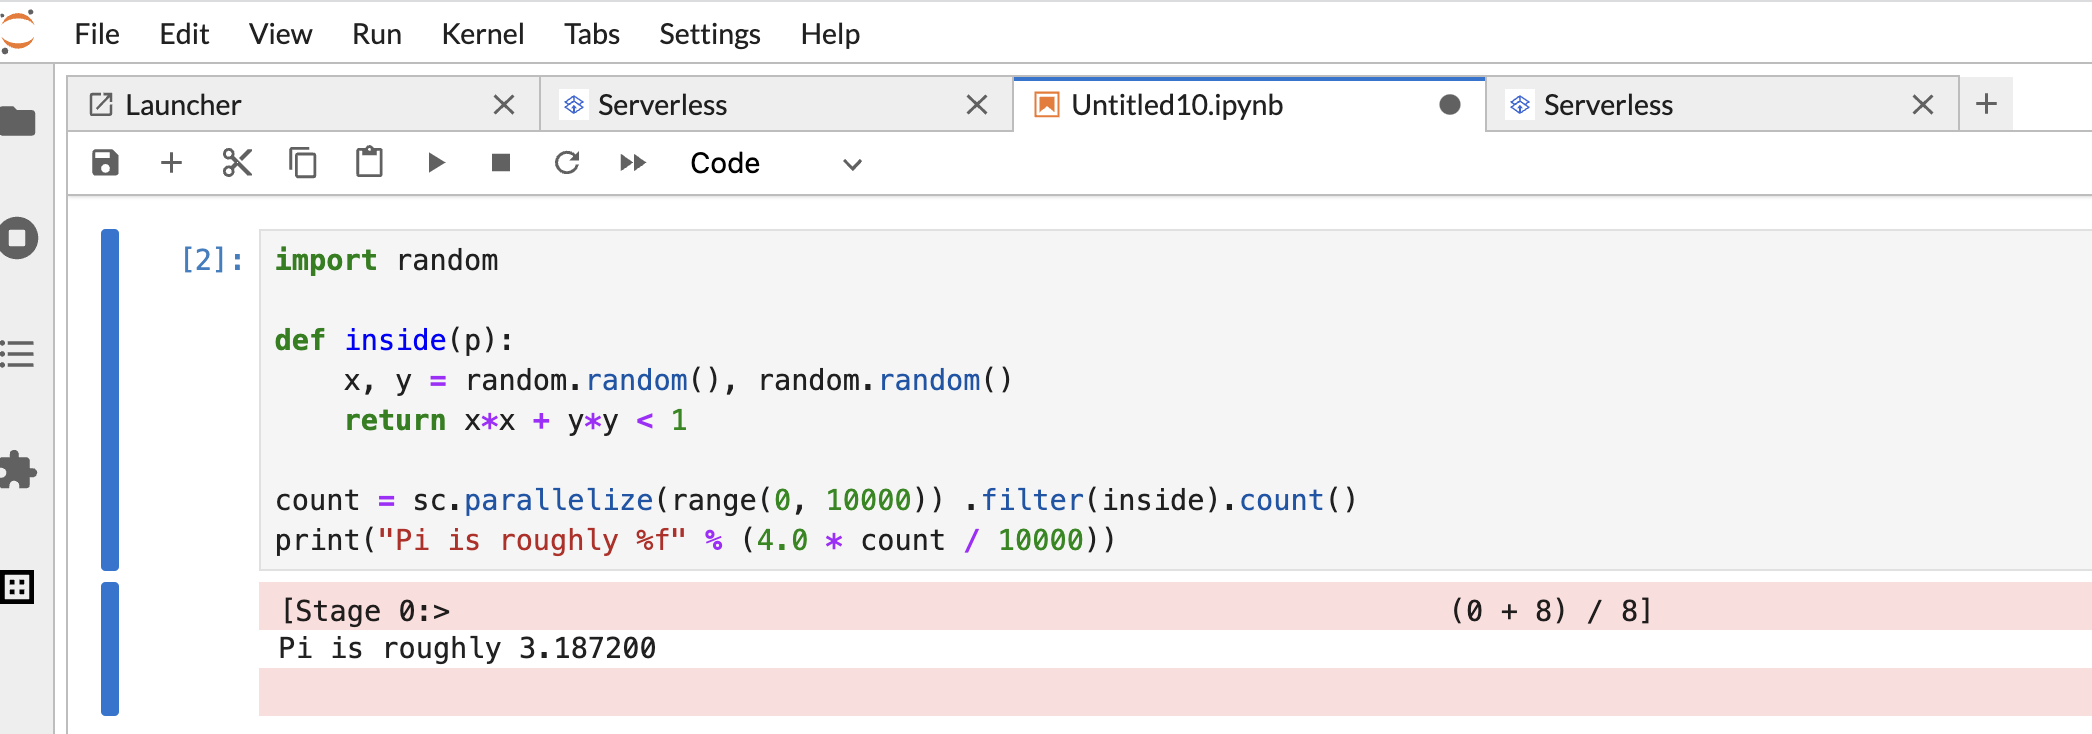
1. Copy and paste the following PySpark `Pi estimation` code
in the PySpark notebook cell, then press Shift+Return to
run the code.
```
import random
def inside(p):
x, y = random.random(), random.random()
return x*x + y*y < 1
count = sc.parallelize(range(0, 10000)) .filter(inside).count()
print("Pi is roughly %f" % (4.0 * count / 10000))
```
Notebook result:
3. After creating and using a notebook, you can terminate the notebook session
by clicking **Shut Down Kernel** from the **Kernel** tab.
- To reuse the session, create a new notebook by choosing **Notebook** from the **File\>\>New** menu. After the new notebook is created, choose the existing session from the kernel selection dialog. The new notebook will reuse the session and retain the session context from the previous notebook.
4. If you don't terminate the session, Managed Service for Apache Spark terminates the session
when the session idle timer expires. You can configure the session
idle time in the
[runtime template configuration](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#create-runtime-template).
The default session idle time is one hour.
### Launch a notebook on a cluster
If you created a [Managed Service for Apache Spark Jupyter cluster](https://docs.cloud.google.com/managed-spark/docs/concepts/components/jupyter.md.txt#install_jupyter),
the JupyterLab **Launcher** page contains a
**Dataproc Cluster Notebook** section with pre-installed kernel cards.
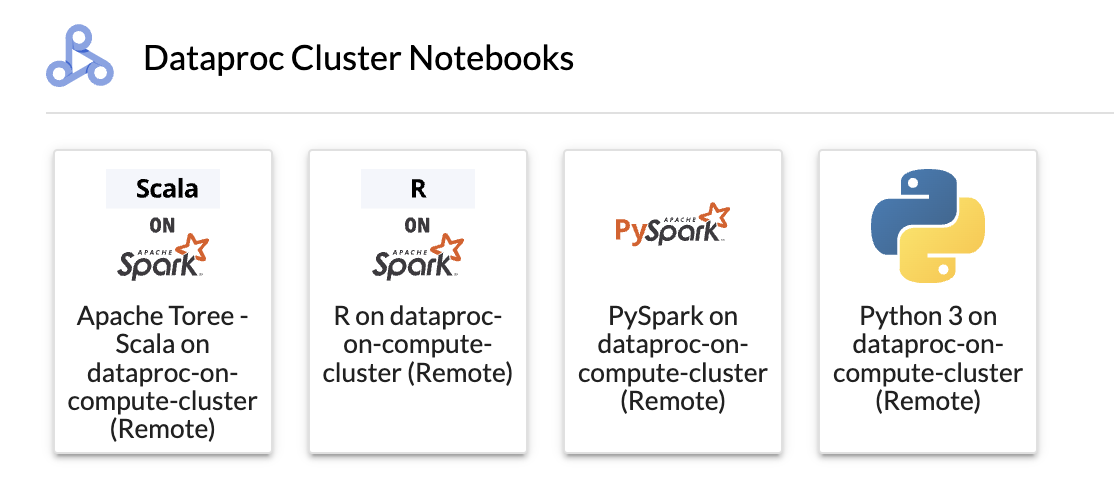
To launch a Jupyter notebook on your Managed Service for Apache Spark on
Compute Engine cluster:
1. Click a card in the **Dataproc Cluster Notebook** section.
2. When the kernel status changes from `Starting` to `Idle (Ready)`, you can
start writing and executing notebook code.
3. After creating and using a notebook, you can terminate the notebook session
by clicking **Shut Down Kernel** from the **Kernel** tab.
### Manage input and output files in Cloud Storage
Analyzing exploratory data and building ML models often involves
file-based inputs and outputs. Managed Service for Apache Spark accesses these files
on Cloud Storage.
- To access the Cloud Storage browser, click the Cloud Storage browser
icon in the JupyterLab **Launcher** page sidebar, then double-click a
folder to view its contents.
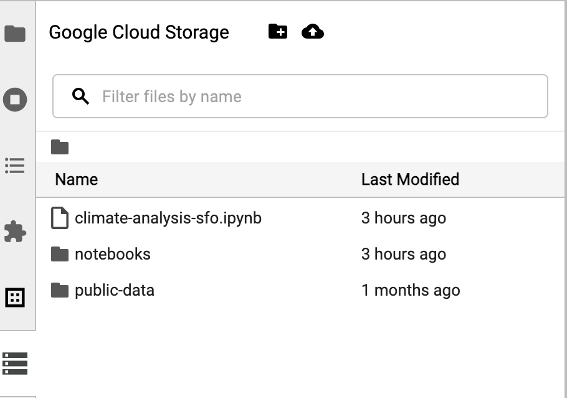
- You can click Jupyter-supported file types to open and edit them. When you
save changes to the files, they are written to Cloud Storage.
- To create a new Cloud Storage folder, click the new folder icon,
then enter the name of the folder.
- To upload files into a Cloud Storage bucket or a folder, click
the upload icon, then select the files to upload.
## Develop Spark notebook code
After [installing the JupyterLab extension](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-interactive-session#set_up_your_machine),
you can launch Jupyter notebooks from the JupyterLab **Launcher** page to develop
application code.
### PySpark and Python code development
Managed Service for Apache Spark clusters support PySpark and Python kernels.
- Click a PySpark card in the
[**Dataproc Serverless Notebooks**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_jupyter_notebook_on_dataproc-serverless)
or [**Dataproc Cluster Notebook**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_notebook_on_a_on_cluster)
section on the JupyterLab **Launcher** page to open a PySpark notebook.
- Click a Python kernel card in the
[**Dataproc Cluster Notebook**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_notebook_on_a_on_cluster) section
on the JupyterLab **Launcher** page to open a Python notebook.
### SQL code development
To open a PySpark notebook to write and execute SQL code, on the JupyterLab
**Launcher** page, in the [**Dataproc Serverless Notebooks**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_jupyter_notebook_on_dataproc-serverless) or [**Dataproc Cluster Notebook**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_notebook_on_a_on_cluster) section, click the PySpark kernel card.
**Spark SQL magic:** Since the PySpark kernel that launches
[**Dataproc Serverless Notebooks**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_jupyter_notebook_on_dataproc-serverless)
is preloaded with Spark SQL magic, instead of using `spark.sql('SQL STATEMENT').show()`
to wrap your SQL statement, you can type
`%%sparksql magic` at the top of a cell, then type your SQL statement in the cell.
**BigQuery SQL:** The BigQuery Spark connector allows your
notebook code to load data from BigQuery tables, perform analysis
in Spark, and then write the results to a BigQuery table.
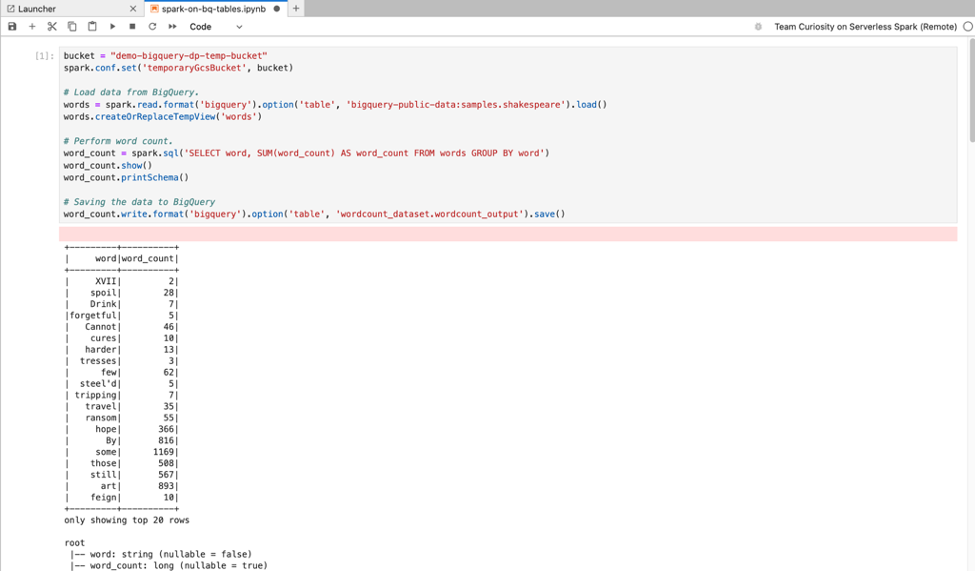
The [Managed Service for Apache Spark `2.2`](https://docs.cloud.google.com/managed-spark/docs/concepts/versions/spark-runtime-versions#spark_runtime_version_21)
and later runtimes include the
[BigQuery Spark connector](https://docs.cloud.google.com/managed-spark/docs/guides/bigquery-connector-spark-example).
If you use earlier runtime to launch Managed Service for Apache Spark notebooks,
you can install Spark BigQuery Connector by adding the following Spark property
to your [Managed Service for Apache Spark runtime template](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-interactive-session#create-runtime-template):
```
spark.jars: gs://spark-lib/bigquery/spark-bigquery-with-dependencies_2.12-0.25.2.jar
```
> [!NOTE]
> **Note:** [Install the BigQuery Spark connector on your Managed Service for Apache Spark cluster](https://github.com/GoogleCloudDataproc/initialization-actions/tree/master/connectors), to use it with [**Dataproc Cluster Notebooks**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_notebook_on_a_on_cluster).
### Scala code development
Managed Service for Apache Spark clusters created with image
versions `2.0` and later include [Apache Toree](https://toree.apache.org/),
a Scala kernel for the Jupyter Notebook platform that provides interactive access
to Spark.
- Click the Apache Toree card in the
[**Dataproc cluster Notebook**](https://docs.cloud.google.com/managed-spark/docs/guides/jupyterlab-sessions-serverless.md.txt#launch_a_notebook_on_a_on_cluster)
section on the JupyterLab **Launcher** page to open a notebook for Scala
code development.
 **Figure 1.** Apache Toree kernel card in the JupyterLab Launcher page.
### Develop code with the Visual Studio Code extension
You can use the Google Cloud [Visual Studio Code (VS Code)](https://code.visualstudio.com/)
extension lets you do the following:
- Develop and run Spark code in Managed Service for Apache Spark notebooks.
- Create and manage Managed Service for Apache Spark runtime profiles (session
templates), interactive sessions, and batch workloads.
The Visual Studio Code extension is free, but you are charged for any
Google Cloud services, including Managed Service for Apache Spark,
Managed Service for Apache Spark and Cloud Storage resources that you use.
**Use VS Code with BigQuery** : You can also
[use VS Code with BigQuery](https://docs.cloud.google.com/bigquery/docs/vs-code-extension) to
do the following:
- Develop and execute BigQuery notebooks.
- Browse, inspect, and preview BigQuery datasets.
#### Before you begin
1. [Download and install VS Code](https://code.visualstudio.com/download).
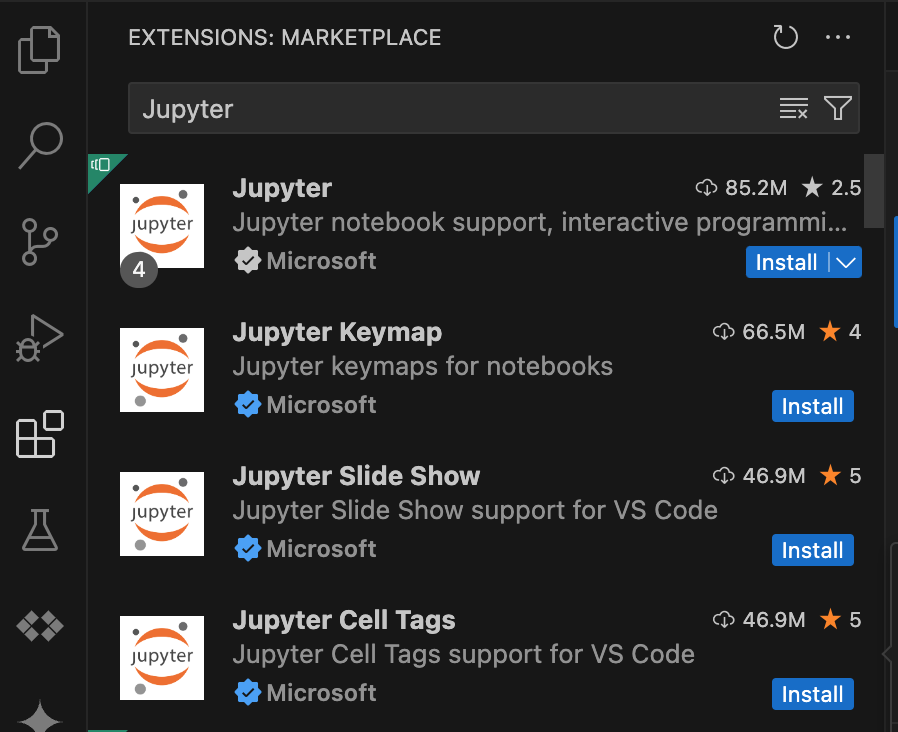
2. Open VS Code, and then in the activity bar, click **Extensions**.
3. Using the search bar, find the **Jupyter** extension, and then click
**Install**. The Jupyter extension by Microsoft is a required dependency.
### Install the Google Cloud extension
1. Open VS Code, and then in the activity bar, click **Extensions**.
2. Using the search bar, find the **Google Cloud Code** extension, and then
click **Install**.
3. If prompted, restart VS Code.
The **Google Cloud Code** icon is now visible in the
VS Code [activity bar](https://code.visualstudio.com/api/ux-guidelines/activity-bar#:%7E:text=The%20Activity%20Bar%20is%20a,Panel%20to%20customize%20their%20layout).
#### Configure the extension
1. Open VS Code, and then in the activity bar, click **Google Cloud Code**.
2. Open the **Dataproc** section.
3. Click **Login to Google Cloud**. You are redirected to sign in with your credentials.
4. Use the top-level application taskbar to navigate to **Code \> Settings \> Settings \> Extensions**.
5. Find **Google Cloud Code** , and click the **Manage** icon to open the menu.
6. Select **Settings**.
7. In the **Project** and **Managed Service for Apache Spark Region** fields, enter the name of the Google Cloud project and the region to use to develop notebooks and manage Managed Service for Apache Spark resources.
#### Develop notebooks
1. Open VS Code, and then in the activity bar, click **Google Cloud Code**.
2. Open the **Notebooks** section, then click **New Serverless Spark Notebook**.
3. Select or create a new runtime profile (session template) to use for the notebook session.
4. A new `.ipynb` file containing sample code is created and opened in the editor.
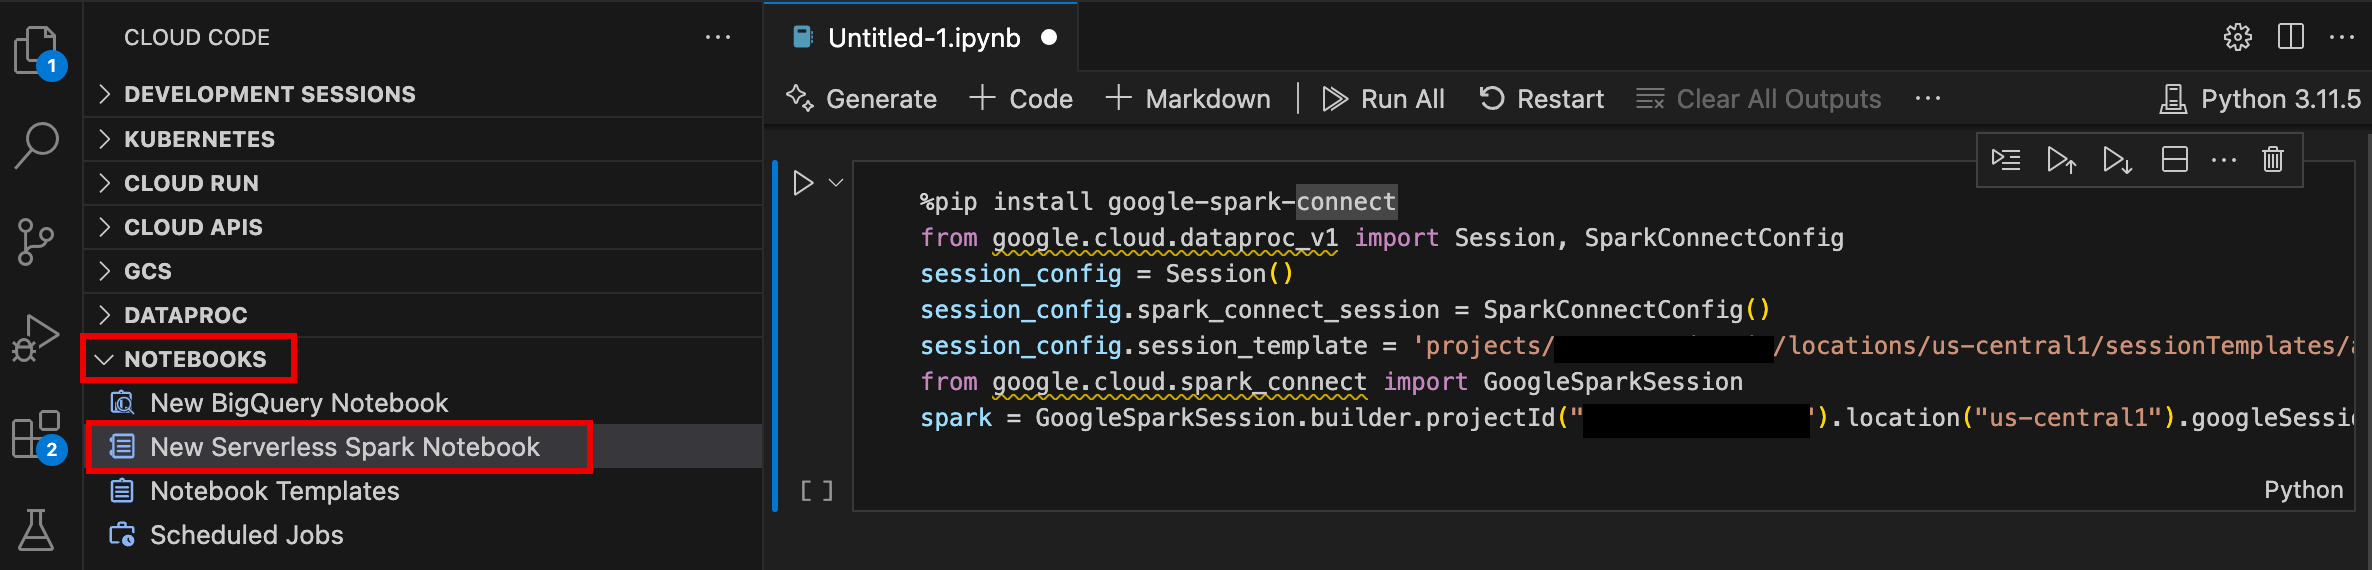
You can now write and execute code in your Managed Service for Apache Spark notebook.
#### Create and manage resources
1. Open VS Code, and then in the activity bar, click **Google Cloud Code**.
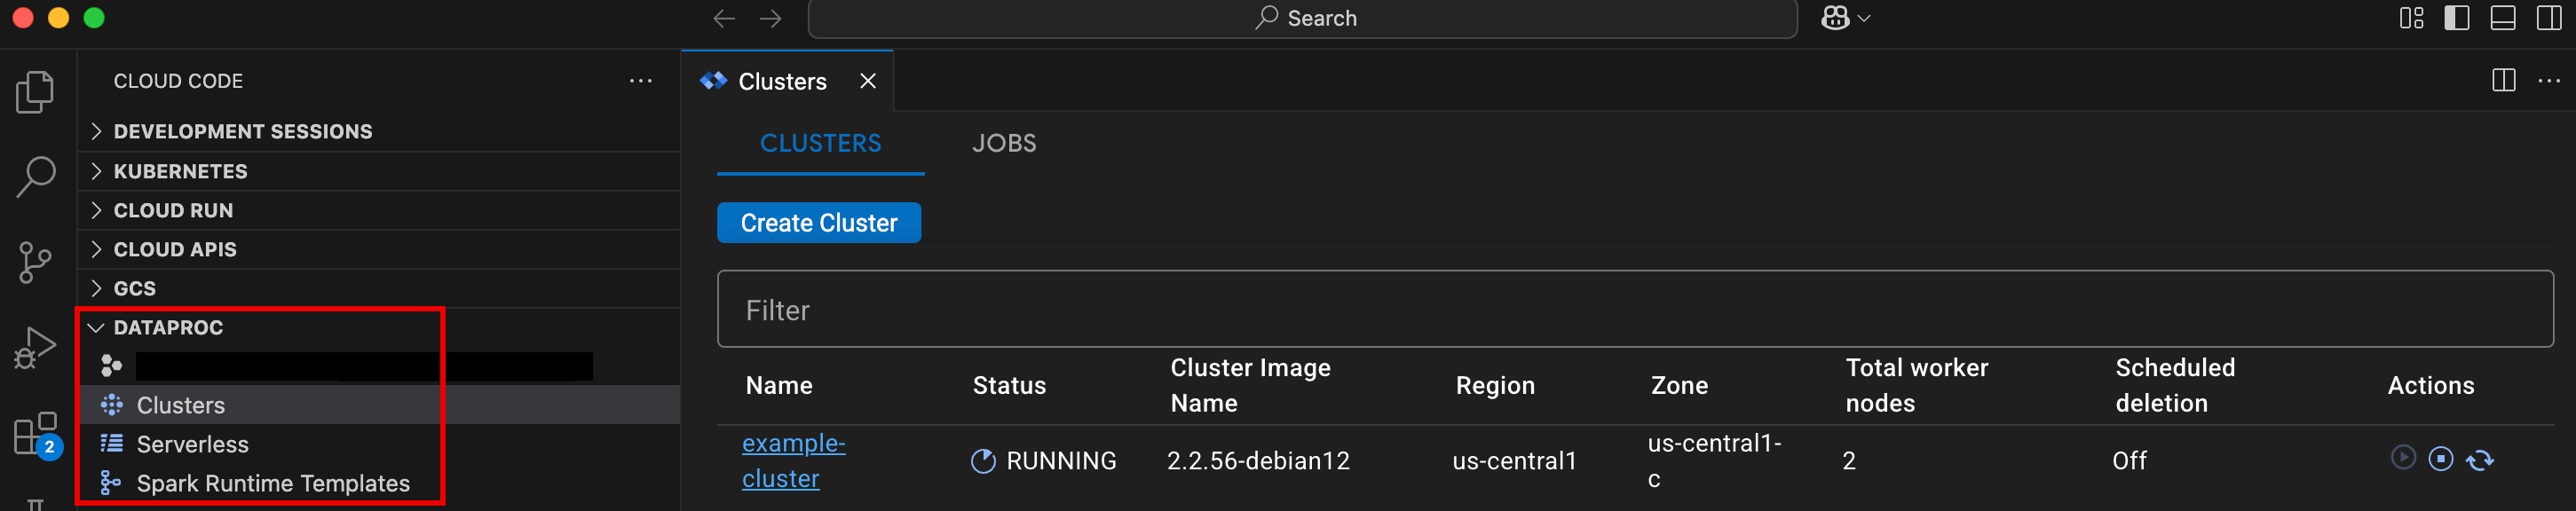
2. Open the **Dataproc** section, then click the following
resource names:
- **Clusters**: Create and manage clusters and jobs.
- **Serverless**: Create and manage batch workloads and interactive sessions.
- **Spark Runtime Templates**: Create and manage runtime profiles (session templates).
### Dataset explorer
Use the JupyterLab Dataset explorer to view
[BigLake metastore](https://docs.cloud.google.com/bigquery/docs/about-blms) datasets.
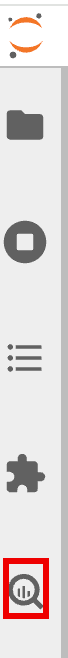
To open the JupyterLab Dataset Explorer, click its icon in the sidebar.
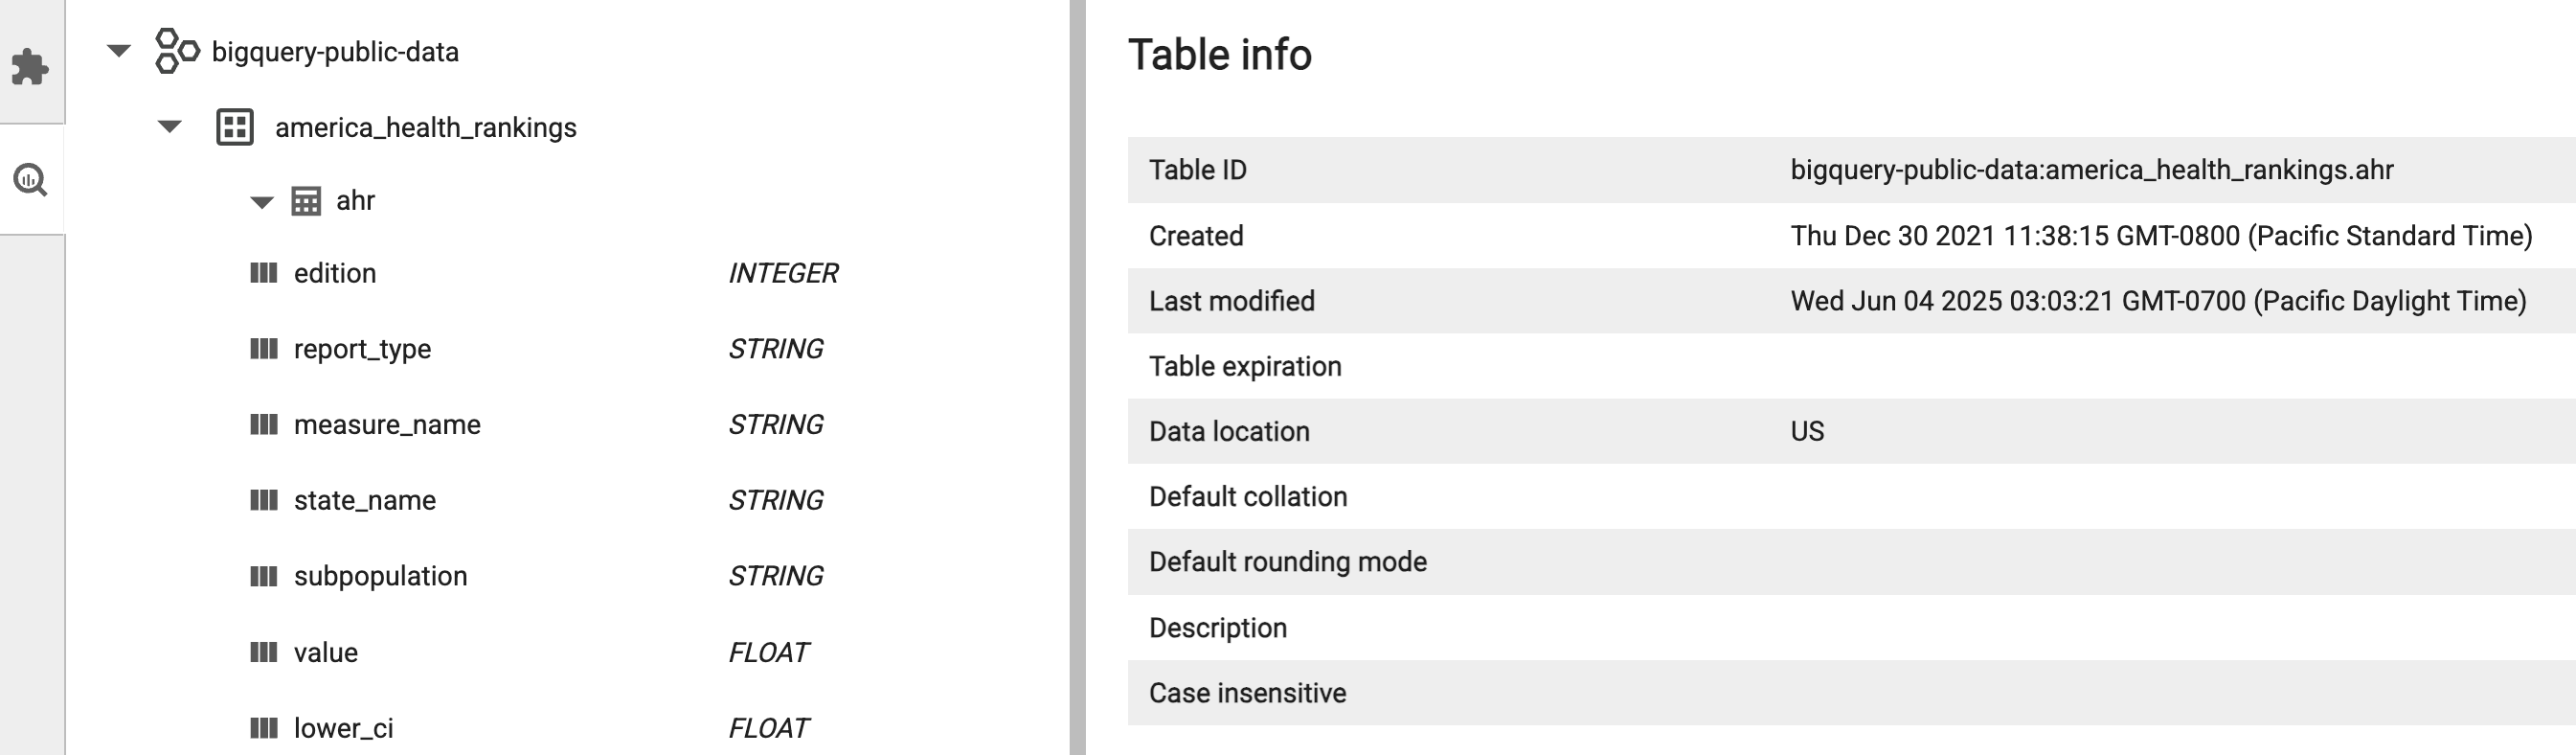
You can search for a database, table, or column in the Dataset explorer.
Click a database, table, or column name to view the associated metadata.
## Deploy your code
After [installing the JupyterLab extension](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-interactive-session#set_up_your_machine),
you can use JupyterLab to:
- Execute your notebook code on the Managed Service for Apache Spark infrastructure
- Schedule notebook execution on Managed Service for Apache Airflow
- Submit batch jobs to the Managed Service for Apache Spark infrastructure or to your
Managed Service for Apache Spark cluster.
### Schedule notebook execution on Managed Airflow
Complete the following steps to schedule your notebook code on Managed Airflow
to run as a batch job on Managed Service for Apache Spark or on a
Managed Service for Apache Spark cluster.
1. [Create a Managed Airflow environment](https://docs.cloud.google.com/composer/docs/composer-3/create-environments.md.txt).
2. Click the **Job Scheduler** button on top right of the notebook.
3. Fill in the **Create A Scheduled Job** form to provide the following information:
- A unique name for the notebook execution job
- The Managed Airflow environment to use to deploy the notebook
- Input parameters if the notebook is parameterized
- The Managed Service for Apache Spark cluster or serverless runtime template to use run the notebook
- If a cluster is selected, whether to stop the cluster after the notebook finishes executing on the cluster
- Retry count and retry delay in minutes if notebook execution fails on the first try
- Execution notifications to send and the recipient list. Notifications are sent using an Airflow SMTP configuration.
- The notebook execution schedule
4. Click **Create**.
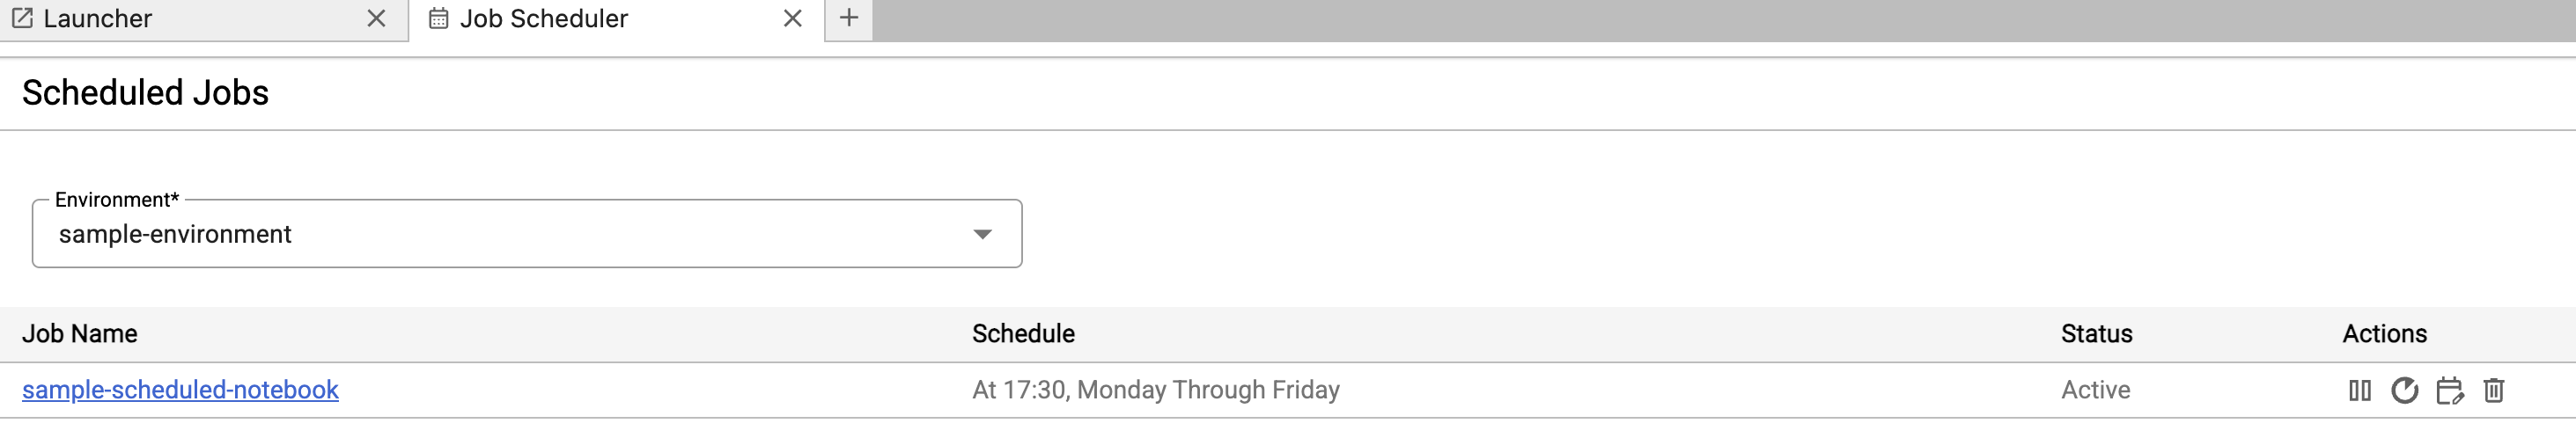
5. After the notebook is successfully scheduled, the job name appears
in the list of scheduled jobs in the Managed Airflow
environment.
### Submit a batch job to Managed Service for Apache Spark
- Click the **Serverless** card in the **Dataproc Jobs and Sessions** section
on the JupyterLab **Launcher** page.
- Click the **Batch** tab, then click **Create Batch** and fill in the
**Batch Info** fields.
- Click **Submit** to submit the job.
### Submit a batch job to a Managed Service for Apache Spark cluster
- Click the **Clusters** card in the **Dataproc Jobs and Sessions** section
on the JupyterLab **Launcher** page.
- Click the **Jobs** tab, then click **Submit Job**.
- Select a **Cluster** , then fill in the **Job** fields.
- Click **Submit** to submit the job.
## View and manage resources
After [installing the JupyterLab extension](https://docs.cloud.google.com/managed-spark/docs/quickstarts/spark-interactive-session#set_up_your_machine),
you can view and manage Managed Service for Apache Spark and Managed Service for Apache Spark
from the **Dataproc Jobs and Sessions** section on the JupyterLab **Launcher** page.
Click the **Dataproc Jobs and Sessions** section to show the **Clusters** and
**Serverless** cards.
To view and manage Managed Service for Apache Spark sessions:
1. Click the **Serverless** card.
2. Click the **Sessions** tab, then a session ID to open the **Session details** page to view session properties, view Google Cloud logs in Logs Explorer, and terminate a session. Note: A unique Managed Service for Apache Spark session is created to launch each Managed Service for Apache Spark notebook.
To view and manage Managed Service for Apache Spark batches:
1. Click the **Batches** tab to view the list of Managed Service for Apache Spark batches in the current project and region. Click a batch ID to view batch details.
To view and manage Managed Service for Apache Spark clusters:
1. Click the **Clusters** card. The **Clusters** tab is selected to list active Managed Service for Apache Spark clusters in the current project and region. You can click the icons in the **Actions** column to start, stop, or restart a cluster. Click a cluster name to view cluster details. You can click the icons in the **Actions** column to clone, stop, or delete a job.
To view and manage Managed Service for Apache Spark jobs:
1. Click the **Jobs** card to view the list of jobs in the current project. Click a job ID to view job details.