This document describes how to enable
[data lineage](https://docs.cloud.google.com/dataplex/docs/about-data-lineage) on
Managed Service for Apache Spark batch workloads and interactive sessions at the
[project](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-at-the-project-level),
[batch workload](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-on-a-spark-batch-workload), or
[interactive session or runtime profile (session template)](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-on-a-spark-interactive-session-or-session-template) level.
## Overview
Data lineage is a [Knowledge Catalog](https://docs.cloud.google.com/dataplex/docs/introduction)
feature that lets you track how data moves through your systems: where it comes
from, where it is passed to, and what transformations are applied to it.
Managed Service for Apache Spark workloads and sessions capture lineage events and publish them to
the Knowledge Catalog [Data Lineage API](https://docs.cloud.google.com/dataplex/docs/reference/data-lineage/rest).
Managed Service for Apache Spark integrates with the Data Lineage API through
[OpenLineage](https://docs.cloud.google.com/dataplex/docs/open-lineage), using the
[OpenLineage Spark plugin](https://github.com/OpenLineage/OpenLineage).
You can access lineage information through Knowledge Catalog, using
[lineage graphs](https://docs.cloud.google.com/dataplex/docs/about-data-lineage#lineage-feature-graph)
and the [Data Lineage API](https://docs.cloud.google.com/dataplex/docs/reference/data-lineage/rest).
For more information, see [View lineage graphs in Knowledge Catalog](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#view-lineage-graphs-in-dataplex).
## Availability
Data lineage, which supports BigQuery and Cloud Storage
data sources, is available for workloads and sessions that run with
[supported Managed Service for Apache Spark runtime versions](https://docs.cloud.google.com/managed-spark/docs/concepts/versions/serverless-versions.md.txt#supported-dataproc-serverless-for-spark-runtime-versions)
with the following exceptions and limitations:
- Data lineage is not available for SparkR or Spark streaming workloads or sessions.
## Before you begin
1. On the project selector page in the Google Cloud console, select the project
to use for your Managed Service for Apache Spark workloads or sessions.
[Go to project selector](https://console.cloud.google.com/projectselector2/home/dashboard)
2. Enable the Data Lineage API.
[Enable the APIs](https://console.cloud.google.com/apis/enableflow?apiid=datalineage.googleapis.com)
**Upcoming Spark data lineage changes** See the
[Managed Service for Apache Spark release notes](https://docs.cloud.google.com/managed-spark/docs/release-notes.md.txt)
for the announcement of a change that will automatically make
Spark data lineage available to your projects, batch workloads,
and interactive sessions when you enable the Data Lineage API (see
[Control lineage ingestion for a service](https://docs.cloud.google.com/dataplex/docs/use-lineage#control-ingestion))
without requiring additional project, batch workload,
or interactive session settings.
## Required roles
If your batch workload uses the
default [Managed Service for Apache Spark service account](https://docs.cloud.google.com/managed-spark/docs/concepts/service-accounts-serverless.md.txt),
it has the [`Dataproc Worker`](https://docs.cloud.google.com/iam/docs/roles-permissions/dataproc.md.txt#dataproc.worker)
role. This role includes the `datalineage.locations.processOpenLineageMessage` permission,
which the OpenLineage Spark plugin uses to capture and publish lineage events to the
Data Lineage API. No additional action is necessary.
If your batch workload or interactive session uses a custom service account,
the service account must have permission to publish lineage events.
To follow the principle of least privilege, grant the minimum role required
for your use case:
- **Dataproc Worker (`roles/dataproc.worker`)** : the standard role required for Managed Service for Apache Spark workload execution. Because this role already includes the `datalineage.locations.processOpenLineageMessage` permission, if your custom service account already has this role, you don't need to grant an additional Data Lineage role.
- **Data Lineage Events Producer (`roles/datalineage.producer`)**: the minimum standalone Data Lineage role required for a custom service account to publish lineage events. Grant this role if the service account doesn't have the Dataproc Worker role.
- **Data Lineage Editor (`roles/datalineage.editor`)**: grants permissions to edit and delete lineage processes and events, in addition to publishing them. This role provides more permissions than needed for standard pipeline execution, and is only required if workloads must modify existing lineage metadata.
- **Data Lineage Administrator (`roles/datalineage.admin`)**: grants full administrative access to Data Lineage resources. This role is not required for workload service accounts.
> [!NOTE]
> **Note:** To view data lineage in Knowledge Catalog or the Google Cloud console, users require the [Data Lineage Viewer (`roles/datalineage.viewer`)](https://docs.cloud.google.com/iam/docs/roles-permissions/datalineage.md.txt#datalineage.viewer) role. This role is intended for users who view lineage, not for the workload service account.
## Enable Spark data lineage
You can enable Spark data lineage for your project, batch workload, or interactive
session.
### Enable data lineage at the project level
After you enable Spark data lineage at the project level, subsequent
Spark jobs that run in a batch workload or interactive session will
have Spark data lineage enabled.
> [!NOTE]
> **Note:** Setting data lineage on a project doesn't enable data lineage for batch workloads and interactive sessions that use the [Managed Service for Apache Spark 3.0 runtime](https://docs.cloud.google.com/managed-spark/docs/concepts/versions/serverless-versions.md.txt#supported-dataproc-serverless-for-spark-runtime-versions). You must separately enable data lineage on the 3.0 [batch workload](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-on-a-spark-batch-workload), or [interactive session or runtime profile (session template)](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-on-a-spark-interactive-session-or-session-template).
To enable Spark data lineage on your project,
[set the following custom project metadata](https://docs.cloud.google.com/compute/docs/metadata/setting-custom-metadata.md.txt#set-custom-project-wide-metadata):
| Key | Value |
|---|---|
| `DATAPROC_LINEAGE_ENABLED` | `true` |
You can disable Spark data lineage for a project by setting the
`DATAPROC_LINEAGE_ENABLED` metadata to `false`.
> [!NOTE]
> **Note:** You can also disable Spark data lineage for a project by [disabling lineage ingestion for Managed Service for Apache Spark](https://docs.cloud.google.com/dataplex/docs/use-lineage#disable-lineage-ingestion). This setting overrides all other data lineage settings.
### Enable data lineage on a Spark batch workload
To enable data lineage on a batch workload,
set the `spark.dataproc.lineage.enabled` property to `true` when you
submit the workload. This setting overrides any Spark data lineage
setting at the [project level](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-at-the-project-level): if Spark
data lineage is disabled at the project level but enabled for the batch workload,
the batch workload setting takes precedence.
You can disable Spark data lineage on a Spark batch workload
by setting the `spark.dataproc.lineage.enabled` property to `false`
when you submit the workload.
> [!NOTE]
> **Note:** You can also disable Spark data lineage by [disabling lineage ingestion for Managed Service for Apache Spark](https://docs.cloud.google.com/dataplex/docs/use-lineage#disable-lineage-ingestion). This setting overrides all other data lineage settings.
This example uses the gcloud CLI to submit a batch
`lineage-example.py` workload with Spark lineage enabled.
```
gcloud dataproc batches submit pyspark lineage-example.py \
--region=REGION \
--deps-bucket=gs://BUCKET \
--properties=spark.dataproc.lineage.enabled=true
```
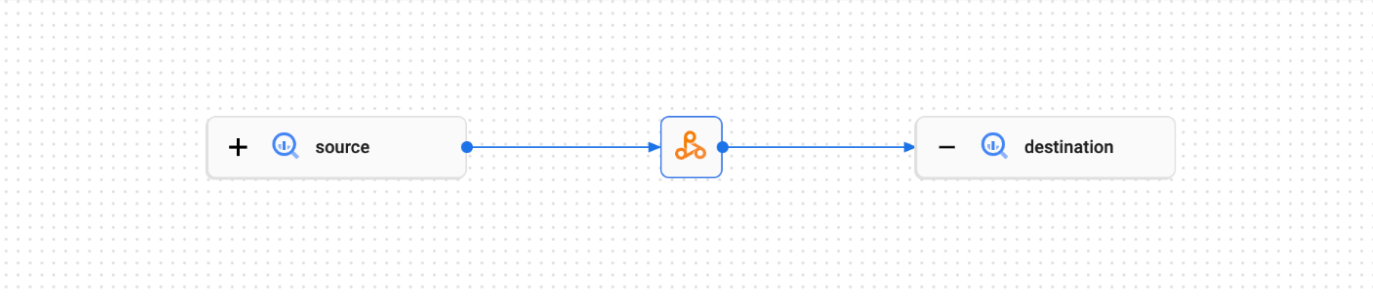
The following `lineage-example.py` code reads data from a public BigQuery
table, and then writes the output a new table in an existing BigQuery
dataset. It uses a Cloud Storage bucket for temporary storage.
```python
#!/usr/bin/env python
from pyspark.sql import SparkSession
import sys
spark = SparkSession \
.builder \
.appName('LINEAGE_BQ_TO_BQ') \
.getOrCreate()
source = 'bigquery-public-data:samples.shakespeare'
words = spark.read.format('bigquery') \
.option('table', source) \
.load()
words.createOrReplaceTempView('words')
word_count = spark.sql('SELECT word, SUM(word_count) AS word_count FROM words GROUP BY word')
destination_table = 'PROJECT_ID:DATASET.TABLE'
word_count.write.format('bigquery') \
.option('table', destination_table) \
.option('writeMethod', 'direct') \
.save()
```
Replace the following:
- REGION: The [region](https://docs.cloud.google.com/compute/docs/regions-zones.md.txt#available) to run the workload
- BUCKET: The name of an existing Cloud Storage bucket to store dependencies
- PROJECT_ID, DATASET, and TABLE: The project ID, the name of an existing BigQuery dataset, and the name of a new table to create in the dataset (the table must not exist)
You can view the lineage graph in the Knowledge Catalog UI.
### Enable data lineage on a Spark interactive session or runtime profile (session template)
To enable data lineage on a Spark interactive session or runtime profile
(session template), set the `spark.dataproc.lineage.enabled` property to `true`
when you
[create the session or runtime profile (session template)](https://docs.cloud.google.com/managed-spark/docs/guides/create-serverless-sessions-templates.md.txt).
For example, on the **Create a runtime profile** page in the Google Cloud console,
under **Additional configuration** , edit **Other customizations** and add the
`spark.dataproc.lineage.enabled` property with the value `true` under **Spark
properties** . This setting overrides any Spark data lineage setting at the
[project level](https://docs.cloud.google.com/managed-spark/docs/guides/data-lineage.md.txt#enable-data-lineage-at-the-project-level): if Spark data
lineage is disabled at the project level but enabled for the interactive
session, the interactive session setting takes precedence.
You can disable Spark data lineage on a Spark interactive session or runtime
profile (session template) by setting the `spark.dataproc.lineage.enabled`
property to `false` when you create the interactive session or runtime profile
(session template).
> [!NOTE]
> **Note:** You can also disable Spark data lineage by [disabling lineage ingestion for Managed Service for Apache Spark](https://docs.cloud.google.com/dataplex/docs/use-lineage#disable-lineage-ingestion). This setting overrides all other data lineage settings.
The following PySpark notebook code configures a Managed Service for Apache Spark
interactive session with Spark data lineage enabled. It then creates a
[Spark Connect](https://spark.apache.org/spark-connect/)
session that runs a word count query on a public BigQuery
Shakespeare dataset, and then writes the output to a new table in an
existing BigQuery dataset (see
[Use the Spark Connect client](https://docs.cloud.google.com/managed-spark/docs/guides/spark-connect-client.md.txt)).
```python
# Configure the Dataproc Serverless interactive session
# to enable Spark data lineage.
from google.cloud.dataproc_v1 import Session
session = Session()
session.runtime_config.properties["spark.dataproc.lineage.enabled"] = "true"
# Create the Spark Connect session.
from google.cloud.managed_spark_connect import ManagedSparkSession
spark = (
ManagedSparkSession.builder
.sessionId("lineage-example")
.sessionConfig(session)
.getOrCreate()
)
# Run a wordcount query on the public BigQuery Shakespeare dataset.
source = "bigquery-public-data:samples.shakespeare"
words = spark.read.format("bigquery").option("table", source).load()
words.createOrReplaceTempView('words')
word_count = spark.sql(
'SELECT word, SUM(word_count) AS word_count FROM words GROUP BY word')
# Output the results to a BigQuery destination table.
destination_table = 'PROJECT_ID:DATASET.TABLE'
word_count.write.format('bigquery') \
.option('table', destination_table) \
.save()
```
Replace the following:
- PROJECT_ID, DATASET, and TABLE: The project ID, the name of an existing BigQuery dataset, and the name of a new table to create in the dataset (the table must not exist)
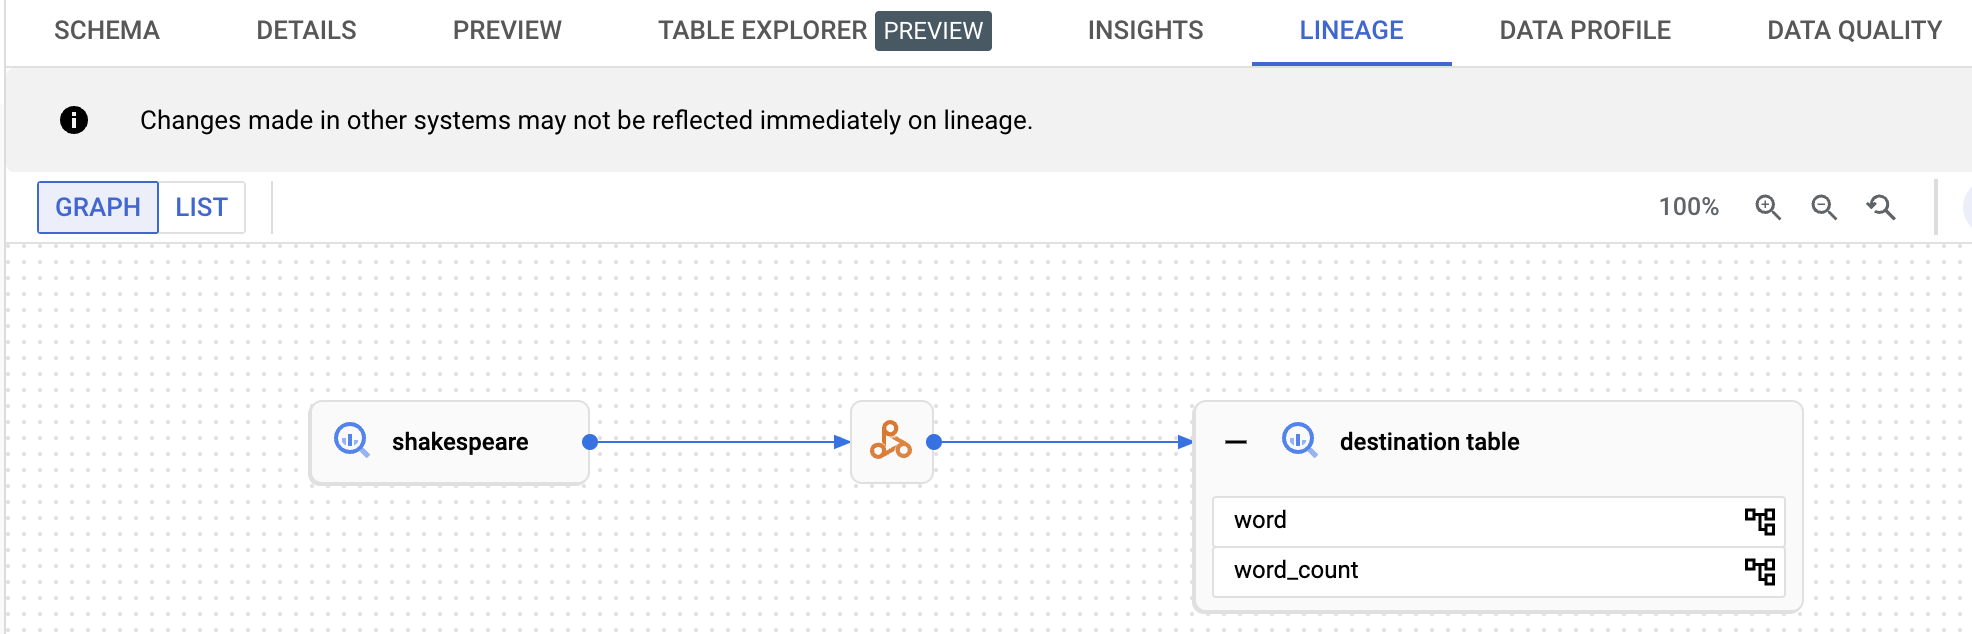
You can view the data lineage graph by clicking the destination table name listed
in the navigation pane on BigQuery **Explorer** page,
then selecting the lineage tab on the table details pane.
## View lineage in Knowledge Catalog
A lineage graph displays relationships between your project
resources and the processes that created them. You can
[view data lineage information](https://docs.cloud.google.com/dataplex/docs/use-lineage)
in the Google Cloud console or
retrieve the information from the
[Data Lineage API](https://docs.cloud.google.com/dataplex/docs/reference/data-lineage/rest)
as JSON data.
## What's next
- Learn more about [data lineage](https://docs.cloud.google.com/dataplex/docs/about-data-lineage).
- Try data lineage in an interactive lab: [Capture and Explore Data Updates With Data Lineage and OpenLineage in Dataplex](https://www.skills.google/focuses/133556?catalog_rank=%7B%22rank%22:1,%22num_filters%22:0,%22has_search%22:true%7D&parent=catalog&search_id=70803730).