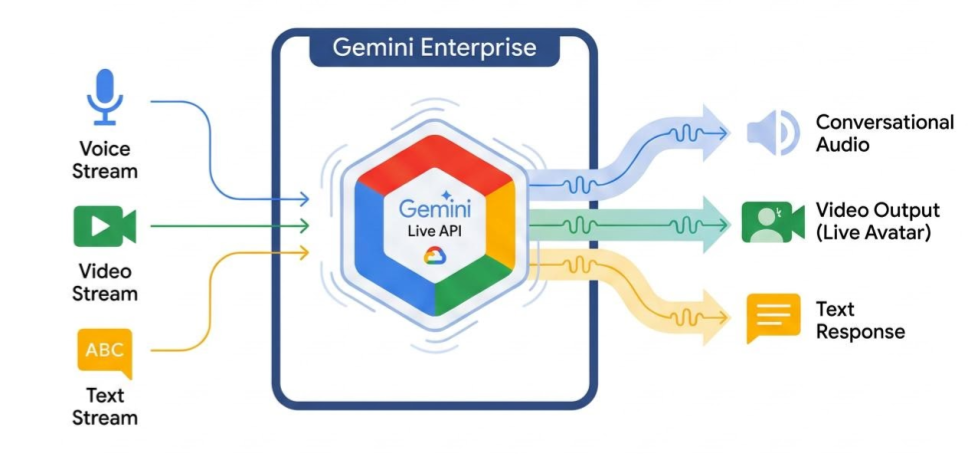
Gemini Live API enables low-latency, real-time voice and video interactions
with Gemini. It processes continuous streams of audio, video, or text
to deliver immediate, human-like spoken responses. This creates a natural
conversational experience for your users. Live avatars add the option to
interact with a human-like icon that synchronizes with the speech responses,
providing an improved and personable experience with users.
[Video](https://www.youtube.com/watch?v=oVG-5BF-dWo)
[Try Gemini Live API in Agent Studio](https://console.cloud.google.com/agent-platform/studio/multimodal-live)
## Example use cases
Gemini Live API can be used to build real-time voice and video agents for a
variety of industries, including:
- **Branded corporate ambassadors**: Interactive brand representatives
deployed on corporate web properties or mobile applications, generated from
authorized employee likenesses or paid talent with executed corporate
releases.
- **E-commerce and retail**: Shopping assistants that offer personalized
recommendations and support agents that resolve customer issues.
- **Gaming**: Interactive non-player characters (NPCs), in-game help
assistants, and real-time translation of in-game content.
- **Next-gen interfaces**: Voice- and video-enabled experiences in robotics,
smart glasses, and vehicles.
- **Healthcare**: Navigational guides that assist with facility and care
logistics.
- **Financial services**: Conversational agents that triage everyday banking
requests.
- **Education**: AI mentors and learner companions that provide personalized
instruction and feedback.
## Key features
Gemini Live API offers a comprehensive set of features for building
robust voice and video agents:
- **High audio quality**: Gemini Live API provides natural,
realistic-sounding speech across multiple languages.
- [**Prebuilt and custom
voices**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/configure-language-voice#voices-supported):
Configure responses with 30 prebuilt HD voices or replicate a custom voice
per session.
- [**Multilingual
support**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/configure-language-voice#languages-supported):
Converse in 24 supported languages.
- [**Barge-in**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/configure-language-voice.md.txt#voice-activity-detection):
Users can interrupt the model at any time for responsive interactions.
- [**Affective dialog**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/configure-gemini-capabilities.md.txt#use-affective-dialog):
Adapts response style and tone to match the user's input expression.
- [**Tool use**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/configure-gemini-capabilities.md.txt#configure-tool-use):
Integrates tools like function calling and Google Search for dynamic
interactions.
- [**Audio transcriptions**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/start-manage-session.md.txt#enable-audio-transcription):
Provides text transcripts of both user input and model output. For
transcription as the end goal rather than as a side channel of a
conversation, see
[Gemini 3.5 Transcribe](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-5-transcribe.md.txt).
- [**Proactive
audio**](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/configure-gemini-capabilities#use-proactive-audio):
Lets you control when the model responds and in what contexts.
## Technical specifications
The following table outlines the technical specifications for the
Gemini Live API:
| Category | Details |
|---|---|
| Input modalities | Audio (raw 16-bit PCM audio, 16kHz, little-endian), images/video (JPEG 1FPS), text |
| Output modalities | Audio (raw 16-bit PCM audio, 24kHz, little-endian), text |
| Video (live avatars) | Video (mp4) |
| Protocol | Stateful WebSocket connection (WSS) |
## Supported models
The following models support Gemini Live API. Select the appropriate model
based on your interaction requirements.
| Model ID | Availability | Use case | Key features |
|---|---|---|---|
| [`gemini-3.8-live`](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-8-live.md.txt) | Generally available | **Recommended**. Low-latency voice agents. Supports seamless multilingual switching. | - Native audio - Audio transcriptions - Voice activity detection - Affective dialog - Proactive audio - Tool use - Live avatar |
| [`gemini-live-2.5-flash-native-audio`](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/2-5-flash-live-api.md.txt) | Generally available | **Recommended**. Low-latency voice agents. Supports seamless multilingual switching and emotional tone. | - Native audio - Audio transcriptions - Voice activity detection - Affective dialog - Proactive audio - Tool use |
| [`gemini-3.5-transcribe-live-preview`](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-5-transcribe.md.txt) | Preview | Speech-to-text only. Real-time captioning, dictation, and call transcription. Returns text, not audio, so it does not hold a conversation. | - Interim and final transcripts - Automatic language detection with code-switching - Utterance-level timestamps - Custom vocabulary biasing |
## Get started
Select the guide that matches your development environment:
> [!TIP]
> **Tip:** If you use an AI coding assistant, you can install the Gemini Live API agent skill (`gemini-live-api`) from the [`google/skills` GitHub repository](https://github.com/google/skills/blob/main/skills/cloud/gemini-live-api/SKILL.md) by running `npx skills add google/skills --skill gemini-live-api`.
Recommended for ease of use
### [Gen AI SDK tutorial](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/get-started-sdk.md.txt)
Connect to the Gemini Live API using the Gen AI SDK to build a real-time multimodal application with a Python backend.
Raw protocol control
### [WebSocket tutorial](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/get-started-websocket.md.txt)
Connect to the Gemini Live API using WebSockets to build a real-time multimodal application with a JavaScript frontend and a Python backend.
Agent development kit
### [ADK tutorial](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/live-api/get-started-adk.md.txt)
Create an agent and use the Agent Development Kit (ADK) Streaming to enable voice and video communication.
### Partner integrations
If you want to integrate with some of our partners, these platforms have already
integrated Gemini Live API over the WebRTC protocol to streamline the
development of real-time audio and video applications.
- [Daily](https://www.daily.co/products/gemini/multimodal-live-api/)
- [LiveKit](https://docs.livekit.io/agents/integrations/google/#multimodal-live-api)
- [Twilio](https://www.twilio.com/docs)
- [Voximplant](https://voximplant.com/products/gemini-client)
#### LiveKit \& ADK reference architecture
For advanced production-grade voice assistants requiring sophisticated session orchestration, routing, and multi-agent delegation, you can build a low-latency, bidirectional integration using **LiveKit (WebRTC)** with the **Gemini Live API** via the **Agent Development Kit (ADK)**.
This architecture allows you to deploy an Orchestrator agent that handles initial customer interaction and dynamically routes requests to specialized sub-agents (for example, delegating context to a Flight Booking or Hotel Booking agent using `transferAgent` orchestration).
To explore and deploy this reference design, see the official [reference codebase implementation on GitHub](https://github.com/GoogleCloudPlatform/generative-ai/tree/main/gemini/multimodal-live-api/livekit-adk).