> [!WARNING]
> **Preview**
>
>
> This feature is a Generative AI Preview offering, subject to the "Pre-GA
> Offerings Terms" of the
> [Service Specific Terms](https://docs.cloud.google.com/terms/service-terms#1) and the
> [Additional Terms for Generative AI Preview Products](https://cloud.google.com/terms/genai-preview-products). Pre-GA features
> are available "as is" and might have limited support. For more information,
> see the [launch
> stage descriptions](https://cloud.google.com/products/#product-launch-stages).
>
>
> For this Generative AI Preview offering, Customers may elect to use it for
> production or commercial purposes, or disclose Generated Output to
> third-parties, and may process personal data as outlined in the
> [Cloud Data Processing Addendum](https://cloud.google.com/terms/data-processing-addendum), subject to the obligations and
> restrictions described in the agreement under which you access Google
> Cloud.
Gemini Robotics ER is a *vision-language model* (VLM) that brings advanced reasoning about the physical world to robotics. The model interprets visual data, performs spatial and temporal reasoning, plans multi-step tasks, and orchestrates robots and tools.
## Models
Gemini Robotics ER 2 is an update to our reasoning model that delivers precise reasoning about a robot's physical environment. It specializes in embodied reasoning capabilities, such as agentic orchestration of robots (for example, using vision-language-action (VLA) models), robot video understanding (including progress understanding and success detection), instrument reading, pointing, and spatial reasoning.
The following model is available in Preview:
- **[`gemini-robotics-er-2-preview`](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/robotics-er-2.md.txt)** : Builds on Gemini 3.5 Flash with improved spatial reasoning, video moment finding, video progress classification, multi-robot orchestration, and multi-step tool use. For technical specifications, token and quota limits, supported capabilities, regional availability, and [pricing](https://cloud.google.com/gemini-enterprise-agent-platform/generative-ai/pricing#gemini-robotics), see the [Gemini Robotics ER 2 model information](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/robotics-er-2.md.txt) page.
This guide uses the Google Gen AI SDK with
Gemini Enterprise Agent Platform. Every example initializes the
client with `enterprise=True` and authenticates with Google Cloud
credentials, so you can call the model using your own Google Cloud project.
## Robotics capabilities
The following table summarizes the core capabilities of Gemini Robotics ER 2:
| Capability | Description | Guide |
|---|---|---|
| Spatial reasoning | Point to objects, track them in video, detect with bounding boxes, plan trajectories. | [Spatial reasoning](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/spatial.md.txt) |
| Agentic code execution | Use code execution to zoom/crop images, read instruments, and annotate scenes. | [Agentic capabilities](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/agentic.md.txt) |
| Task orchestration | Combine spatial reasoning with custom robot APIs to complete long-horizon tasks. | [Task orchestration](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/orchestration.md.txt) |
| Video understanding | Moment finding and progress classification from continuous video feeds. | [Video understanding](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/video-understanding.md.txt) |
## Before you begin
Agent Platform authenticates with Google Cloud
credentials, not a Gemini API key. Complete the following setup before you run
the examples:
1. **Install the Google Gen AI SDK.**
```bash
pip install --upgrade google-genai
```
2. **Enable the API** in your Google Cloud project and make sure you have a
project ID. You can use an existing project or
[create a new one](https://docs.cloud.google.com/resource-manager/docs/creating-managing-projects.md.txt).
3. **Authenticate with Application Default Credentials (ADC).** For local
development, run:
```bash
gcloud auth application-default login
```
4. **Initialize the client** with the
Agent Platform backend. All Python examples on
this page use the following client, so set your own project ID:
```python
from google import genai
client = genai.Client(
enterprise=True,
project="your-project-id",
location="global",
)
```
Alternatively, you can set the `GOOGLE_GENAI_USE_ENTERPRISE=True`
environment variable instead of passing `enterprise=True` to the client.
> [!NOTE]
> **Note:** For preview, the endpoint is available only at `global`.
## Get started
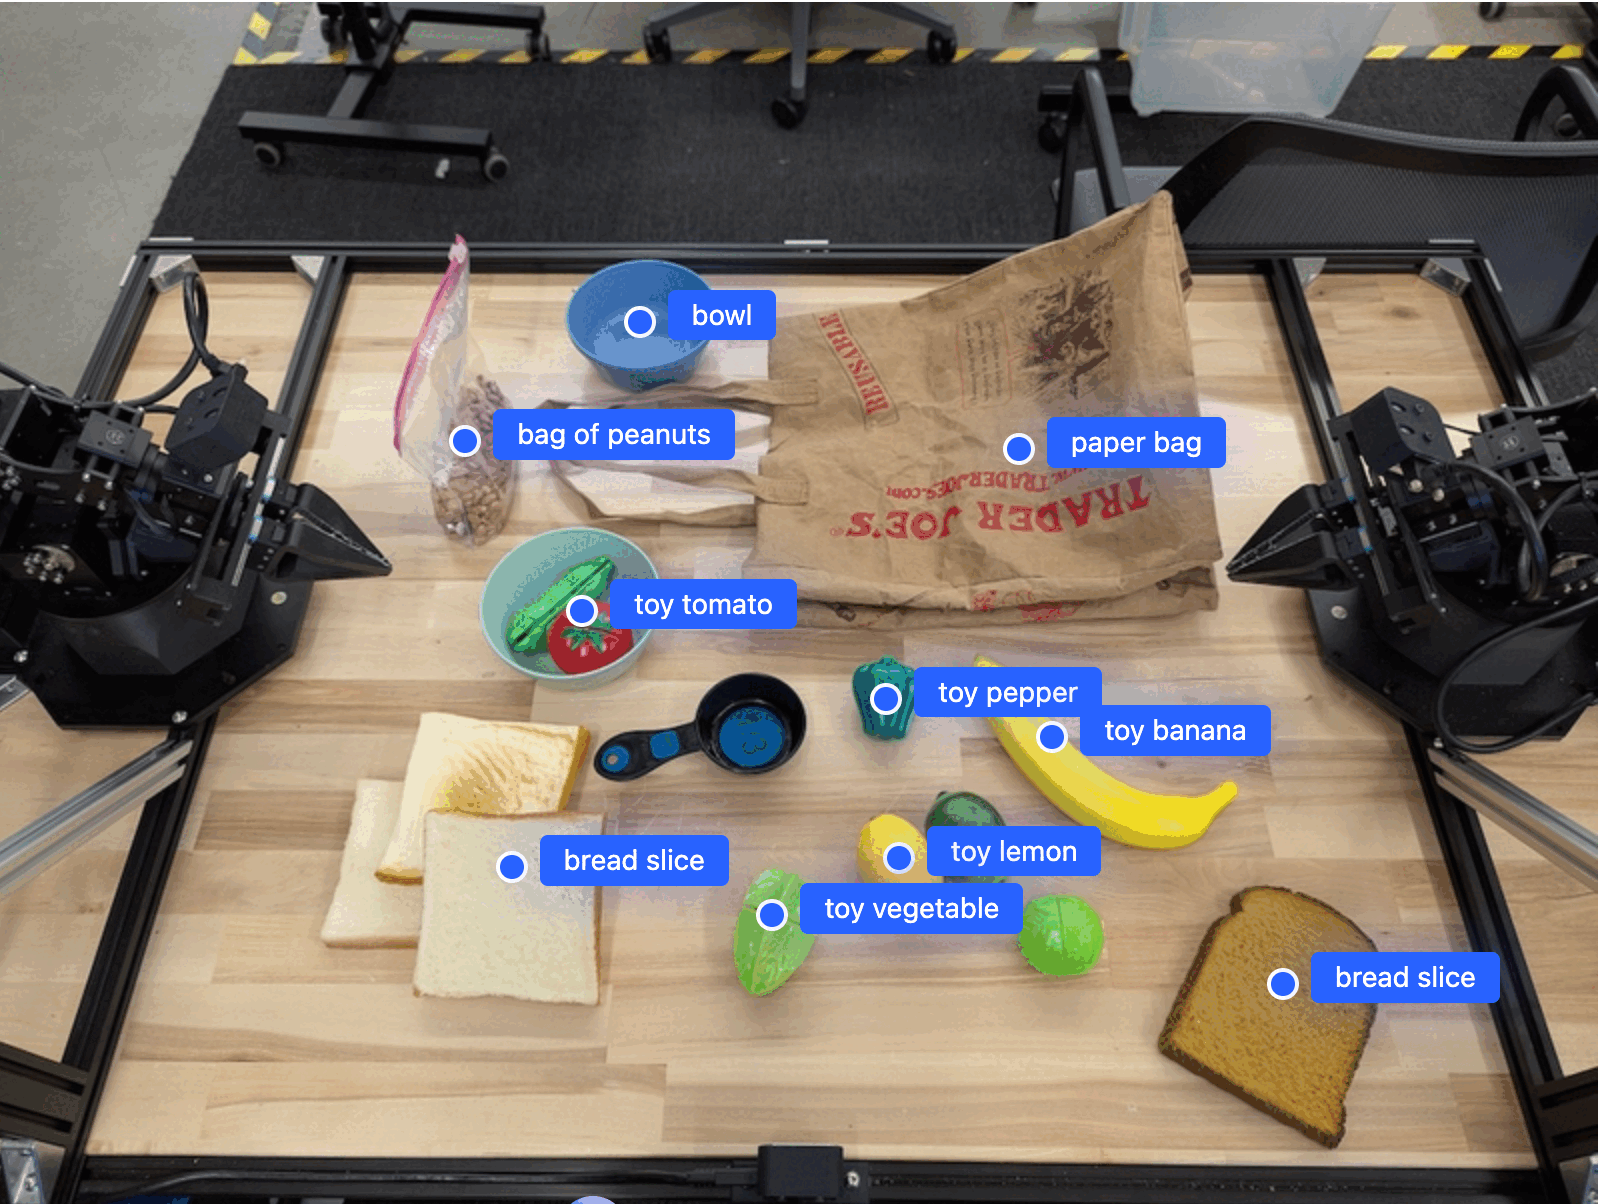
The following example finds objects in an image and returns their normalized 2D
coordinates and labels. You can pass this output directly to a robotics API or a
vision-language-action (VLA) model to generate robot actions.
### Python
```python
from google import genai
from google.genai import types
PROMPT = """
Point to no more than 10 items in the image. The label returned
should be an identifying name for the object detected.
The answer should follow the json format: [{"point": ,
"label": }, ...]. The points are in [y, x] format
normalized to 0-1000.
"""
client = genai.Client(
enterprise=True,
project="your-project-id",
location="global",
)
# Load your image
with open("my-image.png", 'rb') as f:
image_bytes = f.read()
image_response = client.models.generate_content(
model="gemini-robotics-er-2-preview",
contents=[
types.Part.from_bytes(
data=image_bytes,
mime_type='image/png',
),
PROMPT
],
config = types.GenerateContentConfig(
temperature=1.0,
thinking_config=types.ThinkingConfig(
thinking_level=types.ThinkingLevel.HIGH
),
)
)
print(image_response.text)
```
### REST
```bash
# First, ensure you have the image file locally.
# Encode the image to base64
IMAGE_BASE64=$(base64 -w 0 my-image.png)
# Set your Google Cloud project and location.
export PROJECT_ID="your-project-id"
export LOCATION="global"
export MODEL="gemini-robotics-er-2-preview"
# For the "global" location, use the aiplatform.googleapis.com host.
# For a regional location, prefix the host with the region, for example:
# https://us-central1-aiplatform.googleapis.com
curl -X POST \
"https://aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL}:generateContent" \
-H "Authorization: Bearer $(gcloud auth application-default print-access-token)" \
-H "Content-Type: application/json" \
-d '{
"contents": [
{
"parts": [
{
"inlineData": {
"mimeType": "image/png",
"data": "'"${IMAGE_BASE64}"'"
}
},
{
"text": "Point to no more than 10 items in the image. The label returned should be an identifying name for the object detected. The answer should follow the json format: [{\"point\": [y, x], \"label\": }, ...]. The points are in [y, x] format normalized to 0-1000."
}
]
}
],
"generationConfig": {
"temperature": 1.0,
"thinkingConfig": {
"thinkingLevel": "HIGH"
}
}
}'
```
The output will be a JSON array containing objects, each with a `point`
(normalized `[y, x]` coordinates) and a `label` identifying the object.
### JSON
```json
[
{"point": [376, 508], "label": "small banana"},
{"point": [287, 609], "label": "larger banana"},
{"point": [223, 303], "label": "pink starfruit"},
{"point": [435, 172], "label": "paper bag"},
{"point": [270, 786], "label": "green plastic bowl"},
{"point": [488, 775], "label": "metal measuring cup"},
{"point": [673, 580], "label": "dark blue bowl"},
{"point": [471, 353], "label": "light blue bowl"},
{"point": [492, 497], "label": "bread"},
{"point": [525, 429], "label": "lime"}
]
```
The following image is an example of how these points can be displayed:
## How it works
Gemini Robotics ER 2 takes image, video, or audio input with natural language
prompts. It identifies objects, reasons about scene context and spatial
relationships, and returns structured output like coordinates or bounding boxes.
It is also agentic: it breaks complex tasks into sub-tasks and executes them by
calling your robot functions or running generated code. For example, "put the
apple in the bowl" becomes a sequence of locate, grasp, and place steps.
Read more about how function calling with Gemini works on the
[Function calling](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/tools/function-calling.md.txt) page.
## Safety
Gemini Robotics ER 2 is built with safety in mind, but it is your
responsibility to maintain a safe environment around the robot. Generative AI
models can make mistakes, and physical robots can cause damage. Safety is a
priority, and making generative AI models safe when used with real-world
robotics is an active and critical area of our research. To learn more, visit
the [Google DeepMind robotics safety page](https://deepmind.google/models/gemini-robotics/safety).
## Best practices
Follow these best practices to get the best results from Gemini Robotics ER 2:
1. Use plain, natural language. Describe what you want the robot to do as you
would to a person. If a term isn't working, try a common synonym.
2. Optimize visual input. Crop or zoom into small or unclear objects before
sending the image. Lighting and low color contrast can affect detection.
3. Break complex tasks into steps. Send each step as a separate prompt to
improve accuracy on each sub-task.
4. Query multiple times and average results for high-precision tasks. This
consensus approach reduces variance on spatial outputs.
## Limitations
Consider the following limitations when developing with Gemini Robotics ER 2:
- **Latency versus performance:** Complex queries, high-resolution inputs, or `thinking_level.HIGH` can lead to increased processing times. Use `thinking_level.MEDIUM` for a good balance between latency and performance.
- **Hallucinations:** Like all large language models, Gemini Robotics ER 2 can occasionally "hallucinate" or provide incorrect information, especially for ambiguous prompts or out-of-distribution inputs.
- **Dependence on prompt quality:** The quality of the model's output is highly dependent on the clarity and specificity of the input prompt. Vague or poorly structured prompts can lead to suboptimal results.
- **Computational resources:** Running the model, especially with video inputs or `thinking_level.HIGH`, consumes additional computational resources. See the [Thinking](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/thinking.md.txt) page for more details.
- **Input types:** See the following topics for details on the limitations for
each modality:
- [Image inputs](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/capabilities/image-understanding.md.txt)
- [Video inputs](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/capabilities/video-understanding.md.txt)
- [Audio inputs](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/capabilities/audio-understanding.md.txt)
## Privacy notice
You acknowledge that the models referenced in this document (the "Robotics
Models") leverage video and audio data in order to operate and move your
hardware in accordance with your instructions. You therefore may operate the
Robotics Models such that data from identifiable persons, such as voice,
imagery, and likeness data ("Personal Data"), will be collected by the Robotics
Models. If you elect to operate the Robotics Models in a manner that collects
Personal Data, you agree that you will not permit any identifiable persons to
interact with, or be present in the area surrounding, the Robotics Models,
unless and until such identifiable persons have been sufficiently notified of
and consented to the collection and use of their Personal Data as outlined in
the applicable Agent Platform terms of service. You
will ensure that such notice permits the collection and use of Personal Data as
outlined in those terms, and you will use commercially reasonable efforts to
minimize the collection and distribution of Personal Data by using techniques
such as face blurring and operating the Robotics Models in areas not containing
identifiable persons to the extent practicable.
## What's next
To learn more about Gemini Robotics ER 2, see the following resources:
- [Gemini Robotics ER 2 model information](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/robotics-er-2.md.txt): technical specifications, token limits, and supported capabilities.
- [Gemini Robotics ER pricing](https://cloud.google.com/gemini-enterprise-agent-platform/generative-ai/pricing#gemini-robotics): pricing details on Agent Platform.
- [Spatial reasoning](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/spatial.md.txt): pointing, tracking, bounding boxes, and trajectories.
- [Agentic capabilities](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/agentic.md.txt): code execution, instrument reading, and image annotation.
- [Task orchestration](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/orchestration.md.txt): long-horizon tasks with custom robot APIs.
- [Video understanding](https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/gemini-robotics-er/video-understanding.md.txt): moment finding and progress classification.
- [Gemini Robotics ER 2 model card](https://deepmind.google/models/model-cards/gemini-robotics-er-2/): evaluation benchmarks, architecture, and training details.
- [Gemini Robotics ER 2 blog post](https://blog.google/innovation-and-ai/models-and-research/google-deepmind/gemini-robotics-er-2/): announcement and overview from Google DeepMind.
- [Google DeepMind robotics safety](https://deepmind.google/models/gemini-robotics/safety): safety research behind the model family.