This document outlines the network bandwidth capabilities and configurations for
Compute Engine instances with attached GPUs. Learn about the maximum network
bandwidth, Network Interface Card (NIC) arrangements, and recommended
VPC network setups for various GPU machine types, including the
A5X, A4X Max, A4X, A4, A3, A2, G4, G2, and N1 series. Understanding these
configurations can help you optimize performance for your distributed workloads
on Compute Engine.
## Overview
The following table provides a general comparison of networking capabilities
across GPU machine types.
| Machine type | GPU model | Max total bandwidth | GPU to GPU networking technology |
| A5X | NVIDIA Vera Rubin superchips | 7,200 Gbps | GPUDirect RDMA |
| A4X Max | NVIDIA GB300 Ultra superchips | 3,600 Gbps | GPUDirect RDMA |
| A4X | NVIDIA GB200 superchips | 2,000 Gbps | GPUDirect RDMA |
| A4 | NVIDIA B200 | 3,600 Gbps | GPUDirect RDMA |
| A3 Ultra | NVIDIA H200 | 3,600 Gbps | GPUDirect RDMA |
| A3 Mega | NVIDIA H100 80GB | 1,800 Gbps | GPUDirect-TCPXO |
| A3 High | NVIDIA H100 80GB | 1,000 Gbps | GPUDirect-TCPX |
| A3 Edge | NVIDIA H100 80GB | 600 Gbps | GPUDirect-TCPX |
| G4 | NVIDIA RTX PRO 6000 | 400 Gbps | N/A |
| A2 Standard and A2 Ultra | NVIDIA A100 40GB, NVIDIA A100 80GB | 100 Gbps | N/A |
| G2 | NVIDIA L4 | 100 Gbps | N/A |
| N1 (T4, V100) | NVIDIA T4, NVIDIA V100 | 100 Gbps | N/A |
| N1 (P4) | NVIDIA P4 | 32 Gbps | N/A |
|---|---|---|---|
### GPUDirect RDMA and MRDMA functions
On certain accelerator-optimized machine types, Google Cloud uses
MRDMA as the network interface implementation for GPU-to-GPU networking that
supports GPUDirect RDMA.
**GPUDirect RDMA** is an NVIDIA technology that enables a network interface card
(NIC) to directly access GPU memory over PCIe, bypassing host CPU and system
memory. This peer-to-peer communication between NIC and GPU significantly
reduces latency for inter-node GPU-to-GPU communication.
**MRDMA** is the network interface implementation used on A5X, A4X Max, A4X, A4,
and A3 Ultra machine types to provide GPUDirect RDMA capabilities. MRDMA is
based on NVIDIA ConnectX NICs and is deployed in one of the following ways:
- **MRDMA Virtual Functions (VFs)**: used in A3 Ultra, A4, and A4X series.
- **MRDMA Physical Functions (PFs)**: used in the A5X and A4X Max series.
### MRDMA functions and network monitoring tools
The A4X, A4, and A3 Ultra machine types implement high-performance GPU-to-GPU
networking by using MRDMA Virtual Functions (VFs). As these are virtualized
entities, certain hardware-level monitoring capabilities are restricted compared
to Physical Functions (PFs).
With MRDMA VFs, standard physical port counters (such as those
ending in `_phy`) appear in `ethtool -S`
output but won't update during network activity. This is a characteristic of
the MRDMA VF architecture. To accurately track network performance on
these interfaces, review the entries for the **vPort Counter Table** instead
of the **Physical Port Counter Table**.
The A5X and A4X Max machine types use MRDMA PFs. Unlike the MRDMA VF-based
machine types, A5X and A4X Max support the full range of physical port counters
for GPU networking.
## Review networking concepts for GPU machine types
Use the following section to review the network arrangement and bandwidth speed
for each GPU machine type.
### A5X, A4X Max, and A4X machine types
The A5X, A4X Max, and A4X machine series are designed for demanding,
large-scale, distributed AI workloads. The primary differentiator among these
series is their attached accelerators and networking hardware, as outlined in
the following table:
| Feature | A5X machine series | A4X Max machine series | A4X machine series |
| Attached hardware | NVIDIA Vera Rubin superchips | NVIDIA GB300 Ultra superchips | NVIDIA GB200 superchips |
| GPU-to-GPU networking | 8 NVIDIA ConnectX-9 (CX-9) SuperNICs that provide 6,400 Gbps bandwidth in a rail-aligned, 8-plane topology: each GPU has two 800 Gbps NICs, each split into four 200 Gbps ports, and the eight ports of each GPU connect to eight separate network planes | 4 NVIDIA ConnectX-8 (CX-8) SuperNICs that provide 3,200 Gbps bandwidth in an 8-way rail-aligned topology | 4 NVIDIA ConnectX-7 (CX-7) NICs that provide 1,600 Gbps bandwidth in a 4-way rail-aligned topology |
| GPU-to-GPU networking implementation | 32 MRDMA Physical Functions (PFs) configured as 4 PFs per NIC | 8 MRDMA Physical Functions (PFs) configured as 2 PFs per NIC | 4 MRDMA Virtual Functions (VFs) configured as 1 VF per NIC |
| Host networking (Titanium) | 2 Titanium smart NICs that provide 800 Gbps bandwidth | 2 Titanium smart NICs that provide 400 Gbps bandwidth | 2 Titanium smart NICs that provide 400 Gbps bandwidth |
| Total maximum network bandwidth | 7,200 Gbps | 3,600 Gbps | 2,000 Gbps |
|---|---|---|---|
#### Multi-layered networking architecture
A5X, A4X Max, and A4X compute instances use a multi-layered, hierarchical
networking architecture with a rail-aligned design to optimize performance for
various communication types. In this topology, instances connect across multiple
independent network planes, called rails.
- A5X instances use a rail-aligned, 8-plane topology: each GPU has two 800 Gbps CX-9 SuperNICs, each split into four 200 Gbps ports, and the eight ports of each GPU connect to eight separate network planes.
- A4X Max instances use an 8-way rail-aligned topology where each of the four 800 Gbps ConnectX-8 NICs connects to two separate 400 Gbps rails.
- A4X instances use a 4-way rail-aligned topology where each of the four ConnectX-7 NICs connects to a separate rail.
The networking layers for these machine types are as follows:
- **Intra-node and Intra-subblock communication (NVLink)**: A high-speed
NVLink fabric interconnects GPUs for high-bandwidth, low-latency
communication. This fabric connects all the GPUs within a single instance
and extends across a subblock, which consists of 18 A5X, A4X Max, or A4X
instances (a total of 72 GPUs). This allows all 72 GPUs in a subblock to
communicate as if they were in a single, large-scale GPU server.
- **Inter-subblock communication (ConnectX NICs with RoCE)**: to scale
workloads beyond a single subblock, these machines use NVIDIA ConnectX NICs.
These NICs use RDMA over Converged Ethernet (RoCE) to
provide high-bandwidth, low-latency communication between subblocks, to let
you build large-scale training clusters with thousands of GPUs.
- **Host networking (Titanium Smart NICs)**: in addition
to the specialized GPU networks, each instance has two host network
interfaces, providing a combined 800 Gbps of bandwidth on A5X
instances or 400 Gbps of bandwidth on A4X Max and A4X instances.
The host network interfaces are used for storage, management, and
connecting to other Google Cloud services or the public internet.
##### A5X architecture
The A5X architecture uses NVIDIA Vera Rubin superchips. Each instance provides
eight 800 Gbps NVIDIA ConnectX-9 (CX-9) SuperNICs, two per GPU. Each
SuperNIC has four 200 Gbps ports and appears to the instance as four MRDMA
PFs, for 32 MRDMA PFs and 6,400 Gbps of GPU-to-GPU bandwidth. Each instance
also includes two 400 Gbps Titanium smart NICs that provide
800 Gbps of host networking bandwidth.
##### A4X Max architecture
The A4X Max architecture is built around NVIDIA GB300 Ultra superchips. A key
feature of this design is the direct connection of the four 800 Gbps
NVIDIA ConnectX-8 (CX-8) SuperNICs to the GPUs. Each ConnectX-8 is a dual-port
NIC, that is exposed to the instance as two Physical Functions (PFs). These
NICs are part of an 8-way rail-aligned network topology where each NIC
connects to two separate 400 Gbps rails. This direct path enables RDMA,
providing high bandwidth and low latency for GPU-to-GPU communication across
different subblocks. These Compute Engine instances also include
high-performance local SSDs that are attached to the ConnectX-8 NICs,
bypassing the PCIe bus for faster data access.
[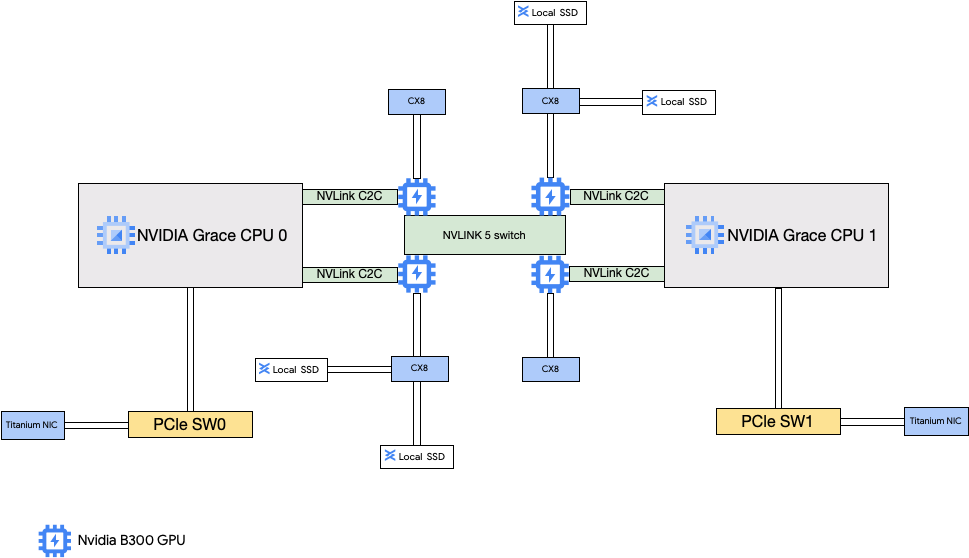](https://docs.cloud.google.com/compute/images/gpus/a4x-max-networking.png) Figure 1. Network architecture for a single A4X Max host
##### A4X architecture
The A4X architecture uses NVIDIA GB200 superchips. In this configuration, the
four NVIDIA ConnectX-7 (CX-7) NICs are connected to the host CPU. This setup
provides high-performance networking for GPU-to-GPU communication between
subblocks.
[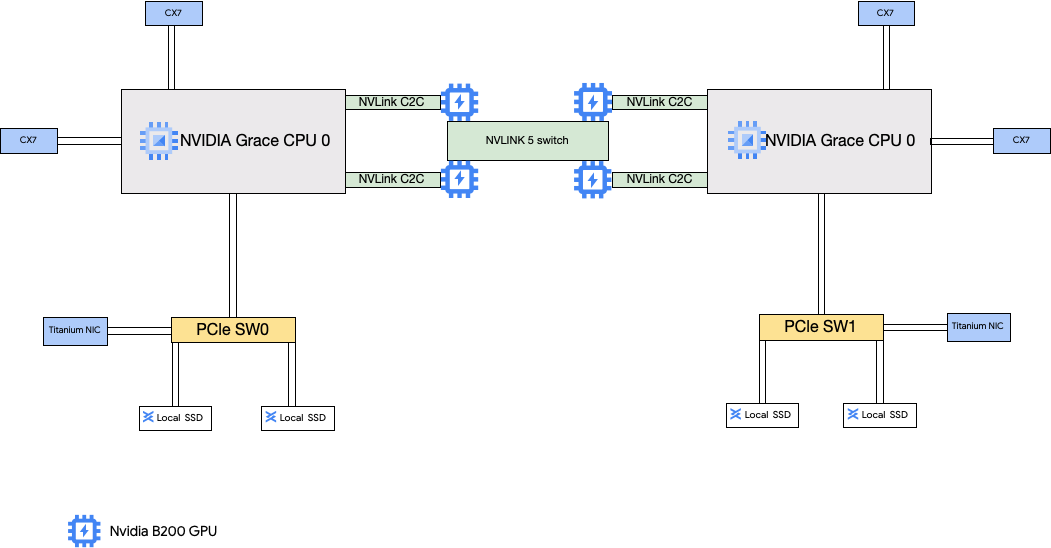](https://docs.cloud.google.com/compute/images/gpus/a4x-networking.png) Figure 2. Network architecture for a single A4X host
#### A5X, A4X Max, and A4X Virtual Private Cloud (VPC) network configuration
To use the full networking capabilities of these machine types, you need
to create and attach VPC networks to your instances. To use all
available NICs, you must create VPC networks as follows:
- **Two regular VPC networks** for the Titanium
Smart NICs. For A5X, these VPC networks support IPv4, IPv6,
and [Bring Your Own IP (BYOIP)](https://docs.cloud.google.com/vpc/docs/bring-your-own-ip) addresses.
However, BYOIP external IPv6 subnet ranges are supported only for VM
instances.
- For A5X and A4X Max, these VPC networks use the [Intel IDPF LAN PF device driver](https://docs.cloud.google.com/compute/docs/networking/using-idpf).
- For A4X, these VPC networks use the [Google Virtual NIC (gVNIC)](https://docs.cloud.google.com/compute/docs/networking/using-gvnic) network interface.
- **One VPC network with a [RoCE network profile](https://docs.cloud.google.com/vpc/docs/rdma-network-profiles)**
is required for the ConnectX NICs when you create clusters of multiple A5X,
A4X Max, or A4X subblocks. If you use a single subblock, you can omit this
VPC network because the multi-node NVLink fabric handles
direct GPU-to-GPU communication.
- For A5X and A4X Max bare metal instances, create a [RoCE VPC network for bare metal instances (`roce-metal`)](https://docs.cloud.google.com/vpc/docs/rdma-network-profiles#roce-metal-supported-features), which automatically provides a single IPv6-only subnet for all MRDMA network interfaces (32 on A5X, 8 on A4X Max).
- For A4X VM instances, create a [RoCE VPC network for VM instances (`roce`)](https://docs.cloud.google.com/vpc/docs/rdma-network-profiles#roce-supported-features), and then manually create four IPv4-only subnets in that network, one subnet for each network rail.
To set up these networks in the AI Hypercomputer documentation, see
the following guides:
- For A5X instances, contact your account team to [reserve capacity](https://docs.cloud.google.com/ai-hypercomputer/docs/reserve-capacity) and get instructions to create instances and clusters.
- For A4X Max instances, see [Create VPC networks for A4X Max](https://docs.cloud.google.com/ai-hypercomputer/docs/create/create-a4xmax-instance#setup-network).
- For A4X instances, see [Create VPC networks for A4X](https://docs.cloud.google.com/ai-hypercomputer/docs/create/create-vm-a4x#setup-network).
#### A5X, A4X Max, and A4X machine types
### A5X
> [!NOTE]
> **Note:** To get started with A5X instances, contact your account team to [reserve capacity](https://docs.cloud.google.com/ai-hypercomputer/docs/reserve-capacity) and get instructions to create instances and clusters.
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA Rubin GPU count | GPU memory (GB HBM4) |
| `a5x-highgpu-4g-metal` | 176 | 1,440 | 48,000 | 10 | 7,200 | 4 | 1,152 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : for A5X bare metal instances, the vCPU count of 176 represents the 176 physical CPU cores across two 88-core sockets on the NVIDIA Vera [CPU platform](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that stores temporary data. It's separate from the instance's memory and handles the higher bandwidth demands of your graphics-intensive workloads.
### A4X Max
> [!NOTE]
> **Note:** When provisioning A4X Max instances, you must [reserve capacity](https://docs.cloud.google.com/ai-hypercomputer/docs/reserve-capacity) to create instances and clusters. You can then create instances that use the features and services available from AI Hypercomputer. For more information, see [Deployment options overview](https://docs.cloud.google.com/ai-hypercomputer/docs/create/create-overview) in the AI Hypercomputer documentation.
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA GB300 GPU count | GPU memory (GB HBM3e) |
| `a4x-maxgpu-4g-metal` | 144 | 960 | 12,000 | 6 | 3,600 | 4 | 1,116 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### A4X
> [!NOTE]
> **Note:** When provisioning A4X instances, you must [reserve capacity](https://docs.cloud.google.com/ai-hypercomputer/docs/reserve-capacity) to create instances and clusters. You can then create instances that use the features and services available from AI Hypercomputer. For more information, see [Deployment options overview](https://docs.cloud.google.com/ai-hypercomputer/docs/create/create-overview) in the AI Hypercomputer documentation.
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA GB200 GPU count | GPU memory (GB HBM3e) |
| `a4x-highgpu-4g` | 140 | 884 | 12,000 | 6 | 2,000 | 4 | 744 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### A4 and A3 Ultra machine types
The A4 machine types have NVIDIA B200 GPUs attached and A3 Ultra machine
types have NVIDIA H200 GPUs attached.
These machine types provide eight NVIDIA ConnectX-7 (CX-7) network interface
cards (NICs) and two Google virtual NICs (gVNIC). The eight CX-7 NICs deliver a
total network bandwidth of 3,200 Gbps. These NICs are dedicated for
only high-bandwidth GPU to GPU communication and can't be used for other
networking needs such as public internet access. As outlined in the following
diagram, each CX-7 NIC is aligned with one GPU to optimize non-uniform memory
access (NUMA). All eight GPUs can rapidly communicate with each other by
using the all to all NVLink bridge that connects them. The two other gVNIC
network interface cards are smart NICs that provide an additional 400 Gbps
of network bandwidth for general purpose networking requirements. Combined, the
network interface cards provide a total maximum network bandwidth of
3,600 Gbps for these machines.
The high-performance GPU-to-GPU networking on A4 and A3 Ultra instances is
implemented by using MRDMA Virtual Functions (VFs) for each of the eight
ConnectX-7 NICs.
[](https://docs.cloud.google.com/compute/images/gpus/a3u-a4-networking.png) Figure 3. Network architecture for a single A4 or A3 Ultra host
To use these multiple NICs, you need to create 3 Virtual Private Cloud networks
as follows:
- Two regular VPC networks: each gVNIC must attach to a different VPC network
- One RoCE VPC network: all eight CX-7 NICs share the same RoCE VPC network
To set up these networks,
see [Create VPC networks](https://docs.cloud.google.com/ai-hypercomputer/docs/create/create-vm#setup-network)
in the AI Hypercomputer documentation.
### A4
> [!NOTE]
> **Note:** When provisioning A4 machine types, you must reserve capacity to create instances or clusters, use Spot VMs, use Flex-start VMs, or create a resize request in a MIG. For instructions on how to create A4 instances, see [Create an A3 Ultra or A4 instance](https://docs.cloud.google.com/compute/docs/gpus/create-gpu-vm-a3u-a4#create-overview). .
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA B200 Blackwell GPU count | GPU memory (GB HBM3e) |
| `a4-highgpu-8g` | 224 | 3,968 | 12,000 | 10 | 3,600 | 8 | 1,440 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### A3 Ultra
> [!NOTE]
> **Note:** When provisioning A3 Ultra machine types, you must reserve capacity to create instances or clusters, use Spot VMs, use Flex-start VMs, or create a resize request in a MIG. For more information about the parameters to set when creating an A3 Ultra instance, see [Create an A3 Ultra or A4 instance](https://docs.cloud.google.com/compute/docs/gpus/create-gpu-vm-a3u-a4#create-overview).
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA H200 GPU count | GPU memory (GB HBM3e) |
| `a3-ultragpu-8g` | 224 | 2,952 | 12,000 | 10 | 3,600 | 8 | 1128 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### A3 Mega, High, and Edge machine types
These machine types have H100 GPUs attached. Each of these machine types
have a fixed GPU count, vCPU count, and memory size.
- **Single NIC A3 VMs**: For A3 VMs with 1 to 4 GPUs attached, only a single physical network interface card (NIC) is available.
- **Multi-NIC A3 VMs** : For A3 VMs with 8 GPUS attached, multiple physical NICs are available. For these A3 machine types the NICs are arranged as follows on a Peripheral Component Interconnect Express (PCIe) bus:
- For the *A3 Mega machine type*: a NIC arrangement of 8+1 is available. With this arrangement, 8 NICs share the same PCIe bus, and 1 NIC resides on a separate PCIe bus.
- For the *A3 High machine type*: a NIC arrangement of 4+1 is available. With this arrangement, 4 NICs share the same PCIe bus, and 1 NIC resides on a separate PCIe bus.
- *For the *A3 Edge machine type* machine type*: a NIC arrangement of 4+1 is available. With this arrangement, 4 NICs share the same PCIe bus, and 1 NIC resides on a separate PCIe bus. These 5 NICs provide a total network bandwidth of 400 Gbps for each VM.
NICs that share the same PCIe bus, have a non-uniform memory access (NUMA) alignment of one NIC
per two NVIDIA H100 GPUs. These NICs are ideal for dedicated high bandwidth GPU to GPU
communication. The physical NIC that resides on a separate PCIe bus is ideal for other networking
needs. For instructions on how to set up networking for A3 High and A3 Edge VMs, see
[set up jumbo frame MTU networks](https://docs.cloud.google.com/compute/docs/gpus/gpudirect#setup-jumbo-frame).
### A3 Mega
> [!NOTE]
> **Note:** When provisioning `a3-megagpu-8g` machine types, we recommend using a cluster of these instances and deploying with a scheduler such as Google Kubernetes Engine (GKE) or Slurm. For detailed instructions on either of these options, review the following:
>
> - To create Google Kubernetes Engine cluster, see [Deploy an A3 Mega cluster
> with GKE](https://docs.cloud.google.com/kubernetes-engine/docs/how-to/gpu-bandwidth-gpudirect-tcpx).
> - To create a Slurm cluster, see [Deploy an A3 Mega Slurm cluster](https://docs.cloud.google.com/cluster-toolkit/docs/deploy/slurm/deploy-a3-mega-cluster).
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA H100 GPU count | GPU memory (GB HBM3) |
| `a3-megagpu-8g` | 208 | 1,872 | 6,000 | 9 | 1,800 | 8 | 640 |
|---|---|---|---|---|---|---|---|
### A3 High
> [!NOTE]
> **Note:** When provisioning `a3-highgpu-1g`, `a3-highgpu-2g`, or `a3-highgpu-4g` machine types, you must create instances by using Spot VMs or Flex-start VMs. For detailed instructions on these options, review the following:
>
> - To create Spot VMs, set the provisioning model to `SPOT` when you [create an accelerator-optimized
> VM](https://docs.cloud.google.com/compute/docs/gpus/create-gpu-vm-accelerator-optimized).
> - To create Flex-start VMs, you can use one of the following methods:
> - Create a standalone VM and set the provisioning model to `FLEX_START` when you [create an
> accelerator-optimized VM](https://docs.cloud.google.com/compute/docs/gpus/create-gpu-vm-accelerator-optimized).
> - Create a resize request in a managed instance group (MIG). For instructions, see [Create a MIG with GPU
> VMs](https://docs.cloud.google.com/compute/docs/instance-groups/create-mig-with-gpu-vms).
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA H100 GPU count | GPU memory (GB HBM3) |
| `a3-highgpu-1g` | 26 | 234 | 750 | 1 | 25 | 1 | 80 |
| `a3-highgpu-2g` | 52 | 468 | 1,500 | 1 | 50 | 2 | 160 |
| `a3-highgpu-4g` | 104 | 936 | 3,000 | 1 | 100 | 4 | 320 |
| `a3-highgpu-8g` | 208 | 1,872 | 6,000 | 5 | 1,000 | 8 | 640 |
|---|---|---|---|---|---|---|---|
### A3 Edge
> [!NOTE]
> **Note:** To get started with A3 Edge instances, see [Create an A3 VM with GPUDirect-TCPX enabled](https://docs.cloud.google.com/compute/docs/gpus/gpudirect).
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA H100 GPU count | GPU memory (GB HBM3) |
| `a3-edgegpu-8g` | 208 | 1,872 | 6,000 | 5 | 600 (`asia-south1` and `northamerica-northeast2`) or 400 (all other [A3 Edge regions](https://docs.cloud.google.com/compute/docs/gpus/gpu-regions-zones#view-using-table)) | 8 | 640 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### A2 machine types
Each A2 machine type has a fixed number of NVIDIA A100 40GB or NVIDIA A100
80 GB GPUs attached. Each machine type also has a fixed vCPU count and
memory size.
A2 machine series are available in two types:
- A2 Ultra: these machine types have A100 80GB GPUs and Local SSD disks attached.
- A2 Standard: these machine types have A100 40GB GPUs attached.
### A2 Ultra
| Machine type | vCPU count | Instance memory (GB) | Attached Local SSD (GiB) | Maximum network bandwidth (Gbps) | NVIDIA A100 80GB GPU count | GPU memory (GB HBM2e) |
| `a2-ultragpu-1g` | 12 | 170 | 375 | 24 | 1 | 80 |
| `a2-ultragpu-2g` | 24 | 340 | 750 | 32 | 2 | 160 |
| `a2-ultragpu-4g` | 48 | 680 | 1,500 | 50 | 4 | 320 |
| `a2-ultragpu-8g` | 96 | 1,360 | 3,000 | 100 | 8 | 640 |
|---|---|---|---|---|---|---|
### A2 Standard
| Machine type | vCPU count | Instance memory (GB) | Local SSD supported | Maximum network bandwidth (Gbps) | NVIDIA A100 40GB GPU count | GPU memory (GB HBM2) |
| `a2-highgpu-1g` | 12 | 85 | Yes | 24 | 1 | 40 |
| `a2-highgpu-2g` | 24 | 170 | Yes | 32 | 2 | 80 |
| `a2-highgpu-4g` | 48 | 340 | Yes | 50 | 4 | 160 |
| `a2-highgpu-8g` | 96 | 680 | Yes | 100 | 8 | 320 |
| `a2-megagpu-16g` | 96 | 1,360 | Yes | 100 | 16 | 640 |
|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### G4 machine types
> [!WARNING]
>
> **Preview**
>
>
> This feature is
>
> subject to the "Pre-GA Offerings Terms" in the General Service Terms section of the
> [Service Specific
> Terms](https://docs.cloud.google.com/terms/service-terms#1).
>
> Pre-GA features are available "as is" and might have limited support.
>
> For more information, see the
> [launch stage descriptions](https://cloud.google.com/products/#product-launch-stages).
[G4 accelerator-optimized](https://docs.cloud.google.com/compute/docs/accelerator-optimized-machines#g4-series)
machine types use [NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs](https://www.nvidia.com/en-us/data-center/rtx-pro-6000-blackwell-server-edition/) (`nvidia-rtx-pro-6000`)
and are
suitable for NVIDIA Omniverse simulation workloads, graphics-intensive applications, video
transcoding, and virtual desktops. G4 machine types also provide a low-cost solution for
performing single host inference and model tuning compared with A series machine types.
You can also add Titanium SSD disks when you create a G4 instance. For the number of disks
you can attach, see
[Machine types that require you to choose a number of Local SSD disks](https://docs.cloud.google.com/compute/docs/disks/local-ssd#lssd_disk_options).
For information about machine type limitations, see
[G4 limitations](https://docs.cloud.google.com/compute/docs/accelerator-optimized-machines#g4-limitations).
> [!NOTE]
> **Note:** To get started with G4 instances, see [Create a G4 instance](https://docs.cloud.google.com/compute/docs/gpus/create-gpu-vm-g-series).
| Machine type | vCPU count | Instance memory (GB) | Maximum Titanium SSD supported (GiB) | Physical NIC count | Maximum network bandwidth (Gbps) | NVIDIA RTX PRO 6000 GPU count | GPU memory (GB GDDR7) |
| `g4-standard-6` | 6 | 22 | 0 | 1 | 20 | 1/8 | 12 |
| `g4-standard-12` | 12 | 45 | 375 | 1 | 20 | 1/4 | 24 |
| `g4-standard-24` | 24 | 90 | 750 | 1 | 20 | 1/2 | 48 |
| `g4-standard-48` | 48 | 180 | 1,500 | 1 | 50 | 1 | 96 |
| `g4-standard-96` | 96 | 360 | 3,000 | 1 | 100 | 2 | 192 |
| `g4-standard-192` | 192 | 720 | 6,000 | 1 | 200 | 4 | 384 |
| `g4-standard-384` | 384 | 1,440 | 12,000 | 2 | 400 | 8 | 768 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### G2 machine types
[G2 accelerator-optimized](https://docs.cloud.google.com/compute/docs/accelerator-optimized-machines#g2-vms)
machine types have [NVIDIA L4 GPUs](https://www.nvidia.com/en-us/data-center/l4/)
attached and are ideal for cost-optimized inference, graphics-intensive and
high performance computing workloads.
Each G2 machine type also has a default memory and a custom
memory range. The custom memory range defines the amount of memory that
you can allocate to your instance for each machine type. You can also add Local
SSD disks when creating a G2 instance. For the number of disks
you can attach, see
[Machine types that require you to choose a number of Local SSD disks](https://docs.cloud.google.com/compute/docs/disks/local-ssd#lssd_disk_options).
To get the higher network bandwidth rates (50 Gbps or higher) applied
to most GPU instances, it is recommended that you use Google Virtual NIC (gVNIC).
For more information about creating GPU instances that use gVNIC, see
[Creating GPU instances that use higher bandwidths](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus#create-high-bandwidth-vm).
| Machine type | vCPU count | Default instance memory (GB) | Custom instance memory range (GB) | Max Local SSD supported (GiB) | Maximum network bandwidth (Gbps) | NVIDIA L4 GPU count | GPU memory (GB GDDR6) |
| `g2-standard-4` | 4 | 16 | 16 to 32 | 375 | 10 | 1 | 24 |
| `g2-standard-8` | 8 | 32 | 32 to 54 | 375 | 16 | 1 | 24 |
| `g2-standard-12` | 12 | 48 | 48 to 54 | 375 | 16 | 1 | 24 |
| `g2-standard-16` | 16 | 64 | 54 to 64 | 375 | 32 | 1 | 24 |
| `g2-standard-24` | 24 | 96 | 96 to 108 | 750 | 32 | 2 | 48 |
| `g2-standard-32` | 32 | 128 | 96 to 128 | 375 | 32 | 1 | 24 |
| `g2-standard-48` | 48 | 192 | 192 to 216 | 1,500 | 50 | 4 | 96 |
| `g2-standard-96` | 96 | 384 | 384 to 432 | 3,000 | 100 | 8 | 192 |
|---|---|---|---|---|---|---|---|
The following notes apply to the preceding table:
- **vCPU count** : a vCPU is implemented as a single hardware hyper-thread on one of the available [CPU platforms](https://docs.cloud.google.com/compute/docs/cpu-platforms).
- **Maximum network bandwidth** : maximum egress bandwidth can't exceed the number given. Actual egress bandwidth depends on the destination IP address and other factors. For more information about network bandwidth, see [Network bandwidth](https://docs.cloud.google.com/compute/docs/network-bandwidth).
- **GPU memory**: GPU memory is the memory on a GPU device that can be used for temporary storage of data. It is separate from the instance's memory and is specifically designed to handle the higher bandwidth demands of your graphics-intensive workloads.
### N1 + GPU machine types
For N1 general-purpose virtual machine (VM) instances that have T4 and V100 GPUs
attached, you can get a
maximum network bandwidth of up to 100 Gbps, based on the combination of
GPU and vCPU count. For all other N1 GPU instances, see [Overview](https://docs.cloud.google.com/compute/docs/gpus/gpu-network-bandwidth#overview).
Review the following section to calculate the maximum network bandwidth that
is available for your T4 and V100 instances based on the GPU model, vCPU, and GPU count.
### Less than 5 vCPUs
For T4 and V100 instances that have 5 vCPUs or less, a maximum network bandwidth
of 10 Gbps is available.
### More than 5 vCPUs
For T4 and V100 instances that have more than 5 vCPUs, maximum network bandwidth
is calculated based on the number of vCPUs and GPUs for that VM.
To get the higher network bandwidth rates (50 Gbps or higher) applied
to most GPU instances, it is recommended that you use Google Virtual NIC (gVNIC).
For more information about creating GPU instances that use gVNIC, see
[Creating GPU instances that use higher bandwidths](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus#create-high-bandwidth-vm).
| GPU model | Number of GPUs | Maximum network bandwidth calculation |
|---|---|---|
| NVIDIA V100 | 1 | `min(vcpu_count * 2, 32)` |
| NVIDIA V100 | 2 | `min(vcpu_count * 2, 32)` |
| NVIDIA V100 | 4 | `min(vcpu_count * 2, 50)` |
| NVIDIA V100 | 8 | `min(vcpu_count * 2, 100)` |
| NVIDIA T4 | 1 | `min(vcpu_count * 2, 32)` |
| NVIDIA T4 | 2 | `min(vcpu_count * 2, 50)` |
| NVIDIA T4 | 4 | `min(vcpu_count * 2, 100)` |
## MTU settings and GPU machine types
To increase network throughput, set a higher
[maximum transmission unit (MTU)](https://docs.cloud.google.com/vpc/docs/mtu) value for your
VPC networks. Higher MTU values increase the packet size and
reduce the packet-header overhead, which in turn increases payload data throughput.
For GPU machine types, we recommend the
following MTU settings for your VPC networks.
| [GPU machine type](https://docs.cloud.google.com/compute/docs/gpus) | Recommended MTU (in bytes) ||
| | Regular VPC network | RoCE VPC network |
|---|---|---|
| - A5X - A4X Max - A4X - A4 - A3 Ultra | 8896 | 8896 |
| - A3 Mega - A3 High - A3 Edge | 8244 | N/A |
| - A2 Standard - A2 Ultra - G4 - G2 - N1 machine types that support GPUs | 8896 | N/A |
When setting the MTU value, note the following:
- 8192 is two 4 KB pages.
- 8244 is recommended in A3 Mega, A3 High, and A3 Edge VMs for GPU NICs that have header split enabled.
- Use a value of 8896 unless otherwise indicated in the table.
## Create high bandwidth GPU machines
To create GPU instances that use higher network bandwidths, use one of the
following methods based on the machine type:
- To create *A2, G2 and N1* instances that use higher network bandwidths, see
[Use higher network bandwidth for A2, G2, and N1 instances](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus#overview).
To test or verify the bandwidth speed for these machines, you can use the
benchmarking test. For more information, see
[Checking network bandwidth](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus#check-bandwidth).
- To create *A3 Mega* instances that use higher network bandwidths, see
[Deploy an A3 Mega Slurm cluster for ML training](https://docs.cloud.google.com/cluster-toolkit/docs/deploy/slurm/deploy-a3-mega-cluster).
To test or verify the bandwidth speed for these machines, use a
benchmarking test by following the steps in
[Checking network bandwidth](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus#check-bandwidth).
- For *A3 High and A3 Edge* instances that use higher network bandwidths, see
[Create an A3 VM with GPUDirect-TCPX enabled](https://docs.cloud.google.com/compute/docs/gpus/gpudirect).
To test or verify the bandwidth speed for these machines, you can use the
benchmarking test. For more information, see
[Checking network bandwidth](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus#check-bandwidth).
- For other accelerator-optimized machine types, no action is required to use
higher network bandwidth; creating an instance as documented already uses
high network bandwidth. To learn how to create instances for other
accelerator-optimized machine types, see
[Create a VM that has attached GPUs](https://docs.cloud.google.com/compute/docs/gpus/create-vm-with-gpus#create_a_vm_that_has_attached_gpus).
## What's next?
- Learn more about [GPU platforms](https://docs.cloud.google.com/compute/docs/gpus).
- Learn how to [create instances with attached GPUs](https://docs.cloud.google.com/compute/docs/gpus/create-vm-with-gpus).
- Learn about [Use higher network bandwidth](https://docs.cloud.google.com/compute/docs/gpus/optimize-gpus).
- Learn about [GPU pricing](https://cloud.google.com/compute/gpus-pricing).