# Manage data processing pipelines
Supported in:
> [!NOTE]
> **Note:** This feature is covered by [Pre-GA Offerings Terms](https://chronicle.security/legal/service-terms/) of the Google Security Operations Service Specific Terms. Pre-GA features might have limited support, and changes to pre-GA features might not be compatible with other pre-GA versions. For more information, see the [Google SecOps Technical Support Service guidelines](https://chronicle.security/legal/technical-support-services-guidelines/) and the [Google SecOps Service Specific Terms](https://chronicle.security/legal/service-terms/).
> If this feature isn't visible in your environment, see [Manage preview features](https://docs.cloud.google.com/chronicle/docs/secops/preview-features-manage) or contact your system administrator.
> [!CAUTION]
> **Caution:** The Ingestion API is [deprecated](https://docs.cloud.google.com/chronicle/docs/deprecations) and will be discontinued on July 20, 2027. To ingest logs into Google SecOps, use the [Chronicle API](https://docs.cloud.google.com/chronicle/docs/reference/ingestion-methods) instead. For details on how to migrate, see [Migrate from legacy SIEM API to Chronicle API](https://docs.cloud.google.com/chronicle/docs/administration/migrate-from-legacy-api-to-chronicle-api).
This document helps security engineers set up and manage data
processing pipelines in Google SecOps to filter events, transform
fields, or redact sensitive values before ingestion. This feature provides robust, pre-parsing control over the data ingestion process. By
following the recommended methods in this guide, you can optimize data compatibility, reduce
costs, and protect sensitive information within Google SecOps.
> [!NOTE]
> **Note:** This feature is available for Google SecOps Enterprise and Enterprise plus users only.
Data processing simplifies log management through the following core actions:
- **Filter**: Reduce noise and costs by ingesting only relevant events.
- **Transform**: Modify data formats, parse fields, and enrich logs for better usability.
- **Redact**: Protect sensitive information by masking or removing sensitive values before storage.
The following diagram illustrates how your data flows into Google SecOps and how the system processes that data:
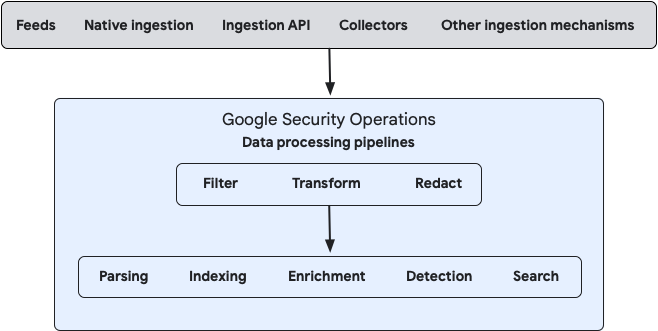
You can configure data processing for both on-premises and cloud data
streams using either the Bindplane management console or by using the
public [Google SecOps Data Pipeline APIs](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#using_secops_data_pipeline_apis) directly.
## Common use cases
Example use cases for data processing include the following:
- Remove empty key-value pairs from raw logs.
- Redact sensitive data.
- Add ingestion labels from raw log content.
- In multi-instance environments, apply ingestion labels to direct-ingestion log data to identify the source stream instance (such as Google Cloud Workspace).
- Filter Palo Alto Cortex data by field values.
- Reduce SentinelOne data by category.
- Extract host information from feeds and direct-ingestion logs and map it to the `ingestion_source` field for Cloud Monitoring.
## Key terminology
Data processing uses the following elements:
- **Streams**: A specific flow of data, defined by log type and ingestion source (like a feed or API), that serves as the input to a data processing pipeline.
- **Processor node**: A component within a pipeline that contains one or more processors, such as filter, transform, or redact actions. These processors manipulate data sequentially as it passes through the node.
- **Destination**: The endpoint of the data processing pipeline, typically the Google SecOps instance where processed data is sent for final ingestion and analysis.
## Before you begin
Before you begin setting up data processing pipelines, review the following requirements:
- **Parser and UDM impact** : Data processing pipelines modify raw log data *before* it reaches Google SecOps parsers. These modifications can affect how parsers interpret logs and convert them into the [Unified Data Model (UDM)](https://docs.cloud.google.com/chronicle/docs/event-processing/udm-overview) format. Before activating a pipeline for a feed or log type, verify that your filtering, transformation, or redaction rules don't unintentionally alter data in a way that prevents parsers from generating correct UDM events.
- **API support** : Data processing is supported for push-based streams by calling the [Chronicle API](https://docs.cloud.google.com/chronicle/docs/reference/ingestion-methods). Filters configured in the Data Processing Manager (DPM) are applied after data has been received by the Chronicle Ingestion API. Consequently, these filters don't prevent customers from hitting Ingestion API quotas and limits, such as importPushLog API limits, because these limits are evaluated before DPM filtering occurs. To effectively manage and stay within Ingestion API limits, customers should implement filtering at the data source itself rather than relying on DPM filters.
> [!NOTE]
> **Note:** Data processing pipelines are only applicable for logs ingested using the [modern Chronicle API](https://docs.cloud.google.com/chronicle/docs/reference/ingestion-methods). Logs ingested using legacy ingestion APIs do not flow through data processing pipelines.
- **Data visibility** : Data ingested from forwarders and Bindplane is tagged with a distinct `collectorID` from direct ingestion streams. To support full log visibility, you must either select all ingestion methods when querying data sources or explicitly reference the relevant `collectorID` when interacting with the API.
- **Bindplane console setup**: If you plan to use the Bindplane console for setup and management, complete the following steps:
1. In the Google SecOps console, grant one of the following roles to the user or service account which you will use to configure the Bindplane integration:
- **A custom role with the following permissions:**
- `chronicle.logProcessingPipelines.associateStreams`
- `chronicle.logProcessingPipelines.create`
- `chronicle.logProcessingPipelines.delete`
- `chronicle.logProcessingPipelines.dissociateStreams`
- `chronicle.logProcessingPipelines.fetchAssociatedPipeline`
- `chronicle.logProcessingPipelines.fetchSampleLogsByStreams`
- `chronicle.logProcessingPipelines.get`
- `chronicle.logProcessingPipelines.list`
- `chronicle.logProcessingPipelines.testPipeline`
- `chronicle.logProcessingPipelines.update`
- `chronicle.logTypes.get`
- `chronicle.logTypes.list`
- `chronicle.feeds.get`
- `chronicle.feeds.list`
- `chronicle.logs.list`
- `chronicle.parsers.list`: This permission is required only if you use Bindplane's [Validate SecOps Parser](https://docs.bindplane.com/feature-guides/pipeline-intelligence/inspect-telemetry#validate-secops-parser) action.
- `chronicle.parsers.runParser`: This permission is required only if you use Bindplane's [Validate SecOps Parser](https://docs.bindplane.com/feature-guides/pipeline-intelligence/inspect-telemetry#validate-secops-parser) action.
We recommend using a custom role with the specified required permissions.
For more information, see [Create and manage custom roles](https://docs.cloud.google.com/iam/docs/creating-custom-roles) and [Configure feature access control using IAM](https://docs.cloud.google.com/chronicle/docs/onboard/configure-feature-access).
- **The predefined Chronicle API Admin `roles/chronicle.admin` role**.
For details, see [Assign the Project IAM Admin role in a dedicated project](https://docs.cloud.google.com/chronicle/docs/onboard/configure-feature-access#project-iam-dedicated).
2. Install the Bindplane Server console. For SaaS or on-premises, see [Install the Bindplane Server console](https://docs.cloud.google.com/chronicle/docs/ingestion/use-bindplane-agent#bp-console).
Ensure that you install the latest version of Bindplane (or Bindplane version 1.96.4 or later).
3. In the Bindplane console, connect a Google SecOps destination instance to your *Bindplane project* . For details, see [Connect to a Google SecOps instance](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#connect_to_a_google_secops_instance).
## Connect to a Google SecOps instance
> [!NOTE]
> **Note:** To use the Google SecOps data processing feature, you must install the latest version of Bindplane (or Bindplane version 1.96.4 or later).
Before you begin, confirm that you have the Bindplane
[project administrator permissions](https://docs.bindplane.com/feature-guides/role-based-access-control-rbac#project-roles) to access the **Project Integrations** page.
The Google SecOps instance serves as the destination for your data output.
To connect to a Google SecOps instance using the Bindplane Server console, do the following:
1. In the Bindplane Server console, click **Menu** and select **Project Settings**.
2. On the **Project Settings** page, go to the **Integrations** card and click **Connect to Google SecOps** to open the **Edit Integration** window.
3. Enter the details for the Google SecOps destination instance.
This instance ingests the processed data (output from your data processing), as follows:
| **Field** | **Description** |
|---|---|
| **Region** | Region of your Google SecOps instance. To find the instance in the Google Cloud console, go to **Security \> Detections and Controls \> Google Security Operations** \> **Instance details**. |
| **Customer ID** | Customer ID of your Google SecOps instance.
In the Google SecOps console, go to **Settings \> Administration \> Profile \> Organization details**. |
| **Google Cloud project number** | Google Cloud project number of your Google SecOps instance. To find the project number in the Google SecOps console, go to **Settings \> Administration \> Profile \> Organization details**. |
| **Credentials** | Service Account credentials are the JSON value required to authenticate and access the Google SecOps Data Pipeline APIs. Get this JSON value from the Google Service Account credential file. The Service Account must be located in the same Google Cloud project as your Google SecOps instance and requires either the Chronicle API Admin role (`roles/chronicle.admin`) privileges or a custom role with the required permissions (see [Prerequisites](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#prerequisites)). For information about how to create a Service Account and download the JSON file, see [Create and delete Service Account keys](https://docs.cloud.google.com/iam/docs/keys-create-delete). Alternatively, Bindplane Cloud deployments support Workload Identity Federation (WIF) for authentication. WIF is not supported in self-hosted Bindplane deployments. For more information, see [Connect the Google SecOps Integration with WIF Auth](https://docs.bindplane.com/how-to-guides/google-secops/connect-the-google-secops-integration-with-wif-auth). |
4. Click **Connect**. If your connection details are correct and you
successfully connect to Google SecOps, you can expect the
following:
- A connection to the Google SecOps instance opens.
- The first time you connect, the **SecOps Pipelines** tab appears in the **Bindplane console**.
- The Bindplane console displays any processed data you previously set up for this instance using the API. The system converts some processors you configured using the API into Bindplane processors, and displays others in their raw OpenTelemetry Transformation Language (OTTL) format. You can use the Bindplane console to edit pipelines and processors previously set up using the API.
5. After you successfully create a connection to a Google SecOps instance, you are ready to set up data processing.
## Set up data processing using the Bindplane console
This section describes how to provision and deploy a new log processing pipeline in Google SecOps using the Bindplane console. You can also use the Bindplane console to manage pipelines previously set up using the API.
### Create a new Google SecOps pipeline
A Google SecOps pipeline is a container for you to configure one data processing container. To create a new Google SecOps pipeline container, do the following:
1. In the **Bindplane console** , click the **SecOps Pipelines** tab to open the **SecOps Pipelines** page.
2. Click **Create SecOps Pipeline**.
3. Enter a **SecOps Pipeline name** and **Description**.
> [!IMPORTANT]
> **Important:** You can't change the name of a Google SecOps pipeline after you create it.
4. Click **Create** . You can see the new pipeline container on the **SecOps Pipelines** page.
5. Configure the data processing container streams and processors within this container.
### Configure a data processing container
A data processing container defines the [*streams*](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#key_terminology) to be ingested and the [*processors*](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#key_terminology) to be applied before the data reaches the [*Destination*](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#key_terminology).
Configure the streams and processor nodes on the *pipeline* configuration card.
To configure a data processing container, do the following:
1. If you haven't already, [create a new Google SecOps pipeline](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#create_a_new_SecOps_Pipeline).
2. In the **Bindplane console** , click the **SecOps Pipelines** tab to open the **SecOps Pipelines** page.
3. Select the Google SecOps pipeline where you want to configure the new data processing container.
4. On the **Pipeline** configuration card:
1. [Add a stream](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#configure_streams).
2. Configure the **processor node** . To add a processor using the Bindplane console, see [Configure processors](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#configure-processors) for details.
> [!NOTE]
> **Note:** Some custom processors let you edit their raw OTTL code directly.
5. Once these configurations are complete, see [Roll out data processing](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#roll-out-data-process-pipe) to begin processing the data.
#### Add a stream
To add a stream, do the following:
1. In the **Pipeline** configuration card, click add **Add Stream** to open the **Add Stream** window.
2. In the **Add Stream** window, enter details for these fields:
| **Field** | **Description** |
|---|---|
| **Log type** | Select the **log type** of the data to ingest. For example, `CrowdStrike Falcon (CS_EDR)`. Note: A warning **Warning** icon indicates that the log type is already configured in another stream (either in this pipeline or another pipeline in your Google SecOps instance). To use an unavailable log type, you must first delete it from the other stream configuration. For instructions on how to find the stream configuration where the log type is configured, see [Filter SecOps pipeline configurations](https://docs.cloud.google.com/chronicle/docs/ingestion/data-processing-pipeline#filter_secops_pipeline_configurations). |
| **Ingestion method** | Select the **ingestion method** to use to ingest the data for the selected **log type** . These ingestion methods were previously defined for your Google SecOps instance. You must select one of the following options: - **All Ingestion Methods** : Includes all ingestion methods for the selected log type. When you select this option, it prevents you from adding subsequent streams that use specific ingestion methods for that same log type. **Exception** : You can select other unconfigured specific ingestion methods for this log type in other streams. - ***Specific*** ingestion method, such as `Cloud Native Ingestion`, `Feed`, `Modern Chronicle Ingestion API`, or `Workspace Ingestion`. |
| **Feed** | If you select `Feed` as the ingestion method, a subsequent field appears with a list of available feeds in **Settings \> Data Management \> Feeds** in your Google SecOps instance for the selected log type. You must select the relevant feed to complete the configuration. To view and manage your available feeds, go to **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**. |
3. Click **Add Stream** to save the new stream.The new data stream immediately appears on the **Pipeline** configuration card. The stream is automatically connected to the processor node and the Google SecOps **Destination**.
#### Filter SecOps pipeline configurations
The search bar on the **SecOps Pipelines** page lets you filter and locate your Google SecOps pipelines (data processing containers) based on multiple configuration elements. You can filter pipelines by searching for specific criteria, such as log type, ingestion method, or feed name.
Use the following syntax to filter:
- `logType:value`
- `ingestionMethod:value`
- `feed:value`
For example, to identify stream configurations that contain a specific log type, in the search bar, enter `logtype:` and select the log type from the resulting list.
#### Configure processors
A data processing container has one processor node, which holds one or more processors. Each processor manipulates the stream data sequentially:
1. The first processor processes the raw stream data.
2. The resulting output from the first processor immediately becomes the input for the next processor in the sequence.
3. This sequence continues for all subsequent processors, in the exact order they appear in the **Processors** pane, with the output of one becoming the input of the next.
4. Configure the processor node by adding, removing, or changing the sequence of one or more processors.
> [!NOTE]
> **Note:** When configuring processors, define a maximum of 10 processors per pipeline. Also, avoid excessive regex matching, as this can cause pipeline creation to fail due to long processing times. For a more efficient solution, parse the data to JSON and search for a specific field.
**Requirements when configuring the Unroll processor**
- The Unroll processor cannot operate directly on raw strings. It requires a structured internal object representation, such as parsed JSON, XML, or CSV.
- You must place a corresponding **Transform** processor ahead of the **Unroll** processor in your pipeline to parse the raw log payload before unrolling.
- JSON example: To parse a raw JSON payload string before unrolling array elements, insert a transform processor with the OTTL statement: `set(body, ParseJSON(body))`.
- Other formats: Similar pre-parsing transform steps are required for log data formatted as CSV, XML, or YAML.
> [!NOTE]
> **Note:** The Unroll processor is based on the OpenTelemetry Collector [unrollprocessor](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/processor/unrollprocessor).
The following table lists the processors:
| Processor type | Capability |
|---|---|
| Filter | Filter by condition |
| Filter | Filter by HTTP status |
| Filter | Filter by metric name |
| Filter | Filter by regex |
| Filter | Filter by severity |
| Redaction | Redact sensitive data |
| Transform | Add fields |
| Transform | Coalesce |
| Transform | Concat |
| Transform | Copy field |
| Transform | Delete fields |
| Transform | Marshal |
| Transform | Move field |
| Transform | Parse CSV |
| Transform | Parse JSON |
| Transform | Parse key value |
| Transform | Parse severity fields |
| Transform | Parse timestamp |
| Transform | Parse with regex |
| Transform | Parse XML |
| Transform | Rename fields |
| Transform | Rewrite timestamp |
| Transform | Split |
| Transform | Transform |
| Unroll | Event breaking Breaks a slice of logs into multiple individual log events |
##### Add a processor
To add a processor, follow these steps:
1. In the **Pipeline** configuration card, click the **Processor** node to open the **Edit Processors** window.
The **Edit Processors** window is divided in these panes, arranged by data flow:
- **Input** (or source data): Recent incoming stream log data (before processing)
- **Configuration** (or processor list): Processors and their configurations
- **Output** (or results): Recent outgoing result log data (after processing)
If the pipeline was previously rolled out, the system shows the recent incoming log data (before processing) and the recent outgoing log data (after processing) in the panes.
2. Click **Add Processor** to display the processor list.
For your convenience, the processor list is grouped by processor type. To organize the list and add your own bundles, select one or more processors and click **Add new Processor bundles**.
3. In the processor list, select a **Processor** to add.
4. Configure the processor as required.
5. Click **Save** to save the processor configuration in the **Processor** node.
The system immediately tests the new configuration by processing a fresh sample of the incoming stream data (from the **Input** pane) and displays the resulting outgoing data in the **Output** pane.
### Roll out data processing pipeline
Once the stream and processor configurations are complete, you must roll out the pipeline to begin processing data:
1. Click **Start rollout** . This immediately activates the data processing and lets Google's infrastructure begin processing data according to your configuration. If the rollout is successful, the data processing container's version number is incremented and displayed next to the container's `name`.
## Set up data processing using API methods
As an alternative to the Bindplane console, you can use the [Google SecOps data pipeline methods](https://docs.cloud.google.com/chronicle/docs/reference/rest?rep_location=africa-south1#rest-resource:-v1alpha.projects.locations.instances.logprocessingpipelines) to manage your processed data. These data pipeline methods include creating, updating, deleting, and listing pipelines, and associating feeds and log types with pipelines.
> [!NOTE]
> **Note:** For more detailed Bindplane documentation, see [Google SecOps Pipelines](https://docs.bindplane.com/feature-guides/google-secops-pipelines).
To use the examples in this section, do the following:
- Replace the customer-specific parameters (for example, URLs and feed IDs) with parameters that suit your own environment.
- Insert your own authentication. In this section, the bearer tokens are redacted with `******`.
### List all pipelines in a specific Google SecOps instance
The following command lists all pipelines that exist in a specific Google SecOps instance:
curl --location 'https://abc.def.googleapis.com/v123/'\
'projects/projectabc-byop/locations/us/'\
'instances/aaaa1aa1-111a-11a1-1111-11111a1aa1aa/'\
'logProcessingPipelines' \
--header 'Authorization: Bearer ******'
### Create a basic pipeline with one processor
To create a basic pipeline with a single transform processor that upserts the value for a custom ingestion label, and associate three sources with it, do the following:
1. Run the following command:
curl --location 'https://abc.def.googleapis.com/v123/projects/projectabc-byop/locations/us/instances/aaaa1aa1-111a-11a1-1111-11111a1aa1aa/logProcessingPipelines' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ******' \
--data '{
"displayName": "Example Pipeline",
"description": "My description",
"processors": [
{
"transformProcessor": {
"statements": [
"set(attributes[\"labels.myLabel.value\"], \"myValue\")"
]
}
}
]
}'
2. From the response, copy the value of the `name` field.
3. Run the following command to associate three streams (log type, log type with collector ID, and feed) with the pipeline. Use the value of the `name` field as the `{pipelineName}` value.
curl --location 'https://abc.def.googleapis.com/v123/{pipelineName}:associateStreams' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ******' \
--data '{
"streams": [
{
"logType": "MICROSOFT_SENTINEL"
},
{
"logType": "A10_LOAD_BALANCER",
"collectorId": "dddddddd-dddd-dddd-dddd-dddddddddddd"
},
{
"feed": "1a1a1a1a-1a1a-1a1a-1a1a-1a1a1a1a1a1a"
}
]
}'
### Create a pipeline with three processors
A pipeline uses the following processors:
- **Filter**: Filters out logs that match a condition based on the ingestion labels.
- **Transform**: Upserts the namespace value.
- **Redaction**: Redacts email addresses and social security numbers from log data based on custom regex patterns.
To create a pipeline and associate three sources with it, do the following:
1. Run the following command:
curl --location 'https://abc.def.googleapis.com/v123/projects/projectabc-byop/locations/us/instances/aaaa1aa1-111a-11a1-1111-11111a1aa1aa/logProcessingPipelines' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ******' \
--data-raw '{
"displayName": "My Pipeline 2",
"description": "My description 2",
"processors": [
{
"filterProcessor": {
"logConditions": [
"attributes[\"labels.log_source.value\"] == \"myLogSourceToFilterOut\""
]
}
},
{
"transformProcessor": {
"statements": [
"set(attributes[\"environment_namespace\"], \"myValue\")"
]
}
},
{
"redactProcessor": {
"blockedValues": [
"\\b\\d{3}[- ]\\d{2}[- ]\\d{4}\\b",
"\\b[a-zA-Z0-9._/\\+\\---|]+@[A-Za-z0-9\\---|]+\\.[a-zA-Z|]{2,6}\\b"
],
"allowAllKeys": true
}
}
]
}'
2. From the response, copy the value of the `name` field.
3. Run the following command to associate three streams (log type, log type with collector ID, and feed) with the pipeline. Use the value of the `name` field as the `{pipelineName}` value.
curl --location 'https://abc.def.googleapis.com/v123/{pipelineName}:associateStreams' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ******' \
--data '{
"streams": [
{
"logType": "MICROSOFT_SENTINEL"
},
{
"logType": "A10_LOAD_BALANCER",
"collectorId": "dddddddd-dddd-dddd-dddd-dddddddddddd"
},
{
"feed": "1a1a1a1a-1a1a-1a1a-1a1a-1a1a1a1a1a1a"
}
]
}'
## Troubleshooting
This section outlines performance expectations and provides self-service fixes for common issues.
### Latency and limits
If you configure an agent using the Ingestion API, you might experience longer acknowledgment times for low-volume Google SecOps pipelines.
Latency averages can rise from 700 ms up to 2 seconds. Increase timeout periods and memory as needed. Acknowledgment time drops when data throughput exceeds 4 MB.
### Validation and testing
You can view data processing details from the Google SecOps console:
#### View all data processing configurations
1. In the Google SecOps console, go to **Settings \> Data Management \> Data Processing** where you can view all of your configured pipelines.
2. In the **Incoming Data Pipelines** search bar, search for any pipeline you built. You can search by elements, such as *pipeline name* or *components*. The search results display the pipeline's processors and a summary of its configuration.
3. From the pipeline summary, you can do any of the following actions:
- Review the processor configurations.
- Copy configuration details.
- Click **Open in Bindplane** to access and manage the pipeline directly within the Bindplane console.
#### View configured feeds
To view configured feeds in your system, do the following:
1. In the Google SecOps console, go to **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds** . The **Feeds** page shows all the feeds that you configured in your system.
2. Hold the pointer over each row to display the ⋮ **More** menu, where you can view feed details, edit, disable, or delete the feed.
3. Click **View Details** to view the details window.
4. Click **Open in Bindplane** to open the stream configuration for that feed in the Bindplane console.
#### View data processing details for available log types
To view data processing details on the **Available Log Types** page, where you can view all available log types, do the following:
1. In the Google SecOps console, go to **Settings \> Data Management \> Available Log Types** . If you are on a SIEM-only platform, go to **Settings \> Available Log Types**. The main page displays all your log types.
2. Hold the pointer over each feed row to display the more_vert **More** menu. This menu lets you view, edit, disable, or delete feed details.
3. Click **View Data Processing** to view the feed's configuration.
4. Click **Open in Bindplane** to open the processor configuration for that processor in the Bindplane console.
**Need more help?** [Get answers from Community members and Google SecOps professionals.](https://security.googlecloudcommunity.com/)