# Work with the feeds UI
Supported in:
This document explains how to create, troubleshoot, and manage feeds within the Feed Management UI,
including instructions for modifying, enabling, and deleting them.
## Before you begin
Each data feed requires specific prerequisites before setup in Google Security Operations. To find the requirements for your feed, see [Configuration by source type](https://docs.cloud.google.com/chronicle/docs/reference/feed-management-api.md.txt#source-types) and search for your specific data source. There is no limit on the number of feeds you can create.
### Supported compression formats and file sizes
Supported compression formats for feed ingestion include .gz, .tar.gz, .tar, and solr.gz.
The following table outlines the different file sizes that Google SecOps feeds transformation supports:
| Operation | Input type | Recommended size | Expected duration | Max size |
|---|---|---|---|---|
| Data Modeling | CSV | \< 5 GB | \< 7 min | 10 GB |
| Data Modeling | CSV | \< 5 GB | \~30 min | 10 GB |
| Data Modeling | CSV | TBD | TBD | 2 GB |
| Data Modeling | XML / JSON | \< 1 GB | \< 10 min | 2 GB |
| Data Modeling | XLS / XLSX | \< 50 MB | \~1 min | 50 MB |
| Merge Files | Any | \< 1 GB | Varies on number of files | 100 GB |
| Decompress Files | Non-ZIP | \< 5 GB | Varies on number of files | 10 GB (uncompressed) |
| Decompress Files | ZIP | - | Varies on number of files | 4 GB (uncompressed) |
#### Log line limits and delimiters
When ingesting text-based logs (JSON, CSV, or Syslog), ensure your data adheres
to these specific ingestion limits:
- **Maximum Line Size** : A single log line cannot exceed **4MB** . If a single line exceeds this limit, the feed fails with the error `MaxLogLineSize4MBExceeded`.
- **Supported Delimiters** : Both Newline (`\n`) and Carriage Return + Newline (`\r\n`) are supported.
> [!NOTE]
> **Note:** For log types with high data density, verify that your log source is not grouping multiple events into a single line that exceeds the 4 MB limit. If you encounter size errors, you may need to adjust the source logging configuration to ensure individual entries are properly delimited.
### Impact of changing your linked Cloud Project on data feeds
If you are updating the Google Cloud project associated with your Google SecOps instance, all feeds ingesting data using the following connectors will stop, and must be re-created manually:
- AMAZON_S3_V2
- AMAZON_SQS_V2
- GOOGLE_CLOUD_STORAGE_V2
- AZURE_BLOBSTORE_V2
- GOOGLE_CLOUD_STORAGE_EVENT_DRIVEN
For all other feeds that are not utilizing these connectors, ingestion continues without any interruption. No action needs to be taken by customers.
#### What to expect during migration
For impacted feeds, you will observe the following changes:
- **Feed status**: Feeds created prior to the migration will immediately stop pulling live data and will become read-only.
- **Existing data**: Any data that was already transferred to Google SecOps before the migration will be ingested automatically; no data will be lost.
- **Error messages** : If you attempt to edit or delete an older feed, you will receive a message stating: `This feed is read-only because this SecOps has now moved to a new Google Cloud Project (BYOP). To continue ingesting data from this source, please create a new feed`.
#### Required actions for customers
To ensure continuous data ingestion, you must manually re-create your feeds in the new environment. Follow these steps to minimize disruption:
1. **Re-create feeds**: You must create new feeds to replace the ones that existed pre-migration.
2. **Configure Max File Age** : When setting up your new feeds, set the **Max File Age** to around 2 hours before the BYOP update was initiated. This time buffer ensures a smooth transition.
3. **Manage duplicate data** : Depending on the **Max File Age** you select, you may experience some duplicate data transfer. For technical details on how Google SecOps filters these redundant logs, see [Prevent deduplication](https://docs.cloud.google.com/chronicle/docs/reference/feed-management-api.md.txt#prevent_deduplication).
> [!NOTE]
> **Note:** This does not apply to feeds where the **Delete after Transfer** option is enabled.
4. **Record and delete existing feeds (before migration)** : Before you begin the
BYOP migration, record the configuration settings for all existing feeds that
use the [impacted connectors](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#impact_of_changing_your_linked_cloud_project_on_data_feeds) (for example, Amazon S3 V2),
and then delete the feeds. If you don't delete feeds created before migration,
they become unmanageable and remain in the Google SecOps web
interface as orphaned settings.
### Ways to set up feeds
There are two ways for Google SecOps customers to set up a feed in the platform. Use the method that works best for your environment:
- **Settings \> Data Management \> Feeds** (standard)
- **Content Hub \> Content Packs** (premium)
> [!NOTE]
> **Note:** If you're using the SIEM standalone platform, you won't have access to the Content Hub. Contact your Google SecOps representative to upgrade.
### Set up IP allowlisting
When Google SecOps pulls data from S3, SQS, Azure, and third-party APIs, the Google infrastructure connects outbound to the customer's bucket or the third-party API.
For ingress allowlisting on your storage buckets or firewalls, you must configure allowlisting according to the feed type, as described in the following list:
- **V2 feeds (S3_V2, SQS_V2, Azure_Blobstore_V2)** : These feeds exclusively use Google Cloud Storage Transfer Service (STS) to pull data from customer storage. They require allowlisting the STS IP ranges: [ipranges.json](https://www.gstatic.com/storage-transfer-service/ipranges.json).
- **Third-party APIs** : Require [goog.json](https://www.gstatic.com/ipranges/goog.json).
- **Legacy feeds (S3, Azure_Blobstore)** : Require dedicated IP ranges. For more information, contact [Google SecOps support](https://docs.cloud.google.com/chronicle/docs/getting-support.md.txt).
- **Azure Event Hub** : Requires region-specific IP ranges. For more information, see [Configure network security (optional) in *Create an Azure Event Hub feed*](https://docs.cloud.google.com/chronicle/docs/administration/create-azure-feed.md.txt#network-security).
> [!NOTE]
> **Note:** Google SecOps can't guarantee that all feeds will exclusively originate from IP addresses according to a specified region.
Because Google Services IP ranges change dynamically, Google recommends that you configure your firewall to periodically fetch and parse the feeds as follows:
- **V2 feeds (S3_V2, SQS_V2, Azure_Blobstore_V2)** : Data transfer is executed exclusively by Storage Transfer Service workers. You only need to periodically fetch and parse [ipranges.json](https://www.gstatic.com/storage-transfer-service/ipranges.json).
- **Legacy feeds (S3, SQS, Azure_Blobstore, Azure Event Hub) and third-party APIs** : These connections originate from the Google infrastructure. You only need to periodically fetch and parse [goog.json](https://www.gstatic.com/ipranges/goog.json) and [cloud.json](https://www.gstatic.com/ipranges/cloud.json).
## Configure your feeds
This section describes how to *generally* configure your feeds, starting with the standard procedural flow. The data feeds listed on the **Feeds** page include all the feeds that Google has configured for your account, including the feeds that you configured.
### Add a feed
> [!CAUTION]
> **Caution:** As of **April 15, 2026** , the v1 connector framework for Cloud Storage, Amazon S3, Amazon SQS, and Azure Blob Storage is deprecated. We recommend using the v2 connector framework, which uses the Google Cloud Storage Transfer Service (STS) for near real-time ingestion. For more information, see [Upgrade cloud storage data feeds to the v2 connector framework](https://docs.cloud.google.com/chronicle/docs/administration/upgrade-data-feeds-v2.md.txt) and [Feature deprecations](https://docs.cloud.google.com/chronicle/docs/deprecations.md.txt).
To add a feed to your Google SecOps account, complete the following steps:
1. In the Google SecOps menu, select **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**.
2. Click **Add New Feed**.
3. On the next page, click **Configure a single feed**. Note: This step is not relevant for customers who use the Google SecOps SIEM standalone platform.
4. Add a feed name.
5. In the **Source type** list, select the source type for importing data into Google SecOps.
You can select from the following feed source types:
- **Amazon Data Firehose**
- **Amazon S3 (Deprecated)**
- **Amazon S3 (V2)**
- **Amazon SQS (Deprecated)**
- **Amazon SQS (V2)**
- **Azure Blob Storage (Deprecated)**
- **Azure Blob Storage (V2)**
- **Custom API**
- **Google Cloud Pub/Sub**
- **Cloud Storage (Deprecated)**
- **Cloud Storage (V2)**
- **Cloud Storage Event Driven**
- **Third party API**
- **Webhook**
**Important:**
- When using Amazon S3 (Deprecated), Amazon SQS (Deprecated), Azure Blob Storage (Deprecated), and Google Cloud Cloud Storage (Deprecated) feeds, make sure that you have a valid directory path.
- When using Amazon SQS (Deprecated) or Amazon SQS (V2), explicitly grant Google SecOps permissions to delete messages from the Amazon SQS queue.
- When using Amazon SQS (Deprecated) feeds, make sure only one feed consumes messages from the queue. Messages read by another application or feed don't get ingested into the current feed.
- For information about upstream API indexing latency in third-party API polling feeds, see [Late-arriving events in polling feeds](https://docs.cloud.google.com/chronicle/docs/reference/feed-management-api.md.txt#late-arriving-events-polling).
- Using Amazon SQS (Deprecated) as the feed source type is only supported for logs in Amazon S3 buckets.
6. In the **Log type** list, select the log type that corresponds to the logs you want to ingest. The available logs vary depending on the source type you selected earlier.
> [!NOTE]
> **Note:** For the `AWS CLOUDTRAIL` log type, verify that the logs are in JSON format and the filename is a JSON file (uncompressed) or a JSON GZipped file (compressed).
If you select **Cloud Storage** as the source type, use the **Get service account**
option to get a unique service account. See [Google Cloud Storage feed setup example](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#storage-example).
7. Click **Next**.
8. Specify the parameters needed from the **Input Parameters** tab. The options presented here vary depending on the source and log type selected on the **Set Properties** tab.
Hold the pointer over the question icon for each field to get additional information on what you need to provide.
9. Optional: You can specify a namespace in the **Set Properties** tab.
For more information about namespaces, see [Work with asset namespaces](https://docs.cloud.google.com/chronicle/docs/investigation/asset-namespaces.md.txt).
10. Click **Next**.
11. Review your new feed configuration on the **Finalize** tab.
12. Click **Submit**. Google SecOps completes a validation check of the new feed. If the feed passes the check, a name is generated for the feed, it's submitted to Google SecOps, and Google SecOps begins to attempt to fetch data.
### Configure multiple feeds for a product family (Google SecOps customers only)
You can configure multiple feeds per product family, based on log type.
- **Baseline log types** : Marked as **recommended**. These log types are recommended for core platform functionality.
- **Supplementary log types** : Marked as **optional**. These log types provide additional context.
To simplify the setup, the platform provides specific setup instructions and predefined parameters for each configuration.
For example, for CrowdStrike Falcon, you can create multiple unique feeds under both **recommended** and **optional** log types to make sure there's enough comprehensive data coverage.
### Configure the feed for CrowdStrike EDR
Follow these steps to configure a log feed for CrowdStrike EDR.
1. **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds** .
1. Click **Add New Feed**.
2. Click the **CrowdStrike Falcon** product:.
3. Select **CrowdStrike EDR** log type.
2. Alternatively, from **Content Hub \> Content Packs** , click the **CrowdStrike Falcon** product:
1. Click **Get Started**.
2. Select **CrowdStrike EDR** log type.
3. Specify values for the following fields:
| Field | Description |
|---|---|
| `Source Type` | Amazon SQS |
| `Region` | The AWS S3 region associated with the URI. |
| `Queue Name` | The SQS queue name to read from. |
| `Account Number` | The SQS account number. |
| `Source Deletion Option` | Indicates whether to delete files and directories after the transfer. |
| `Queue Access Key ID` | A 20-character alphanumeric access key for the account, such as `AKIAOSFOODNN7EXAMPLE`. |
| `Queue Secret Access Key` | A 40-character alphanumeric secret access key for the account, such as, `wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY`. |
4. Optional: Configure the following parameters:
- Feed Name: prepopulated unique name for the feed.
- Asset namespace: namespace associated with the feed.
- Ingestion labels: labels applied to the events from this feed.
5. Click **Create Feed**.
You can repeat this process to create additional feeds for the same log type. You can also configure feeds for other available log types directly from this page. When finished, go to the **Feed Management** page to view a detailed summary of all configured log types.
### Delete source files
The **source deletion option** lets you delete feed source objects (files and
folders) from storage, after a successful transfer. This option is only
available for selected feed source types, including
Cloud Storage. These feed source types include the **SOURCE DELETION OPTION**
field in their **Add new** and **Edit feed** workflows.
> [!NOTE]
> **Note:** When you configure the **SOURCE DELETION OPTION** field, if you select an option to delete source objects, you must enable the required deletion permissions for that feed type. For information about permissions, see [Configuration by source type](https://docs.cloud.google.com/chronicle/docs/reference/feed-management-api.md.txt#source-types).
#### Source deletion options
- For supported feed source types, including Cloud Storage, the **SOURCE DELETION
OPTION** field offers these options:
- **Never delete files**
- **Delete transferred files and empty directories**
- **Delete transferred files**
- Microsoft Azure Blob Storage (AZURE_BLOBSTORE) doesn't support deletion of
source files. For the **SOURCE DELETION OPTION** field, only select
the **Never delete files** option.
- For the following feed sources (`"feedSourceType"`):
`GOOGLE_CLOUD_STORAGE_V2`, `GOOGLE_CLOUD_STORAGE_EVENT_DRIVEN`,
`AMAZON_S3_V2`, `AMAZON_SQS_V2`, and `AZURE_BLOBSTORE_V2`, the
**SOURCE DELETION OPTION** field offers two options:
- **NEVER**: Never deletes any files after transfers.
- **ON_SUCCESS**: Deletes all files and empty directories after transfer.
### Filter objects by prefix in STS feeds
> [!NOTE]
> **Note:** Prefix-based filtering using the **Include prefixes** (`include_prefixes`) field is in Limited Preview and requires your tenant to be on the allowlist. To enable this feature (`enable_feed_include_prefixes`) for your tenant, contact your Google Cloud account team, Technical Account Manager (TAM), or [Cloud Customer Care](https://cloud.google.com/support-hub). If your tenant isn't on the allowlist, saving a feed with prefixes returns an error. For details, see [Error: `Generic::failed_precondition: include_prefixes is not enabled for this customer`](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#error-include-prefixes-not-enabled).
The **Include prefixes** (`include_prefixes`) field filters storage objects transferred by Storage Transfer Service (STS) before ingestion based on object key prefixes. Values that you specify in this field are passed directly to STS [`ObjectConditions.include_prefixes`](https://docs.cloud.google.com/storage-transfer/docs/reference/rest/v1/TransferSpec.md.txt#ObjectConditions).
#### Supported STS feed source types
Prefix-based filtering is supported for the following STS feed source types (`feedSourceType`):
- **Cloud Storage (V2)** (`GOOGLE_CLOUD_STORAGE_V2`) and **Cloud Storage Event Driven** (`GOOGLE_CLOUD_STORAGE_EVENT_DRIVEN`)
- **Amazon S3 (V2)** (`AMAZON_S3_V2`) and **Amazon SQS (V2)** (`AMAZON_SQS_V2`)
- **Azure Blob Storage (V2)** (`AZURE_BLOBSTORE_V2`) and **Azure Blob Storage Event Driven** (`AZURE_BLOBSTORE_EVENT_DRIVEN`)
#### Prefix syntax and validation rules
When you configure **Include prefixes** (`include_prefixes`), follow these syntax and validation rules:
- **No leading slashes** : Prefixes are relative to the bucket or container root and must not start with a leading slash (`/`). For example, enter `logs/audit/` instead of `/logs/audit/`.
- **Trailing slashes versus partial matching** : Trailing slashes control whether a prefix matches only objects in a specific folder or any object key that starts with the prefix:
- **With a trailing slash** : A prefix ending with `/` (for example, `logs/app/`) restricts matches strictly to objects inside that folder. Include a trailing slash for directory-level scoping.
- **Without a trailing slash** : A prefix without a trailing `/` (for example, `logs/app`) matches any object starting with that string, including `logs/app_old/` and `logs/application/`.
- **Case sensitivity**: Object key prefixes are strictly case-sensitive.
- **No wildcards or regular expressions** : Pattern matching isn't supported. Characters such as `*` and `?` are treated as literal characters.
- **No empty values** : Individual prefix entries can't be empty or contain only whitespace. To ingest the entire bucket or container, leave the **Include prefixes** field blank.
- **Distinct, non-overlapping namespaces** : A prefix can't be a prefix of another prefix in the same list. For example, `["logs/", "logs/audit/"]` is invalid, whereas sibling prefixes such as `["logs/audit/", "logs/vpc/"]` are valid.
- **Limits** : A feed supports up to 1,000 prefixes. Each prefix can have a maximum length of 1,024 bytes when UTF-8 encoded and can't contain carriage return (`\r`) or newline (`\n`) characters.
## Source-specific setup and permissions
Different source types require specific authentication and networking configurations to communicate with Google SecOps. This section describes how to configure permissions and set up service accounts. The setup outlined focuses on Cloud Storage ingestion (pull based), multi-cloud ingestion (cross-cloud pull), and push-based ingestion (API or real-time).
> [!NOTE]
> **Note:** If you use VPC Service Controls see [Configure VPC Service Controls for Google SecOps](https://docs.cloud.google.com/chronicle/docs/secops/vpcsc-for-secops.md.txt) for more information (includes details for configuring rules for Cloud Storage-based V2 feeds).
### Google Cloud Storage feed setup example
> [!NOTE]
> **Note:** If you use the [Domain Restricted Sharing](https://docs.cloud.google.com/resource-manager/docs/organization-policy/restricting-domains) organization policy in Google Cloud, make sure you add the Google SecOps customer ID `C02h8e9nw` to the allowlist.
1. From the Google SecOps menu, select **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**.
2. Click **Add New Feed**.
3. On the next page, click **Configure a single feed**. This step doesn't apply if you are using the SIEM-only platform.
4. Select **Cloud Storage v2** for **Source Type**.
5. Select the **Log type** . For example, to create a feed for Google Kubernetes Engine audit logs, select **Google Kubernetes Engine audit logs** as the **Log Type**.
6. Click **Get service account** . Google SecOps provides a unique service account that Google SecOps uses to ingest data. Alternatively, you can get this service account programmatically using the API. See [Fetch service account](https://docs.cloud.google.com/chronicle/docs/reference/feed-management-api.md.txt#fetch-sa).
7. Optional: Configure the service account. For more information, see [Grant access to the Google SecOps service account](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#grant-sa-access).
8. Click **Next**.
9. Based on the Cloud Storage configuration that you created, specify values for the following fields:
- **Storage bucket URI**
> [!NOTE]
> **Note:** Use a wildcard to match an entire directory name. For example, `gs://cs-myprod/*/more-data` is valid (where `*` replaces the entire name of a single directory level).
> [!NOTE]
> **Note:** For Cloud Storage Event Driven feed types, set up a Pub/Sub subscription for Cloud Storage, as described in [Configure Pub/Sub](https://docs.cloud.google.com/storage-transfer/docs/event-driven-google.md.txt#configure_pub_sub).
- **Source deletion option**
- Optional: **Include prefixes** (optional). This is currently in Limited Preview. For syntax rules and allowlist details, see [Filter objects by prefix in STS feeds](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#include-prefixes).
To learn more about how to set up Cloud Storage buckets, see
[Create Buckets](https://docs.cloud.google.com/storage/docs/creating-buckets.md.txt).
> [!NOTE]
> **Note:** Cloud Storage bucket feeds don't work with empty folder names.
10. Click **Next** and then click **Submit**.
### Grant access to the Google SecOps service account
1. In the Google Cloud console, go to the Cloud Storage **Buckets** page.
[Go to Buckets](https://console.cloud.google.com/storage/browser)
2. Grant access to the service account to the relevant Cloud Storage objects.
- To grant read permission to a *specific file*, complete the following steps:
1. Select the file and click **Edit access**.
2. Click **Add principal**.
3. In the **New principals** field, enter the name of the Google SecOps service account.
4. Assign a role that contains the read permission to the Google SecOps service account. For example, **Storage Object Viewer** (`roles/storage.objectViewer`). This can only be done if you've not enabled [uniform bucket-level access](https://docs.cloud.google.com/storage/docs/uniform-bucket-level-access.md.txt).
5. Click **Save**.
- To grant read permission to *multiple files*, grant access at the bucket level as follows:
- For `"feedSourceType": "GOOGLE_CLOUD_STORAGE"`:
1. Add the Google SecOps service account as a principal to your storage bucket and grant it the IAM **Storage Object
Viewer** (`roles/storage.objectViewer`) role.
2. If you configure the feed to delete source files, you must add the Google SecOps service account as a principal on your bucket and grant it the IAM **Storage Object Admin** (`roles/storage.objectAdmin`) role.
- For `"feedSourceType": "GOOGLE_CLOUD_STORAGE_V2"`, grant the following roles:
1. Grant this role:
- **Storage Object Viewer** (`roles/storage.objectViewer`) if the transfer is to another Cloud Storage bucket.
2. Grant *one* of the following roles, depending on what you select for the [Source Deletion Option](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#delete_source_files). If you select **On Success** , grant the **Storage Legacy Bucket Writer** role. If you select **Never** , grant the **Storage Legacy Bucket Reader** role:
- **Storage Legacy Bucket Writer** (`roles/storage.legacyBucketWriter`) if object delete permission is required.
- **Storage Legacy Bucket Reader** (`roles/storage.legacyBucketReader`) if object delete permission is not required.
- For `"feedSourceType": "GOOGLE_CLOUD_STORAGE_EVENT_DRIVEN"`:
1. Grant either of these roles:
- **Storage Object Viewer** (`roles/storage.objectViewer`) if the transfer is to another Cloud Storage bucket.
- **Storage Object Creator** (`roles/storage.objectCreator`) if the transfer is to a file system.
2. Grant either of these roles:
- **Storage Legacy Bucket Writer** (`roles/storage.legacyBucketWriter`) if object delete permission is required.
- **Storage Legacy Bucket Reader** (`roles/storage.legacyBucketReader`) if object delete permission is not required.
## Enable STS access for Amazon S3 and Azure Storage
The STS is used by the following Google Cloud Storage
feeds to transfer data from Amazon S3 and Azure Storage blobstores to
Google SecOps:
- **Amazon S3 (V2)**
- **Amazon SQS (V2)**
- **Azure Blob Storage (V2)**
STS sends data transfer requests to the Amazon S3 and Azure storage services
from a set of defined STS IP address ranges. These STS IP address ranges are
published in the following JSON file:
[IP ranges](https://www.gstatic.com/storage-transfer-service/ipranges.json).
To use these STS feed source types, you may need to adjust IP access restrictions to enable STS to access your
Amazon S3 and Azure storage services:
1. Pull the latest IP ranges from the JSON file.
We recommend reading data from this JSON file at least weekly to keep your
security configuration up to date. When a new range is added to the file, the
system waits at least 7 days before using that range for requests from STS.
For a sample Python script that fetches IP ranges from a JSON file, see [IP addresses for default domains](https://docs.cloud.google.com/vpc/docs/configure-private-google-access.md.txt#ip-addr-defaults).
2. Compare the current IP range `creationTime` to the IP range `creationTime`
read from the previous JSON file. If these differ, update the IP access
restrictions in Amazon S3 and Azure Storage blobstores.
- For **Amazon S3**
To update the IP access restrictions in your Amazon S3 blobstore:
If your AWS project uses IP restrictions for access to storage, you must add
the IP ranges used by STS workers to your list of allowed IPs.
> [!NOTE]
> **Note:** If you're using agents instead of an agentless transfer, add your agent machine IP address(es) to your list of allowed IPs instead.
To add these ranges as allowed IPs, use the `Condition` field in a `bucket policy`, as described in the AWS S3 documentation: [Managing access based on specific IP addresses](https://docs.aws.amazon.com/AmazonS3/latest/userguide/example-bucket-policies.html#example-bucket-policies-IP).
- For **Azure Storage**
To update the IP access restrictions in your Azure Storage blobstore:
If you restrict access to your Azure resources using an Azure Storage
firewall, you must add the IP ranges used by STS workers to your list of
allowed IPs.
To add these ranges as allowed IPs, follow these instructions: [Configure Azure Storage firewalls and virtual networks](https://learn.microsoft.com/en-us/azure/storage/common/storage-network-security#grant-access-from-an-internet-ip-range).
### Set up a Pub/Sub push feed
To set up a Pub/Sub push feed, do the following:
1. Create a Pub/Sub push feed.
2. Specify the endpoint URL in a Pub/Sub subscription.
> [!NOTE]
> **Note:** The Pub/Sub push feed needs to be in your Google Cloud project bound to Google SecOps for the subscription to authenticate. It uses a JWT token from your service account for authentication. For more details, see [Authentication for push subscriptions](https://docs.cloud.google.com/pubsub/docs/authenticate-push-subscriptions.md.txt).
#### Create a Pub/Sub push feed
1. In the Google SecOps menu, select **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**.
2. Click **Add new**.
3. In the **Feed name** field, enter a name for the feed.
4. In the **Source type** list, select **Google Cloud Pub/Sub Push**.
5. Select the **Log type** . For example, to create a feed for Open Cybersecurity Schema Framework, select **Open Cybersecurity Schema Framework (OCSF)** as the **Log type**.
6. Click **Next**.
7. Optional: Specify values for the following input parameters:
- **Split delimiter** : the delimiter that is used to separate log lines. You can only use `\n`.
- **Asset namespace** : the [asset namespace](https://docs.cloud.google.com/chronicle/docs/investigation/asset-namespaces.md.txt).
- **Ingestion labels**: the label to be applied to the events from this feed.
8. Click **Next**.
9. Review your new feed configuration in the **Finalize** screen, and then click **Submit**.
10. From the **Details** tab, copy the feed endpoint URL from the **Endpoint Information** field. You need this endpoint URL to create a push subscription in Pub/Sub.
11. Optional: Click the **Feed Enabled** toggle to disable the feed. The feed is enabled by default.
12. Click **Done**.
#### Specify the endpoint URL
After you create a Pub/Sub push feed, specify the endpoint URL as follows:
1. In Pub/Sub, create a push subscription. For more information about how to create a push subscription, see [Create push subscriptions](https://docs.cloud.google.com/pubsub/docs/create-push-subscription.md.txt).
2. Specify the endpoint URL, which is available in the Google Cloud Pub/Sub push feed.
3. Select **Enable authentication**, and select a service account.
4. Disable both the **Push payload unwrapping** and **Push payload unwrapping write message metadata** options.
> [!NOTE]
> **Note:** If you need to push logs from an another Google Cloud project that isn't bound to Google SecOps, such as from a user-managed service account, you must set up a log sink. For more information about log sinks, see [Route logs to supported destinations](https://docs.cloud.google.com/logging/docs/export/configure_export_v2.md.txt#overview).
### Set up an Amazon Data Firehose feed
To set up an Amazon Data Firehose feed, do the following:
1. [Create an Amazon Data Firehose feed](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#firehose-create) and copy the endpoint URL and secret key.
2. [Create an API key](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#firehose-api-key) to authenticate to Google SecOps. You can also reuse your existing API key to authenticate to Google SecOps.
3. [Specify the endpoint URL](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#firehose-endpoint-url) in Amazon Data Firehose.
#### Create an Amazon Data Firehose feed
1. In the Google SecOps menu, select **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**.
2. Click **Add new**.
3. In the **Feed name** field, enter a name for the feed.
4. In the **Source type** list, select **Amazon Data Firehose**.
5. Select the **Log type** . For example, to create a feed for Open Cybersecurity Schema Framework, select **Open Cybersecurity Schema Framework (OCSF)** as the **Log type**.
6. Click **Next**.
7. Optional: Specify values for the following input parameters:
- **Split delimiter** : the delimiter that is used to separate log lines. You can only use `\n`.
- **Asset namespace** : the [asset namespace](https://docs.cloud.google.com/chronicle/docs/investigation/asset-namespaces.md.txt).
- **Ingestion labels**: the label to be applied to the events from this feed.
8. Click **Next**.
9. Review your new feed configuration in the **Finalize** screen, and then click **Submit**.
10. Click **Generate Secret Key** to generate a secret key to authenticate this feed.
11. Copy and store the secret key as you cannot view this secret again. You can generate a new secret key again, but regeneration of the secret key makes the previous secret key obsolete.
12. On the **Details** tab, copy the feed endpoint URL from the **Endpoint Information** field. You need this endpoint URL when you specify the destination settings for your delivery stream in Amazon Data Firehose.
13. Optional: Click the **Feed Enabled** toggle to disable the feed. The feed is enabled by default.
14. Click **Done**.
#### Create an API key for the Amazon Data Firehose feed
To create an API key for the Amazon Data Firehose feed, do the following:
1. Go to the Google Cloud console [Credentials](https://console.cloud.google.com/apis/credentials) page.
2. Click **Create credentials** and select **API key**.
3. Restrict the API key access to the Chronicle API.
#### Specify the endpoint URL
In Amazon Data Firehose, specify the HTTPS endpoint and access key, as follows:
1. Append the API key to the feed endpoint URL and specify
this URL as the HTTP endpoint URL in the following format:
ENDPOINT_URL?key=API_KEY
Replace the following:
- `ENDPOINT_URL`: the feed endpoint URL.
- `API_KEY`: the API key to authenticate to Google SecOps.
2. For the access key, specify the secret key that you obtained when you created
the Amazon Data Firehose feed.
### Set up an HTTPS webhook feed
Before you begin:
- Ensure that a [Google Cloud project for Google SecOps is configured](https://docs.cloud.google.com/chronicle/docs/onboard/configure-cloud-project.md.txt) and the Chronicle API is enabled for the project.
- [Link a Google SecOps instance to Google Cloud services](https://docs.cloud.google.com/chronicle/docs/onboard/link-chronicle-cloud.md.txt).
> [!NOTE]
> **Note:** Batches of data sent through Webhook feeds may experience ingestion delays if the request size or QPS limits are set too low. The HTTPS push endpoint supports a maximum request size of 4 MB per request and a maximum throughput of 15 K QPS per Google SecOps instance.
To set up an HTTPS webhook feed, do the following:
1. [Create an HTTPS webhook feed](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#webhook-create) and copy the endpoint URL and secret key.
2. [Create an API key](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#webhook-api-key) that is specified with the endpoint URL. You can also reuse your existing API key to authenticate to Google SecOps.
3. [Specify the endpoint URL](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#webhook-endpoint-url) in your application.
#### Send multiple events in a single webhook request
The following code sample shows how to format a single request body with multiple, newline-separated JSON objects after the `curl --location` item:
--header 'Content-Type: application/json' \
--header 'X-goog-api-key: API_KEY' \
--header 'X-Webhook-Access-Key: SECRET' \
--data '{"principal": {"asset_id": "asset 123"}, "metadata": {"event_type": "GENERIC_EVENT", "product_name": "Product Acme"}}
{"principal": {"asset_id": "asset 123"}, "metadata": {"event_type": "GENERIC_EVENT", "product_name": "Product Acme"}}'
#### Create an HTTPS webhook feed
1. In the Google SecOps menu, select **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**.
2. Click **Add new**.
3. In the **Feed name** field, enter a name for the feed.
4. In the **Source type** list, select **Webhook**.
5. Select the **Log type** . For example, to create a feed for Open Cybersecurity Schema Framework, select **Open Cybersecurity Schema Framework (OCSF)** as the **Log type**.
6. Click **Next**.
7. Optional: Specify values for the following input parameters:
- **Split delimiter** : the delimiter that is used to separate log lines. You can only use `\n`.
- **Asset namespace** : the [asset namespace](https://docs.cloud.google.com/chronicle/docs/investigation/asset-namespaces.md.txt).
- **Ingestion labels**: the label to be applied to the events from this feed.
8. Click **Next**.
9. Review your new feed configuration in the **Finalize** screen, and then click **Submit**.
10. Click **Generate Secret Key** to generate a secret key to authenticate this feed.
11. Copy and store the secret key as you cannot view this secret again. You can generate a new secret key again, but regeneration of the secret key makes the previous secret key obsolete.
12. From the **Details** tab, copy the feed endpoint URL from the **Endpoint Information** field.
You need to specify this endpoint URL in your client application.
> [!CAUTION]
> **Caution:** When configuring your client application, you must paste the full endpoint URL copied from the **Endpoint Information** field (ending in `:importPushLogs`). Do not paste the generic Google SecOps console URL, which results in `HTTP 404 Not Found` errors.
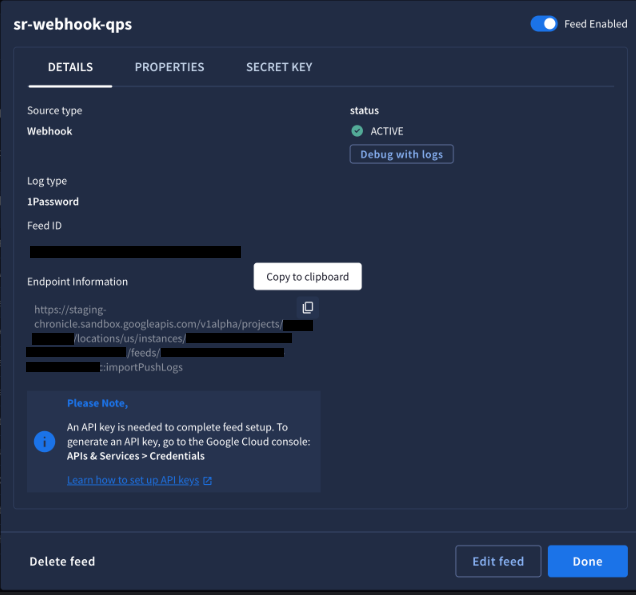
**Figure 1.** Webhook feed endpoint information
13. Optional: Click the **Feed Enabled** toggle to disable the feed. The feed is enabled by default.
14. Click **Done**.
#### Create an API key for the webhook feed
1. Go to the Google Cloud console [**Credentials**](https://console.cloud.google.com/apis/credentials) page.
2. Click **Create credentials** , and then select **API key**.
3. Restrict the API key access to the Chronicle API.
#### Specify the endpoint URL
1. In your client application, specify the HTTPS endpoint, which is available in the webhook feed.
2. Enable authentication by specifying the API key and secret key as part of the custom header
in the following format:
`X-goog-api-key = API_KEY`
`X-Webhook-Access-Key = SECRET`
We recommend that you specify the API key as a header instead of specifying it
in the URL. If your webhook client doesn't support custom headers, you can specify
the API key and secret key by using query parameters in the following format:
ENDPOINT_URL?key=API_KEY&secret=SECRET
Replace the following:
- `ENDPOINT_URL`: the feed endpoint URL.
- `API_KEY`: the API key to authenticate to Google SecOps.
- `SECRET`: the secret key that you generated to authenticate the feed.
### Set up a Custom API feed
> [!NOTE]
> **Note:** This feature is covered by [Pre-GA Offerings Terms](https://chronicle.security/legal/service-terms/) of the Google Security Operations Service Specific Terms. Pre-GA features might have limited support, and changes to pre-GA features might not be compatible with other pre-GA versions. For more information, see the [Google SecOps Technical Support Service guidelines](https://chronicle.security/legal/technical-support-services-guidelines/) and the [Google SecOps Service Specific Terms](https://chronicle.security/legal/service-terms/).
> If this feature isn't visible in your environment, see [Manage preview features](https://docs.cloud.google.com/chronicle/docs/secops/preview-features-manage.md.txt) or contact your system administrator.
> [!NOTE]
> **Note:** This feature is in Private Preview and is not available to all customers in all regions. Private Preview features are not manageable in the Public Preview Features page in the Google SecOps platform.
Google Security Operations Custom API feeds (also known as Codeless Connectors) enable you to ingest telemetry from third-party REST APIs using a flexible, configuration-based model. You can configure data pulls by defining endpoints, authentication, pagination strategies, and state management directly in the console.
#### Key benefits
- **Accelerate integration**: Onboard new telemetry sources in minutes through a guided wizard without waiting for backend updates.
- **Stateful checkpointing**: Ensure zero data duplication and zero missing logs across polling cycles.
- **Parent-child fan-out:** Supports two-tier discovery workflows, such as listing resources and fetching their associated telemetry.
- **Automated resilience and rate limiting** : Prevents vendor throttling and quota exhaustion. For reliable, uninterrupted ingestion, the Custom API feed automatically handles HTTP 429 responses with an exponential backoff, paces requests with configurable rate limiting and task delay staggering, and enforces safety guardrails. For more information, see [Rate limiting and throttling guardrails](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#rate-limiting-throttling-guardrails).
#### Prerequisites
Verify the following prerequisites before creating a Custom API feed:
- **Permissions:** To create or modify feeds, you must have the Chronicle API Admin (`roles/chronicle.admin`) or Chronicle API Editor (`roles/chronicle.editor`) role.
- **Third-party API requirements:**
- A valid API base URL (must use `https://`).
- API credentials (API Key, Basic Auth credentials, or OAuth 2.0 Client ID/Secret).
- Vendor API documentation detailing endpoint paths, request parameters, JSON response structures, and rate limits.
- **Secret Manager access:** Credentials are encrypted and managed securely within Secret Manager. The service identity executing the connector automatically interacts with Secret Manager (`roles/secretmanager.secretAccessor` and `roles/secretmanager.admin`).
#### Configure a Custom API feed
To configure a Custom API feed, do the following:
1. Go to **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**.
2. Click **Add new feed**.
3. Click **Configure a single feed**.
4. In the **Feed name** field, enter a unique descriptive name (for example, `1Password-Audit-Events`).
5. In the **Source type** list, select **Custom API**.
6. In the **Log type** list, select the target Google SecOps Log Type.
7. Click **Next**.
8. Under **General settings**, configure the following:
- **Base URL:** Enter the primary host (for example, `https://events.1password.com`). It must start with `https://`. Don't append sub-paths or trailing slashes.
- **Polling frequency:** Specify how often the platform checks the API for new telemetry, in minutes. Supported range: 5 to 2880 minutes (default: 15 minutes). For **Standard API (Sequential)** feeds, 10--15 minutes is standard; for **List \& Detail (Parent-Child)** feeds, 30--60 minutes is recommended to allow full fan-out task execution without overlap.
9. Under **Authentication**, select one of the supported authentication methods, and then configure the required fields:
- **Basic Authentication:** Enter the **Username** (API account identity) and **Secret** (that is, the secret password or token).
- **OAuth 2.0 Client Credentials:** Authenticate using the OAuth 2.0 Client Credentials Grant flow. Google SecOps automatically requests, caches, and refreshes bearer access tokens before each ingestion cycle. Enter the **OAuth token endpoint** (for example, `https://auth.vendor.com/oauth/token`), **OAuth client ID** , and **OAuth client secret**.
- **API Key Request Headers:** Authenticate using custom API keys injected into request headers (the most common enterprise REST pattern). Enter the **Header name** (for example, `Authorization` or `X-API-Key`) and **Header value** (for example, `Bearer ` or ``).
- **API Key Query Parameters:** Authenticate using custom API keys injected into URL query parameters. Enter the **Query parameter name** (for example, `api_key`) and **Query parameter value** (for example, ``).
> [!NOTE]
> **Note:** All credentials that you enter here are automatically masked during entry and securely encrypted in Secret Manager, with optional customer-managed encryption keys (CMEK) support.
10. Select the connector model that your custom API uses:
- **Standard API (Sequential):** A linear polling flow where each poll builds directly on the state of the previous one. In this model, the next poll uses a cursor, token, or timestamp extracted from the previous poll to fetch only new data. Select this card when the vendor provides an endpoint that directly returns telemetry event records (for example, 1Password, Okta, SentinelOne, GitHub, or Slack).
- **List \& Detail (Parent-Child):** A two-tier discovery flow. The feed makes an initial call (parent) to retrieve a list of resources or objects (for example, a list of user IDs or zones). The feed then automatically spawns dependent follow-up calls (child) to fetch detailed telemetry for each individual resource identified. Select this card when the vendor API requires a two-tier discovery pattern: first calling an endpoint to fetch a dynamic list of entities (for example, zones, accounts, projects, devices), and then executing follow-up detail requests per entity to retrieve telemetry (for example, Cloudflare, AWS CloudWatch, or Tenable).
> [!NOTE]
> **Note:** Both models use *checkpointing*, which is a state-management process that extracts and stores the highest timestamp or ID from a poll to resume ingestion in the next cycle without missing logs or creating duplicate data.
11. If you selected **Standard API (Sequential)**, do the following:
1. Under **API endpoint** , configure the following parameters to define the technical route and rate pacing for the request:
- **Endpoint path:** The specific API route appended to the **Base URL** (for example, `/api/v1/auditevents`). This defines the exact telemetry resource to query.
- **HTTP method:** Select **GET** to retrieve data using URL query parameters, or **POST** to submit a search payload or filter body.
2. **Request body:** For POST requests, provide the JSON data payload. You can embed dynamic checkpoint variables such as `{"limit": 100, "start_time": "{{.last_timestamp}}"}`.
3. **Max requests per minute:** Enter the maximum number of requests to send per minute. This is a client-side rate limiter to comply with vendor API rate limits (default: **5 RPM** = 1 request every 12 seconds). This setting prevents quota exhaustion during multi-page pagination.
4. Optional: Under **Custom headers** , configure the **Header name** and **Value** , and then click **Add** to define specialized HTTP headers required by the target API (for example, `Content-Type: application/json, Accept: application/json`).
5. Optional: Under **Query parameters** , configure the **Key** and **Value** , and then click **Add** to specify extra filters or options appended to the URL query string (for example, `count=1000`, `status=active`) or bind dynamic template variables (for example, `start={{.last_run_time}}`).
6. Under **Pagination strategy:** Select the paging mechanism that the third-party API requires to handle multi-page result sets, and then configure the required fields:
- **None:** Fetch data in a single request without paging.
- **Token Pagination:** Use tokens (custom keys) to get the next page. Enter the **Next page token JSON path** (for example, `meta.next_cursor`) and **Token pagination query parameter name** (for example, `cursor`).
- **Link Pagination:** Follow URLs provided in the response to get more data. Enter the **Next page link JSON path** (for example, `links.next` or `@odata.nextLink`).
- **Offset Pagination:** Skip a set number of records to get the next set. Enter the **Offset query parameter name** (for example, `offset`).
- **Page Number Pagination:** Go to the next sequential page number. Enter the **Page number query parameter name** (for example, `page`).
7. Under **Checkpointing**, configure the settings that allow the connector to remember where it left off between recurring polling cycles:
- **Strategy:** Choose one of the following strategies and configure the required fields:
- **None:** Fetch all available data without tracking progress across cycles.
- **Latest Timestamp:** Track the timestamp of the newest record. Enter the **Checkpoint value JSON path** (for example, `timestamp` or `event_time`) and **Checkpoint variable** (for example, `last_run_time`, referenced in subsequent polls as `{{.last_run_time}}`).
- **Latest Record:** Track the highest record ID to fetch only new records. Enter the **Checkpoint value JSON path** (for example, `id` or `event_id`) and **Checkpoint variable** (for example, `last_id`, referenced as `{{.last_id}}`).
- **Iterator Token:** Use persistent continuation tokens provided by the API. Enter the **Checkpoint value JSON path** and **Checkpoint variable** (for example, `iterator_token`, referenced as `{{.iterator_token}}`).
8. Under **Response Mapping**, provide rules that tell the platform how to locate and extract logs:
- **Target data JSON path:** Enter the exact path in the API response payload where the list of target log entries is located. For object-wrapped arrays (for example, `{"items": [...]}`), enter `items`. For APIs returning a root JSON array directly (for example, `[{...}, {...}]`), leave this field completely empty (`[]`).
12. If you selected **List \& Detail (Parent-Child)**, do the following:
1. **Parent Request (Discovery):** Configure the endpoint that returns a list of items:
1. Under **API endpoint** , configure the following parameters to define the technical route and rate pacing for the request:
- **Endpoint path:** The specific API route appended to the **Base URL** (for example, `/api/v1/auditevents`). This defines the exact telemetry resource to query.
- **HTTP method:** Select **GET** to retrieve data using URL query parameters, or **POST** to submit a search payload or filter body.
- **Request body:** For POST requests, provide the JSON data payload. You can embed dynamic checkpoint variables such as `{"limit": 100, "start_time": "{{.last_timestamp}}"}`.
2. **Max requests per minute:** Enter the maximum number of requests to send per minute. This is a client-side rate limiter to comply with vendor API rate limits (default: **5 RPM** = 1 request every 12 seconds). This setting prevents quota exhaustion during multi-page pagination.
3. Optional: Under **Custom headers** , configure the **Header name** and **Value** , and then click **Add** to define specialized HTTP headers required by the target API (for example, `Content-Type: application/json, Accept: application/json`).
4. Optional: Under **Query parameters** , configure the **Key** and **Value** , and then click **Add** to specify extra filters or options appended to the URL query string (for example, `count=1000`, `status=active`) or bind dynamic template variables (for example, `start={{.last_run_time}}`).
5. Under **Pagination strategy:** Select the paging mechanism that the third-party API requires to handle multi-page result sets, and then configure the required fields:
- **None:** Fetch data in a single request without paging.
- **Token Pagination:** Use tokens (custom keys) to get the next page. Enter the **Next page token JSON path** (for example, `meta.next_cursor`) and **Token pagination query parameter name** (for example, `cursor`).
- **Link Pagination:** Follow URLs provided in the response to get more data. Enter the **Next page link JSON path** (for example, `links.next` or `@odata.nextLink`).
- **Offset Pagination:** Skip a set number of records to get the next set. Enter the **Offset query parameter name** (for example, `offset`).
- **Page Number Pagination:** Go to the next sequential page number. Enter the **Page number query parameter name** (for example, `page`).
6. Under **Checkpointing** , configure the settings that allow the connector to remember where it left off between recurring polling cycles:
- **Strategy:** Choose one of the following strategies and configure the required fields:
- **None:** Fetch all available data without tracking progress across cycles.
- **Latest Timestamp:** Track the timestamp of the newest record. Enter the **Checkpoint value JSON path** (for example, `timestamp` or `event_time`) and **Checkpoint variable** (for example, `last_run_time`, referenced in subsequent polls as `{{.last_run_time}}`).
- **Latest Record:** Track the highest record ID to fetch only new records. Enter the **Checkpoint value JSON path** (for example, `id` or `event_id`) and **Checkpoint variable** (for example, `last_id`, referenced as `{{.last_id}}`).
- **Iterator Token:** Use persistent continuation tokens provided by the API. Enter the **Checkpoint value JSON path** and **Checkpoint variable** (for example, `iterator_token`, referenced as `{{.iterator_token}}`).
2. **Data extraction (the bridge):** Configure the following:
- **Item identifier JSON path:** The specific field in the parent response that uniquely identifies an individual entity (for example, `id` or `zone_id`). The connector extracts this identifier from each item in the parent array.
- **Template variable name:** Specify a custom variable name to hold the extracted ID (for example, `zone_id`). The UI displays a dynamic badge: **Use `{{.zone_id}}` in your child request below**.
3. **Child Request (Detail):** Configure the endpoint that returns detailed logs for each item:
1. Under **API endpoint** , configure the following parameters to define the technical route and rate pacing for the request:
- **Endpoint path:** The specific API route appended to the **Base URL** (for example, `/client/v4/zones/{{.zone_id}}/logs/received`). This defines the exact telemetry resource to query.
- **HTTP method:** Select **GET** to retrieve data using URL query parameters, or **POST** to submit a search payload or filter body.
- **Request body:** For POST requests, provide the JSON data payload. You can embed dynamic checkpoint variables such as `{"limit": 100, "start_time": "{{.last_timestamp}}"}`.
2. **Max requests per minute:** Enter the maximum number of requests to send per minute. This is a client-side rate limiter to comply with vendor API rate limits (default: **5 RPM** = 1 request every 12 seconds). This setting prevents quota exhaustion during multi-page pagination.
3. Optional: Under **Custom headers** , configure the **Header name** and **Value** , and then click **Add** to define specialized HTTP headers required by the target API (for example, `Content-Type: application/json, Accept: application/json`).
4. Optional: Under **Query parameters** , configure the **Key** and **Value** , and then click **Add** to specify extra filters or options appended to the URL query string (for example, `count=1000`, `status=active`) or bind dynamic template variables (for example, `start={{.last_run_time}}`).
5. Under **Pagination strategy:** Select the paging mechanism that the third-party API requires to handle multi-page result sets, and then configure the required fields:
- **None:** Fetch data in a single request without paging.
- **Token Pagination:** Use tokens (custom keys) to get the next page. Enter the **Next page token JSON path** (for example, `meta.next_cursor`) and **Token pagination query parameter name** (for example, `cursor`).
- **Link Pagination:** Follow URLs provided in the response to get more data. Enter the **Next page link JSON path** (for example, `links.next` or `@odata.nextLink`).
- **Offset Pagination:** Skip a set number of records to get the next set. Enter the **Offset query parameter name** (for example, `offset`).
- **Page Number Pagination:** Go to the next sequential page number. Enter the **Page number query parameter name** (for example, `page`).
6. Under **Checkpointing** , configure the settings that allow the connector to remember where it left off between recurring polling cycles:
- **Strategy:** Choose one of the following strategies and configure the required fields:
- **None:** Fetch all available data without tracking progress across cycles.
- **Latest Timestamp:** Track the timestamp of the newest record. Enter the **Checkpoint value JSON path** (for example, `timestamp` or `event_time`) and **Checkpoint variable** (for example, `last_run_time`, referenced in subsequent polls as `{{.last_run_time}}`).
13. Configure the following **Scheduling \& Labels** settings:
- **Polling Frequency:** Select a standard interval (for example, `5m`, `1h`).
- **Namespace:** Optional organizational tag.
- **Ingestion Labels:** Key-value pairs for Data RBAC.
14. Click **Submit**. Google SecOps performs an automated credential and endpoint validation check. If validation succeeds, the feed begins polling.
#### Sample configuration 1: 1Password audit events (Standard API (Sequential) model)
The following declarative JSON configuration demonstrates a **Standard API (Sequential)** model, with cursor-based checkpointing for 1Password:
```json
{
"base_url": "https://events.1password.com",
"polling_frequency": 15,
"header_auth": {
"header_key_values": [
{
"key": "Authorization",
"value": "Bearer "
}
]
},
"primary_request": {
"request_settings": {
"endpoint_path": "/api/v1/auditevents",
"http_method": "POST",
"request_body": "{\"limit\": 1000, \"start_time\": \"{{.last_run_time}}\"}",
"custom_headers": [
{
"key": "Content-Type",
"value": "application/json"
}
],
"max_requests_per_minute": 5
},
"pagination_strategy": {
"token": {
"next_page_token_json_path": "additional_items_url",
"query_param": "cursor"
}
},
"checkpointing": {
"latest_timestamp_strategy": {
"checkpoint_value_path": "timestamp",
"checkpoint_variable": "last_run_time"
}
},
"response_mapping": {
"target_data_path": ["items"]
}
}
}
```
#### Concrete sample configuration 2: Cloudflare zone telemetry (List \& Detail (Parent-Child) model)
The following declarative JSON configuration demonstrates a **List \& Detail (Parent-Child)** fan-out model for Cloudflare:
```json
{
"base_url": "https://api.cloudflare.com",
"polling_frequency": 30,
"header_auth": {
"header_key_values": [
{
"key": "Authorization",
"value": "Bearer "
}
]
},
"primary_request": {
"request_settings": {
"endpoint_path": "/client/v4/zones",
"http_method": "GET"
},
"response_mapping": {
"target_data_path": ["result"]
},
"pagination_strategy": {
"none": {}
},
"checkpointing": {
"none_strategy": {}
},
"dependent_requests_config": {
"item_id_json_path": "id",
"item_id_variable": "zone_id",
"dependent_requests": [
{
"request_settings": {
"endpoint_path": "/client/v4/zones/{{.zone_id}}/logs/received",
"http_method": "GET",
"query_parameters": [
{
"key": "start",
"value": "{{.last_run_time}}"
},
{
"key": "count",
"value": "1000"
}
],
"max_requests_per_minute": 5
},
"pagination_strategy": {
"none": {}
},
"checkpointing": {
"latest_timestamp_strategy": {
"checkpoint_value_path": "EdgeStartTimestamp",
"checkpoint_variable": "last_run_time"
}
},
"response_mapping": {
"target_data_path": []
}
}
]
}
}
}
```
#### Custom API best practices
- **Polling frequency guidance** :
- **Start with moderate polling intervals**: Set the initial polling interval to 15 minutes or 30 minutes for high-volume endpoints to observe vendor API quota behavior before lowering to 5 minutes.
- **Optimize for high-volume fan-out** : For **Parent-Child (List \& Detail)** feeds discovering dozens or hundreds of resources, Google strongly recommends that you set the **Polling frequency** to 30 to 60 minutes to allow all paced child tasks to complete cleanly before the next discovery cycle initiates.
- **Validate ingestion paths**: Use vendor documentation or API testing tools to confirm the exact JSON field name for timestamps before configuring state checkpointing.
- **Decompose multi-child APIs** : If a third-party API requires fetching alerts *and* audit logs for a single user list, create two separate single-child feeds (one for alerts and one for audit logs) to maintain optimal isolation.
#### Rate limiting and throttling guardrails
To prevent customer feed configurations from overwhelming third-party vendor quotas or monopolizing system resources, the Custom API feed type implements the following automated guardrails:
- **Configurable request pacing (rate limiting):** Outgoing HTTP requests are automatically paced to prevent exceeding vendor rate limits. The default pacing rate is 5 requests per minute (1 request every 12 seconds). You can tune this per endpoint using the **Max requests per minute** field in the endpoint settings to match your vendor's published API quotas.
- **Child request ceiling:** For **Parent-Child (List \& Detail)** feeds, a discovery request can dispatch up to 500 child requests per polling cycle.
- **Single-level fan-out depth:** The connector strictly enforces a maximum fan-out depth of 1 level (Parent discovery → Child details). Nested dependent requests (grandchild calls) are not supported.
- **Response payload size ceiling:** The maximum allowed HTTP response size for any single request or page is 50 MB. If an unpaginated API returns a response exceeding 50 MB, the fetch will fail with a resource exhausted error. To prevent this, always configure pagination query parameters (such as `limit` or `page_size`) to retrieve records in smaller batches.
- **Automated HTTP 429 back-off:** If a third-party vendor API responds with HTTP 429 (Too Many Requests), Google SecOps automatically captures the status and initiates an exponential back-off period, pausing task execution until the vendor quota window refills.
#### Custom API limitations
When planning your ingestion paths, note that the Custom API feed type has the following limitations:
- **Strict JSON support:** Only JSON API responses are supported. Other formats such as XML, CSV, Parquet, and Avro are not supported.
- **No dynamic request signing:** APIs requiring dynamic cryptographic signatures per request are not supported (for example, AWS SigV4, Akamai, or Oracle OCI).
- **No multi-step authentication:** APIs that require an initial programmatic login call to exchange credentials for a temporary session token (such as Saviynt) before polling are not supported.
- **No WebSockets or Push ingestion:** Custom API feeds support standard HTTPS pull polling. Persistent streaming connections (WebSockets) and incoming webhooks are not supported.
- **No Mutual TLS (mTLS):** Authentication must rely on API keys, basic authentication, or standard OAuth 2.0 client credentials. Client-side certificate handshakes are not supported.
#### Troubleshoot Custom API feeds
To investigate errors for Custom API feeds in Cloud Logging Logs Explorer, use the following queries:
```json
resource.type="gce_instance" OR resource.type="generic_task"
jsonPayload.service="gopher"
jsonPayload.feed_id="FEED_ID"
```
Replace `FEED_ID` with your feed ID.
To filter specifically for failed HTTP requests, use the following query:
```json
jsonPayload.service="gopher"
jsonPayload.feed_id="FEED_ID"
jsonPayload.http_status_code >= 400
```
Replace `FEED_ID` with your feed ID.
**Common failure modes and solutions**
| Symptom / Error | Root cause | Solution / Remedy |
|---|---|---|
| HTTP 401 Unauthorized / HTTP 403 Forbidden | Expired or invalid API Key, password, or OAuth credentials. | Edit the feed, re-enter valid credentials, and click **Submit**. |
| HTTP 404 Not Found | Incorrect Base URL or Endpoint Path template. | Inspect *endpoint* in the vendor API documentation. Make sure that the Base URL ends cleanly and the Endpoint Path starts with /. |
| HTTP 429 Too Many Requests | Exceeded vendor API rate limits. | Increase the polling frequency or reduce the `limit` parameter in the query parameters. |
| JSON Extraction Error (items_path empty) | Mismatch in response configuration path. | Verify the API response payload structure and update the target data JSON path. |
| Duplicate Data Ingestion | Invalid state configuration timestamp or ID extractor path. | Check the log record field name for timestamp and update the extractor path. |
## Manage feeds
After you configure your data feeds, use the management tools to monitor ingestion health, modify existing parameters, and manage the feed lifecycle. This section outlines how to interpret feed statuses and perform essential maintenance tasks to ensure continuous data visibility.
The **Feeds** page provides several tools to help you navigate and organize your
list of configured feeds:
- Search: Use the search bar to find a feed by its **Feed Name** , **Feed ID** ,
or **Source type**.
- Filter: Click the filter icon to narrow the list based on specific feed
attributes.
- Download CSV: Click **Download as CSV** to export the current list of feeds to
a CSV file.
- Pagination: Use the pagination controls to:
- Change the number of **Rows per page**.
- Navigate through multiple pages of feeds using the page tabs and arrows.
- Last refreshed time: View the timestamp to see when the feed list was last
updated.
### View configured feeds
The **Feeds** page shows all the feeds you've configured.
1. Go to **Settings \> Data Management \> Feeds** . If you are on a SIEM-only platform, go to **Settings \> Feeds**. The main page displays all your configured feeds.
2. Hold the pointer over each row to display the more_vert **More** menu.
3. In the menu, you can view feed details, edit, disable, or delete the feed.
### Monitor the feed status
You can monitor the status of the feed on the initial **Feeds** page, where feeds can have the following statuses:
- **Active**: Feed is configured and ready to ingest data into your Google SecOps account.
> [!NOTE]
> **Note:** An **Active** status indicates that the feed configuration is enabled, but does not reflect runtime authentication or collection health. If logs are not arriving from an active third-party feed, check the [Health Hub](https://docs.cloud.google.com/chronicle/docs/reports/data-health-monitoring-and-troubleshooting-dashboard.md.txt) for operational errors such as expired secrets or invalid tokens.
- **InProgress**: Google SecOps attempts to pull data from the configured third party.
- **Completed**: Data successfully retrieved by this feed.
- **Archived**: Disabled feed.
- **Failed** : Feed is failing to successfully fetch data. This is likely due to a configuration issue. Click the question to display the configuration error. Once you've corrected the error and resubmitted the feed, return to the **Feeds** page to determine whether or not the feed is now working.
> [!NOTE]
> **Note:** The **Last succeeded on** column on the **Feeds** page shows the last time data was fetched successfully by that feed. For a new feed, this field is blank. Push feeds, like Webhook and Google Cloud pubsub don't populate this column. These push feeds don't have a schedule, meaning the data comes in when it is pushed. For Amazon SQS (V2) feeds, the **Last succeeded on** column represents the active ingestion heartbeat timestamp. Updates to this column are throttled and can be delayed by up to 15 minutes.
### Edit existing feeds
On the **Feeds** page, you can edit an existing feed, as follows:
1. Hold the pointer over an existing feed and click more_vert in the right column.
2. Click **Edit Feed**. You can now modify the input parameters for the feed and
resubmit it to Google SecOps, which will attempt to use the updated feed.
> [!NOTE]
> **Note:** Existing feeds show **\[Not Configured\]** as a feed name on the **Feeds** page. Edit the feed to add a feed name.
#### Google Workspace feeds restrictions
In-place editing using **Edit Feed** is not supported for the following Google Workspace
feed types:
- `WORKSPACE_ACTIVITY`
- `WORKSPACE_ALERTS`
- `WORKSPACE_CHROMEOS`
- `WORKSPACE_GROUPS`
- `WORKSPACE_MOBILE`
- `WORKSPACE_USERS`
Attempting to save modifications to an existing feed for these log types returns an
`HTTP 400 INVALID_ARGUMENT` error. To modify settings or rotate authentication keys, such as OAuth service account keys, disable or delete the existing feed and create
a new feed.
> [!NOTE]
> **Note:** In-place editing *is* supported for `WORKSPACE_PRIVILEGES` feeds.
### Enable (resume) and disable (pause) feeds
When you disable a feed, Google SecOps stops ingesting new data from that source. To stop data ingestion immediately, you should delete the feed. Existing active or throttled transfers continue until finished. When you re-enable the feed, Google SecOps can retrieve data that was missed while the feed was disabled. This capability is called "backfillability".
In the **Status** column, enabled feeds are labeled as **Active** , **InProgress** , **Completed** , or **Failed** . Disabled fields are labeled as **Archived** . For a description, see [Monitor the feed status](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#feed-status).
On the **Feeds** page, you can enable (resume) or disable (pause) any of the existing feeds:
1. Hold the pointer over an existing feed and click more_vert in the right column.
2. Optional: Click the **Feed Enabled** toggle to enable the feed.
3. Optional: Click the **Disable Feed** toggle to disable the feed. The feed is now labeled as **Archived**.
#### Data recovery when you re-enable feeds (backfillability)
The ability for Google SecOps to backfill data depends on whether your feed is pull-based (supported) or push-based (not supported).
**Pull-based feeds**
With these feeds, Google SecOps pulls data from external sources. Pull feeds include:
- Cloud storage buckets, such as Amazon S3, Google Cloud Storage, Azure Blob Storage
- SFTP servers
- Third-party APIs, such as Microsoft 365, Okta, Proofpoint
When you re-enable pull-based feeds, Google SecOps can retrieve data that was generated while the feed was disabled.
**Push-based feeds**
With these feeds external systems "push" data to Google SecOps. Push feeds include:
- HTTPS webhooks
- Google Cloud Pub/Sub
- Amazon Kinesis Data Firehose
- Direct API/agent ingestions, such as Bindplane
Google SecOps cannot automatically initiate data backfill from push-based feeds. While the feed is disabled and your system pushes data, Google SecOps sends either an `HTTP 403 Forbidden` error or a generic 4xx error.
If your system doesn't store and retry sending the data to Google SecOps, the data will be lost. In addition, if your system is set to "drop on failure" or clear its buffer, the data is permanently lost for the respective period. To avoid data loss, you should configure your system to buffer and resend data once a feed is re-enabled. Google SecOps can then ingest the missed data when the feed is resumed.
**Backfill considerations**
- **Source system limits:** The amount of historical data Google SecOps can backfill from pull-based feeds is limited by how long the source system keeps the data and what its API allows. For example, some APIs only provide access to the last seven days of data.
- **Google SecOps buffer:** For automated recovery, Google SecOps' internal buffer for pull-based feeds holds data for up to 90 days, after which the data is dropped.
- **Tenant restrictions:** Non-paying tenants, such as proofs of concept, might have limitations on backfilling of older data.
- **Ingestion quotas:** To avoid impacting real-time data ingestion, backfill data is processed with a lower priority than live data. Pull-based data backfill is also rate-limited, typically to one-third (33%) of your tenant's burst limit per log type. This ensures critical push-based feeds, such as EDR agents, aren't negatively affected.
- **Dynamic rate limiting:** If the backfill consumes all the available pull quota, ingestion is paused for the remainder of the five-minute interval and resumes automatically when the interval restarts.
- **Cloud storage:** You can use feed settings to control backfill, such as filters for new or updated files, or date range filters, such as "Maximum file age".
- **Large backlogs:** If a large backlog from a pull-based feed causes issues upon re-enabling, you can contact Google Support to clear the backlog. This means the feed will start ingesting only new data going forward, and the missed data won't be backfilled.
- **Editing disabled feeds:** Any configuration changes made to a feed while it is disabled will apply as soon as the feed is re-enabled.
### Delete feeds
On the **Feeds** page, you can also delete an existing feed:
1. Hold the pointer over an existing feed and click more_vert in the right column.
2. Click **Delete Feed** . The **DELETE FEED** window opens. To permanently delete the feed, click **Yes, delete it**.
> [!NOTE]
> **Note:** When you delete a feed, no new data will be ingested. There may be data already in the queue that will still be processed.
For Custom API feeds, a dialog window appears with an optional checkbox: **Delete pending backlog data**:
- **Unchecked (Default):** The feed configuration and credentials are deleted, but queued backlog data is allowed to process through to ingestion.
- **Checked:** The feed configuration, credentials, and all pending backlog data are permanently removed.
## Control the rate of ingestion
When the data ingestion rate for a tenant reaches a certain threshold,
Google Security Operations restricts the rate of ingestion for new data feeds to prevent
a source with a high ingestion rate from affecting the ingestion rate of another
data source. In this case, there is a delay but no data is lost. The ingestion
volume and tenant's usage history determine the threshold.
You can request a rate limit increase by contacting
[Cloud Customer Care](https://cloud.google.com/support-hub).
## Troubleshoot failed feeds
- On the **Feeds** page, you can view details such as source type, log type, feed
ID, and status of the existing feeds, as follows:
1. Hold the pointer over an existing feed and click more_vert in the right column.
2. Click **View Feed** . A dialog appears showing the feed details. For a failed feed,
you can find error details under **Details** \> **Status**.
- For a failed feed, the details include the cause of the error and steps to fix it.
- See the [Source and Ingestion Errors](https://docs.cloud.google.com/chronicle/docs/ingestion/troubleshooting-ingestion.md.txt#source_and_ingestion_errors) table for error messages that you might encounter when
working with data feeds.
- For detailed analysis and troubleshooting of feed activity, you can view logs in Cloud Logging. See [Analyze feed activity with Cloud Logging](https://docs.cloud.google.com/chronicle/docs/ingestion/analyze-feed-activity-with-cloud-logging.md.txt).
- `Generic::failed_precondition` error:
Error: `Generic::failed_precondition: include_prefixes is not enabled for this customer`
This error occurs when you save an STS feed with values in the **Include prefixes** (`include_prefixes`) field, but your Google SecOps tenant isn't on the allowlist for prefix-based filtering.
To resolve this error, do one of the following:
1. Remove all prefixes from the **Include prefixes** (`include_prefixes`) field and save the feed again to ingest the entire bucket or container.
2. Contact your Google Cloud account team, Technical Account Manager (TAM), or [Cloud Customer Care](https://cloud.google.com/support-hub) to request access to the `include_prefixes` (`enable_feed_include_prefixes`) feature for your tenant. For more information, see [Filter objects by prefix in STS feeds](https://docs.cloud.google.com/chronicle/docs/administration/feed-management.md.txt#include-prefixes).
**Need more help?** [Get answers from Community members and Google SecOps professionals.](https://security.googlecloudcommunity.com/)