# Work with user-defined functions in Python
Python [user-defined functions (UDFs)](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/user-defined-functions) let you extend your
BigQuery SQL queries with custom scalar functions written in
Python. Python UDFs are similar to SQL and JavaScript UDFs, but with additional
capabilities. Creating these functions lets you use the
[Python Package Index (PyPI)](https://pypi.org/) ecosystem and access external services through
[Cloud resource connections](https://docs.cloud.google.com/bigquery/docs/create-cloud-resource-connection) without leaving BigQuery.
Python UDFs are built and run on BigQuery managed resources.
## Limitations
- `python-3.11` is the only supported runtime.
- You can't create a temporary Python UDF.
- You can't use a Python UDF with a materialized view.
- The results of a query that calls a Python UDF aren't cached because the return value of a Python UDF is always assumed to be non-deterministic.
- [Assured workloads](https://docs.cloud.google.com/assured-workloads/docs/overview) aren't supported.
- These data types are not supported: `JSON`, `RANGE`, `INTERVAL`, and `GEOGRAPHY`.
- Containers that run Python UDFs can only be configured up to [4 vCpu and 16
GiB](https://docs.cloud.google.com/bigquery/docs/user-defined-functions-python#configure-container-limits).
- Encrypting Python UDF code with [Customer-managed encryption keys (CMEK)](https://docs.cloud.google.com/kms/docs/cmek) isn't supported.
- Python UDFs support VPC Service Controls, but [VPC networks](https://docs.cloud.google.com/vpc/docs/vpc) aren't supported.
- Python UDFs aren't supported with [default connections](https://docs.cloud.google.com/bigquery/docs/default-connections).
## Required roles
The required IAM roles are based on whether you are a Python UDF
owner or a Python UDF user.
### UDF owners
A Python UDF owner typically creates or updates a UDF. Additional roles are also
required if you create a Python UDF that references a Cloud resource connection.
This connection is required only if your UDF uses the
[`WITH CONNECTION`](https://docs.cloud.google.com/bigquery/docs/user-defined-functions-python#use-online-service) clause to access
an external service.
To get the permissions that
you need to create or update a Python UDF,
ask your administrator to grant you the
following IAM roles:
- [BigQuery Data Editor](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.dataEditor) (`roles/bigquery.dataEditor`) on the dataset
- [BigQuery Job User](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.jobUser) (`roles/bigquery.jobUser`) on the project
- [BigQuery Connection Admin](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.connectionAdmin) (`roles/bigquery.connectionAdmin`) on the project
For more information about granting roles, see [Manage access to projects, folders, and organizations](https://docs.cloud.google.com/iam/docs/granting-changing-revoking-access).
These predefined roles contain
the permissions required to create or update a Python UDF. To see the exact permissions that are
required, expand the **Required permissions** section:
#### Required permissions
The following permissions are required to create or update a Python UDF:
- Create a Python UDF using the `CREATE FUNCTION` statement: `bigquery.routines.create` on the dataset
- Update a Python UDF using the `CREATE FUNCTION` statement: `bigquery.routines.update` on the dataset
- Run a `CREATE FUNCTION` statement query job: `bigquery.jobs.create` on the project
- [Create a new Cloud resource connection](https://docs.cloud.google.com/bigquery/docs/create-cloud-resource-connection#create-cloud-resource-connection): `bigquery.connections.create` on the project
- Use a connection in the `CREATE FUNCTION` statement: `bigquery.connections.delegate` on the connection
You might also be able to get
these permissions
with [custom roles](https://docs.cloud.google.com/iam/docs/creating-custom-roles) or
other [predefined roles](https://docs.cloud.google.com/iam/docs/roles-overview#predefined).
For more information about roles in BigQuery, see [Predefined
IAM roles](https://docs.cloud.google.com/bigquery/docs/access-control#bigquery).
### UDF users
A Python UDF user invokes a UDF created by someone else. Additional roles are
also required if you invoke a Python UDF that references a Cloud resource
connection.
To get the permissions that
you need to invoke a Python UDF created by someone else,
ask your administrator to grant you the
following IAM roles:
- [BigQuery User](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.user) (`roles/bigquery.user`) on the project
- [BigQuery Data Viewer](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.dataViewer) (`roles/bigquery.dataViewer`) on the dataset
- [BigQuery Connection User](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.connectionUser) (`roles/bigquery.connectionUser`) on the connection
For more information about granting roles, see [Manage access to projects, folders, and organizations](https://docs.cloud.google.com/iam/docs/granting-changing-revoking-access).
These predefined roles contain
the permissions required to invoke a Python UDF created by someone else. To see the exact permissions that are
required, expand the **Required permissions** section:
#### Required permissions
The following permissions are required to invoke a Python UDF created by someone else:
- To run a query job that references a Python UDF: `bigquery.jobs.create` on the project
- To invoke a Python UDF created by someone else: `bigquery.routines.get` on the dataset
- To run a Python UDF that references a Cloud resource connection: `bigquery.connections.use` on the connection
You might also be able to get
these permissions
with [custom roles](https://docs.cloud.google.com/iam/docs/creating-custom-roles) or
other [predefined roles](https://docs.cloud.google.com/iam/docs/roles-overview#predefined).
For more information about roles in BigQuery, see [Predefined
IAM roles](https://docs.cloud.google.com/bigquery/docs/access-control#bigquery).
## Create a persistent Python UDF
Follow these rules when you create a Python UDF:
- The body of the Python UDF must be a quoted string literal that represents
the Python code. To learn more about quoted string literals, see [Formats
for quoted literals](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/lexical#quoted_literals).
- The body of the Python UDF must include a Python function that is used in
the `entry_point` argument in the Python UDF options list.
- A Python runtime version needs to be specified in the `runtime_version`
option. The only supported Python runtime version is `python-3.11`. For a
full list of available options, see the [Function option list](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#function_option_list) for the
`CREATE FUNCTION` statement.
To create a persistent Python UDF, use the [`CREATE FUNCTION` statement](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#create_function_statement)
without the `TEMP` or `TEMPORARY` keyword. To delete a persistent Python UDF,
use the [`DROP FUNCTION`](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#drop_function_statement) statement.
### Example
To see an example of creating a persistent Python UDF, choose on of the
following options:
### Console
The following example creates a persistent Python UDF named `multiplyInputs`
and calls the UDF from within a `SELECT` statement:
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following `CREATE FUNCTION` statement:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.multiplyInputs(x FLOAT64, y FLOAT64)
RETURNS FLOAT64
LANGUAGE python
OPTIONS(runtime_version="python-3.11", entry_point="multiply")
AS r'''
def multiply(x, y):
return x * y
''';
-- Call the Python UDF.
WITH numbers AS
(SELECT 1 AS x, 5 as y
UNION ALL
SELECT 2 AS x, 10 as y
UNION ALL
SELECT 3 as x, 15 as y)
SELECT x, y,
`PROJECT_ID.DATASET_ID`.multiplyInputs(x, y) AS product
FROM numbers;
```
Replace PROJECT_ID.DATASET_ID with your project ID and dataset ID.
3. Click **Run**.
This example produces the following output:
+---+---+---+
| x | y | product |
+---+---+---+
| 1 | 5 | 5.0 |
| 2 | 10 | 20.0 |
| 3 | 15 | 45.0 |
+---+---+---+
### BigQuery DataFrames
The following example uses BigQuery DataFrames to turn a
custom function into a Python UDF:
import bigframes.pandas as bpd
# Set BigQuery DataFrames options
bpd.options.bigquery.project = your_gcp_project_id
bpd.options.bigquery.location = "US"
# BigQuery DataFrames gives you the ability to turn your custom functions
# into a BigQuery Python UDF. One can find more details about the usage and
# the requirements via `help` command.
help(bpd.udf)
# Read a table and inspect the column of interest.
df = bpd.read_gbq("bigquery-public-data.ml_datasets.penguins")
df["body_mass_g"].peek(10)
# Define a custom function, and specify the intent to turn it into a
# BigQuery Python UDF. Let's try a `pandas`-like use case in which we want
# to apply a user defined function to every value in a `Series`, more
# specifically bucketize the `body_mass_g` value of the penguins, which is a
# real number, into a category, which is a string.
@bpd.udf(
dataset=your_bq_dataset_id,
name=your_bq_routine_id,
)
def get_bucket(num: float) -> str:
if not num:
return "NA"
boundary = 4000
return "at_or_above_4000" if num >= boundary else "below_4000"
# Then we can apply the udf on the `Series` of interest via
# `apply` API and store the result in a new column in the DataFrame.
df = df.assign(body_mass_bucket=df["body_mass_g"].apply(get_bucket))
# This will add a new column `body_mass_bucket` in the DataFrame. You can
# preview the original value and the bucketized value side by side.
df[["body_mass_g", "body_mass_bucket"]].peek(10)
# The above operation was possible by doing all the computation on the
# cloud through an underlying BigQuery Python UDF that was created to
# support the user's operations in the Python code.
# The BigQuery Python UDF created to support the BigQuery DataFrames
# udf can be located via a property `bigframes_bigquery_function`
# set in the udf object.
print(f"Created BQ Python UDF: {get_bucket.bigframes_bigquery_function}")
# If you have already defined a custom function in BigQuery, either via the
# BigQuery Google Cloud Console or with the `udf` decorator,
# or otherwise, you may use it with BigQuery DataFrames with the
# `read_gbq_function` method. More details are available via the `help`
# command.
help(bpd.read_gbq_function)
existing_get_bucket_bq_udf = get_bucket.bigframes_bigquery_function
# Here is an example of using `read_gbq_function` to load an existing
# BigQuery Python UDF.
df = bpd.read_gbq("bigquery-public-data.ml_datasets.penguins")
get_bucket_function = bpd.read_gbq_function(existing_get_bucket_bq_udf)
df = df.assign(body_mass_bucket=df["body_mass_g"].apply(get_bucket_function))
df.peek(10)
# Let's continue trying other potential use cases of udf. Let's say we
# consider the `species`, `island` and `sex` of the penguins sensitive
# information and want to redact that by replacing with their hash code
# instead. Let's define another scalar custom function and decorate it
# as a udf. The custom function in this example has external package
# dependency, which can be specified via `packages` parameter.
@bpd.udf(
dataset=your_bq_dataset_id,
name=your_bq_routine_id,
packages=["cryptography"],
)
def get_hash(input: str) -> str:
from cryptography.fernet import Fernet
# handle missing value
if input is None:
input = ""
key = Fernet.generate_key()
f = Fernet(key)
return f.encrypt(input.encode()).decode()
# We can use this udf in another `pandas`-like API `map` that
# can be applied on a DataFrame
df_redacted = df[["species", "island", "sex"]].map(get_hash)
df_redacted.peek(10)
# If the BigQuery routine is no longer needed, we can clean it up
# to free up any cloud quota
session = bpd.get_global_session()
session.bqclient.delete_routine(f"{your_bq_dataset_id}.{your_bq_routine_id}")
## Container build status
When you create a Python UDF using the `CREATE FUNCTION` statement,
BigQuery creates or updates a container image that is based on a
base image. The container is built on the base image using your code and any
specified package dependencies.
Creating the container is a long-running process. The first query after you run
the `CREATE FUNCTION` statement waits for the image build to complete. If there
are no external dependencies, the container image is typically created in
less than a minute.
The size of all Python UDF containers per project and per region is restricted to
a sum total of 10GiB. For more information, see [User-defined function limits
for persistent UDFs](https://docs.cloud.google.com/bigquery/quotas#udf_limits). Your container build fails if
your project has reached the quota.
To see the status of your container build, choose one of the following:
### Console
1. Go to the BigQuery **Studio** page.
[Go to Studio](https://console.cloud.google.com/bigquery)
2. In the left pane, expand your project and then click **Datasets**.
3. Click the link to open the dataset that contains your Python UDF.
4. On the dataset page, click the **Routines** tab.
5. In the **Routine ID** column, click your Python UDF.
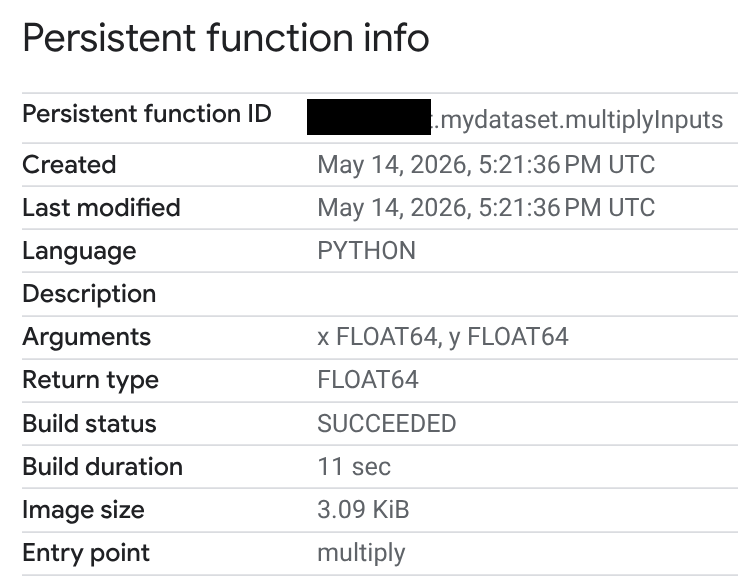
6. On the **Persistent function info** page, you can view the build status,
build duration, and image size. The build status is one of the following:
- In progress
- Succeeded
- Failed
If a build fails, the function information page provides detailed error
messages so you can troubleshoot issues such as syntax errors or problems
installing external packages.
### SQL
To query the build status fields in the `INFORMATION_SCHEMA.ROUTINES` view,
follow these steps:
1. Go to the BigQuery **Studio** page.
[Go to Studio](https://console.cloud.google.com/bigquery)
2. Switch to the query editor or click
**SQL query**.
3. Enter the following query to retrieve the `BUILD_STATUS` fields from the
[`INFORMATION_SCHEMA.ROUTINES` view](https://docs.cloud.google.com/bigquery/docs/information-schema-routines).
The `BUILD_STATUS` column is a
[`STRUCT`](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-types#struct_type)
type in GoogleSQL:
SELECT
build_status.*
FROM
`PROJECT_ID.DATASET_ID`.INFORMATION_SCHEMA.ROUTINES;
Replace PROJECT_ID.DATASET_ID
with your project ID and dataset ID.
The output should look like the following. Error fields are omitted:
+---+---+---+---+
| build_state | build_state_update_time | build_duration_seconds | image_size_bytes |
+---+---+---+---+
| SUCCEEDED | 2026-05-14 17:21:49.736000 UTC | 11 | 3167 |
+---+---+---+---+
### API
View the container build status by using [`RoutineBuildStatus`](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/routines#routinebuildstatus) in the API.
## Create a vectorized Python UDF
You can implement your Python UDF to process a batch of rows instead of a single
row by using vectorization. Vectorization can improve query performance. You can
create a vectorized UDF using either Pandas or Apache Arrow.
To control batching behavior, specify the maximum number of rows in each batch
by using the `max_batching_rows` option in the [`CREATE OR REPLACE FUNCTION`
option list](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#function_option_list). If you specify `max_batching_rows`, BigQuery
determines the number of rows in a batch, up to the `max_batching_rows` limit.
If `max_batching_rows` is not specified, the number of rows to batch is
determined automatically.
### Use Pandas
A vectorized Python UDF has a single [`pandas.DataFrame`](https://pandas.pydata.org/docs/reference/api/pandas.DataFrame.html) argument that must
be annotated. The `pandas.DataFrame` argument has the same number of columns as
the Python UDF parameters defined in the `CREATE FUNCTION` statement. The column
names in the `pandas.DataFrame` argument have the same names as the UDF's
parameters.
Your function needs to return either a [`pandas.Series`](https://pandas.pydata.org/docs/reference/api/pandas.Series.html#pandas.Series) or a single-column
`pandas.DataFrame` with the same number of rows as the input.
The following example creates a vectorized Python UDF named `multiplyInputs`
with two parameters---`x` and `y`:
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following `CREATE FUNCTION` statement:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.multiplyVectorized(x FLOAT64, y FLOAT64)
RETURNS FLOAT64
LANGUAGE python
OPTIONS(runtime_version="python-3.11", entry_point="vectorized_multiply")
AS r'''
import pandas as pd
def vectorized_multiply(df: pd.DataFrame):
return df['x'] * df['y']
''';
```
Replace PROJECT_ID.DATASET_ID
with your project ID and dataset ID.
Calling the UDF is the same as in the previous example.
3. Click
**Run**.
### Use Apache Arrow
The following example uses the Apache Arrow
[`RecordBatch` interface](https://arrow.apache.org/docs/python/generated/pyarrow.RecordBatch.html#pyarrow.RecordBatch). When you use the `RecordBatch` interface, the
function passes a batch of rows of columns of equal length to the entrypoint.
The following example uses Apache Arrow to create a vectorized Python
UDF named `multiplyVectorizedArrow`.
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following `CREATE FUNCTION` statement:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.multiplyVectorizedArrow(x FLOAT64, y FLOAT64)
RETURNS FLOAT64
LANGUAGE python
OPTIONS(
runtime_version="python-3.11",
entry_point="vectorized_multiply_arrow"
)
AS r'''
import pyarrow as pa
import pyarrow.compute as pc
def vectorized_multiply_arrow(batch: pa.RecordBatch):
# Access columns directly from the Arrow RecordBatch
x = batch.column('x')
y = batch.column('y')
# Use pyarrow.compute for vectorized operations
return pc.multiply(x, y)
''';
```
Replace PROJECT_ID.DATASET_ID
with your project ID and dataset ID.
Calling the UDF is the same as in the previous examples.
3. Click
**Run**.
## Call a Python UDF
If you have permission to invoke a Python UDF, then you can call it like any
other function. To use a function defined in a different project, use the fully
qualified name for the function. For example, to call an XML extraction function
named [`cw_xml_extract`](https://github.com/GoogleCloudPlatform/bigquery-utils/blob/master/udfs/community/cw_xml_extract.sqlx)
in another project, complete the following steps.
> [!NOTE]
> **Note:** This example is based on a sample from [bigquery-utils](https://github.com/GoogleCloudPlatform/bigquery-utils).
### Console
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following example:
SELECT
`PROJECT_ID.DATASET_ID`.`cw_xml_extract`(xml, '//title/text()') AS `title`
FROM UNNEST([
STRUCT('''
The Great Gatsby
F. Scott Fitzgerald
''' AS xml),
STRUCT('''
1984
George Orwell
''' AS xml),
STRUCT('''
Brave New World
Aldous Huxley
''' AS xml)
])
3. Click
**Run**.
This example produces the following output:
+---+
| title |
+---+
| The Great Gatsby |
| 1984 |
| Brave New World |
+---+
### BigQuery DataFrames
The following example uses the [BigQuery
DataFrames](https://dataframes.bigquery.dev/index.html)
[`sql_scalar`](https://dataframes.bigquery.dev/reference/api/bigframes.bigquery.sql_scalar.html),
[`read_gbq_function`](https://dataframes.bigquery.dev/reference/api/bigframes.pandas.read_gbq_function.html),
and
[`apply`](https://dataframes.bigquery.dev/reference/api/bigframes.pandas.Series.apply.html)
methods to call a Python UDF:
import textwrap
from typing import Tuple
import bigframes.pandas as bpd
import pandas as pd
import pyarrow as pa
# Set partial ordering mode for BigQuery DataFrames.
bpd.options.bigquery.ordering_mode = "partial"
def call_python_udf(
project_id: str = "your-project-id",
location: str = "US",
) -> Tuple[pd.Series, bpd.Series]:
"""Demonstrates calling a Python UDF using pandas and BigQuery DataFrames."""
# Set the billing project to use for queries. This step is optional, as the
# project can be inferred from your environment in many cases.
bpd.options.bigquery.project = project_id
# Since this example works with local data, set a processing location.
bpd.options.bigquery.location = location
# Create a sample series.
xml_series = pd.Series(
[
textwrap.dedent(
"""
The Great Gatsby
F. Scott Fitzgerald
"""
),
textwrap.dedent(
"""
1984
George Orwell
"""
),
textwrap.dedent(
"""
Brave New World
Aldous Huxley
"""
),
],
dtype=pd.ArrowDtype(pa.string()),
)
df = pd.DataFrame({"xml": xml_series})
# Use the BigQuery Accessor, which is automatically registered on pandas
# DataFrames when you import bigframes. This example uses a function that
# has been deployed to bigquery-utils for demonstration purposes. To use in
# production, deploy the function at
# https://github.com/GoogleCloudPlatform/bigquery-utils/blob/master/udfs/community/cw_xml_extract.sqlx
# to your own project.
titles_pandas = df.bigquery.sql_scalar(
"`bqutil`.`fn`.cw_xml_extract({xml}, '//title/text()')",
)
# Alternatively, call read_gbq_function to get a pointer to the function
# that can be applied on BigQuery DataFrames objects.
cw_xml_extract = bpd.read_gbq_function("bqutil.fn.cw_xml_extract")
xml_bigframes = bpd.read_pandas(xml_series)
xpath_query = "//title/text()"
titles_bigframes = xml_bigframes.apply(cw_xml_extract, args=(xpath_query,))
return titles_pandas, titles_bigframes
# Run the sample:
# titles_pandas, titles_bigframes = call_python_udf("your-project-id", "US")
## Supported Python UDF data types
The following table defines the mapping between BigQuery data
types, Python data types, and Pandas data types:
| BigQuery data type | Python built-in data type used by standard UDF | Pandas data type used by vectorized UDF | PyArrow data type used for ARRAY and STRUCT in vectorized UDF |
|---|---|---|---|
| `BOOL` | `bool` | `BooleanDtype` | `DataType(bool)` |
| `INT64` | `int` | `Int64Dtype` | `DataType(int64)` |
| `FLOAT64` | `float` | `FloatDtype` | `DataType(double)` |
| `STRING` | `str` | `StringDtype` | `DataType(string)` |
| `BYTES` | `bytes` | `binary[pyarrow]` | `DataType(binary)` |
| `TIMESTAMP` | Function parameter: `datetime.datetime` (with UTC timezone set) Function return value: `datetime.datetime` (with any timezone set) | Function parameter: `timestamp[us, tz=UTC][pyarrow]` Function return value: `timestamp[us, tz=*][pyarrow]\(any timezone\)` | `TimestampType(timestamp[us])`, with timezone |
| `DATE` | `datetime.date` | `date32[pyarrow]` | `DataType(date32[day])` |
| `TIME` | `datetime.time` | `time64[pyarrow]` | `Time64Type(time64[us])` |
| `DATETIME` | `datetime.datetime` (without timezone) | `timestamp[us][pyarrow]` | `TimestampType(timestamp[us])`, without timezone |
| `ARRAY` | `list` | `list<...>[pyarrow]`, where the element data type is a [`pandas.ArrowDtype`](https://pandas.pydata.org/docs/reference/api/pandas.ArrowDtype.html) | `ListType` |
| `STRUCT` | `dict` | `struct<...>[pyarrow]`, where the field data type is a [`pandas.ArrowDtype`](https://pandas.pydata.org/docs/reference/api/pandas.ArrowDtype.html) | `StructType` |
## Supported runtime versions
BigQuery Python UDFs support the `python-3.11` runtime. This
Python version includes some additional pre-installed packages. For system
libraries, check the runtime base image.
| Runtime version | Python version | Includes |
|---|---|---|
| python-3.11 | Python 3.11 | numpy 1.26.3 pyarrow 14.0.2 pandas 2.1.4 python-dateutil 2.8.2 absl-py 2.0.0 pytz 2023.3.post1 tzdata 2023.4 six 1.16.0 |
## Use third-party packages
You can use the [`CREATE FUNCTION` option list](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#function_option_list) to use modules other than
those provided by the [Python standard library](https://docs.python.org/3/library/index.html) and pre-installed packages.
You can install packages from the [Python Package Index (PyPI)](https://pypi.org/), or you can
import Python files from Cloud Storage.
### Install a package from the Python package index
When you install a package, you must provide the package name, and you can
optionally provide the package version using [Python package version
specifiers](https://packaging.python.org/en/latest/specifications/version-specifiers).
If the package is in the runtime, that package is used unless a particular
version is specified in the `CREATE FUNCTION` option list. If a package version
is not specified, and the package isn't in the runtime, the latest available
version is used. Only packages with [the wheels binary format](https://peps.python.org/pep-0427) are
supported.
The following example shows you how to create a Python UDF that installs the
`scipy` package using the `CREATE OR REPLACE FUNCTION` option list:
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following `CREATE FUNCTION` statement:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.area(radius FLOAT64)
RETURNS FLOAT64 LANGUAGE python
OPTIONS (entry_point='area_handler', runtime_version='python-3.11', packages=['scipy==1.15.3'])
AS r"""
import scipy
def area_handler(radius):
return scipy.constants.pi*radius*radius
""";
SELECT `PROJECT_ID.DATASET_ID`.area(4.5);
```
Replace PROJECT_ID.DATASET_ID
with your project ID and dataset ID.
3. Click
**Run**.
### Import additional Python files as libraries
You can extend your Python UDFs using the [Function option list](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#function_option_list) by importing
Python files from Cloud Storage.
> [!NOTE]
> **Note:** The user that creates the UDF needs the [`storage.objects.get`](https://docs.cloud.google.com/storage/docs/access-control/iam-permissions#objects) permission on the Cloud Storage bucket.
In your UDF's Python code, you can import the Python files from
Cloud Storage as modules by using the import statement followed by the
path to the Cloud Storage object. For example, if you are importing
`gs://BUCKET_NAME/path/to/lib1.py`, then your import statement would be `import
path.to.lib1`.
The Python filename needs to be a Python identifier. Each `folder` name in the
object name (after the `/`) should be a valid Python identifier. Within the
ASCII range (U+0001..U+007F), the following characters can be used in
identifiers:
- Uppercase and lowercase letters A through Z.
- Underscores.
- The digits zero through nine, but a number cannot appear as the first character in the identifier.
The following example shows you how to create a Python UDF that imports the
`lib1.py` client library package from a Cloud Storage bucket named
`my_bucket`:
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following `CREATE FUNCTION` statement:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.myFunc(a FLOAT64, b STRING)
RETURNS STRING LANGUAGE python
OPTIONS (
entry_point='compute', runtime_version='python-3.11',
library=['gs://BUCKET_NAME/PATH/lib1.py'])
AS r"""
import path.to.lib1 as lib1
def compute(a, b):
# doInterestingStuff is a function defined in
# gs://BUCKET_NAME/PATH/lib1.py
return lib1.doInterestingStuff(a, b);
""";
```
Replace the following:
- PROJECT_ID: your project ID.
- DATASET_ID: your dataset ID.
- BUCKET_NAME: the name of the Cloud Storage bucket that contains `lib1.py`.
- PATH: the path to the Cloud Storage bucket.
3. Click
**Run**.
## Configure container limits for Python UDFs
You can use the [`CREATE FUNCTION` option list](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#function_option_list) to specify CPU, memory, and
container request concurrency limits for containers that run Python UDFs.
By default, containers are allocated the following resources:
- The memory allocated is `512Mi`.
- The CPU allocated is `1.0` vCPU.
- The container request concurrency limit is `80`.
> [!NOTE]
> **Note:** If you set CPU allocation to less than `1.0` vCPU, and you don't set the container request concurrency limit, the container request concurrency is set to `1` at run time.
The following example creates a Python UDF using the `CREATE FUNCTION` option
list to specify container limits:
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following `CREATE FUNCTION` statement:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.square_area(length FLOAT64)
RETURNS FLOAT64 LANGUAGE python
OPTIONS (entry_point='square_area', runtime_version='python-3.11',
container_memory='CONTAINER_MEMORY', container_cpu=CONTAINER_CPU, container_request_concurrency=CONTAINER_REQUEST_CONCURRENCY)
AS r"""
def square_area(length):
return length*length
""";
SELECT `PROJECT_ID.DATASET_ID`.square_area(4.5);
```
Replace the following:
- PROJECT_ID.DATASET_ID: your project ID and dataset ID.
- CONTAINER_MEMORY: the memory value in the following format: ``. The unit must be one of these values: `Mi` (MiB), `M` (MB), `Gi` (GiB), or `G` (GB). For example, `2Gi`.
- CONTAINER_CPU: the CPU value. Python UDFs support fractional CPU values between `0.33` and `1.0` and non-fractional CPU values of `1`, `2`, and `4`.
- CONTAINER_REQUEST_CONCURRENCY: the maximum number of concurrent requests per Python UDF container instance. The value must be an integer from `1` to `1000`.
3. Click
**Run**.
### Supported CPU values
Python UDFs support fractional CPU values between `0.33` and `1.0` and
non-fractional CPU values of `1`, `2`, and `4`. Containers that run Python UDFs
can be configured up to [`4` vCpu](https://docs.cloud.google.com/bigquery/docs/user-defined-functions-python#configure-container-limits). The default value is `1.0`. Fractional
input values are rounded to two decimal places before they're applied to the
container.
### Supported memory values
Python UDF containers support memory values in the following format:
``. The unit must be one of these values: `Mi`, `M`, `Gi`,
`G`. The minimum amount of memory you can configure is `256Mi`. The maximum
amount of memory you can configure is `16Gi`.
Based on the memory value you choose, you must also specify an appropriate
amount of CPU. The following table shows the minimum and maximum CPU values for
each memory value:
| Memory | Minimum CPU | Maximum CPU |
|---|---|---|
| `256Mi` to `512Mi` | `0.33` | `2` |
| Greater than `512Mi` and less than or equal to `1Gi` | `0.5` | `2` |
| Greater than `1Gi` and less than `2Gi` | `1` | `2` |
| `2Gi` to `4Gi` | `1` | `4` |
| Greater than `4Gi` and up to `8Gi` | `2` | `4` |
| Greater than `8Gi` and up to `16Gi` | `4` | `4` |
Alternatively, if you've determined the amount of CPU you're allocating, you can
use the following table to determine the appropriate memory range:
| CPU | Minimum memory | Maximum memory |
|---|---|---|
| Less than `0.5` | `256Mi` | `512Mi` |
| `0.5` to less than `1` | `256Mi` | `1Gi` |
| `1` | `256Mi` | `4Gi` |
| `2` | `256Mi` | `8Gi` |
| `4` | `2Gi` | `16Gi` |
## Call Google Cloud or online services in Python code
A Python UDF accesses a Google Cloud service or an external service by using the
[Cloud resource connection](https://docs.cloud.google.com/bigquery/docs/create-cloud-resource-connection) service account. The connection's service account
must be granted permissions to access the service. The permissions required vary
depending on the service that is accessed and the APIs that are called from your
Python code.
If you create a Python UDF without using a Cloud resource connection, the
function is executed in an environment that blocks network access. If your UDF
accesses online services, you must create the UDF with a Cloud resource
connection. If you don't, the UDF is blocked from accessing the network until an
internal connection timeout is reached. When you use a Cloud resource
connection, implement the following:
- Timeouts. When you make network calls within your Python UDF, always include
a reasonable timeout. This prevents the UDF from hanging indefinitely if the
external service is slow to respond or is unreachable.
- Use Error Handling. Wrap your network call code in a `try...except` block to
gracefully handle potential errors, such as connection errors, timeouts, or
HTTP failure status codes. This allows your UDF to return a meaningful error
or a fallback value instead of causing the query to fail or stop responding.
The following example shows you how to access the Cloud Translation service
from a Python UDF. This example has two projects---a project named
`my_query_project` where you create the UDF and the Cloud resource connection,
and a project where you are running the Cloud Translation named
`my_translate_project`.
### Create a Cloud resource connection
First, you create a Cloud resource connection in `my_query_project`. To create
the cloud resource connection, follow these steps.
Select one of the following options:
### Console
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the left pane, click
**Explorer**:

If you don't see the left pane, click
**Expand left pane** to open the pane.
3. In the **Explorer** pane, expand your project name, and then click
**Connections**.
4. On the **Connections** page, click **Create connection**.
5. For **Connection type** , choose **Vertex AI remote models, remote
functions, BigLake and Spanner (Cloud Resource)**.
6. In the **Connection ID** field, enter a name for your connection.
7. For **Location type**, select a location for your connection. The
connection should be colocated with your other resources such as
datasets.
8. Click **Create connection**.
9. Click **Go to connection**.
10. In the **Connection info** pane, copy the service account ID for use in
a later step.
### SQL
Use the [`CREATE CONNECTION` statement](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#create_connection_statement):
1. In the Google Cloud console, go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following statement:
```googlesql
CREATE CONNECTION [IF NOT EXISTS] `CONNECTION_NAME`
OPTIONS (
connection_type = "CLOUD_RESOURCE",
friendly_name = "FRIENDLY_NAME",
description = "DESCRIPTION"
);
```
Replace the following:
- `CONNECTION_NAME`: the name of the connection in either the `PROJECT_ID.LOCATION.CONNECTION_ID`, `LOCATION.CONNECTION_ID`, or `CONNECTION_ID` format. If the project or location are omitted, then they are inferred from the project and location where the statement is run.
- `FRIENDLY_NAME` (optional): a descriptive name for the connection.
- `DESCRIPTION` (optional): a description of the connection.
3. Click **Run**.
For more information about how to run queries, see [Run an interactive query](https://docs.cloud.google.com/bigquery/docs/running-queries#queries).
### bq
1. In a command-line environment, create a connection:
```bash
bq mk --connection --location=REGION --project_id=PROJECT_ID \
--connection_type=CLOUD_RESOURCE CONNECTION_ID
```
The `--project_id` parameter overrides the default project.
Replace the following:
- `REGION`: your [connection region](https://docs.cloud.google.com/bigquery/docs/locations#supported_locations)
- `PROJECT_ID`: your Google Cloud project ID
- `CONNECTION_ID`: an ID for your connection
When you create a connection resource, BigQuery creates a
unique system service account and associates it with the connection.
**Troubleshooting** : If you get the following connection error,
[update the Google Cloud SDK](https://docs.cloud.google.com/sdk/docs/quickstart):
```
Flags parsing error: flag --connection_type=CLOUD_RESOURCE: value should be one of...
```
2. Retrieve and copy the service account ID for use in a later
step:
```bash
bq show --connection PROJECT_ID.REGION.CONNECTION_ID
```
The output is similar to the following:
```
name properties
1234.REGION.CONNECTION_ID {"serviceAccountId": "connection-1234-9u56h9@gcp-sa-bigquery-condel.iam.gserviceaccount.com"}
```
### Python
Before trying this sample, follow the Python setup instructions in the
[BigQuery quickstart using
client libraries](https://docs.cloud.google.com/bigquery/docs/quickstarts/quickstart-client-libraries).
For more information, see the
[BigQuery Python API
reference documentation](https://docs.cloud.google.com/python/docs/reference/bigquery/latest).
To authenticate to BigQuery, set up Application Default Credentials.
For more information, see
[Set up authentication for client libraries](https://docs.cloud.google.com/bigquery/docs/authentication#client-libs).
import google.api_core.exceptions
from google.cloud import https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest
client = https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest.https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest/google.cloud.bigquery_connection_v1.services.connection_service.ConnectionServiceClient.html()
def create_connection(
project_id: str,
location: str,
connection_id: str,
):
"""Creates a BigQuery connection to a Cloud Resource.
Cloud Resource connection creates a service account which can then be
granted access to other Google Cloud resources for federated queries.
Args:
project_id: The Google Cloud project ID.
location: The location of the connection (for example, "us-central1").
connection_id: The ID of the connection to create.
"""
parent = client.https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest/google.cloud.bigquery_connection_v1.services.connection_service.ConnectionServiceClient.html#google_cloud_bigquery_connection_v1_services_connection_service_ConnectionServiceClient_common_location_path(project_id, location)
connection = https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest.https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest/google.cloud.bigquery_connection_v1.types.Connection.html(
friendly_name="Example Connection",
description="A sample connection for a Cloud Resource.",
cloud_resource=https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest.https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest/google.cloud.bigquery_connection_v1.types.CloudResourceProperties.html(),
)
try:
created_connection = client.https://docs.cloud.google.com/python/docs/reference/bigqueryconnection/latest/google.cloud.bigquery_connection_v1.services.connection_service.ConnectionServiceClient.html#google_cloud_bigquery_connection_v1_services_connection_service_ConnectionServiceClient_create_connection(
parent=parent, connection_id=connection_id, connection=connection
)
print(f"Successfully created connection: {created_connection.name}")
print(f"Friendly name: {created_connection.friendly_name}")
print(
f"Service Account: {created_connection.cloud_resource.service_account_id}"
)
except google.api_core.exceptions.AlreadyExists:
print(f"Connection with ID '{connection_id}' already exists.")
print("Please use a different connection ID.")
except Exception as e:
print(f"An unexpected error occurred while creating the connection: {e}")
### Node.js
Before trying this sample, follow the Node.js setup instructions in the
[BigQuery quickstart using
client libraries](https://docs.cloud.google.com/bigquery/docs/quickstarts/quickstart-client-libraries).
For more information, see the
[BigQuery Node.js API
reference documentation](https://googleapis.dev/nodejs/bigquery/latest/index.html).
To authenticate to BigQuery, set up Application Default Credentials.
For more information, see
[Set up authentication for client libraries](https://docs.cloud.google.com/bigquery/docs/authentication#client-libs).
const {ConnectionServiceClient} =
require('https://docs.cloud.google.com/nodejs/docs/reference/bigquery-connection/latest/overview.html').v1;
const {status} = require('@grpc/grpc-js');
const client = new https://docs.cloud.google.com/nodejs/docs/reference/bigquery-connection/latest/overview.html();
/**
* Creates a new BigQuery connection to a Cloud Resource.
*
* A Cloud Resource connection creates a service account that can be granted access
* to other Google Cloud resources.
*
* @param {string} projectId The Google Cloud project ID. for example, 'example-project-id'
* @param {string} location The location of the project to create the connection in. for example, 'us-central1'
* @param {string} connectionId The ID of the connection to create. for example, 'example-connection-id'
*/
async function createConnection(projectId, location, connectionId) {
const parent = client.locationPath(projectId, location);
const connection = {
friendlyName: 'Example Connection',
description: 'A sample connection for a Cloud Resource',
// The service account for this cloudResource will be created by the API.
// Its ID will be available in the response.
cloudResource: {},
};
const request = {
parent,
connectionId,
connection,
};
try {
const [response] = await client.createConnection(request);
console.log(`Successfully created connection: ${response.name}`);
console.log(`Friendly name: ${response.friendlyName}`);
console.log(`Service Account: ${response.cloudResource.serviceAccountId}`);
} catch (err) {
if (err.code === status.ALREADY_EXISTS) {
console.log(`Connection '${connectionId}' already exists.`);
} else {
console.error(`Error creating connection: ${err.message}`);
}
}
}
### Java
Before trying this sample, follow the Java setup instructions in the
[BigQuery quickstart using
client libraries](https://docs.cloud.google.com/bigquery/docs/quickstarts/quickstart-client-libraries).
For more information, see the
[BigQuery Java API
reference documentation](https://docs.cloud.google.com/java/docs/reference/google-cloud-bigquery/latest/overview).
To authenticate to BigQuery, set up Application Default Credentials.
For more information, see
[Set up authentication for client libraries](https://docs.cloud.google.com/bigquery/docs/authentication#client-libs).
import com.google.api.gax.rpc.https://docs.cloud.google.com/java/docs/reference/gax/latest/com.google.api.gax.rpc.AlreadyExistsException.html;
import com.google.api.gax.rpc.https://docs.cloud.google.com/java/docs/reference/gax/latest/com.google.api.gax.rpc.ApiException.html;
import com.google.cloud.bigquery.connection.v1.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CloudResourceProperties.html;
import com.google.cloud.bigquery.connection.v1.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html;
import com.google.cloud.bigquery.connection.v1.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CreateConnectionRequest.html;
import com.google.cloud.bigquery.connection.v1.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.LocationName.html;
import com.google.cloud.bigqueryconnection.v1.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigqueryconnection.v1.ConnectionServiceClient.html;
import java.io.IOException;
public class CreateConnection {
/**
* Creates a BigQuery connection to a Cloud Resource. A Cloud Resource connection provisions a
* service account that can be granted access to other Google Cloud resources for federated
* queries.
*
* @param projectId The Google Cloud project ID (for example, "example-project-id").
* @param location The geographic location of the connection (for example, "us-central1").
* @param connectionId The ID of the connection to create (for example, "example-connection-id").
*/
public static void createConnection(String projectId, String location, String connectionId) {
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.LocationName.html parent = https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.LocationName.html.of(projectId, location);
// CloudResourceProperties provisions a managed Google Cloud service account on creation.
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CloudResourceProperties.html cloudResourceProperties = https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CloudResourceProperties.html.newBuilder().build();
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html connection =
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html.newBuilder()
.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.Builder.html#com_google_cloud_bigquery_connection_v1_Connection_Builder_setFriendlyName_java_lang_String_("Example Connection")
.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.Builder.html#com_google_cloud_bigquery_connection_v1_Connection_Builder_setDescription_java_lang_String_("Cloud Resource connection for federated queries.")
.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.Builder.html#com_google_cloud_bigquery_connection_v1_Connection_Builder_setCloudResource_com_google_cloud_bigquery_connection_v1_CloudResourceProperties_(cloudResourceProperties)
.build();
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CreateConnectionRequest.html request =
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CreateConnectionRequest.html.newBuilder()
.setParent(parent.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.LocationName.html#com_google_cloud_bigquery_connection_v1_LocationName_toString__())
.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.CreateConnectionRequest.Builder.html#com_google_cloud_bigquery_connection_v1_CreateConnectionRequest_Builder_setConnectionId_java_lang_String_(connectionId)
.setConnection(connection)
.build();
try (https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigqueryconnection.v1.ConnectionServiceClient.html client = https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigqueryconnection.v1.ConnectionServiceClient.html.create()) {
https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html response = client.createConnection(request);
System.out.printf("Successfully created connection: %s%n", response.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html#com_google_cloud_bigquery_connection_v1_Connection_getName__());
System.out.printf("Friendly name: %s%n", response.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html#com_google_cloud_bigquery_connection_v1_Connection_getFriendlyName__());
System.out.printf(
"Service Account: %s%n", response.https://docs.cloud.google.com/java/docs/reference/google-cloud-bigqueryconnection/latest/com.google.cloud.bigquery.connection.v1.Connection.html#com_google_cloud_bigquery_connection_v1_Connection_getCloudResource__().getServiceAccountId());
} catch (https://docs.cloud.google.com/java/docs/reference/gax/latest/com.google.api.gax.rpc.AlreadyExistsException.html err) {
System.err.printf(
"error: connection '%s' already exists in location '%s' for project '%s': %s%n",
connectionId, location, projectId, err.https://docs.cloud.google.com/java/docs/reference/gax/latest/com.google.api.gax.rpc.ErrorDetails.html#com_google_api_gax_rpc_ErrorDetails__T_getMessage_java_lang_Class_T__());
} catch (https://docs.cloud.google.com/java/docs/reference/gax/latest/com.google.api.gax.rpc.ApiException.html | IOException err) {
System.err.printf(
"error: failed to create connection '%s' in location '%s' for project '%s': %s%n",
connectionId, location, projectId, err.https://docs.cloud.google.com/java/docs/reference/gax/latest/com.google.api.gax.rpc.ErrorDetails.html#com_google_api_gax_rpc_ErrorDetails__T_getMessage_java_lang_Class_T__());
}
}
### Terraform
Use the
[`google_bigquery_connection`](https://registry.terraform.io/providers/hashicorp/google/latest/docs/resources/bigquery_connection)
resource.
> [!NOTE]
> **Note:** To create BigQuery objects using Terraform, you must enable the [Cloud Resource Manager API](https://docs.cloud.google.com/resource-manager/reference/rest).
To authenticate to BigQuery, set up Application Default
Credentials. For more information, see
[Set up authentication for client libraries](https://docs.cloud.google.com/bigquery/docs/authentication#client-libs).
The following example creates a Cloud resource connection named
`my_cloud_resource_connection` in the `US` region:
# This queries the provider for project information.
data "google_project" "default" {}
# This creates a cloud resource connection in the US region named my_cloud_resource_connection.
# Note: The cloud resource nested object has only one output field - serviceAccountId.
resource "google_bigquery_connection" "default" {
connection_id = "my_cloud_resource_connection"
project = data.google_project.default.project_id
location = "US"
cloud_resource {}
}
To apply your Terraform configuration in a Google Cloud project, complete the steps in the
following sections.
## Prepare Cloud Shell
1. Launch [Cloud Shell](https://shell.cloud.google.com/).
2. Set the default Google Cloud project
where you want to apply your Terraform configurations.
You only need to run this command once per project, and you can run it in any directory.
```
export GOOGLE_CLOUD_PROJECT=PROJECT_ID
```
Environment variables are overridden if you set explicit values in the Terraform
configuration file.
## Prepare the directory
Each Terraform configuration file must have its own directory (also
called a *root module*).
1. In [Cloud Shell](https://shell.cloud.google.com/), create a directory and a new file within that directory. The filename must have the `.tf` extension---for example `main.tf`. In this tutorial, the file is referred to as `main.tf`.
```
mkdir DIRECTORY && cd DIRECTORY && touch main.tf
```
2. If you are following a tutorial, you can copy the sample code in each section or step.
Copy the sample code into the newly created `main.tf`.
Optionally, copy the code from GitHub. This is recommended
when the Terraform snippet is part of an end-to-end solution.
3. Review and modify the sample parameters to apply to your environment.
4. Save your changes.
5. Initialize Terraform. You only need to do this once per directory.
```
terraform init
```
Optionally, to use the latest Google provider version, include the `-upgrade`
option:
```
terraform init -upgrade
```
## Apply the changes
1. Review the configuration and verify that the resources that Terraform is going to create or update match your expectations:
```
terraform plan
```
Make corrections to the configuration as necessary.
2. Apply the Terraform configuration by running the following command and entering `yes` at the prompt:
```
terraform apply
```
Wait until Terraform displays the "Apply complete!" message.
3. [Open your Google Cloud project](https://console.cloud.google.com/) to view the results. In the Google Cloud console, navigate to your resources in the UI to make sure that Terraform has created or updated them.
> [!NOTE]
> **Note:** Terraform samples typically assume that the required APIs are enabled in your Google Cloud project.
### Grant access to the connection's service account
You need the service account ID you copied previously when you configure
permissions for the connection. When you create a connection resource,
BigQuery creates a unique system service account and associates
it with the connection.
To grant the Cloud resource connection service account access to your projects,
grant the service account the [Service usage consumer role](https://docs.cloud.google.com/iam/docs/roles-permissions/serviceusage#serviceusage.serviceUsageConsumer)
(`roles/serviceusage.serviceUsageConsumer`) in `my_query_project` and the [Cloud
Translation API user role](https://docs.cloud.google.com/translate/docs/access-control#cloudtranslate.user) (`roles/cloudtranslate.user`) in
`my_translate_project`.
### Console
1. Go to the **IAM** page.
[Go to IAM](https://console.cloud.google.com/project/_/iam-admin)
2. Verify that `my_query_project` is selected.
3. Click **Grant Access**.
4. In the **New principals** field, enter the Cloud resource connection's
service account ID that you copied previously.
5. In the **Select a role** field, choose **Service usage** , and then select
**Service usage consumer**.
6. Click **Save**.
7. In the project selector, choose **`my_translate_project`**.
8. Go to the **IAM** page.
[Go to IAM](https://console.cloud.google.com/project/_/iam-admin)
9. Click **Grant Access**.
10. In the **New principals** field, enter the Cloud resource connection's
service account ID that you copied previously.
11. In the **Select a role** field, choose **Cloud translation** , and then
select **Cloud Translation API user**.
12. Click **Save**.
### SQL
Use the [`GRANT` statement](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-control-language#grant_statement)
to grant the [Service usage consumer role](https://docs.cloud.google.com/iam/docs/roles-permissions/serviceusage#serviceusage.serviceUsageConsumer) (`roles/serviceusage.serviceUsageConsumer`)
to the service account in `my_query_project`:
1. In the Google Cloud console, go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following statement:
```googlesql
GRANT `roles/serviceusage.serviceUsageConsumer`
ON PROJECT `my_query_project`
TO "connection:SERVICE_ACCOUNT_ID";
```
Replace `SERVICE_ACCOUNT_ID` with the service
account ID you copied previously.
3. Click **Run**.
For more information about how to run queries, see [Run an interactive query](https://docs.cloud.google.com/bigquery/docs/running-queries#queries).
Use the [`GRANT` statement](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-control-language#grant_statement)
to grant the [Cloud Translation API user role](https://docs.cloud.google.com/translate/docs/access-control#cloudtranslate.user) (`roles/cloudtranslate.user`)
in `my_translate_project`:
1. In the Google Cloud console, go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following statement:
```googlesql
GRANT `roles/cloudtranslate.user`
ON PROJECT `my_translate_project`
TO "connection:SERVICE_ACCOUNT_ID";
```
Replace `SERVICE_ACCOUNT_ID` with the service
account ID you copied previously.
3. Click **Run**.
For more information about how to run queries, see [Run an interactive query](https://docs.cloud.google.com/bigquery/docs/running-queries#queries).
### Create a Python UDF that calls the Cloud Translation service
In `my_query_project`, create a Python UDF that calls the Cloud Translation
service using your Cloud resource connection.
1. In the Google Cloud console, go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. Enter the following `CREATE FUNCTION` statement in the query editor:
```sql
CREATE FUNCTION `PROJECT_ID.DATASET_ID`.translate_to_es(x STRING)
RETURNS STRING LANGUAGE python
WITH CONNECTION `PROJECT_ID.REGION.CONNECTION_ID`
OPTIONS (entry_point='do_translate', runtime_version='python-3.11', packages=['google-cloud-translate>=3.11', 'google-api-core'])
AS r"""
from google.api_core.retry import Retry
from google.cloud import translate
project = "my_translate_project"
translate_client = translate.TranslationServiceClient()
def do_translate(x : str) -> str:
response = translate_client.translate_text(
request={
"parent": f"projects/PROJECT_ID/locations/us-central1",
"contents": [x],
"target_language_code": "es",
"mime_type": "text/plain",
},
retry=Retry(),
)
return response.translations[0].translated_text
""";
-- Call the UDF.
WITH text_table AS
(SELECT "Hello" AS text
UNION ALL
SELECT "Good morning" AS text
UNION ALL
SELECT "Goodbye" AS text)
SELECT text,
`PROJECT_ID.DATASET_ID`.translate_to_es(text) AS translated_text
FROM text_table;
```
Replace the following:
- `PROJECT_ID`: the project ID.
- `DATASET_ID`: the dataset ID.
- `REGION`: your connection's region.
- `CONNECTION_ID`: the connection ID.
3. Click
**Run**.
The output should look like the following:
+---+---+
| text | translated_text |
+---+---+
| Hello | Hola |
| Good morning | Buen dia |
| Goodbye | Adios |
+---+---+
### Create a Python UDF with volume mounts
> [!WARNING]
>
> **Preview**
>
>
> This product or feature is
>
> subject to the "Pre-GA Offerings Terms" in the General Service Terms section
> of the [Service Specific
> Terms](https://docs.cloud.google.com/terms/service-terms#1).
>
> Pre-GA products and features are available "as is" and might have limited support.
>
> For more information, see the
> [launch stage descriptions](https://cloud.google.com/products/#product-launch-stages).
> [!NOTE]
> **Note:** To provide feedback or ask questions that are related to this Preview feature, contact [bq-python-udf-feedback@google.com](mailto:bq-python-udf-feedback@google.com).
If you have volume mount dependency files in a Cloud Storage bucket,
you can include them in your Python UDF using the `volume_mounts` parameter.
#### Before you begin
Before you create a Python UDF with volume mounts, do the following:
- [Create a Cloud resource connection](https://docs.cloud.google.com/bigquery/docs/create-cloud-resource-connection) in the same region that you plan to create the Python UDF.
- Grant your service account the [required Identity and Access Management roles](https://docs.cloud.google.com/bigquery/docs/user-defined-functions-python#required_roles_vm).
##### Required roles
To ensure that your connection service account has the necessary
permissions to create a Python UDF with volume mounts,
ask your administrator to grant the
[Storage Object Viewer](https://docs.cloud.google.com/iam/docs/roles-permissions/storage#storage.objectViewer) (`roles/storage.objectViewer`) IAM role to your connection service account on your Cloud Storage bucket. As a security best practice, restrict this role through prefix matching to only target the subfolder where you are creating the volume mount---for example, with the `resource.name.startsWith("projects/_/buckets/BUCKET_NAME/objects/SUBFOLDER_NAME/"))` condition. This best practice ensures that the UDF container can't read unauthorized objects or subfolders in the bucket.
**Important:** You must grant this role to your connection service account, *not* to your user account. Failure to grant the role to the correct principal might result in permission errors. For more information about granting roles, see [Manage access to projects, folders, and organizations](https://docs.cloud.google.com/iam/docs/granting-changing-revoking-access).
This predefined role contains
the permissions required to create a Python UDF with volume mounts. To see the exact permissions that are
required, expand the **Required permissions** section:
#### Required permissions
The following permissions are required to create a Python UDF with volume mounts:
- `storage.objects.get` on your Cloud Storage folder.
- `storage.objects.list` on your Cloud Storage folder.
Your administrator might also be able to give your connection service account
these permissions
with [custom roles](https://docs.cloud.google.com/iam/docs/creating-custom-roles) or
other [predefined roles](https://docs.cloud.google.com/iam/docs/roles-overview#predefined).
#### Volume mounts example
The following statement creates a Python UDF with volume mounts on the
`gs://my-udf-deps-bucket` bucket:
```sql
CREATE OR REPLACE FUNCTION `my-project.my-dataset`.my-udf-name(x STRING)
RETURNS STRING
LANGUAGE python
WITH CONNECTION `my-project`.us-central1.`my-connection`
OPTIONS (
entry_point="python_func",
runtime_version="python-3.11",
volume_mounts=['{"source_path": "gs://my-udf-deps-bucket", "mount_path": "/mnt"}'])
AS r"""
# User needs to add the mount_path to sys.path in their code
import sys
sys.path.append('/mnt')
# common-utils is a direct subfolder of gs://my-udf-deps-bucket
from common-utils import string_helpers
def python_func(x):
suffix = string_helpers.functionA()
return x + suffix
""";
```
You can also create a function with volume mounts on a specific folder in the
bucket. To do so in the previous example, replace `gs://my-udf-deps-bucket` with
`gs://my-udf-deps-bucket/common-utils`.
#### Volume mounts formatting
Mount paths must adhere to the following formatting:
- Path names must start with the forward slash (`/`) character.
- Path names can't end with the forward slash (`/`) character.
- Path names must be at most 256 characters.
- Paths can't be within subdirectories of the `/dev`, `/opt`, `/proc`, `/root`, `/srv`, `/sys`, `/udf_modules`, `/user_site_packages`, or `/usr` folders.
- Path components can't be empty.
- Subdirectories within the path can't contain the period (`.`) character.
#### Volume mounts limitations
The following limitations apply to Python UDFs with volume mounts:
- Using volume mounts doesn't provide managed version control. If there is a change in the Cloud Storage resource, it can be reflected in the UDF automatically, even during a query run and without updating the function.
- Volume mounted files are read-only.
- UDFs can have a maximum of 10 volume mounts.
- If defined, container memory must be at least 512 MiB.
- If defined, container CPU must be at least 1.0 CPU.
- There must be a strict one-to-one map between each source path and mount path.
## Use VPC Service Controls
Python UDFs inherit the VPC Service Controls perimeter of the project that runs
the query job. This perimeter protects your jobs from data exfiltration, and it
ensures that service interactions are secure.
When you invoke a Python UDF inside the VPC Service Controls perimeter, it has
the following network connectivity:
- Python UDFs that don't use a Cloud resource connection are fully isolated. All outbound traffic is blocked.
- Python UDFs that use a Cloud resource connection are blocked from public internet access. Python UDFs can only access Google Cloud services that support VPC Service Controls. Outbound traffic to any destination other than `restricted.googleapis.com` is blocked.
### Configure Python UDFs to access Google Cloud services securely within VPC Service Controls
To access Google Cloud services from Python UDFs while enforcing
VPC Service Controls, follow these steps:
1. Create the Python UDF using the [CREATE FUNCTION statement's](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#create_function_statement) `WITH CONNECTION` clause.
2. Include the BigQuery project where the query job runs and the target service project in the service perimeter. Alternatively, configure a [perimeter bridge](https://docs.cloud.google.com/vpc-service-controls/docs/create-perimeter-bridges).
3. Add the target service API to the perimeter configuration. For example, `translate.googleapis.com` if you're connecting to the Cloud Translation API.
For more details on configuring a VPC Service Controls perimeter, see:
- [VPC Service Controls for BigQuery](https://docs.cloud.google.com/bigquery/docs/vpc-sc)
- [Overview of VPC Service Controls](https://docs.cloud.google.com/vpc-service-controls/docs/overview)
### Configure VPC Service Controls settings for volume mounts
If your Python UDF includes volume mounts, do the following:
- If the BigQuery query execution project is protected by a perimeter, create an [egress rule](https://docs.cloud.google.com/vpc-service-controls/docs/ingress-egress-rules) that allows outbound calls to `storage.googleapis.com` targeting the Cloud Storage bucket owner's project.
- If the Cloud Storage bucket owner's project is protected by a perimeter, create an [ingress rule](https://docs.cloud.google.com/vpc-service-controls/docs/ingress-egress-rules) that allows inbound calls to `storage.googleapis.com` targeting the Cloud Storage bucket owner's project from the BigQuery connection owner project or connection service account.
- If the BigQuery query execution project and the Cloud Storage bucket owner's project reside within the same perimeter, no ingress or egress rules are required.
## Use logging
When you enable logging, you can view real-time logs generated by your Python
UDFs in Cloud Logging to help you identify and resolve issues in your
code. To prevent accidental data exfiltration, Python UDF logging is off by
default.
> [!CAUTION]
> **Caution:** Logs are saved to Logging. Users with permission to view logs can see all of the data that is logged, whether or not they have access to view the underlying data in BigQuery. Avoid logging sensitive output.
### Enable logging
To enable logging for your session, run the following statement before
you run your query:
SET @@udf.properties = JSON '{"enableDebugOutput": true}';
To log information, use functions in the Python `logging` library, such as
`logging.info` or `logging.error`. The `print()` function isn't supported.
Logs are written to the `bigquery.googleapis.com/ManagedRoutineInvocation`
resource in Logging, which has the following labels available
for filtering:
- `resource_container`: the ID of the project where the query job ran.
- `location`: the location where the query job ran.
- `query_job_id`: the ID of the query job that invoked the Python UDF.
- `routine_project_id`: the project ID where the invoked routine is stored.
- `routine_dataset_id`: the dataset ID where the invoked routine is stored.
- `routine_id`: the ID of the invoked routine.
Data logged to Cloud Logging is subject to
[Google Cloud Observability pricing](https://cloud.google.com/products/observability/pricing).
### Example
The following example shows how to use logging to debug errors in a Python UDF
without causing the query to fail.
The Python UDF `extract_user_email` extracts email addresses
from JSON strings. Because an
unhandled exception in a UDF can cause an entire query to fail, the function
catches exceptions and returns `None`, which becomes a `NULL` value in
BigQuery. To help you identify the invalid
inputs that failed to parse, the function selectively logs the problematic
payload to Cloud Logging:
CREATE OR REPLACE FUNCTION `PROJECT_ID.DATASET_ID`.extract_user_email(payload STRING)
RETURNS STRING
LANGUAGE python
OPTIONS (entry_point='parse_email', runtime_version='python-3.11')
AS
r"""
import json
import logging
def parse_email(payload):
try:
# Attempt to parse the JSON and extract the email
data = json.loads(payload)
return data.get('email')
except Exception as e:
# Log the exact bad data and the error to Cloud Logging
logging.info(f"Failed to parse payload: '{payload}'. Error: {e}")
# Return None (NULL in BigQuery) to prevent the query from failing.
return None
""";
-- The query completes successfully, returning NULL for the invalid row.
-- The info log for 'corrupted_payload_string' is sent to Cloud Logging.
SET @@udf.properties = JSON '{"enableDebugOutput": true}';
SELECT `PROJECT_ID.DATASET_ID`.extract_user_email(raw_data) AS email
FROM UNNEST([
'{"email": "cloudysanfrancisco@gmail.com", "event": "click"}',
'corrupted_payload_string',
'{"email": "baklavainthebalkans@gmail.com", "event": "view"}'
]) AS raw_data;
The logs that contain the `corrupted_payload_string` input are accessible in
Logging.
### View logs
To view the logs for your Python UDFs, choose one of the options in the
following sections.
#### Job information
To view Python UDF logs for a query job from the **Job information** tab, follow
these steps:
1. In the **Query results** pane, click the **Job information** tab.
2. In the **Log** field, click **Log**. Logs Explorer opens and is
prepopulated with a query that shows the logs for your Python UDF call.
#### Logs Explorer
You can also go directly to Logs Explorer and build a query yourself to view
Python UDF logs:
1. Go to the Cloud Logging **Logs Explorer** page.
[Go to Logs Explorer](https://console.cloud.google.com/logs/query)
2. In the query editor, [build a query](https://docs.cloud.google.com/logging/docs/view/building-queries)
using the `bigquery.googleapis.com/ManagedRoutineInvocation` resource type
and any relevant resource labels. For example, you can use the following
query to view Python UDF logs that came from a query job:
resource.type="bigquery.googleapis.com/ManagedRoutineInvocation"
resource.labels.query_job_id="QUERY_JOB_ID"
Replace `QUERY_JOB_ID` with the ID of the query job
that invoked the Python UDF.
## View Python UDF metrics
Python UDFs export metrics to Cloud Monitoring. These metrics help you
monitor various aspects of your UDF's operational health and resource
consumption, providing insights into the performance and behavior of your UDF
instances.
### Monitoring resource type
The metrics for Python UDFs are reported under the following Cloud Monitoring
resource type:
- *Type* : `bigquery.googleapis.com/ManagedRoutineInvocation`
- *Display Name*: BigQuery Managed Routine Invocation
- *Labels* :
- `resource_container`: the ID of the project where the query job ran.
- `location`: the location where the query job ran.
- `query_job_id`: the ID of the query job that invoked the Python UDF.
- `routine_project_id`: the project ID where the invoked routine is stored.
- `routine_dataset_id`: the dataset ID where the invoked routine is stored.
- `routine_id`: the ID of the invoked routine.
### Metrics
The following metrics are available for the
`bigquery.googleapis.com/ManagedRoutineInvocation` resource type:
| Metric | Description | Unit | Value type |
|---|---|---|---|
| `bigquery.googleapis.com/managed_routine/python/cpu_utilizations` | When a Python UDF is invoked, this metric shows the distribution of CPU utilization across all Python UDF instances for the query job. | A percentage value | `DISTRIBUTION` |
| `bigquery.googleapis.com/managed_routine/python/memory_utilizations` | When a Python UDF is invoked, this metric shows the distribution of memory utilization across all Python UDF instances for the query job. | A percentage value | `DISTRIBUTION` |
| `bigquery.googleapis.com/managed_routine/python/max_request_concurrencies` | This metric shows the distribution of the maximum number of concurrent requests served by each Python UDF instance. | Count | `DISTRIBUTION` |
### View metrics
To view the metrics for your Python UDFs, choose one of the options in the
following sections.
#### Job details
To view Python UDF metrics for a specific query job, follow these steps:
1. Go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. Click **Job history**.
3. In the **Job ID** column, click the query job ID.
4. On the **Query job details** page, click **Cloud Monitoring dashboard**.
This link displays a dashboard that is filtered to show the Python UDF
metrics for the job.
#### Metrics Explorer
To view Python UDF metrics in the Metrics Explorer, follow these steps:
1. Go to the Cloud Monitoring **Metrics explorer** page.
[Go to Metrics explorer](https://console.cloud.google.com/monitoring/metrics-explorer)
2. Click **Select a metric** , and in the **Filter** field, type `BigQuery
Managed Routine Invocation` or
`bigquery.googleapis.com/ManagedRoutineInvocation`.
3. Choose **BigQuery Managed Routine \> Managed_routine**.
4. Click any of the available metrics such as the following:
- Instance CPU utilization
- Instance memory utilization
- Max concurrent requests
5. Click **Apply**.
By default, the metrics are displayed in a chart.
6. You can filter and group the metrics using the labels defined in the
[Monitoring resource types](https://docs.cloud.google.com/bigquery/docs/user-defined-functions-python#monitoring_resource_type). To filter the metrics, follow these steps:
1. In the **Filter** field choose a resource type such as `query_job_id` or
`routine_id`.
2. In the **Value** field, enter the job ID or routine ID, or choose one
from the list.
#### Cloud Monitoring dashboards
To view Python UDF metrics using the monitoring dashboards, follow these steps:
1. Go to the Cloud Monitoring **Dashboards** page.
[Go to Dashboards](https://console.cloud.google.com/monitoring/dashboards)
2. Click the **BigQuery Managed Routine Query Monitoring** dashboard.
This dashboard provides an overview of key metrics across your UDFs.
3. To filter this dashboard, follow these steps:
1. Click **Filter**.
2. In the **Filter by resource** list, choose an option such as project ID,
location, routine ID, or job ID.
## Best practices
When you create Python UDFs, follow these best practices:
- Optimize your query logic for batching. Complex query structures can disable batching. This forces slow, row-by-row processing, which significantly increases latency on large datasets.
- Optimize the data payload. The size of individual rows can impact the efficiency of the batching feature. Keep each row as small as possible to maximize the number of rows that can be processed in a single batch.
- Configure [container limits](https://docs.cloud.google.com/bigquery/docs/user-defined-functions-python#configure-container-limits) efficiently. Scalability is a function of CPU, memory, and request concurrency. Check monitoring metrics to tune the container configuration. If CPU utilization is high, increase CPU allocation using the `container_cpu` limit, or reduce container request concurrency using the `container_request_concurrency` limit.
- When you use iterative tuning, start with default values. If performance is suboptimal, analyze monitoring metrics to identify specific bottlenecks.
- Implement API timeouts. When your Python UDF accesses the internet, set a timeout on the API call to avoid unexpected behavior. An example of internet access is reading from a Cloud Storage bucket.
- To reduce cost and improve readability, limit logging to exceptions, data anomalies, or specific debugging windows.
## Supported locations
Python UDFs are supported in all BigQuery [multi-region and
regional locations](https://docs.cloud.google.com/bigquery/docs/locations).
## Pricing
Python UDF charges are billed using the [BigQuery Services SKU](https://cloud.google.com/skus?&filter=BigQuery+Services¤cy=USD).
Charges include the following:
- Building or rebuilding the UDF container image. This charge is proportional
to the duration required to build the corresponding image with customer code
and dependencies.
- If you're using the [Routines API](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/routines), the latest build duration is in the `BuildStatus` field. You can also view the build duration in the `BuildStatus` column in the [`INFORMATION_SCHEMA.ROUTINES` view](https://docs.cloud.google.com/bigquery/docs/information-schema-routines).
- To view the total cost of builds per project, you can filter your billing report by using the following:
- *Key* : `goog-bq-feature-type`
- *Value* : `MANAGED_ROUTINE_BUILD`
- Python UDF customers are also charged for the cost of invoking a Python UDF.
This charge is proportional to the amount of compute and memory consumed
when the Python UDF is invoked.
- To view Python UDF costs per query, you can query the `ExternalServiceCosts` field using the [Job API](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/Job#externalservicecost). You can also view costs per query by viewing the `external_service_costs` column in the [`INFORMATION_SCHEMA.JOBS` view](https://docs.cloud.google.com/bigquery/docs/information-schema-jobs) and applying the following filter: `'external_service_costs.external_service="MANAGED_ROUTINE_EXECUTION"'`.
- To view the total cost of running Python UDFs per project, you can filter the billing report by using the following:
- *Key* : `goog-bq-feature-type`
- *Value* : `MANAGED_ROUTINE_EXECUTION`
- If Python UDFs result in external or internet network egress, you also see a
[Premium Tier](https://cloud.google.com/network-tiers/pricing) internet egress charge based on the [BigQuery Egress SKUs](https://cloud.google.com/skus/sku-groups/network-egress).
## Quotas
See [UDF quotas and limits](https://docs.cloud.google.com/bigquery/quotas#udf_limits).