# Create and manage AWS Glue federated datasets
A *federated dataset* mirrors the schema and tables from an external data
source, making them appear as read-only tables in a BigQuery
dataset. You can use a federated dataset as an efficient way to access data from
AWS Glue in BigQuery.
## Before you begin
Ensure that you have a connection to access AWS Glue data.
- To create or modify a connection, follow the instructions in
[Connect to Amazon S3](https://docs.cloud.google.com/bigquery/docs/omni-aws-create-connection).
When you create that connection, include the following policy statement for
AWS Glue in your
[AWS Identity and Access Management policy for BigQuery](https://docs.cloud.google.com/bigquery/docs/omni-aws-create-connection#creating-aws-iam-policy).
Include this statement in addition to the other permissions on the
Amazon S3 bucket where the data in your AWS Glue tables is
stored.
```json
{
"Effect": "Allow",
"Action": [
"glue:GetDatabase",
"glue:GetTable",
"glue:GetTables",
"glue:GetPartitions"
],
"Resource": [
"arn:aws:glue:REGION:ACCOUNT_ID:catalog",
"arn:aws:glue:REGION:ACCOUNT_ID:database/DATABASE_NAME",
"arn:aws:glue:REGION:ACCOUNT_ID:table/DATABASE_NAME/*"
]
}
```
Replace the following:
- `REGION`: the AWS region---for example `us-east-1`
- `ACCOUNT_ID:`: the 12-digit AWS Account ID
- `DATABASE_NAME`: the AWS Glue database name
### Required permissions
To get the permissions that
you need to create a federated dataset,
ask your administrator to grant you the
[BigQuery Admin](https://docs.cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.admin) (`roles/bigquery.admin`) IAM role.
For more information about granting roles, see [Manage access to projects, folders, and organizations](https://docs.cloud.google.com/iam/docs/granting-changing-revoking-access).
This predefined role contains
the permissions required to create a federated dataset. To see the exact permissions that are
required, expand the **Required permissions** section:
#### Required permissions
The following permissions are required to create a federated dataset:
- `bigquery.datasets.create`
- `bigquery.connections.use`
- `bigquery.connections.delegate`
You might also be able to get
these permissions
with [custom roles](https://docs.cloud.google.com/iam/docs/creating-custom-roles) or
other [predefined roles](https://docs.cloud.google.com/iam/docs/roles-overview#predefined).
For more information about IAM roles and permissions in
BigQuery, see
[Introduction to IAM](https://docs.cloud.google.com/bigquery/docs/access-control).
## Create a federated dataset
To create a federated dataset, do the following:
### Console
1. Open the BigQuery page in the Google Cloud console.
[Go to the BigQuery page](https://console.cloud.google.com/bigquery)
2. In the left pane, click **Explorer**:
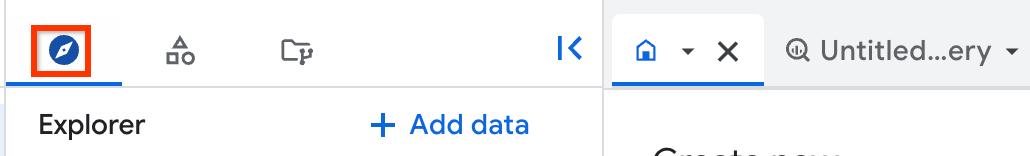
If you don't see the left pane, click **Expand left pane** to open the pane.
3. In the **Explorer** pane, select the project where you want to create
the dataset.
4. Click
**View actions** , and then click **Create dataset**.
5. On the **Create dataset** page, do the following:
- For **Dataset ID**, enter a unique dataset name.
- For **Location type** , choose an AWS location for the dataset, such as `aws-us-east-1`. After you create a dataset, the location can't be changed.
- For **External Dataset**, do the following:
- Check the box next to **Link to an external dataset**.
- For **External dataset type** , select `AWS Glue`.
- For **External source** , enter `aws-glue://` followed by the [Amazon Resource Name (ARN)](https://docs.aws.amazon.com/glue/latest/dg/glue-specifying-resource-arns.html) of the AWS Glue database---for example, `aws-glue://arn:aws:glue:us-east-1:123456789:database/test_database`.
- For **Connection ID**, select your AWS connection.
- Leave the other default settings as they are.
6. Click **Create dataset**.
### SQL
Use the
[`CREATE EXTERNAL SCHEMA` data definition language (DDL) statement](https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/data-definition-language#create_external_schema_statement).
1. In the Google Cloud console, go to the **BigQuery** page.
[Go to BigQuery](https://console.cloud.google.com/bigquery)
2. In the query editor, enter the following statement:
```googlesql
CREATE EXTERNAL SCHEMA DATASET_NAME
WITH CONNECTION PROJECT_ID.CONNECTION_LOCATION.CONNECTION_NAME
OPTIONS (
external_source = 'AWS_GLUE_SOURCE',
location = 'LOCATION');
```
Replace the following:
- `DATASET_NAME`: the name of your new dataset in BigQuery.
- `PROJECT_ID`: your project ID.
- `CONNECTION_LOCATION`: the location of your AWS connection---for example, `aws-us-east-1`.
- `CONNECTION_NAME`: the name of your AWS connection.
- `AWS_GLUE_SOURCE`: the [Amazon Resource Name (ARN)](https://docs.aws.amazon.com/glue/latest/dg/glue-specifying-resource-arns.html) of the AWS Glue database with a prefix identifying the source---for example, `aws-glue://arn:aws:glue:us-east-1:123456789:database/test_database`.
- `LOCATION`: the location of your new dataset in BigQuery---for example, `aws-us-east-1`. After you create a dataset, you can't change its location.
3. Click **Run**.
For more information about how to run queries, see [Run an interactive query](https://docs.cloud.google.com/bigquery/docs/running-queries#queries).
### bq
In a command-line environment, create a dataset by using the
[`bq mk` command](https://docs.cloud.google.com/bigquery/docs/reference/bq-cli-reference#mk-dataset):
```bash
bq --location=LOCATION mk --dataset \
--external_source aws-glue://AWS_GLUE_SOURCE \
--connection_id PROJECT_ID.CONNECTION_LOCATION.CONNECTION_NAME \
DATASET_NAME
```
Replace the following:
- `LOCATION`: the location of your new dataset in BigQuery---for example, `aws-us-east-1`. After you create a dataset, you can't change its location. You can set a default location value by using the [`.bigqueryrc` file](https://docs.cloud.google.com/bigquery/docs/reference/bq-cli-reference#set_default_values_for_command-line_flags).
- `AWS_GLUE_SOURCE`: the [Amazon Resource Name (ARN)](https://docs.aws.amazon.com/glue/latest/dg/glue-specifying-resource-arns.html) of the AWS Glue database---for example, `arn:aws:glue:us-east-1:123456789:database/test_database`.
- `PROJECT_ID`: your BigQuery project ID.
- `CONNECTION_LOCATION`: the location of your AWS connection---for example, `aws-us-east-1`.
- `CONNECTION_NAME`: the name of your AWS connection.
- `DATASET_NAME`: the name of your new dataset in BigQuery. To create a dataset in a project other than your default project, add the project ID to the dataset name in the following format: `PROJECT_ID`:`DATASET_NAME`.
### Terraform
Use the
[`google_bigquery_dataset` resource](https://registry.terraform.io/providers/hashicorp/google/latest/docs/resources/bigquery_dataset#example-usage---bigquery-dataset-external-reference-aws-docs).
> [!NOTE]
> **Note:** To create BigQuery objects using Terraform, you must enable the [Cloud Resource Manager API](https://docs.cloud.google.com/resource-manager/reference/rest).
To authenticate to BigQuery, set up Application Default
Credentials. For more information, see
[Set up authentication for client libraries](https://docs.cloud.google.com/bigquery/docs/authentication#client-libs).
The following example creates an AWS Glue federated dataset:
```json
resource "google_bigquery_dataset" "dataset" {
provider = google-beta
dataset_id = "example_dataset"
friendly_name = "test"
description = "This is a test description."
location = "aws-us-east-1"
external_dataset_reference {
external_source = "aws-glue://arn:aws:glue:us-east-1:999999999999:database/database"
connection = "projects/project/locations/aws-us-east-1/connections/connection"
}
}
```
To apply your Terraform configuration in a Google Cloud project, complete the steps in the
following sections.
## Prepare Cloud Shell
1. Launch [Cloud Shell](https://shell.cloud.google.com/).
2. Set the default Google Cloud project
where you want to apply your Terraform configurations.
You only need to run this command once per project, and you can run it in any directory.
```
export GOOGLE_CLOUD_PROJECT=PROJECT_ID
```
Environment variables are overridden if you set explicit values in the Terraform
configuration file.
## Prepare the directory
Each Terraform configuration file must have its own directory (also
called a *root module*).
1. In [Cloud Shell](https://shell.cloud.google.com/), create a directory and a new file within that directory. The filename must have the `.tf` extension---for example `main.tf`. In this tutorial, the file is referred to as `main.tf`.
```
mkdir DIRECTORY && cd DIRECTORY && touch main.tf
```
2. If you are following a tutorial, you can copy the sample code in each section or step.
Copy the sample code into the newly created `main.tf`.
Optionally, copy the code from GitHub. This is recommended
when the Terraform snippet is part of an end-to-end solution.
3. Review and modify the sample parameters to apply to your environment.
4. Save your changes.
5. Initialize Terraform. You only need to do this once per directory.
```
terraform init
```
Optionally, to use the latest Google provider version, include the `-upgrade`
option:
```
terraform init -upgrade
```
## Apply the changes
1. Review the configuration and verify that the resources that Terraform is going to create or update match your expectations:
```
terraform plan
```
Make corrections to the configuration as necessary.
2. Apply the Terraform configuration by running the following command and entering `yes` at the prompt:
```
terraform apply
```
Wait until Terraform displays the "Apply complete!" message.
3. [Open your Google Cloud project](https://console.cloud.google.com/) to view the results. In the Google Cloud console, navigate to your resources in the UI to make sure that Terraform has created or updated them.
> [!NOTE]
> **Note:** Terraform samples typically assume that the required APIs are enabled in your Google Cloud project.
### API
Call the
[`datasets.insert` method](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/datasets/insert)
with a defined [dataset resource](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/datasets)
and [`externalDatasetReference` field](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/datasets#ExternalDatasetReference)
for your AWS Glue database.
## List tables in a federated dataset
To list the tables that are available for query in your federated dataset, see
[List datasets](https://docs.cloud.google.com/bigquery/docs/listing-datasets).
## Get table information
To get information on the tables in your federated dataset, such as schema
details, see
[Get table information](https://docs.cloud.google.com/bigquery/docs/tables#get_table_information).
## Control access to tables
To manage access to the tables in your federated dataset, see
[Control access to resources with IAM](https://docs.cloud.google.com/bigquery/docs/control-access-to-resources-iam).
[Row-level security](https://docs.cloud.google.com/bigquery/docs/managing-row-level-security),
[column-level security](https://docs.cloud.google.com/bigquery/docs/column-level-security-intro), and
[data masking](https://docs.cloud.google.com/bigquery/docs/column-data-masking-intro) are also supported for
tables in federated datasets.
Schema operations that might invalidate security policies, such as deleting a
column in AWS Glue, can cause jobs to fail until the policies are
updated. Additionally, if you delete a table in AWS Glue and recreate
it, your security policies no longer apply to the recreated table.
## Query AWS Glue data
[Querying tables](https://docs.cloud.google.com/bigquery/docs/running-queries) in federated datasets is the
same as querying tables in any other BigQuery dataset.
You can query AWS Glue tables in the following formats:
- CSV (compressed and uncompressed)
- JSON (compressed and uncompressed)
- Parquet
- ORC
- Avro
- Iceberg
- Delta Lake
## Table mapping details
Every table that you grant access to in your AWS Glue database
appears as an equivalent table in your BigQuery dataset.
### Format
The format of each BigQuery table is determined by the following
fields of the respective
[AWS Glue table](https://docs.aws.amazon.com/glue/latest/dg/aws-glue-api-catalog-tables.html#aws-glue-api-catalog-tables-Table):
- `InputFormat` (`Table.StorageDescriptor.InputFormat`)
- `OutputFormat` (`Table.StorageDescriptor.OutputFormat`)
- `SerializationLib` (`Table.StorageDescriptor.SerdeInfo.SerializationLibrary`)
The only exception is Iceberg tables, which use the `TableType`
(`Table.Parameters["table_type"]`) field.
For example, an AWS Glue table with the following fields is mapped to
an ORC table in BigQuery:
- `InputFormat` = `"org.apache.hadoop.hive.ql.io.orc.OrcInputFormat"`
- `OutputFormat` = `"org.apache.hadoop.hive.ql.io.orc.OrcOutputFormat"`
- `SerializationLib` = `"org.apache.hadoop.hive.ql.io.orc.OrcSerde"`
### Location
The location of each BigQuery table is determined by the
following:
- Iceberg tables: the `Table.Parameters["metadata_location"]` field in the AWS Glue table
- Non-Iceberg unpartitioned tables: the `Table.StorageDescriptor.Location` field in the AWS Glue table
- Non-Iceberg partitioned tables: the AWS Glue GetPartitions API
### Other properties
Additionally, some AWS Glue table properties are automatically mapped
to format-specific options in BigQuery:
| **Format** | **SerializationLib** | **AWS Glue table value** | **BigQuery option** |
|---|---|---|---|
| CSV | LazySimpleSerDe | Table.StorageDescriptor.SerdeInfo.Parameters\["field.delim"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).fieldDelimiter |
| CSV | LazySimpleSerDe | Table.StorageDescriptor.Parameters\["serialization.encoding"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).encoding |
| CSV | LazySimpleSerDe | Table.StorageDescriptor.Parameters\["skip.header.line.count"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).skipLeadingRows |
| CSV | OpenCsvSerDe | Table.StorageDescriptor.SerdeInfo.Parameters\["separatorChar"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).fieldDelimiter |
| CSV | OpenCsvSerDe | Table.StorageDescriptor.SerdeInfo.Parameters\["quoteChar"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).quote |
| CSV | OpenCsvSerDe | Table.StorageDescriptor.Parameters\["serialization.encoding"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).encoding |
| CSV | OpenCsvSerDe | Table.StorageDescriptor.Parameters\["skip.header.line.count"\] | [CsvOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#csvoptions).skipLeadingRows |
| JSON | Hive [JsonSerDe](https://github.com/apache/hive/blob/master/hcatalog/core/src/main/java/org/apache/hive/hcatalog/data/JsonSerDe.java) | Table.StorageDescriptor.Parameters\["serialization.encoding"\] | [JsonOptions](https://docs.cloud.google.com/bigquery/docs/reference/rest/v2/tables#jsonoptions).encoding |
## Create a view in a federated dataset
You can't create a view in a federated dataset. However, you can create a view
in a standard dataset that's based on a table in a federated dataset. For more
information, see [Create views](https://docs.cloud.google.com/bigquery/docs/views).
## Delete a federated dataset
Deleting a federated dataset is the same as deleting any other
BigQuery dataset. For more information, see
[Delete datasets](https://docs.cloud.google.com/bigquery/docs/managing-datasets#delete-datasets).
## Pricing
For information about pricing, see
[BigQuery Omni pricing](https://cloud.google.com/bigquery/pricing#bqomni).
## Limitations
- All [BigQuery Omni limitations](https://docs.cloud.google.com/bigquery/docs/omni-introduction#limitations) apply.
- You can't add, delete, or update data or metadata in tables in an AWS Glue federated dataset.
- You can't create new tables, views, or materialized views in an AWS Glue federated dataset.
- [`INFORMATION_SCHEMA` views](https://docs.cloud.google.com/bigquery/docs/information-schema-intro) aren't supported.
- [Metadata caching](https://docs.cloud.google.com/bigquery/docs/biglake-intro#metadata_caching_for_performance) isn't supported.
- Dataset-level settings that are related to table creation defaults don't affect federated datasets because you can't create tables manually.
- The Apache Hive data type `UNION` isn't supported for Avro tables.
- [External table limitations](https://docs.cloud.google.com/bigquery/docs/external-tables#limitations) apply.
## What's next
- Learn more about [BigQuery Omni](https://docs.cloud.google.com/bigquery/docs/omni-introduction).
- Try the [BigQuery Omni with AWS lab](https://www.cloudskillsboost.google/catalog_lab/5345).